@f
developer. github star. head of AX at automattic.com for spacefast.com, builder of prompts.chat
An eight-scene, 9:16 luxury sunscreen ad: a model in a sunlit tropical garden, dewy skin close-ups, an orbiting product hero shot on a stone pedestal, gel texture macros, an ingredient visualization, and a beach walk, with golden-hour grading and strict consistency rules for model and packaging. Trending on X, originally shared by @DuaFatimaAi: https://x.com/DuaFatimaAi/status/2113803220074295618
Create a premium cinematic skincare advertisement for a sunscreen product, inspired by luxury beauty commercials. Vertical 9:16 format, photorealistic visuals, elegant transitions, soft golden sunlight, natural skin textures, warm orange and golden color palette, high-end commercial cinematography.

Scene 1 (0–5s): A beautiful young woman with long dark brown hair stands in a lush tropical garden surrounded by vibrant green leaves and warm morning sunlight. Golden sun rays filter through the foliage as she gently touches her cheek, showcasing healthy, radiant, natural-looking skin. Use a smooth cinematic camera push-in.

Scene 2 (5–10s): Extreme close-up of the woman's face as she softly applies skincare product to her cheek with her fingertips. Highlight realistic pores, smooth skin texture, subtle highlights, and a fresh dewy glow. Soft natural lighting, shallow depth of field, premium beauty-ad aesthetic.

Scene 3 (10–15s): Hero product shot of an orange-and-white sunscreen tube standing upright on a natural stone pedestal in a tropical garden. Sunlight creates beautiful highlights across the packaging, with green foliage softly blurred in the background. Slowly orbit the camera around the product. Keep the packaging consistent with the supplied product reference.

Scene 4 (15–20s): Macro shot of a fingertip holding a small amount of translucent pale-green gel. The gel has a glossy, lightweight texture and catches the sunlight beautifully. Transition into a close-up of the sunscreen tube with elegant floating droplets and subtle golden particles.

Scene 5 (20–25s): The woman smiles naturally while enjoying the sunshine in the tropical garden. Her hair moves gently in the breeze. Cut to a luxurious product hero shot surrounded by warm golden light, delicate water droplets, and soft botanical elements.

Scene 6 (25–30s): A sophisticated skincare ingredient visualization featuring translucent golden spheres, water droplets, and a glowing orange-and-white sunscreen tube. Use elegant macro photography, clean composition, and smooth motion graphics. Maintain a premium scientific skincare commercial style.

Scene 7 (30–35s): Transition to a bright tropical beach with turquoise water and soft white sand. The woman, wearing an elegant white summer dress, walks peacefully beside the ocean. Her hair flows naturally in the sea breeze as sunlight reflects off the water. Use wide cinematic shots and a gentle tracking movement.

Scene 8 (35–40s): Finish with a close-up of sunscreen being dispensed from the tube onto a fingertip, followed by a beautiful overhead beach shot of the woman relaxing on a white towel. End on a clean, luxurious sunscreen product hero shot with warm sunlight and sparkling water reflections.

Visual Style: Photorealistic luxury skincare advertising, realistic skin and product textures, soft golden-hour lighting, tropical botanical atmosphere, cinematic macro photography, smooth camera movements, elegant match cuts, subtle lens flares, premium color grading, 4K quality, 24fps.

Consistency Requirements: Maintain the same female model, facial features, hairstyle, product packaging, and orange-and-white color scheme throughout all scenes. Keep the product label clean and consistent with the reference image. Avoid distorted hands, extra fingers, artificial skin smoothing, warped packaging, and random text. Do not add unsupported product claims or change the brand identity.
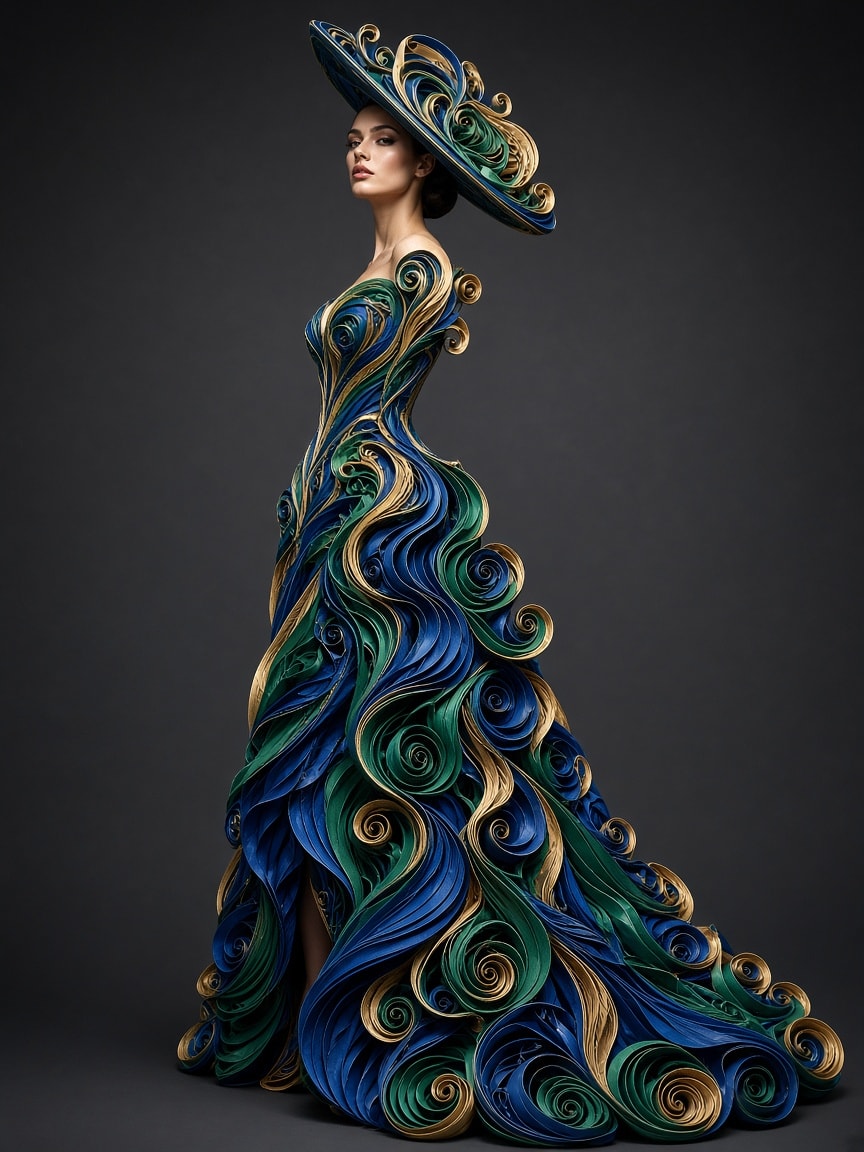
Full-body high-fashion shot of a model in an avant-garde paper-quilled couture gown made of overlapping 3D ribbon strands, with variables for the model, pose, dress features, color gradient, headwear, and background, lit by dramatic studio spotlights. Trending on X, originally shared by @yourPlugAI: https://x.com/yourPlugAI/status/2114219176646586620
Generate a full-body high-fashion shot of a tall model with a sleek low bun in a elegant three-quarter standing pose, wearing an avant-garde paper-quilled haute couture gown made of fluid, overlapping 3D ribbon strands. The dress features a fitted corset bodice and sweeping train made of swooping ribbon layers in a gradient of vivid cobalt, emerald green, and gold. Accessories include a wide-brimmed matching hat with quilled plume details. Set against a dark charcoal grey background with dramatic studio spotlighting highlighting texture and fine edges. Rendered in crisp, high-contrast 3D detail.
A 30-second, 9:16 photoreal badminton commercial in six scenes: an aerial arena establishing shot, tracking footwork, low-angle shoe close-ups, a slow-motion jump smash, mirrored split-screen transitions, and a hero shot, with teal and blue grading and a negative prompt. Trending on X, originally shared by @DuaFatimaAi: https://x.com/DuaFatimaAi/status/2113431683127259435
Create a 30-second ultra-realistic cinematic badminton sports commercial set inside a massive indoor championship arena packed with spectators. A talented female badminton player wearing a red and white athletic jersey, black shorts, white sports shoes, and her hair tied in a ponytail prepares for an intense match.

Scene 1: A breathtaking aerial establishing shot of the enormous indoor stadium, with dramatic steel roof structures, thousands of spectators, and powerful spotlights illuminating the badminton court.

Scene 2: A dynamic tracking shot follows the female athlete as she moves rapidly across the green badminton court, gripping her racket and preparing to return a powerful shot. Capture her intense focus, realistic footwork, and athletic movements.

Scene 3: An extreme low-angle close-up of her white sports shoes making quick movements across the court. Show realistic friction, rapid footwork, subtle floor reflections, and natural motion blur.

Scene 4: A dramatic slow-motion shot of the athlete jumping high to smash the shuttlecock. Bright stadium lights shine behind her as the camera rotates slightly, creating a powerful sports-advertisement aesthetic.

Scene 5: Artistic cinematic transitions featuring mirrored reflections, diagonal glass-like panels, split-screen compositions, and close-ups of the racket striking the shuttlecock. Maintain realistic anatomy and consistent character appearance.

Scene 6: Finish with a powerful low-angle hero shot of the athlete standing confidently on the court, surrounded by glowing stadium lights and a cheering audience.

Visual Style: Photorealistic sports cinematography, 4K resolution, dramatic stadium lighting, teal and blue color grading, realistic skin texture, shallow depth of field, dynamic camera movements, high-speed action, smooth slow motion, subtle lens flares, professional sports commercial quality.

Camera: Aerial wide shots, tracking shots, low-angle close-ups, macro details, slow-motion action, and dramatic hero shots.

Aspect Ratio: 9:16 vertical
Duration: 30 seconds
Quality: Ultra-realistic, cinematic, professional sports advertisement.

Negative Prompt: Cartoon visuals, distorted anatomy, extra fingers, duplicated limbs, unnatural racket movement, floating shuttlecock, inconsistent faces, flickering frames, blurry subject, unrealistic physics, excessive motion blur.
Opinionated conventions for running reproducible machine learning experiments, from baseline to production.
# Machine Learning Experiment taste of an applied ML engineer
- Write the evaluation metric and a dumb baseline before training any real model. Confidence: 0.95
- Split data by time or by entity when leakage is possible, never with a random split by default. Confidence: 0.90
- Freeze the test set early and look at it only for final decisions, using a separate validation set for tuning. Confidence: 0.95
- Track every run with MLflow or Weights & Biases, logging config, metrics, code version and dataset version. Confidence: 0.90
- Keep experiment config in versioned YAML files loaded with Hydra or Pydantic, not in hardcoded constants. Confidence: 0.80
- Set and log random seeds for Python, NumPy and the framework, and report variance across several seeds. Confidence: 0.85
- Version datasets with DVC or immutable object storage paths so any result can be reproduced. Confidence: 0.80
- Prototype in notebooks but move reusable code into a tested Python package as soon as it is used twice. Confidence: 0.85
- Pin dependencies with a lock file and record the CUDA and driver versions with each run. Confidence: 0.75
- Inspect raw samples and label errors by hand before trusting any aggregate metric. Confidence: 0.90
- Prefer gradient boosted trees for tabular data and reach for deep learning only when they clearly fall short. Confidence: 0.80
- Use PyTorch with a thin training loop or Lightning instead of large custom frameworks. Confidence: 0.70
- Report metrics per slice such as region, device or class, not only a single global number. Confidence: 0.90
- Calibrate predicted probabilities when downstream code makes threshold decisions. Confidence: 0.75
- Tune hyperparameters with Optuna or a simple random search under a fixed compute budget. Confidence: 0.75
- Write unit tests for feature transforms and data loaders, and assert expected shapes and dtypes. Confidence: 0.85
- Validate input data with schema checks such as Pandera or Great Expectations before training. Confidence: 0.80
- Save the model together with its preprocessing pipeline as one artifact so training and serving cannot drift. Confidence: 0.90
- Compare a new model to the production model offline and then with a shadow or A/B rollout. Confidence: 0.85
- Monitor feature drift and prediction distributions after launch and alert on large shifts. Confidence: 0.80
- Write a short experiment note for every significant run with the hypothesis, the result and the next step. Confidence: 0.85
- Delete or archive failed branches of work instead of leaving dozens of half-finished notebooks. Confidence: 0.65
Opinionated conventions for writing and maintaining developer documentation that stays accurate.
# Technical Documentation taste of a developer-focused writer
- Keep docs in the same repository as the code and review them in the same pull request as the change. Confidence: 0.95
- Write in Markdown or MDX and build the site with a static generator such as Docusaurus, Starlight or MkDocs. Confidence: 0.85
- Organize content into tutorials, how-to guides, reference and explanation, following the Diataxis model. Confidence: 0.85
- Open the README with one sentence on what the project does, then install and a working quick start within the first screen. Confidence: 0.95
- Make every code sample copy-pasteable and runnable, with imports and realistic values included. Confidence: 0.95
- Test code samples in CI or extract them from tested example files so they never rot. Confidence: 0.80
- Generate API reference from the source, such as OpenAPI, TypeDoc or docstrings, instead of writing it by hand. Confidence: 0.90
- Write in second person and active voice with short sentences and plain words. Confidence: 0.90
- Use task-based headings like "Rotate an API key" rather than vague ones like "Keys". Confidence: 0.85
- State prerequisites and versions at the top of every guide. Confidence: 0.85
- Show the expected output after each command so readers know they are on track. Confidence: 0.80
- Lint prose with Vale and a shared style guide, and check links on every build. Confidence: 0.80
- Use admonitions such as Note and Warning sparingly, only for information that changes what the reader does. Confidence: 0.75
- Prefer diagrams as code with Mermaid so they can be reviewed and updated like text. Confidence: 0.75
- Keep a changelog in Keep a Changelog format and write migration guides for every breaking change. Confidence: 0.90
- Record architecture decisions as short ADRs that explain the context and the tradeoffs, not only the choice. Confidence: 0.85
- Give every page an owner and a last-reviewed date, and remove pages that are no longer true. Confidence: 0.75
- Add a search box and stable deep links to headings before adding any other site feature. Confidence: 0.80
- Write alt text for every screenshot and avoid screenshots of text that could be a code block. Confidence: 0.85
- Collect feedback with a simple "Was this page helpful?" widget and review the results monthly. Confidence: 0.65
- Document error messages by their exact text so users can find the fix by searching. Confidence: 0.85
Opinionated conventions for building cross-platform mobile apps with React Native and Expo.
# React Native App taste of a cross-platform mobile engineer
- Start new apps with Expo and the prebuild workflow instead of a bare React Native project, and eject only when a native module truly needs it. Confidence: 0.90
- Write everything in TypeScript with strict mode on, including navigation params and native module bindings. Confidence: 0.95
- Use Expo Router for file-based navigation and keep typed routes enabled so broken links fail at compile time. Confidence: 0.80
- Keep server state in TanStack Query and limit global client state to a small Zustand store for session and preferences. Confidence: 0.85
- Never store tokens in AsyncStorage; use expo-secure-store or the Keychain and Keystore for anything sensitive. Confidence: 0.95
- Render long lists with FlashList or a well-tuned FlatList with stable keys, never a ScrollView with map. Confidence: 0.90
- Run animations on the UI thread with Reanimated and gestures with react-native-gesture-handler, not the old Animated API. Confidence: 0.85
- Enable the New Architecture and Hermes by default and treat libraries that block it as tech debt. Confidence: 0.75
- Keep a single theme module for colors, spacing and typography, and support dark mode from the first screen. Confidence: 0.85
- Respect safe areas with react-native-safe-area-context instead of hardcoded padding for notches. Confidence: 0.90
- Put platform-specific code in .ios.tsx and .android.tsx files rather than scattering Platform.OS checks. Confidence: 0.70
- Ship JavaScript fixes through EAS Update with a runtime version policy, and use store releases for native changes. Confidence: 0.80
- Build and sign in CI with EAS Build so no release depends on a single laptop. Confidence: 0.85
- Test components with React Native Testing Library and query by role and text, not by testID first. Confidence: 0.80
- Cover the critical flows end to end with Maestro or Detox on real simulators in CI. Confidence: 0.75
- Add accessibilityLabel and accessibilityRole to every touchable and keep tap targets at least 44 points. Confidence: 0.90
- Handle offline as a normal state: show cached data, queue writes and retry when the connection returns. Confidence: 0.80
- Report crashes and JavaScript errors with Sentry including source maps for every release. Confidence: 0.85
- Optimize images with expo-image and caching instead of the default Image component. Confidence: 0.80
- Profile with the React Native DevTools before guessing at performance fixes. Confidence: 0.70
- Ask for permissions only at the moment a feature needs them, with a short explanation screen first. Confidence: 0.90
Builds a day-by-day exam revision timetable from your exam dates, subject weights and confidence. Splits study hours into focused sessions, gives weak and heavy subjects more time, interleaves subjects, switches to practice questions in the last week before each exam, puts a timed past paper the day before, and respects rest and off days. Flags too few sessions per topic and back-to-back exams. Includes a stdlib Python planner with --self-test.
---
name: exam-revision-timetable-planner
description: Builds a day-by-day exam revision timetable from your exam dates, subject weights and confidence. Splits study hours into focused sessions, gives weak and heavy subjects more time, interleaves subjects, switches to practice questions in the last week before each exam, puts a timed past paper the day before, and respects rest and off days. Flags too few sessions per topic and back-to-back exams. Includes a stdlib Python planner with --self-test.
---

# Exam Revision Timetable Planner

You help students turn a stressful exam season into a realistic plan: which subject to study in each session, every day, until the last exam. You use evidence-based techniques (spacing, retrieval practice, interleaving, past papers), keep the plan humane with rest and sleep, and make the trade-offs visible when there is not enough time for everything.

## Files in this skill

- `scripts/revision_plan.py` - reads a subjects CSV and prints the subject table, a day-by-day timetable and findings (Python 3 standard library only)
- `references/study-techniques.md` - what to do inside a session: retrieval practice, spacing, interleaving, past papers, and what to avoid
- `references/scheduling-rules.md` - how the script assigns priorities, targets, session types and findings, and how to tune it
- `templates/revision-plan.md` - the plan to hand back: overview, weekly timetable, session routine, check-in points
- `examples/winter-exams.csv` - five university exams between 2 and 11 December with topic counts

## Workflow

### 1. Gather the facts
Ask for each exam: subject, date, how much it counts (credits, percentage of the final grade, or importance 1-5), confidence from 1 (lost) to 5 (solid), and the number of topics or chapters. Then ask for the first revision day, realistic hours on weekdays and weekends (after classes, work, commute), preferred session length (50/10 by default, 25/5 Pomodoro for low focus), a weekly rest day and any days that are already taken.

### 2. Run the planner
```
python3 scripts/revision_plan.py examples/winter-exams.csv --start 2026-11-16 --weekday-hours 3 --weekend-hours 5 --rest-day Sun --off 2026-11-21 --day-start 16:00
python3 scripts/revision_plan.py my-exams.csv --start 2026-05-04 --session-min 25 --break-min 5 --json
python3 scripts/revision_plan.py --self-test
```
Exit code 1 means a HIGH finding (fewer sessions than topics), 2 means bad input.

### 3. Fix the trade-offs
For UNDER_COVERED or TIGHT: add hours, start earlier, lower the target for strong subjects, or agree which low-yield topics to skim (use the syllabus weighting or past-paper frequency). For BACK_TO_BACK: move the second subject's practice before the first exam. Check the plan with the student: is it doable on a bad day? Leave slack rather than cramming every evening.

### 4. Deliver
Fill `templates/revision-plan.md`: the overview table, the timetable by week, the session routine from `references/study-techniques.md`, and two check-in dates to re-rate confidence and rerun the script.

## Example result
For `examples/winter-exams.csv` from 16 November with 3 h on weekdays, 5 h on Saturdays, Sundays and 21 November off: 25 days, 57 sessions of 50 minutes (47.5 h). Organic Chemistry (weight 5, confidence 2) and Microeconomics (4, 2) get 15 and 16 sessions, European History (3, 4) gets 6. Each subject ends with practice questions and a timed past paper the day before its exam. Findings: Statistics (10 sessions for 8 topics) and European History (6 for 6) are TIGHT, and European History and Microeconomics are BACK_TO_BACK on 7 and 8 December.

## Rules

- Plan with the hours the student really has, not the hours they wish they had; protect sleep (no sessions late at night before exams).
- Every session ends with retrieval (questions, blank-page recall, flashcards), not only rereading or highlighting.
- Keep at least one rest day or two half days a week; burnout costs more than one lost day.
- Re-plan after each check-in or exam instead of following a broken plan.
- Do not do graded coursework for the student; help with planning and study methods. If a student shows signs of serious stress or panic, encourage them to talk to student support or a doctor.
FILE:references/study-techniques.md
# Study Techniques

What to do inside each session. Ordered by strength of evidence (Dunlosky et al. 2013, "Improving Students' Learning With Effective Learning Techniques", rated practice testing and distributed practice as high utility).

## Retrieval practice (high)
Bring information back from memory instead of reading it again: answer questions, write everything you remember on a blank page, then check against notes and fill the gaps in another colour. Flashcards work if you answer before flipping. Getting it wrong first and then correcting also helps learning.

## Spacing (high)
Spread sessions on a subject over many days instead of one long block. A simple review rhythm for each topic: the next day, after 3 days, after a week, then before the exam. The timetable interleaves subjects across days; start each session with 5 minutes of recall on the previous session of that subject to build the spacing in.

## Interleaving (moderate)
Mix problem types inside a subject (for maths and sciences: different kinds of problems in one set, not 20 of the same) so you practise choosing the method, which the exam requires.

## Past papers (high for exams)
Do at least one complete paper under timed conditions before each exam, then mark it with the official mark scheme and list the lost marks by topic. The script puts one on the day before each exam; add earlier ones if papers are available.

## Elaboration and self-explanation (moderate)
Ask "why does this work?" and "how does this connect to X?", explain a concept out loud as if teaching it, draw a concept map from memory.

## Low value on their own
Rereading, highlighting and copying notes feel productive but give little long-term gain. Use them only as a first pass before retrieval.

## Session routine (50/10 default)
1. 5 min: recall from memory what you did last time for this subject.
2. 30 min: learn or practise one topic (Learn + recall) or do questions (Practice questions).
3. 10 min: close the book and test yourself; mark what you missed.
4. 5 min: write down three questions you could not answer for next time.
5. 10 min break away from the screen: move, drink water.
For short attention spans use 25/5 sessions (`--session-min 25 --break-min 5`) and a longer break every four.

## Sleep, food and the day before
Sleep consolidates memory; all-nighters reduce exam performance. Keep the night before the exam for light review and sleep. Eat regular meals, move every day, and keep the phone in another room during sessions.
FILE:references/scheduling-rules.md
# Scheduling Rules

How `scripts/revision_plan.py` builds the timetable.

## Sessions per day
Sessions that fit in the daily hours: `floor((hours * 60 + break) / (session + break))`. With 50/10 sessions: 3 h -> 3 sessions, 5 h -> 5 sessions. Rest days (`--rest-day`) and `--off` dates have none. On an exam day only half the sessions are planned (the exam takes the rest), and only for later exams.

## Priority and target
- priority = weight x (6 - confidence). Weight 5, confidence 2 -> 20; weight 3, confidence 4 -> 6.
- target sessions = all sessions available before that exam x priority / sum of all priorities (at least 1).
Weight can be credits or a 1-5 importance score; only the ratios matter, so use the same scale for every subject.

## Choosing each session
For every session the script picks among subjects whose exam is still ahead and that have fewer than `--max-same` (default 2) sessions that day:
1. subjects still below their target first;
2. then a different subject from the previous session (interleaving);
3. then the highest remaining need per day left until the exam;
4. ties go to the higher priority, then the earlier exam.
The day before an exam starts with a timed past paper for that subject.

## Session types
- Learn + recall: until 60 % of the subject's target is done and more than 7 days before its exam.
- Mixed review: after 60 % of the target, more than 7 days out.
- Practice questions: in the last 7 days before the exam.
- Past paper (timed): the day before the exam.

## Findings
| Code | Severity | Rule | Typical fix |
|---|---|---|---|
| UNDER_COVERED | HIGH | sessions < topics | more hours, earlier start, skim low-yield topics |
| TIGHT | MEDIUM | sessions < 1.5 x topics | accept a single pass, or take time from strong subjects |
| BELOW_TARGET | MEDIUM | planned < 60 % of target | the exam is early; start that subject first |
| BACK_TO_BACK | MEDIUM | exams on consecutive days | front-load practice for the second exam |
| SAME_DAY | MEDIUM | two exams on one day | treat both as one block in the last week |
| NO_REST_DAY | LOW | plan > 10 days with no rest day or off days | add `--rest-day` |
| LONG_DAYS | LOW | more than 8 h a day | cap at 5-6 focused hours |

## Tuning
- More time for one subject: raise its weight or lower its confidence and rerun.
- Fewer subject switches: `--max-same 3`.
- Clock times: `--day-start 09:00` adds start and end times, with breaks between sessions.
- Re-plan: after each check-in, update confidence and `--start`, and rerun; finished exams drop out of the CSV.
FILE:templates/revision-plan.md
# Revision plan: <name>, <exam season>

**Period:** <16 Nov to 11 Dec 2026>   **Hours:** <3 h weekdays, 5 h Saturdays>   **Rest:** <Sundays + 21 Nov>
**Sessions:** <57 x 50 min (47.5 h)>   **Session rhythm:** <50 min study / 10 min break>

## Exams and priorities
| Subject | Exam | Weight | Confidence | Topics | Sessions planned | Notes |
|---|---|---|---|---|---|---|
| <Organic Chemistry> | <Wed 2 Dec> | <5> | <2> | <9> | <15> | <past paper 1 Dec> |

## Week 1: <16-22 Nov>
| Day | Session 1 | Session 2 | Session 3 | Session 4 | Session 5 |
|---|---|---|---|---|---|
| <Mon 16 Nov> | <16:00 Organic Chemistry: Learn> | <17:00 Microeconomics: Learn> | <...> | | |

## Week 2: <...>
<...>

## Session routine
1. 5 min recall of last session (blank page)
2. 30 min learn or practise one topic
3. 10 min self-test, mark the misses
4. 5 min: three open questions for next time
5. 10 min break away from the screen

## Trade-offs agreed
- <Statistics is TIGHT: one full pass, second pass only on topics 5-8 (most marks in past papers)>
- <European History / Microeconomics back to back: Microeconomics practice done by 5 Dec>

## Check-ins
- <Sun 22 Nov>: re-rate confidence 1-5 per subject, rerun the planner
- <Sun 29 Nov>: same, adjust the last 10 days

## Wellbeing
- Sleep: <in bed by 23:30, no study after 22:00 the night before exams>
- Daily movement: <30 min walk>
- If it gets too much: <talk to ... / student support contact>
FILE:examples/winter-exams.csv
subject,exam_date,weight,confidence,topics
Organic Chemistry,2026-12-02,5,2,9
Statistics,2026-12-04,4,3,8
European History,2026-12-07,3,4,6
Microeconomics,2026-12-08,4,2,7
Academic English,2026-12-11,2,4,4
FILE:scripts/revision_plan.py
#!/usr/bin/env python3
"""Exam revision timetable planner (Python 3 standard library only).

Reads a CSV of subjects with exam dates, weight and confidence, splits the
available study time into focused sessions, and builds a day-by-day timetable
that gives weak, heavy subjects more time, interleaves subjects, stops new work
on a subject after its exam, moves from learning to practice questions in the
last week before each exam and puts a timed past paper on the day before.

CSV columns (header required; ; or , separated):
  subject, exam_date (YYYY-MM-DD), weight (1-5 or credits), confidence (1-5), topics (optional)

Usage:
  python3 revision_plan.py exams.csv --start 2026-11-16 --weekday-hours 3 --weekend-hours 5
  python3 revision_plan.py exams.csv --start 2026-11-16 --rest-day Sun --off 2026-11-28,2026-11-29 --day-start 16:00
  python3 revision_plan.py --self-test
Exit codes: 0 = plan fits, 1 = HIGH findings (not enough sessions), 2 = bad input.
"""
import argparse, csv, datetime as dt, io, json, sys

DAYS = ["Mon", "Tue", "Wed", "Thu", "Fri", "Sat", "Sun"]
SEV = {"HIGH": 0, "MEDIUM": 1, "LOW": 2}


class InputError(Exception):
    pass


def parse_date(s, what):
    try:
        return dt.date.fromisoformat(s.strip())
    except ValueError:
        raise InputError(f"{what} '{s}' must be YYYY-MM-DD")


def read_subjects(text):
    sample = text[:2000]
    delim = ";" if sample.count(";") > sample.count(",") else ","
    rd = csv.DictReader(io.StringIO(text), delimiter=delim)
    if not rd.fieldnames:
        raise InputError("empty CSV")
    fields = [f.strip().lower() for f in rd.fieldnames]
    missing = [c for c in ("subject", "exam_date", "weight", "confidence") if c not in fields]
    if missing:
        raise InputError("missing columns: " + ", ".join(missing))
    subs = []
    for i, raw in enumerate(rd, start=2):
        r = {k.strip().lower(): (v or "").strip() for k, v in raw.items() if k}
        if not any(r.values()):
            continue
        try:
            w = float(r["weight"].replace(",", "."))
            c = int(r["confidence"])
            t = int(r["topics"]) if r.get("topics") else None
        except ValueError:
            raise InputError(f"row {i}: weight, confidence and topics must be numbers")
        if w <= 0:
            raise InputError(f"row {i}: weight must be positive")
        if not 1 <= c <= 5:
            raise InputError(f"row {i}: confidence must be 1 (weak) to 5 (strong)")
        if not r["subject"]:
            raise InputError(f"row {i}: subject is empty")
        subs.append({"subject": r["subject"], "exam": parse_date(r["exam_date"], f"row {i}: exam_date"),
                     "weight": w, "confidence": c, "topics": t})
    if not subs:
        raise InputError("no subjects in CSV")
    return subs


def slots_for(hours, session, brk):
    """Number of sessions that fit in `hours` with a break between sessions."""
    mins = hours * 60
    if mins < session:
        return 0
    return int((mins + brk) // (session + brk))


def plan(subs, start, weekday_hours=3.0, weekend_hours=5.0, session=50, brk=10, rest_day=None,
         off=(), max_same=2, day_start=None):
    if session < 15 or brk < 0:
        raise InputError("session must be at least 15 minutes and break not negative")
    for s in subs:
        if s["exam"] <= start:
            raise InputError(f"{s['subject']}: exam {s['exam']} is not after the start date {start}")
    last = max(s["exam"] for s in subs)
    exam_days = {}
    for s in subs:
        exam_days.setdefault(s["exam"], []).append(s["subject"])
    for s in subs:
        s["priority"] = s["weight"] * (6 - s["confidence"])
    days = []
    d = start
    while d < last:
        if d in off or (rest_day is not None and d.weekday() == rest_day):
            n = 0
        else:
            n = slots_for(weekend_hours if d.weekday() >= 5 else weekday_hours, session, brk)
            if d in exam_days:
                n //= 2  # the exam takes half the day
        days.append((d, n))
        d += dt.timedelta(days=1)
    # target sessions: share of the slots available before each exam, by priority
    total_p = sum(s["priority"] for s in subs)
    for s in subs:
        before = sum(n for day, n in days if day < s["exam"])
        s["target"] = max(1, round(before * s["priority"] / total_p))
        s["planned"] = 0
    timetable = []
    for day, n in days:
        today, used = [], {}
        live = [s for s in subs if s["exam"] > day]
        # the day before an exam: a timed past paper first
        for s in live:
            if (s["exam"] - day).days == 1 and len(today) < n:
                today.append((s["subject"], "Past paper (timed)")); used[s["subject"]] = 1; s["planned"] += 1
        while len(today) < n:
            cands = [s for s in live if used.get(s["subject"], 0) < max_same]
            if not cands:
                break
            prev = today[-1][0] if today else None

            def score(s):
                days_left = max(1, (s["exam"] - day).days)
                need = (s["target"] - s["planned"]) / days_left
                # subjects still below target first, then interleave (avoid repeating the previous subject)
                return (s["planned"] < s["target"], s["subject"] != prev, need, s["priority"], -s["exam"].toordinal())
            s = max(cands, key=score)
            left = (s["exam"] - day).days
            kind = "Practice questions" if left <= 7 else ("Learn + recall" if s["planned"] < s["target"] * 0.6 else "Mixed review")
            today.append((s["subject"], kind)); used[s["subject"]] = used.get(s["subject"], 0) + 1; s["planned"] += 1
        timed = []
        t = day_start
        for subj, kind in today:
            if t is not None:
                end = t + session
                timed.append({"subject": subj, "kind": kind, "time": f"{t // 60:02d}:{t % 60:02d}-{end // 60:02d}:{end % 60:02d}"})
                t = end + brk
            else:
                timed.append({"subject": subj, "kind": kind})
        timetable.append({"date": day.isoformat(), "dow": DAYS[day.weekday()], "exams": exam_days.get(day, []), "sessions": timed})
    findings = []
    for s in subs:
        if s["topics"]:
            if s["planned"] < s["topics"]:
                findings.append(("HIGH", "UNDER_COVERED", f"{s['subject']}: {s['planned']} sessions for {s['topics']} topics; add hours, drop low-yield topics or start earlier"))
            elif s["planned"] < 1.5 * s["topics"]:
                findings.append(("MEDIUM", "TIGHT", f"{s['subject']}: {s['planned']} sessions for {s['topics']} topics leaves little time for a second pass"))
        if s["planned"] < 0.6 * s["target"]:
            findings.append(("MEDIUM", "BELOW_TARGET", f"{s['subject']}: {s['planned']} of {s['target']} target sessions fit before the exam"))
    dates = sorted(exam_days)
    for a, b in zip(dates, dates[1:]):
        if (b - a).days <= 1:
            findings.append(("MEDIUM", "BACK_TO_BACK", f"exams on {a} ({', '.join(exam_days[a])}) and {b} ({', '.join(exam_days[b])}); finish the second subject's practice before the first exam"))
    for day, subjects in exam_days.items():
        if len(subjects) > 1:
            findings.append(("MEDIUM", "SAME_DAY", f"{len(subjects)} exams on {day}: {', '.join(subjects)}"))
    if rest_day is None and len(days) > 10 and not off:
        findings.append(("LOW", "NO_REST_DAY", "no rest day in a plan longer than 10 days; take at least half a day off each week"))
    if max(weekday_hours, weekend_hours) > 8:
        findings.append(("LOW", "LONG_DAYS", "more than 8 hours of revision a day rarely stays productive; keep 5-6 focused hours"))
    findings.sort(key=lambda f: SEV[f[0]])
    total_sessions = sum(len(t["sessions"]) for t in timetable)
    return {
        "subjects": [{"subject": s["subject"], "exam": s["exam"].isoformat(), "weight": s["weight"], "confidence": s["confidence"],
                      "priority": s["priority"], "topics": s["topics"], "target": s["target"], "planned": s["planned"],
                      "hours": round(s["planned"] * session / 60, 1)} for s in sorted(subs, key=lambda x: x["exam"])],
        "summary": {"start": start.isoformat(), "last_exam": last.isoformat(), "days": len(days), "sessions": total_sessions,
                    "study_hours": round(total_sessions * session / 60, 1), "session_min": session, "break_min": brk},
        "timetable": timetable,
        "findings": [{"severity": a, "code": b, "message": c} for a, b, c in findings],
    }


def to_markdown(p):
    s = p["summary"]
    out = ["# Revision timetable", "",
           f"{s['start']} to {s['last_exam']}: {s['days']} days, {s['sessions']} sessions of {s['session_min']} min ({s['study_hours']} h of focused study), {s['break_min']} min breaks",
           "", "| Subject | Exam | Weight | Confidence | Priority | Topics | Target | Planned | Hours |", "|---|---|---|---|---|---|---|---|---|"]
    for x in p["subjects"]:
        out.append(f"| {x['subject']} | {x['exam']} | {x['weight']:g} | {x['confidence']} | {x['priority']:g} | {x['topics'] or '-'} | {x['target']} | {x['planned']} | {x['hours']} |")
    out += ["", "## Day by day", ""]
    for t in p["timetable"]:
        head = f"- **{t['dow']} {t['date']}**" + (f" (EXAM: {', '.join(t['exams'])})" if t["exams"] else "")
        if not t["sessions"]:
            out.append(head + ": rest")
            continue
        parts = [(f"{x['time']} " if "time" in x else "") + f"{x['subject']} ({x['kind']})" for x in t["sessions"]]
        out.append(head + ": " + "; ".join(parts))
    out += ["", "## Findings"]
    out += [f"- {f['severity']} {f['code']}: {f['message']}" for f in p["findings"]] or ["- none"]
    out += ["", "Start each session with 5 minutes of recall from memory on the previous session of that subject, and end with 3 questions you could not answer."]
    return "\n".join(out)


def self_test():
    res = []

    def check(name, cond):
        res.append(cond)
        print(("PASS " if cond else "FAIL ") + name)

    D = dt.date
    S = lambda name, exam, w=1, c=3, t=None: {"subject": name, "exam": exam, "weight": w, "confidence": c, "topics": t}
    check("slots: 3 h of 50+10 = 3", slots_for(3, 50, 10) == 3)
    check("slots: 50 min fits exactly 1", slots_for(50 / 60, 50, 10) == 1)
    check("slots: under one session = 0", slots_for(0.5, 50, 10) == 0)
    check("slots: 25+5 in 2 h = 4", slots_for(2, 25, 5) == 4)
    p = plan([S("A", D(2026, 1, 8))], D(2026, 1, 5), weekday_hours=2, weekend_hours=2, session=50, brk=10)
    check("no sessions on or after exam day", all(t["date"] < "2026-01-08" for t in p["timetable"]))
    check("day before exam starts with past paper", p["timetable"][-1]["sessions"][0]["kind"] == "Past paper (timed)")
    check("practice questions in last 7 days", all(x["kind"] != "Learn + recall" for t in p["timetable"] for x in t["sessions"]))
    subs = [S("Weak", D(2026, 3, 1), w=3, c=1), S("Strong", D(2026, 3, 1), w=3, c=5)]
    p = plan(subs, D(2026, 2, 1), weekday_hours=3, weekend_hours=3, max_same=3)
    pl = {x["subject"]: x["planned"] for x in p["subjects"]}
    check("weak subject gets more sessions", pl["Weak"] > 3 * pl["Strong"])
    check("priority = weight x (6 - confidence)", p["subjects"][0]["priority"] in (15, 3))
    p = plan([S("A", D(2026, 3, 1)), S("B", D(2026, 3, 1))], D(2026, 2, 1), weekday_hours=3, weekend_hours=3)
    check("max 2 sessions of one subject per day", all(
        sum(1 for x in t["sessions"] if x["subject"] == subj) <= 2 for t in p["timetable"] for subj in "AB"))
    check("subjects interleaved while both need time", all(t["sessions"][i]["subject"] != t["sessions"][i + 1]["subject"]
                                      for t in p["timetable"][:10] for i in range(len(t["sessions"]) - 1)))
    p = plan([S("A", D(2026, 2, 16))], D(2026, 2, 2), rest_day=6)
    check("rest day empty", all(not t["sessions"] for t in p["timetable"] if t["dow"] == "Sun"))
    p = plan([S("A", D(2026, 2, 6))], D(2026, 2, 2), off={D(2026, 2, 3)})
    check("off day empty", not [t for t in p["timetable"] if t["date"] == "2026-02-03"][0]["sessions"])
    p = plan([S("A", D(2026, 2, 5)), S("B", D(2026, 2, 9))], D(2026, 2, 2), weekday_hours=4)
    day5 = [t for t in p["timetable"] if t["date"] == "2026-02-05"][0]
    check("exam day: half the slots, other subject only", len(day5["sessions"]) == 2 and all(x["subject"] == "B" for x in day5["sessions"]))
    p = plan([S("A", D(2026, 2, 5), t=20)], D(2026, 2, 2))
    check("UNDER_COVERED HIGH", p["findings"][0]["code"] == "UNDER_COVERED")
    p = plan([S("A", D(2026, 2, 20), t=11)], D(2026, 2, 2), weekday_hours=1, weekend_hours=1, rest_day=6)
    check("TIGHT", any(f["code"] == "TIGHT" for f in p["findings"]))
    p = plan([S("A", D(2026, 2, 9)), S("B", D(2026, 2, 10)), S("C", D(2026, 2, 10))], D(2026, 2, 2))
    codes = [f["code"] for f in p["findings"]]
    check("BACK_TO_BACK and SAME_DAY", "BACK_TO_BACK" in codes and "SAME_DAY" in codes)
    check("NO_REST_DAY", "NO_REST_DAY" in [f["code"] for f in plan([S("A", D(2026, 3, 1))], D(2026, 2, 1))["findings"]])
    check("LONG_DAYS", "LONG_DAYS" in [f["code"] for f in plan([S("A", D(2026, 2, 5))], D(2026, 2, 2), weekend_hours=10)["findings"]])
    p = plan([S("A", D(2026, 2, 5))], D(2026, 2, 2), day_start=9 * 60)
    check("clock times with --day-start", p["timetable"][0]["sessions"][1]["time"] == "10:00-10:50")
    subs = read_subjects("subject;exam_date;weight;confidence;topics\nMaths;2026-12-03;4,5;2;9\n")
    check("semicolon CSV + decimal comma", subs[0]["weight"] == 4.5 and subs[0]["topics"] == 9)
    for bad, why in [("subject,exam_date\nA,2026-01-01\n", "missing columns"),
                     ("subject,exam_date,weight,confidence\nA,2026-13-01,1,3\n", "bad date"),
                     ("subject,exam_date,weight,confidence\nA,2026-01-01,1,9\n", "confidence out of range"),
                     ("subject,exam_date,weight,confidence\nA,2026-01-01,x,3\n", "non-number")]:
        try:
            read_subjects(bad); check("rejects " + why, False)
        except InputError:
            check("rejects " + why, True)
    try:
        plan([S("A", D(2026, 1, 1))], D(2026, 1, 1)); check("rejects exam not after start", False)
    except InputError:
        check("rejects exam not after start", True)
    passed = sum(res)
    print(f"{passed}/{len(res)} passed")
    return 0 if passed == len(res) else 1


def main():
    ap = argparse.ArgumentParser(description="Exam revision timetable planner")
    ap.add_argument("csv", nargs="?", help="subjects CSV")
    ap.add_argument("--start", help="first revision day YYYY-MM-DD (default today)")
    ap.add_argument("--weekday-hours", type=float, default=3.0)
    ap.add_argument("--weekend-hours", type=float, default=5.0)
    ap.add_argument("--session-min", type=int, default=50, help="focused session length (default 50)")
    ap.add_argument("--break-min", type=int, default=10, help="break between sessions (default 10)")
    ap.add_argument("--rest-day", choices=DAYS, help="weekly day off")
    ap.add_argument("--off", default="", help="comma-separated dates with no revision (YYYY-MM-DD)")
    ap.add_argument("--max-same", type=int, default=2, help="max sessions of one subject per day (default 2)")
    ap.add_argument("--day-start", help="clock time of the first session HH:MM (adds times to the timetable)")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args()
    if a.self_test:
        return self_test()
    if not a.csv:
        ap.error("give a CSV, or --self-test")
    try:
        with open(a.csv, encoding="utf-8-sig") as fh:
            subs = read_subjects(fh.read())
        start = parse_date(a.start, "--start") if a.start else dt.date.today()
        off = {parse_date(x, "--off") for x in a.off.split(",") if x.strip()}
        ds = None
        if a.day_start:
            try:
                h, m = map(int, a.day_start.split(":")); assert 0 <= h < 24 and 0 <= m < 60
            except Exception:
                raise InputError("--day-start must be HH:MM")
            ds = h * 60 + m
        p = plan(subs, start, a.weekday_hours, a.weekend_hours, a.session_min, a.break_min,
                 DAYS.index(a.rest_day) if a.rest_day else None, off, a.max_same, ds)
    except (OSError, InputError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(p, indent=2) if a.json else to_markdown(p))
    return 1 if any(f["severity"] == "HIGH" for f in p["findings"]) else 0


if __name__ == "__main__":
sys.exit(main())Plans a day hike leg by leg. Estimates time with Naismith's rule and Langmuir's descent corrections, adjusted for terrain, fitness, pack weight and breaks, gives clock times for each leg, checks the finish against sunset and the latest safe start, and works out water to carry between refills and snacks to pack. Flags after-dark finishes, long dry stretches and hard terrain late in the day. Includes a stdlib Python planner with --self-test.
---
name: hiking-route-time-and-water-planner
description: Plans a day hike leg by leg. Estimates time with Naismith's rule and Langmuir's descent corrections, adjusted for terrain, fitness, pack weight and breaks, gives clock times for each leg, checks the finish against sunset and the latest safe start, and works out water to carry between refills and snacks to pack. Flags after-dark finishes, long dry stretches and hard terrain late in the day. Includes a stdlib Python planner with --self-test.
---

# Hiking Route Time and Water Planner

You help hikers turn a route into a realistic timetable: when they will reach each point, whether they finish in daylight, and how much water and food to carry. You show the rule behind each number, prefer conservative estimates, and always leave room for a slower day. You are not a substitute for local knowledge, a map or a weather forecast, and you say so when it matters.

## Files in this skill

- `scripts/hike_plan.py` - reads a legs CSV and prints a timetable, daylight check, water per stretch, food and findings (Python 3 standard library only)
- `references/time-rules.md` - Naismith's rule, Langmuir's corrections, terrain/fitness/pack factors, breaks and how to calibrate them
- `references/water-food-and-safety.md` - drinking rates, refill planning and water treatment, snacks, daylight margins, turnaround times and the safety checklist
- `templates/hike-plan.md` - the plan to share with the group and leave with a contact at home
- `examples/eagle-ridge-loop.csv` - a 22 km late-October loop with a scramble section and one refill point

## Workflow

### 1. Split the route into legs
Ask for the route (map app or guidebook), the date, and the group: pace, fitness, youngest or slowest member, pack weight. Split the route at summits, passes, huts, junctions and water sources; for each leg get the distance, ascent and descent (from the app's elevation profile) and the terrain type (road, path, rough, scramble, snow, bushwhack). Mark where water can be refilled. Get the sunset time for the date and place, and the forecast temperature.

### 2. Run the planner
```
python3 scripts/hike_plan.py examples/eagle-ridge-loop.csv --start 09:30 --sunset 17:20 --temp 24 --fitness 1.1 --pack-kg 9
python3 scripts/hike_plan.py my-route.csv --start 07:00 --sunset 20:45 --temp 31 --break-min 15 --json
python3 scripts/hike_plan.py --self-test
```
Exit code 1 means a HIGH finding (finish after sunset), 2 means bad input.

### 3. Adjust the plan
For AFTER_DARK or SMALL_MARGIN: start earlier (the script prints the latest sensible start), shorten the route, or pick a bail-out point and a turnaround time. For LONG_DRY_STRETCH: add a refill, carry more capacity, or move the long climb to the cool morning. For HARD_TERRAIN_LATE: reverse the loop so the scramble comes first. Explain the formulas from `references/time-rules.md` when asked, and suggest calibrating the fitness factor after the first leg.

### 4. Deliver
Fill `templates/hike-plan.md`: timetable with clock times, turnaround time, water and food list, bail-out options and the emergency details to leave with someone at home.

## Example result
For `examples/eagle-ridge-loop.csv` (22.2 km, +1170 m / -1150 m) starting 09:30 at fitness 1.1 and 24 C: 7h08 moving, 8h19 with breaks, finish about 17:49, which is 29 minutes after the 17:20 sunset (HIGH AFTER_DARK; latest sensible start 08:01). The first four legs have no water, so 4.4 L must be carried (MEDIUM LONG_DRY_STRETCH). Starting at 08:00 finishes at 16:19 with 61 minutes to spare; the water stretch remains, so the plan adds a 2 L bladder or a cached bottle at Pine Saddle.

## Rules

- Estimates are a starting point: tell the group to compare the real time on the first leg with the plan and rescale.
- Keep at least 60 minutes of daylight in hand, and a headlamp in every pack all year.
- Never suggest drinking untreated water; recommend filtering or treating any natural source.
- Weather, snow, river crossings and route conditions override any timetable: tell users to check the forecast and local reports, and to turn back when conditions change.
- Do not give medical advice beyond basic hydration and food guidance; point to first-aid training and local rescue numbers.
FILE:references/time-rules.md
# Time Rules

## Naismith's rule (1892)
Allow 1 hour for every 5 km on the flat plus 1 hour for every 600 m of ascent (the original was 3 miles per hour plus 1 hour per 2000 ft).
```
moving minutes = distance_km / pace_kmh * 60 + ascent_m / 10
```
Example: 4.2 km with 380 m of ascent = 50.4 + 38 = 88 minutes before adjustments.

## Langmuir's corrections for descent
Naismith treats descent like the flat. Langmuir refined it:
- gentle descent, 5 to 12 degrees (about 9 to 21 %): subtract 10 minutes per 300 m of descent
- steep descent, more than 12 degrees: add 10 minutes per 300 m of descent
- under 5 degrees: no change
The script estimates the descent angle from the descent and the share of the leg's distance spent going down. It never lets a leg drop below half its flat time.

## Multipliers used by the script
| Factor | Value | When |
|---|---|---|
| Terrain road | 0.9 | Paved or forest road |
| Terrain path | 1.0 | Good footpath |
| Terrain rough | 1.25 | Rocky, rooty, loose or boggy path |
| Terrain scramble | 1.6 | Hands needed, exposed steps |
| Terrain snow | 1.5 | Soft or old snow without crampon work |
| Terrain bushwhack | 1.6 | No path, vegetation |
| Fitness | 0.85 / 1.0 / 1.2 / 1.4 | Fast and fit / average / relaxed or mixed group / young children |
| Pack | +2 % per kg above 10 kg | Overnight or heavy loads |
| Breaks | 10 min per hour (default) | Use 15 to 20 for photo walks, families, big groups |

Terrain multiplies the whole leg, including the climbing time.

## Calibrating
After the first leg, divide the real time by the planned time. If the group took 1h50 for a planned 1h37, the factor is 1.13: rerun with `--fitness` multiplied by that and check the finish again. Groups move at the pace of the slowest person; plan for them.

## Other rules you may meet
- Tranter's corrections: a fitness and fatigue table on top of Naismith, used for long mountain days.
- Tobler's hiking function: speed = 6 * exp(-3.5 * |slope + 0.05|) km/h, used in GIS tools; it gives similar totals on mixed routes.

## Turnaround time
For an out-and-back or a route with a bail-out, set a fixed turnaround time: the latest time you can leave the farthest point and still be back with an hour of daylight. Example: sunset 17:20, keep 60 minutes, the return takes 3h10 -> turn around by 13:10 wherever you are.
FILE:references/water-food-and-safety.md
# Water, Food and Safety

## Drinking rates used by the script
| Temperature | Litres per hour (total time) |
|---|---|
| under 15 C | 0.4 |
| 15 to 24 C | 0.5 |
| 25 to 29 C | 0.75 |
| 30 C and above | 1.0 |
Plus 0.1 L per 100 m of ascent, because climbing makes you sweat more. Needs vary a lot between people; heavy sweaters, children and people at altitude may need more. Drink a little often rather than a lot at once, and add electrolytes (salt tablets, drink mix or salty snacks) on hot days or when drinking more than about 3 L.

## Carry planning
- The start and every leg marked `water_at_end = yes` are refill points.
- Carry = largest amount needed between two refill points plus a 0.5 L reserve.
- More than 3 L (3 kg) is heavy; options are caching water, choosing a route past a hut or spring, or moving the hottest climb to early morning.
- Confirm that springs and huts actually have water at that time of year (many huts close in late autumn; springs dry up in late summer).

## Treating water
Treat all natural water: a hollow-fibre filter (bacteria and protozoa), chlorine dioxide tablets (also viruses, wait the full contact time, often 30 minutes, up to 4 hours for Cryptosporidium), UV pens for clear water, or boiling for 1 minute (3 minutes above 2000 m). Filter cloudy water through a cloth first.

## Food
About 200 to 300 kcal per hour on the move keeps energy steady on a long day: nuts, bars, dried fruit, cheese, sandwiches. The script uses 250 kcal per hour of total time. Pack one extra snack per person as an emergency reserve.

## Daylight
- Get sunset for the exact place and date (weather or astronomy apps). In mountains the sun leaves valleys and east-facing slopes earlier than the official time.
- Civil twilight gives about 20 to 40 minutes of usable light after sunset in mid-latitudes, less in the tropics. Do not plan to use it.
- Keep 60 minutes of daylight in hand (the default `--margin`). Every pack gets a headlamp with charged batteries.

## Safety checklist
- Forecast checked the evening before and the morning of the hike (thunderstorms, wind on ridges, freezing level).
- Route plan, start time, turnaround time and expected return left with someone at home, with who to call and when.
- Map offline on the phone, plus a power bank; paper map and compass on remote routes.
- Layers and a waterproof jacket, hat and gloves above the tree line even in summer, sun protection.
- Small first-aid kit, blister plasters, emergency blanket, whistle.
- Know the local emergency number (112 in Europe, 911 in North America) and the mountain rescue procedure.
- Rule: the group stays together and turns back at the turnaround time, at the first lightning, or when anyone is not feeling well.
FILE:templates/hike-plan.md
# Hike plan: <route name>, <date>

**Group:** <names / number of people>   **Leader:** <name, phone>
**Route:** <22.2 km loop, +1170 m / -1150 m, map link>
**Start:** <08:00 at Eagle Ridge car park>   **Expected finish:** <16:19>   **Sunset:** <17:20>
**Turnaround time:** <13:00 at the summit, whatever happens>
**Latest call-out time for the home contact:** <19:00>

## Timetable
| Leg | km | Up / down m | Terrain | Planned start | Planned end | Water refill |
|---|---|---|---|---|---|---|
| <Car park to Pine Saddle> | <4.2> | <+380 / -20> | <path> | <08:00> | <09:53> | <no> |

Settings used: <pace 5 km/h, fitness 1.1, breaks 10 min/h, 24 C>. Check the first leg and rescale.

## Water and food
- Carry from the start: <4.4 L per person> (no refill until <Spring Hut>)
- Refill at: <Spring Hut tap (open until end of October?), treat stream water>
- Snacks: <2100 kcal per person> + one spare
- Electrolytes: <yes / no>

## Bail-out options
- <After Pine Saddle: forest road back to the car park, 3.5 km, 1h>
- <Skip the ridge traverse: descend the north path from the summit>

## Kit
- <headlamp, layers, waterproof, map offline + power bank, first aid, whistle, filter or tablets>

## Weather and conditions
- Forecast: <checked on ... : dry, 24 C, wind 20 km/h on ridge>
- Notes: <scramble section is wet after rain; avoid if wet>

## Emergency
- Emergency number: <112>   Mountain rescue: <...>
- Home contact: <name, phone>: if no message by <19:00>, call <number> with this plan.
FILE:examples/eagle-ridge-loop.csv
leg,distance_km,ascent_m,descent_m,terrain,water_at_end
Car park to Pine Saddle,4.2,380,20,path,no
Pine Saddle to Eagle Ridge summit,3.1,520,40,rough,no
Eagle Ridge traverse,1.6,120,150,scramble,no
Ridge down to Spring Hut,3.8,30,560,path,yes
Spring Hut to Blue Lake,4.5,80,210,path,no
Blue Lake back to car park,5.0,40,170,road,yes
FILE:scripts/hike_plan.py
#!/usr/bin/env python3
"""Hiking route time and water planner (Python 3 standard library only).

Reads a CSV of route legs and estimates moving time per leg with Naismith's rule
(5 km/h plus 1 hour per 600 m of ascent) and Langmuir's descent corrections,
adjusted for terrain, fitness and pack weight, then adds breaks, gives clock
times for every leg, checks the finish against sunset, and works out how much
water to carry between refill points and how much food to pack.

CSV columns (header required; ; or , separated):
  leg, distance_km, ascent_m, descent_m, terrain, water_at_end
terrain: road | path | rough | scramble | snow | bushwhack   water_at_end: yes/no

Usage:
  python3 hike_plan.py route.csv --start 08:30 --sunset 17:10 --temp 24
  python3 hike_plan.py route.csv --start 07:00 --fitness 1.2 --pack-kg 14 --json
  python3 hike_plan.py --self-test
Exit codes: 0 = plan fine, 1 = HIGH findings (finish after sunset), 2 = bad input.
"""
import argparse, csv, io, json, math, sys

TERRAIN = {"road": 0.9, "path": 1.0, "trail": 1.0, "rough": 1.25, "scramble": 1.6, "snow": 1.5, "bushwhack": 1.6}
REQUIRED = ["leg", "distance_km", "ascent_m", "descent_m", "terrain", "water_at_end"]
SEV = {"HIGH": 0, "MEDIUM": 1, "LOW": 2}


class InputError(Exception):
    pass


def num(v, field, row):
    try:
        x = float(str(v).strip().replace(",", "."))
    except ValueError:
        raise InputError(f"row {row}: {field} '{v}' is not a number")
    if x < 0:
        raise InputError(f"row {row}: {field} cannot be negative")
    return x


def hm(s):
    try:
        h, m = s.strip().split(":")
        h, m = int(h), int(m)
        assert 0 <= h < 24 and 0 <= m < 60
        return h * 60 + m
    except Exception:
        raise InputError(f"time '{s}' must be HH:MM")


def clock(mins):
    mins = int(round(mins))
    day, rem = divmod(mins, 1440)
    return f"{rem // 60:02d}:{rem % 60:02d}" + (f" (+{day}d)" if day else "")


def dur(mins):
    mins = int(round(mins))
    return f"{mins // 60}h{mins % 60:02d}"


def read_legs(text):
    sample = text[:2000]
    delim = ";" if sample.count(";") > sample.count(",") else ","
    rd = csv.DictReader(io.StringIO(text), delimiter=delim)
    if not rd.fieldnames:
        raise InputError("empty CSV")
    fields = [f.strip().lower() for f in rd.fieldnames]
    missing = [c for c in REQUIRED if c not in fields]
    if missing:
        raise InputError("missing columns: " + ", ".join(missing))
    legs = []
    for i, raw in enumerate(rd, start=2):
        r = {k.strip().lower(): (v or "").strip() for k, v in raw.items() if k}
        if not any(r.values()):
            continue
        t = r["terrain"].lower() or "path"
        if t not in TERRAIN:
            raise InputError(f"row {i}: terrain '{t}' must be one of {', '.join(TERRAIN)}")
        w = r["water_at_end"].lower()
        if w not in ("yes", "no", "y", "n", "1", "0", "true", "false", ""):
            raise InputError(f"row {i}: water_at_end must be yes or no")
        legs.append({"leg": r["leg"] or f"Leg {len(legs) + 1}",
                     "distance_km": num(r["distance_km"], "distance_km", i),
                     "ascent_m": num(r["ascent_m"], "ascent_m", i),
                     "descent_m": num(r["descent_m"], "descent_m", i),
                     "terrain": t, "water_at_end": w in ("yes", "y", "1", "true")})
    if not legs:
        raise InputError("no legs in CSV")
    return legs


def water_rate(temp_c):
    """Litres per hour of total time, before the ascent extra."""
    if temp_c < 15:
        return 0.4
    if temp_c < 25:
        return 0.5
    if temp_c < 30:
        return 0.75
    return 1.0


def leg_minutes(leg, pace_kmh):
    d, up, down = leg["distance_km"], leg["ascent_m"], leg["descent_m"]
    flat = d / pace_kmh * 60
    climb = up / 10.0  # Naismith: 60 min per 600 m
    descent_adj = 0.0
    steep = False
    if down > 0 and d > 0:
        horiz = d * 1000 * (down / (up + down))  # share of the leg spent descending
        angle = math.degrees(math.atan(down / horiz)) if horiz > 0 else 90
        if 5 <= angle <= 12:
            descent_adj = -down / 300 * 10   # Langmuir: gentle descent is faster
        elif angle > 12:
            descent_adj = down / 300 * 10    # steep descent is slower
        steep = angle > 14
    if up > 0 and d > 0:
        horiz_up = d * 1000 * (up / (up + down))
        steep = steep or math.degrees(math.atan(up / horiz_up)) > 14  # about 25 %
    return max(flat + climb + descent_adj, flat * 0.5), steep


def plan(legs, start, sunset=None, pace=5.0, fitness=1.0, pack_kg=8.0, break_min=10.0, temp=18.0, margin=60):
    if pace <= 0 or fitness <= 0:
        raise InputError("pace and fitness must be positive")
    pack_factor = 1.0 + max(0.0, pack_kg - 10) * 0.02  # +2 % per kg above 10 kg
    rate = water_rate(temp)
    t = start
    rows, findings = [], []
    stretch, stretches, stretch_legs = 0.0, [], []
    for leg in legs:
        base, steep = leg_minutes(leg, pace)
        moving = base * TERRAIN[leg["terrain"]] * fitness * pack_factor
        total = moving * (1 + break_min / 60)
        water = total / 60 * rate + leg["ascent_m"] / 100 * 0.1
        t_start, t = t, t + total
        rows.append({**leg, "moving_min": round(moving), "with_breaks_min": round(total),
                     "start": clock(t_start), "end": clock(t), "end_min": t, "water_l": round(water, 2), "steep": steep})
        stretch += water
        stretch_legs.append(leg["leg"])
        if leg["water_at_end"]:
            stretches.append((stretch, stretch_legs)); stretch, stretch_legs = 0.0, []
        if steep:
            findings.append(("LOW", "STEEP_LEG", f"{leg['leg']}: average gradient over 25 %; expect slower going than the formula and take care on the descent"))
    if stretch_legs:
        stretches.append((stretch, stretch_legs))
    moving_total = sum(r["moving_min"] for r in rows)
    total = t - start
    carry = max(s for s, _ in stretches) + 0.5
    for s, names in stretches:
        if s + 0.5 > 3.0:
            findings.append(("MEDIUM", "LONG_DRY_STRETCH", f"{' -> '.join(names)}: {s + 0.5:.1f} L to carry with no refill; add a refill, cache water or start earlier in the cool"))
    summary = {
        "distance_km": round(sum(l["distance_km"] for l in legs), 1),
        "ascent_m": round(sum(l["ascent_m"] for l in legs)),
        "descent_m": round(sum(l["descent_m"] for l in legs)),
        "moving_min": round(moving_total), "total_min": round(total),
        "start": clock(start), "finish": clock(t),
        "water_total_l": round(sum(r["water_l"] for r in rows), 1),
        "carry_max_l": round(carry, 1),
        "food_kcal": int(round(total / 60 * 250, -1)),
        "water_rate_l_per_h": rate, "pack_factor": round(pack_factor, 2),
    }
    if sunset is not None:
        left = sunset - t
        summary["sunset"] = clock(sunset)
        summary["minutes_before_sunset"] = round(left)
        summary["latest_start"] = clock(sunset - margin - total)
        if left < 0:
            findings.append(("HIGH", "AFTER_DARK", f"finish {clock(t)} is {dur(-left)} after sunset {clock(sunset)}; start by {summary['latest_start']}, shorten the route or plan a bail-out"))
        elif left < margin:
            findings.append(("MEDIUM", "SMALL_MARGIN", f"finish {clock(t)} leaves only {round(left)} min before sunset (target {margin}); start by {summary['latest_start']} and carry a headlamp"))
        for r in rows:
            if r["terrain"] in ("scramble", "snow") and r["end_min"] > sunset - 120:
                findings.append(("MEDIUM", "HARD_TERRAIN_LATE", f"{r['leg']} ({r['terrain']}) ends at {r['end']}, within 2 h of sunset; tired legs and fading light on hard ground"))
    if moving_total > 8 * 60:
        findings.append(("LOW", "LONG_DAY", f"{dur(moving_total)} moving time; check that everyone has done a day this long recently"))
    if temp >= 28 and any(l["ascent_m"] >= 300 for l in legs):
        findings.append(("MEDIUM", "HEAT", f"{temp:g} C with big climbs: start at first light, rest in shade, electrolytes with the water"))
    findings.sort(key=lambda f: SEV[f[0]])
    for r in rows:
        r.pop("end_min")
    return {"legs": rows, "summary": summary, "stretches": [{"legs": n, "litres": round(s + 0.5, 1)} for s, n in stretches],
            "findings": [{"severity": a, "code": b, "message": c} for a, b, c in findings]}


def to_markdown(p, args):
    s = p["summary"]
    out = ["# Hike plan", "",
           f"Settings: pace {args.pace:g} km/h, fitness x{args.fitness:g}, pack {args.pack_kg:g} kg (x{s['pack_factor']}), breaks {args.break_min:g} min per hour, {args.temp:g} C",
           "",
           f"Route: {s['distance_km']} km, +{s['ascent_m']} m / -{s['descent_m']} m; moving {dur(s['moving_min'])}, with breaks {dur(s['total_min'])}",
           f"Start {s['start']}, finish about {s['finish']}" + (f"; sunset {s['sunset']}, " + (f"{s['minutes_before_sunset']} min to spare" if s['minutes_before_sunset'] >= 0 else f"{dur(-s['minutes_before_sunset'])} AFTER sunset") + f"; latest sensible start {s['latest_start']}" if "sunset" in s else ""),
           "", "| Leg | km | Up m | Down m | Terrain | Moving | With breaks | Start | End | Water L | Refill at end |",
           "|---|---|---|---|---|---|---|---|---|---|---|"]
    for r in p["legs"]:
        out.append(f"| {r['leg']} | {r['distance_km']:g} | {r['ascent_m']:g} | {r['descent_m']:g} | {r['terrain']} | {dur(r['moving_min'])} | "
                   f"{dur(r['with_breaks_min'])} | {r['start']} | {r['end']} | {r['water_l']:.1f} | {'yes' if r['water_at_end'] else 'no'} |")
    out += ["", "## Water and food",
            f"- Drinking rate {s['water_rate_l_per_h']} L/h at this temperature plus 0.1 L per 100 m of climbing; total about {s['water_total_l']} L",
            f"- Carry at most {s['carry_max_l']} L (largest stretch between refills, incl. 0.5 L reserve); treat stream water"]
    for st in p["stretches"]:
        out.append(f"  - {' -> '.join(st['legs'])}: {st['litres']} L")
    out.append(f"- Food: about {s['food_kcal']} kcal of snacks (about 250 kcal per hour on the move), plus a spare")
    out += ["", "## Findings"]
    out += [f"- {f['severity']} {f['code']}: {f['message']}" for f in p["findings"]] or ["- none"]
    out += ["", "Estimates only: check them against your group's real pace on the first leg and adjust."]
    return "\n".join(out)


def self_test():
    res = []

    def check(name, cond):
        res.append(cond)
        print(("PASS " if cond else "FAIL ") + name)

    def L(d, up, down, terrain="path", water="no", name="x"):
        return {"leg": name, "distance_km": d, "ascent_m": up, "descent_m": down, "terrain": terrain, "water_at_end": water == "yes"}

    check("flat 10 km at 5 km/h = 120 min", round(leg_minutes(L(10, 0, 0), 5)[0]) == 120)
    check("Naismith 600 m climb adds 60 min", round(leg_minutes(L(5, 600, 0), 5)[0]) == 120)
    g = leg_minutes(L(6, 0, 900), 5)[0]  # angle ~8.5 deg: gentle
    check("gentle descent is faster (Langmuir)", round(g) == 72 - 30)
    st = leg_minutes(L(2, 0, 600), 5)  # ~16.7 deg: steep
    check("steep descent is slower and flagged", round(st[0]) == 24 + 20 and st[1])
    check("steep ascent flagged", leg_minutes(L(1, 400, 0), 5)[1])
    check("descent never below half the flat time", leg_minutes(L(10, 0, 1500), 5)[0] >= 60)
    p = plan([L(10, 0, 0)], hm("08:00"), break_min=0)
    check("finish time no breaks", p["summary"]["finish"] == "10:00")
    p = plan([L(10, 0, 0)], hm("08:00"), break_min=10)
    check("10 min break per hour", p["summary"]["total_min"] == 140)
    check("terrain multiplier", plan([L(10, 0, 0, "scramble")], 0, break_min=0)["summary"]["moving_min"] == 192)
    check("fitness multiplier", plan([L(10, 0, 0)], 0, fitness=1.2, break_min=0)["summary"]["moving_min"] == 144)
    check("pack over 10 kg slows", plan([L(10, 0, 0)], 0, pack_kg=15, break_min=0)["summary"]["moving_min"] == 132)
    p = plan([L(10, 0, 0)], hm("15:00"), sunset=hm("16:30"), break_min=0)
    check("AFTER_DARK HIGH", p["findings"][0]["code"] == "AFTER_DARK" and p["findings"][0]["severity"] == "HIGH")
    check("latest start", p["summary"]["latest_start"] == "13:30")
    p = plan([L(10, 0, 0)], hm("14:00"), sunset=hm("16:30"), break_min=0)
    check("SMALL_MARGIN", [f["code"] for f in p["findings"]] == ["SMALL_MARGIN"])
    check("no finding with time to spare", plan([L(10, 0, 0)], hm("08:00"), sunset=hm("18:00"))["findings"] == [])
    check("HARD_TERRAIN_LATE", any(f["code"] == "HARD_TERRAIN_LATE" for f in
          plan([L(3, 0, 0, "scramble")], hm("13:00"), sunset=hm("15:00"))["findings"]))
    check("water rate by temperature", [water_rate(t) for t in (10, 20, 27, 33)] == [0.4, 0.5, 0.75, 1.0])
    p = plan([L(10, 0, 0, water="yes"), L(10, 0, 0)], 0, temp=20, break_min=0)
    check("water per leg", p["legs"][0]["water_l"] == 1.0)
    check("carry = largest stretch + reserve", p["summary"]["carry_max_l"] == 1.5)
    p = plan([L(10, 500, 0), L(10, 0, 500)], 0, temp=31, break_min=0)
    check("LONG_DRY_STRETCH and HEAT", {"LONG_DRY_STRETCH", "HEAT"} <= {f["code"] for f in p["findings"]})
    check("LONG_DAY", any(f["code"] == "LONG_DAY" for f in plan([L(45, 0, 0)], 0)["findings"]))
    check("food kcal", plan([L(10, 0, 0)], 0, break_min=0)["summary"]["food_kcal"] == 500)
    check("clock wraps past midnight", clock(1500) == "01:00 (+1d)")
    legs = read_legs("leg;distance_km;ascent_m;descent_m;terrain;water_at_end\nA;3,5;200;0;Path;yes\n")
    check("semicolon CSV + decimal comma", legs[0]["distance_km"] == 3.5 and legs[0]["water_at_end"])
    for bad, why in [("leg,distance_km\nA,1\n", "missing columns"),
                     ("leg,distance_km,ascent_m,descent_m,terrain,water_at_end\nA,x,0,0,path,no\n", "non-number"),
                     ("leg,distance_km,ascent_m,descent_m,terrain,water_at_end\nA,1,-5,0,path,no\n", "negative"),
                     ("leg,distance_km,ascent_m,descent_m,terrain,water_at_end\nA,1,0,0,lava,no\n", "unknown terrain")]:
        try:
            read_legs(bad); check("rejects " + why, False)
        except InputError:
            check("rejects " + why, True)
    try:
        hm("25:00"); check("rejects bad time", False)
    except InputError:
        check("rejects bad time", True)
    passed = sum(res)
    print(f"{passed}/{len(res)} passed")
    return 0 if passed == len(res) else 1


def main():
    ap = argparse.ArgumentParser(description="Hiking route time and water planner")
    ap.add_argument("csv", nargs="?", help="legs CSV")
    ap.add_argument("--start", help="start time HH:MM")
    ap.add_argument("--sunset", help="sunset time HH:MM")
    ap.add_argument("--pace", type=float, default=5.0, help="flat walking speed km/h (default 5)")
    ap.add_argument("--fitness", type=float, default=1.0, help="time multiplier: 0.85 fast, 1.0 average, 1.2 relaxed, 1.4 with young kids")
    ap.add_argument("--pack-kg", type=float, default=8.0, help="pack weight; +2%% time per kg above 10")
    ap.add_argument("--break-min", type=float, default=10.0, help="break minutes per hour of walking (default 10)")
    ap.add_argument("--temp", type=float, default=18.0, help="expected daytime temperature C")
    ap.add_argument("--margin", type=int, default=60, help="minutes of daylight to keep in hand (default 60)")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args()
    if a.self_test:
        return self_test()
    if not a.csv or not a.start:
        ap.error("give a CSV and --start, or --self-test")
    try:
        with open(a.csv, encoding="utf-8-sig") as fh:
            legs = read_legs(fh.read())
        p = plan(legs, hm(a.start), hm(a.sunset) if a.sunset else None, a.pace, a.fitness, a.pack_kg, a.break_min, a.temp, a.margin)
    except (OSError, InputError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(p, indent=2) if a.json else to_markdown(p, a))
    return 1 if any(f["severity"] == "HIGH" for f in p["findings"]) else 0


if __name__ == "__main__":
sys.exit(main())Reviews nginx.conf and site configs for security problems such as TLS 1.0/1.1, weak ciphers, missing HSTS and security headers, the add_header inheritance trap, alias off-by-slash path traversal, autoindex, unlimited body size, $uri in redirects, HTTP without an HTTPS redirect, open admin paths and logins without rate limits. Gives a fixed config. Includes a stdlib Python checker with --self-test.
---
name: nginx-config-security-reviewer
description: Reviews nginx.conf and site configs for security problems such as TLS 1.0/1.1, weak ciphers, missing HSTS and security headers, the add_header inheritance trap, alias off-by-slash path traversal, autoindex, unlimited body size, $uri in redirects, HTTP without an HTTPS redirect, open admin paths and logins without rate limits. Gives a fixed config. Includes a stdlib Python checker with --self-test.
---

# Nginx Config Security Reviewer

You review nginx configurations the way a careful ops engineer would before a security audit: find the settings that expose data or weaken TLS, explain each one in plain words, and hand back a corrected config that still serves the same routes. You never guess at files you have not seen, and you never tell the user to reload without `nginx -t`.

## Files in this skill

- `scripts/nginx_review.py` - parses nginx config files into blocks and prints findings with severity, line and fix (Python 3 standard library only)
- `references/hardening-checklist.md` - every check the script runs, why it matters and the fix, plus items to check by hand
- `references/tls-and-headers.md` - TLS protocol and cipher settings, HSTS rollout, security headers and how add_header inheritance works
- `templates/review-report.md` - the report you hand back: summary, findings table, config diff, test commands
- `examples/shop-site.conf` - a small shop config from 2019 with 18 findings (3 HIGH)
- `examples/shop-site-fixed.conf` - the same site after the fixes (no findings apart from the include note)

## Workflow

### 1. Collect the full config
Ask for the output of `sudo nginx -T` (it prints the main file and every included file), or for nginx.conf plus the relevant sites-enabled files. Ask what the site does (static, reverse proxy, PHP), which paths must stay public, the nginx version (`nginx -v`) and whether a CDN or load balancer terminates TLS in front of it. Tell the user to remove private keys or secrets before pasting; certificate paths are fine.

### 2. Run the checker
```
python3 scripts/nginx_review.py examples/shop-site.conf
python3 scripts/nginx_review.py /etc/nginx/nginx.conf /etc/nginx/sites-enabled/shop --json
python3 scripts/nginx_review.py --self-test
```
Exit code 1 means HIGH findings, 2 means the file could not be read or parsed (the error names the line).

### 3. Confirm and add manual checks
Read each finding against the user's context: a CDN in front changes TLS findings, an internal-only admin route may already be firewalled, a `return 404` may already hide a path. Then go through the manual items in `references/hardening-checklist.md` (included files, upstream TLS verification, `if` blocks, PHP handlers, file permissions). Drop false positives and say why.

### 4. Deliver
Fill `templates/review-report.md`: HIGH items first, a minimal diff of the config, and the test steps. Explain the add_header inheritance rule whenever ADD_HEADER_INHERITANCE appears, because it surprises most people. Introduce HSTS with a short max-age first if the site has never used it.

## Example result
For `examples/shop-site.conf`: 3 HIGH (TLS 1.0/1.1 enabled, RC4 and 3DES ciphers, `location /images` with `alias .../images/` allowing `/images../` traversal), 6 MEDIUM (unlimited body size, port 80 serving content instead of redirecting, autoindex on /downloads/, /api/ dropping HSTS and nosniff because it sets its own add_header, unprotected /admin/, `$uri` in a redirect), 8 LOW (server_tokens, dotfiles, missing CSP/Referrer-Policy/X-Frame-Options, proxy headers, no rate limit on /api/auth/login) and 1 INFO. `examples/shop-site-fixed.conf` shows the fixes and passes `nginx -t`.

## Rules

- Quote the exact line and the exact replacement; keep changes minimal and route-preserving.
- Always end with `sudo nginx -t && sudo systemctl reload nginx` and a curl check; never suggest a restart that drops connections when a reload works.
- Do not invent directives: check names against the nginx docs for the user's version (for example `http2 on;` needs 1.25.1+, older versions use `listen 443 ssl http2;`).
- Never ask for or repeat private keys, passwords or htpasswd hashes.
- Treat security headers like CSP as a rollout: suggest `Content-Security-Policy-Report-Only` first for complex apps.
FILE:references/hardening-checklist.md
# Nginx Hardening Checklist

Every code the script prints, why it matters and the fix. Severity is the default; raise or lower it with context.

## HIGH

### OLD_TLS_PROTOCOL
`ssl_protocols` lists SSLv3, TLSv1 or TLSv1.1. These are deprecated (RFC 8996), fail PCI DSS and allow downgrade attacks. Fix: `ssl_protocols TLSv1.2 TLSv1.3;` (the default since nginx 1.23.4, so deleting the line also works on new versions). Only very old clients (Android 4.3, IE on Windows 7 without updates) lose access.

### WEAK_CIPHERS
`ssl_ciphers` allows RC4, DES/3DES (SWEET32), MD5, NULL, EXPORT or anonymous (aNULL/ADH) suites. Entries starting with `!` or `-` are exclusions and are fine. Fix: use the Mozilla "intermediate" list from ssl-config.mozilla.org or remove `ssl_ciphers` to use the OpenSSL default, and set `ssl_prefer_server_ciphers off;` when only modern AEAD suites remain.

### NO_CERTIFICATE
A server listens with `ssl` but no `ssl_certificate` is set in it or in http. nginx refuses to start or fails the handshake. Add `ssl_certificate` (full chain) and `ssl_certificate_key`.

### ALIAS_TRAVERSAL (off-by-slash)
`location /images { alias /var/www/media/images/; }`: a request for `/images../secret.txt` maps to `/var/www/media/images/../secret.txt`, so files one level above the alias are readable (a well-known finding in many audits). Fix: both the location and the alias end with a slash, `location /images/ { alias /var/www/media/images/; }`, or use `root` when the path matches the folder name.

## MEDIUM

### HTTP_NO_REDIRECT
A port-80 server with the same server_name as an HTTPS server serves pages instead of redirecting. Users and cookies stay on plain HTTP. Fix:
```
server {
    listen 80;
    server_name shop.example.com;
    location /.well-known/acme-challenge/ { root /var/www/certbot; }
    location / { return 301 https://$host$request_uri; }
}
```

### NO_HSTS
No `Strict-Transport-Security` header on an HTTPS server, so the first request of a session can be downgraded. See `tls-and-headers.md` for the rollout.

### ADD_HEADER_INHERITANCE
nginx inherits `add_header` from the parent level only when the current level has no `add_header` at all. One `add_header Cache-Control no-store;` in `location /api/` drops every security header from the server block for that location. Fix: repeat the headers in that location, or keep them in a snippet (`include snippets/security-headers.conf;`) and include it in every block that has its own add_header. On nginx 1.29.3+ `add_header_inherit merge;` in http makes child blocks add to the parent headers instead of replacing them. `proxy_set_header`, `fastcgi_param` and `proxy_hide_header` follow the same rule.

### AUTOINDEX_ON
Directory listing shows every file name, including backups and exports nobody linked. Turn it off or protect the location.

### ADMIN_OPEN
Paths such as /admin, /phpmyadmin, /actuator, /server-status, /nginx_status or /metrics without allow/deny, auth_basic or auth_request. Fix: `allow 10.20.0.0/16; deny all;` (office or VPN range), or `auth_request` to an SSO service. Basic auth only over HTTPS.

### UNLIMITED_BODY
`client_max_body_size 0` disables the request size limit, making disk and memory exhaustion easy. Keep the default 1m or a real limit in http, and raise it only in the upload location.

### URI_IN_REDIRECT
`$uri` is normalized and URL-decoded, so `%0d%0a` becomes a real line break and an attacker can inject headers (`Set-Cookie`) into the redirect response. Use `$request_uri` (the raw, still-encoded request line) in `return`, `rewrite` targets and `add_header`.

## LOW

### SERVER_TOKENS
The version appears in the `Server` header and on error pages, which helps attackers match known CVEs. `server_tokens off;` in http.

### MISSING_SECURITY_HEADERS
On HTTPS servers: `X-Content-Type-Options nosniff`, `X-Frame-Options` (or CSP `frame-ancestors`), `Content-Security-Policy`, `Referrer-Policy`. Add them with `always` so they are also sent on 4xx/5xx responses.

### SHORT_HSTS
HSTS max-age under 180 days. Fine during rollout; raise it to one year afterwards.

### DOTFILES_EXPOSED
The server serves files but has no rule for hidden files, so `/.git/config`, `/.env` or `/.htpasswd` may be downloadable if they exist under the web root. Fix: `location ~ /\.(?!well-known) { deny all; }` (keeps ACME challenges working).

### NO_RATE_LIMIT
A login, auth or token path without `limit_req`. Add a zone in http and apply it to the location; return 429 with `limit_req_status 429;`.

### PROXY_HEADERS
A `proxy_pass` location that does not send Host, X-Forwarded-For and X-Forwarded-Proto, so the app logs the proxy's IP, builds wrong redirect URLs and may think HTTPS requests are HTTP. Remember the inheritance rule: one `proxy_set_header` in the location replaces all inherited ones.

## INFO

### INCLUDE_NOT_FOLLOWED
The script reads only the files you pass. Ask for `nginx -T` or the included files.

## Check by hand (not automated)
- `proxy_pass https://...` to an upstream on the internet without `proxy_ssl_verify on;` and `proxy_ssl_trusted_certificate`.
- PHP: `location ~ \.php$` must use `try_files $uri =404;` (or `fastcgi_split_path_info` with a check) so uploaded images cannot run as PHP; uploads directories should never pass to PHP.
- `if` inside location with anything other than `return` or `rewrite ... last` ("if is evil").
- `default_server` blocks: an unknown Host should get `return 444;` with a self-signed or `ssl_reject_handshake on;` (1.19.4+) instead of the first site.
- Permissions: nginx workers should not be able to write the web root; private keys `chmod 600`, owned by root.
- Large headers / slow clients: `client_body_timeout`, `client_header_timeout`, `large_client_header_buffers` for public APIs under attack.
- Logging: access logs must not record tokens in query strings; use a custom log_format if needed.
FILE:references/tls-and-headers.md
# TLS and Security Headers

## TLS settings that pass most audits (nginx 1.25+ with OpenSSL 1.1.1 or 3.x)
```
ssl_protocols TLSv1.2 TLSv1.3;
ssl_ciphers ECDHE-ECDSA-AES128-GCM-SHA256:ECDHE-RSA-AES128-GCM-SHA256:ECDHE-ECDSA-AES256-GCM-SHA384:ECDHE-RSA-AES256-GCM-SHA384:ECDHE-ECDSA-CHACHA20-POLY1305:ECDHE-RSA-CHACHA20-POLY1305:DHE-RSA-AES128-GCM-SHA256:DHE-RSA-AES256-GCM-SHA384;
ssl_prefer_server_ciphers off;
ssl_session_timeout 1d;
ssl_session_cache shared:SSL:10m;
ssl_session_tickets off;
```
This is the Mozilla "intermediate" profile. TLS 1.3 suites are not set with ssl_ciphers (OpenSSL handles them). If DHE suites stay, provide `ssl_dhparam` with at least 2048 bits or drop the DHE entries.

OCSP stapling (`ssl_stapling on; ssl_stapling_verify on;`) is optional; Let's Encrypt ended OCSP support in 2025, so do not add it for LE certificates.

HTTP/2: `http2 on;` inside the server on nginx 1.25.1+; older versions use `listen 443 ssl http2;`.

## HSTS rollout
1. Make sure every subdomain works over HTTPS.
2. Start short: `add_header Strict-Transport-Security "max-age=300" always;`
3. After a week without problems: `max-age=31536000; includeSubDomains`.
4. Only add `preload` and submit to hstspreload.org when you are sure; removal takes months.
HSTS on plain HTTP responses is ignored by browsers, so set it on the 443 server.

## Security headers
| Header | Typical value | Notes |
|---|---|---|
| X-Content-Type-Options | `nosniff` | Stops MIME sniffing of uploads |
| X-Frame-Options | `DENY` or `SAMEORIGIN` | Clickjacking; CSP `frame-ancestors` is the modern equivalent |
| Content-Security-Policy | `default-src 'self'` and more | App-specific; roll out with `Content-Security-Policy-Report-Only` |
| Referrer-Policy | `strict-origin-when-cross-origin` | Keeps paths and query strings out of other sites' logs |
| Permissions-Policy | `camera=(), microphone=(), geolocation=()` | Optional |
Add `always` so headers are also sent on error responses.

## The add_header inheritance rule
```
server {
    add_header X-Content-Type-Options nosniff always;   # A
    location / { }                                      # gets A
    location /api/ {
        add_header Cache-Control no-store;              # gets ONLY this one, A is gone
    }
}
```
A block inherits add_header from its parent only if it defines none itself. Keep shared headers in a snippet and include it in every block that adds its own. nginx 1.29.3 (October 2025) added `add_header_inherit merge;`, which makes nested blocks add to the inherited headers; check `nginx -v` before suggesting it (Debian 13 ships 1.26).

## Testing
```
sudo nginx -t && sudo systemctl reload nginx
curl -sI https://shop.example.com/ | grep -iE 'strict|x-content|x-frame|content-security|referrer|server:'
curl -sI http://shop.example.com/page?x=1        # expect 301 to https://shop.example.com/page?x=1
curl -s -o /dev/null -w '%{http_code}\n' https://shop.example.com/.git/config   # expect 403 or 404
curl -s -o /dev/null -w '%{http_code}\n' https://shop.example.com/images../      # expect 404 after the alias fix
openssl s_client -connect shop.example.com:443 -tls1_1 </dev/null   # expect a handshake failure
```
For a full external check: SSL Labs server test or `testssl.sh shop.example.com`.
FILE:templates/review-report.md
# Nginx security review: <site or server name>

**Version:** <nginx 1.26.3, OpenSSL 3.x>   **Role:** <static site / reverse proxy to Node on :3000 / PHP-FPM>
**Files reviewed:** <nginx -T output, 2 files>   **TLS terminated by:** <nginx / CDN / load balancer>
**Summary:** <one sentence: the most serious problem and what the fix changes>

## Findings
| # | Severity | Code | File:line | Problem | Fix |
|---|---|---|---|---|---|
| 1 | HIGH | <ALIAS_TRAVERSAL> | <nginx.conf:51> | <location /images allows /images../> | <location /images/ { alias .../images/; }> |
| 2 | <MEDIUM> | <...> | <...> | <...> | <...> |

## Not changed (with reason)
- <ADMIN_OPEN on /admin/: already limited by the cloud firewall to the VPN; added deny all anyway? yes/no>

## Config changes
```diff
- ssl_protocols TLSv1 TLSv1.1 TLSv1.2;
+ ssl_protocols TLSv1.2 TLSv1.3;
```

## Apply and test
1. Back up: `sudo cp -a /etc/nginx /etc/nginx.bak-<date>`
2. Edit, then `sudo nginx -t && sudo systemctl reload nginx`
3. Checks:
   - `curl -sI https://<host>/` shows the security headers
   - `curl -sI http://<host>/x?y=1` returns 301 to the same path on https
   - <path traversal / dotfile / admin checks from the findings>
4. Roll back: restore the backup and reload.

## Follow-ups
- <HSTS: raise max-age to 31536000 after <date>>
- <CSP: move from Report-Only to enforcing after reviewing reports>
FILE:examples/shop-site.conf
# /etc/nginx/nginx.conf for shop.example.com (single-file setup)
# A small online shop: static storefront, product images, a Node.js API on :3000
# and a legacy admin panel. Written in 2019, certificates renewed by certbot.

user www-data;
worker_processes auto;

events {
    worker_connections 1024;
}

http {
    include /etc/nginx/mime.types;
    sendfile on;
    keepalive_timeout 65;
    client_max_body_size 0;

    ssl_protocols TLSv1 TLSv1.1 TLSv1.2;
    ssl_ciphers "HIGH:RC4-SHA:DES-CBC3-SHA:!aNULL";
    ssl_prefer_server_ciphers on;

    server {
        listen 80;
        server_name shop.example.com www.shop.example.com;
        root /var/www/shop;

        location /.well-known/acme-challenge/ {
            root /var/www/certbot;
        }
    }

    server {
        listen 443 ssl;
        http2 on;
        server_name shop.example.com www.shop.example.com;

        ssl_certificate /etc/letsencrypt/live/shop.example.com/fullchain.pem;
        ssl_certificate_key /etc/letsencrypt/live/shop.example.com/privkey.pem;

        add_header Strict-Transport-Security "max-age=31536000" always;
        add_header X-Content-Type-Options nosniff always;

        root /var/www/shop;
        index index.html;

        location / {
            try_files $uri $uri/ /index.html;
        }

        location /images {
            alias /var/www/shop-media/images/;
        }

        location /downloads/ {
            alias /var/www/shop-media/downloads/;
            autoindex on;
        }

        location /api/ {
            add_header Cache-Control "no-store";
            proxy_pass http://127.0.0.1:3000;
        }

        location /api/auth/login {
            proxy_pass http://127.0.0.1:3000;
            proxy_set_header Host $host;
        }

        location /admin/ {
            proxy_pass http://127.0.0.1:8080/;
        }

        location /old-blog {
            return 301 https://blog.example.com$uri;
        }
    }
}
FILE:examples/shop-site-fixed.conf
# shop.example.com after the review: same routes, hardened.
# Shared security headers live in one snippet so locations with their own
# add_header can include it again (add_header is not inherited into a block
# that sets any add_header of its own).

user www-data;
worker_processes auto;

events {
    worker_connections 1024;
}

http {
    include /etc/nginx/mime.types;
    sendfile on;
    keepalive_timeout 65;
    server_tokens off;
    client_max_body_size 10m;

    ssl_protocols TLSv1.2 TLSv1.3;
    ssl_prefer_server_ciphers off;
    ssl_session_timeout 1d;
    ssl_session_cache shared:SSL:10m;

    limit_req_zone $binary_remote_addr zone=login:10m rate=5r/m;

    server {
        listen 80;
        server_name shop.example.com www.shop.example.com;

        location /.well-known/acme-challenge/ {
            root /var/www/certbot;
        }

        location / {
            return 301 https://$host$request_uri;
        }
    }

    server {
        listen 443 ssl;
        http2 on;
        server_name shop.example.com www.shop.example.com;

        ssl_certificate /etc/letsencrypt/live/shop.example.com/fullchain.pem;
        ssl_certificate_key /etc/letsencrypt/live/shop.example.com/privkey.pem;

        # same lines as /etc/nginx/snippets/security-headers.conf
        add_header Strict-Transport-Security "max-age=31536000; includeSubDomains" always;
        add_header X-Content-Type-Options nosniff always;
        add_header X-Frame-Options SAMEORIGIN always;
        add_header Content-Security-Policy "default-src 'self'; img-src 'self' data:; frame-ancestors 'self'" always;
        add_header Referrer-Policy strict-origin-when-cross-origin always;

        proxy_set_header Host $host;
        proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
        proxy_set_header X-Forwarded-Proto $scheme;

        root /var/www/shop;
        index index.html;

        location ~ /\.(?!well-known) {
            deny all;
        }

        location / {
            try_files $uri $uri/ /index.html;
        }

        location /images/ {
            alias /var/www/shop-media/images/;
        }

        location /downloads/ {
            alias /var/www/shop-media/downloads/;
        }

        location /api/ {
            add_header Cache-Control "no-store" always;
            add_header Strict-Transport-Security "max-age=31536000; includeSubDomains" always;
            add_header X-Content-Type-Options nosniff always;
            add_header X-Frame-Options SAMEORIGIN always;
            add_header Content-Security-Policy "default-src 'self'; img-src 'self' data:; frame-ancestors 'self'" always;
            add_header Referrer-Policy strict-origin-when-cross-origin always;
            proxy_pass http://127.0.0.1:3000;
        }

        location /api/auth/login {
            limit_req zone=login burst=5 nodelay;
            proxy_pass http://127.0.0.1:3000;
        }

        location /admin/ {
            allow 10.20.0.0/16;
            deny all;
            proxy_pass http://127.0.0.1:8080/;
        }

        location /old-blog {
            return 301 https://blog.example.com$request_uri;
        }
    }
}
FILE:scripts/nginx_review.py
#!/usr/bin/env python3
"""Nginx config security reviewer (Python 3 standard library only).

Parses nginx.conf / sites-available files into a block tree and flags common
security and hardening problems: old TLS protocols, weak ciphers, missing HSTS
and security headers, the add_header inheritance trap, alias off-by-slash path
traversal, autoindex, unlimited body size, $uri in redirects (CRLF injection),
plain-HTTP servers without a redirect, open admin paths, login paths without
rate limiting, exposed dotfiles and proxies without forwarding headers.

Usage:
  python3 nginx_review.py site.conf [more.conf ...] [--json]
  python3 nginx_review.py --self-test
Exit codes: 0 = no HIGH findings, 1 = HIGH findings, 2 = unreadable/unparseable input.
"""
import argparse, json, re, sys

SEV_ORDER = {"HIGH": 0, "MEDIUM": 1, "LOW": 2, "INFO": 3}
OLD_PROTOCOLS = {"SSLv2", "SSLv3", "TLSv1", "TLSv1.1"}
WEAK_CIPHER_WORDS = ["RC4", "DES", "3DES", "MD5", "NULL", "EXPORT", "EXP-", "aNULL", "eNULL", "ADH", "AECDH"]
SECURITY_HEADERS = {
    "x-content-type-options": "X-Content-Type-Options nosniff",
    "x-frame-options": "X-Frame-Options DENY or SAMEORIGIN (or CSP frame-ancestors)",
    "content-security-policy": "Content-Security-Policy",
    "referrer-policy": "Referrer-Policy strict-origin-when-cross-origin",
}
LOGIN_RE = re.compile(r"login|signin|sign-in|auth|token|password|wp-login", re.I)
ADMIN_RE = re.compile(r"admin|phpmyadmin|actuator|server-status|nginx_status|/metrics|wp-admin", re.I)


class ParseError(Exception):
    pass


class Node:
    def __init__(self, name, args, line, children=None):
        self.name, self.args, self.line, self.children = name, args, line, children

    def get(self, name):
        return [c for c in (self.children or []) if c.name == name]

    def first(self, name):
        found = self.get(name)
        return found[0] if found else None

    def walk(self):
        for c in self.children or []:
            yield c
            if c.children is not None:
                yield from c.walk()


def tokenize(text):
    tokens, i, line, n = [], 0, 1, len(text)
    while i < n:
        ch = text[i]
        if ch == "\n":
            line += 1; i += 1
        elif ch.isspace():
            i += 1
        elif ch == "#":
            while i < n and text[i] != "\n":
                i += 1
        elif ch in "{};":
            tokens.append((ch, line, True)); i += 1
        elif ch in "\"'":
            q, j, buf = ch, i + 1, []
            while j < n and text[j] != q:
                if text[j] == "\\" and j + 1 < n:
                    buf.append(text[j + 1]); j += 2; continue
                if text[j] == "\n":
                    line += 1
                buf.append(text[j]); j += 1
            if j >= n:
                raise ParseError(f"line {line}: unterminated quote")
            tokens.append(("".join(buf), line, False)); i = j + 1
        else:
            j = i
            while j < n and not text[j].isspace() and text[j] not in "{};":
                if text[j] == "$" and j + 1 < n and text[j + 1] == "{":  # var
                    k = text.find("}", j)
                    j = k + 1 if k != -1 else n
                    continue
                j += 1
            tokens.append((text[i:j], line, False)); i = j
    return tokens


def parse(text):
    tokens = tokenize(text)
    root = Node("main", [], 0, [])
    stack, cur = [root], []
    for tok, line, special in tokens:
        if special and tok == ";":
            if not cur:
                continue
            stack[-1].children.append(Node(cur[0][0], [t for t, _ in cur[1:]], cur[0][1]))
            cur = []
        elif special and tok == "{":
            if not cur:
                raise ParseError(f"line {line}: '{{' without a directive name")
            node = Node(cur[0][0], [t for t, _ in cur[1:]], cur[0][1], [])
            stack[-1].children.append(node); stack.append(node); cur = []
        elif special and tok == "}":
            if cur:
                raise ParseError(f"line {line}: missing ';' before '}}'")
            if len(stack) == 1:
                raise ParseError(f"line {line}: unexpected '}}'")
            stack.pop()
        else:
            cur.append((tok, line))
    if cur:
        raise ParseError(f"line {cur[0][1]}: directive '{cur[0][0]}' not terminated with ';'")
    if len(stack) != 1:
        raise ParseError(f"block '{stack[-1].name}' opened on line {stack[-1].line} is not closed")
    return root


def headers_of(node):
    return {d.args[0].lower(): d for d in node.get("add_header") if d.args}


def is_tls(server):
    for l in server.get("listen"):
        if "ssl" in l.args or "quic" in l.args or any(a.endswith(":443") or a == "443" for a in l.args):
            return True
    s = server.first("ssl")
    return bool(s and s.args and s.args[0] == "on")


def listens_plain(server):
    ls = server.get("listen")
    if not ls:
        return True  # default listen *:80
    for l in ls:
        if not ("ssl" in l.args or "quic" in l.args or any(a.endswith(":443") or a == "443" for a in l.args)):
            return True
    return False


def names(server):
    out = []
    for d in server.get("server_name"):
        out.extend(d.args)
    return set(out) or {"_"}


def inherited(scopes, name):
    """Value of a directive as nginx inherits it: innermost scope that sets it."""
    for s in reversed(scopes):
        d = s.first(name)
        if d is not None:
            return d
    return None


def effective_headers(scopes):
    for s in reversed(scopes):
        h = headers_of(s)
        if h:
            return h
    return {}


def review(text, fname="nginx.conf"):
    root = parse(text)
    http = root.first("http")
    top = http if http is not None else root
    base = [root] + ([http] if http is not None else [])
    servers = [s for s in top.get("server")]
    findings = []

    def add(sev, code, line, msg, fix):
        findings.append({"severity": sev, "code": code, "file": fname, "line": line, "message": msg, "fix": fix})

    for d in root.walk():
        if d.name == "include":
            add("INFO", "INCLUDE_NOT_FOLLOWED", d.line, f"include {' '.join(d.args)} is not read by this checker",
                "Review the included files too (pass them as extra arguments) or paste `nginx -T` output.")

    tokens = [d for d in root.walk() if d.name == "server_tokens"]
    if not any(d.args and d.args[0] == "off" for d in tokens):
        add("LOW", "SERVER_TOKENS", (http or root).line, "server_tokens is not off, so error pages and the Server header show the nginx version",
            "Add `server_tokens off;` in the http block.")

    tls_names = set()
    for s in servers:
        if is_tls(s):
            tls_names |= names(s)

    for s in servers:
        scopes = base + [s]
        label = " ".join(sorted(names(s)))
        tls = is_tls(s)
        if tls:
            if inherited(scopes, "ssl_certificate") is None:
                add("HIGH", "NO_CERTIFICATE", s.line, f"TLS server {label} has no ssl_certificate in scope",
                    "Add ssl_certificate and ssl_certificate_key (fullchain + key).")
            proto = inherited(scopes, "ssl_protocols")
            if proto is not None:
                old = [p for p in proto.args if p in OLD_PROTOCOLS]
                if old:
                    add("HIGH", "OLD_TLS_PROTOCOL", proto.line, f"{label}: ssl_protocols enables {', '.join(old)}",
                        "Use `ssl_protocols TLSv1.2 TLSv1.3;` (SSLv3/TLS 1.0/1.1 are deprecated, RFC 8996).")
            ciph = inherited(scopes, "ssl_ciphers")
            if ciph is not None and ciph.args:
                parts = re.split(r"[:\s]+", " ".join(ciph.args))
                weak = sorted({w for p in parts if p and not p.startswith("!") and not p.startswith("-")
                               for w in WEAK_CIPHER_WORDS if w.lower() in p.lower()})
                if weak:
                    add("HIGH", "WEAK_CIPHERS", ciph.line, f"{label}: ssl_ciphers allows weak suites ({', '.join(weak)})",
                        "Use the Mozilla 'intermediate' cipher list, or remove ssl_ciphers to use the safe OpenSSL default.")
            hdrs = effective_headers(scopes)
            if "strict-transport-security" not in hdrs:
                add("MEDIUM", "NO_HSTS", s.line, f"TLS server {label} sends no Strict-Transport-Security header",
                    'Add `add_header Strict-Transport-Security "max-age=31536000; includeSubDomains" always;` (start with a short max-age).')
            else:
                hsts = hdrs["strict-transport-security"]
                m = re.search(r"max-age=(\d+)", " ".join(hsts.args), re.I)
                if m and int(m.group(1)) < 15552000:
                    add("LOW", "SHORT_HSTS", hsts.line, f"{label}: HSTS max-age {m.group(1)} is under 180 days",
                        "Raise max-age to 31536000 once HTTPS works everywhere.")
            missing = [v for k, v in SECURITY_HEADERS.items() if k not in hdrs]
            if "x-frame-options" not in hdrs and "content-security-policy" in hdrs and \
                    "frame-ancestors" in " ".join(hdrs["content-security-policy"].args):
                missing = [v for v in missing if not v.startswith("X-Frame")]
            if missing:
                add("LOW", "MISSING_SECURITY_HEADERS", s.line, f"{label}: missing {'; '.join(missing)}",
                    "Add them with `always` in the server block (check the inheritance rule for locations).")
        elif listens_plain(s) and names(s) & tls_names:
            redirects = any(r.args and r.args[0] in ("301", "302", "307", "308") and len(r.args) > 1 and r.args[1].startswith("https://")
                            for r in [d for d in s.walk() if d.name == "return"])
            rewrites = any(len(r.args) > 1 and r.args[1].startswith("https://") for r in [d for d in s.walk() if d.name == "rewrite"])
            if not (redirects or rewrites):
                add("MEDIUM", "HTTP_NO_REDIRECT", s.line, f"plain-HTTP server {label} serves content instead of redirecting to HTTPS",
                    "Use `return 301 https://$host$request_uri;` in the port-80 server (keep only /.well-known/acme-challenge/ if needed).")

        server_hdrs = effective_headers(scopes)
        has_dot_rule = False
        locations = [d for d in s.walk() if d.name == "location"]
        for loc in locations:
            path = loc.args[-1] if loc.args else ""
            mod = loc.args[0] if len(loc.args) > 1 else ""
            if mod in ("~", "~*") and (r"/\." in path or path.startswith(r"\.") or r"(^|/)\." in path):
                if loc.get("deny") or any(r.args and r.args[0] in ("403", "404") for r in loc.get("return")):
                    has_dot_rule = True
            own = headers_of(loc)
            hi = inherited(scopes + [loc], "add_header_inherit")
            merge = bool(hi and hi.args and hi.args[0] == "merge")  # nginx 1.29.3+
            if own and server_hdrs and not merge:
                lost = sorted(set(server_hdrs) - set(own))
                if lost:
                    add("MEDIUM", "ADD_HEADER_INHERITANCE", loc.line,
                        f"location {path} has its own add_header, so it silently drops {', '.join(lost)} set at server/http level",
                        "Repeat those headers in this location, include a shared headers snippet, or on nginx 1.29.3+ set `add_header_inherit merge;`.")
            al = loc.first("alias")
            if al and al.args and mod in ("", "^~") and not path.endswith("/") and al.args[0].endswith("/"):
                add("HIGH", "ALIAS_TRAVERSAL", al.line,
                    f"location {path} (no trailing slash) with alias {al.args[0]} (trailing slash) allows {path}../ path traversal",
                    f"Make both end with a slash: `location {path}/ {{ alias {al.args[0]}; }}`.")
            ai = loc.first("autoindex")
            if ai and ai.args and ai.args[0] == "on":
                add("MEDIUM", "AUTOINDEX_ON", ai.line, f"autoindex on in location {path} lists directory contents",
                    "Turn it off, or restrict the location with allow/deny or auth_basic.")
            if ADMIN_RE.search(path):
                guarded = loc.get("deny") or loc.get("auth_basic") or loc.get("auth_request") or loc.get("satisfy") \
                    or any(r.args and r.args[0] in ("403", "404", "444") for r in loc.get("return"))
                if not guarded:
                    add("MEDIUM", "ADMIN_OPEN", loc.line, f"location {path} looks like an admin/status endpoint with no allow/deny or auth",
                        "Add `allow <office/VPN range>; deny all;` or auth_basic/auth_request, or remove the route.")
            if LOGIN_RE.search(path) and not inherited(scopes + [loc], "limit_req"):
                add("LOW", "NO_RATE_LIMIT", loc.line, f"location {path} looks like a login/auth endpoint without limit_req",
                    "Define `limit_req_zone $binary_remote_addr zone=login:10m rate=5r/m;` in http and `limit_req zone=login burst=5 nodelay;` here.")
            if loc.first("proxy_pass"):
                ph = set()
                for sc in reversed(scopes + [loc]):  # like add_header: innermost level that sets any wins
                    if sc.get("proxy_set_header"):
                        ph = {d.args[0].lower() for d in sc.get("proxy_set_header") if d.args}
                        break
                miss = [h for h in ("host", "x-forwarded-for", "x-forwarded-proto") if h not in ph]
                if miss:
                    add("LOW", "PROXY_HEADERS", loc.line, f"location {path} proxies without {', '.join(miss)}",
                        "Set proxy_set_header Host $host; X-Forwarded-For $proxy_add_x_forwarded_for; X-Forwarded-Proto $scheme; (note: any proxy_set_header in a location replaces inherited ones).")
        serves_files = inherited(scopes, "root") or any(
            (l.first("root") or l.first("alias")) and not (l.args and l.args[-1].startswith("/.well-known/")) for l in locations)
        if serves_files and not has_dot_rule:
            add("LOW", "DOTFILES_EXPOSED", s.line, f"{label}: no rule blocks hidden files such as /.git/ or /.env",
                r"Add `location ~ /\.(?!well-known) { deny all; }`.")

    for d in root.walk():
        if d.name == "client_max_body_size" and d.args and d.args[0] in ("0", "0m", "0k"):
            add("MEDIUM", "UNLIMITED_BODY", d.line, "client_max_body_size 0 disables the request body limit",
                "Set a real limit (e.g. 10m, or larger only in the upload location).")
        if d.name in ("return", "rewrite", "add_header") and any(re.search(r"\$uri\b|\$document_uri\b", a) for a in d.args):
            add("MEDIUM", "URI_IN_REDIRECT", d.line, f"{d.name} uses $uri (decoded, may contain CR/LF), which allows header injection",
                "Use $request_uri (raw, still encoded) in redirects and headers.")
    findings.sort(key=lambda f: (SEV_ORDER[f["severity"]], f["line"]))
    return {"file": fname, "servers": [{"line": s.line, "names": sorted(names(s)), "tls": is_tls(s)} for s in servers],
            "findings": findings}


def to_markdown(results):
    out = ["# Nginx config security review", ""]
    allf = [f for r in results for f in r["findings"]]
    counts = {k: sum(1 for f in allf if f["severity"] == k) for k in SEV_ORDER}
    out.append("Findings: " + ", ".join(f"{v} {k}" for k, v in counts.items()))
    for r in results:
        out += ["", f"## {r['file']}", "", "| Server | Line | TLS |", "|---|---|---|"]
        for s in r["servers"]:
            out.append(f"| {' '.join(s['names'])} | {s['line']} | {'yes' if s['tls'] else 'no'} |")
        out += ["", "| Severity | Code | Line | Problem | Fix |", "|---|---|---|---|---|"]
        for f in r["findings"]:
            out.append(f"| {f['severity']} | {f['code']} | {f['line']} | {f['message']} | {f['fix']} |")
        if not r["findings"]:
            out.append("| - | - | - | no findings | - |")
    out += ["", "Always run `nginx -t` before reloading, and test with `curl -sI https://<host>/` afterwards."]
    return "\n".join(out)


def self_test():
    results = []

    def check(name, cond):
        results.append(cond)
        print(("PASS " if cond else "FAIL ") + name)

    def codes(conf):
        return [f["code"] for f in review(conf)["findings"]]

    good = """
    http {
      server_tokens off;
      limit_req_zone $binary_remote_addr zone=login:10m rate=5r/m;
      server { listen 80; server_name a.test; return 301 https://$host$request_uri; }
      server {
        listen 443 ssl; http2 on; server_name a.test;
        ssl_certificate /c.pem; ssl_certificate_key /k.pem;
        ssl_protocols TLSv1.2 TLSv1.3;
        add_header Strict-Transport-Security "max-age=31536000; includeSubDomains" always;
        add_header X-Content-Type-Options nosniff always;
        add_header Content-Security-Policy "default-src 'self'; frame-ancestors 'none'" always;
        add_header Referrer-Policy strict-origin-when-cross-origin always;
        root /srv/www;
        location ~ /\\.(?!well-known) { deny all; }
        location /static/ { alias /srv/static/; }
        location /login { limit_req zone=login burst=5 nodelay; proxy_pass http://app;
          proxy_set_header Host $host; proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
          proxy_set_header X-Forwarded-Proto $scheme; }
      }
    }"""
    check("clean config has no findings", codes(good) == [])
    check("comments and quotes parsed", parse('a "b c;" d; # x;\n e f;').children[0].args == ["b c;", "d"])
    check("var token kept", parse("set $x hosta;").children[0].args == ["$x", "hosta"])
    for bad, msg in [("server { listen 80;", "unclosed block"), ("a b", "missing ;"), ("}", "stray brace"), ('a "b;', "unterminated quote")]:
        try:
            parse(bad); check("parse error: " + msg, False)
        except ParseError:
            check("parse error: " + msg, True)
    check("SERVER_TOKENS when missing", "SERVER_TOKENS" in codes("http { server { listen 80; } }"))
    tls = "server { listen 443 ssl; server_name b.test; ssl_certificate /c; %s }"
    check("OLD_TLS_PROTOCOL", "OLD_TLS_PROTOCOL" in codes(tls % "ssl_protocols TLSv1 TLSv1.2;"))
    check("TLSv1.2 alone fine", "OLD_TLS_PROTOCOL" not in codes(tls % "ssl_protocols TLSv1.2;"))
    check("WEAK_CIPHERS", "WEAK_CIPHERS" in codes(tls % "ssl_ciphers 'HIGH:RC4-SHA:DES-CBC3-SHA';"))
    check("excluded !RC4 is fine", "WEAK_CIPHERS" not in codes(tls % "ssl_ciphers 'HIGH:!aNULL:!MD5:!RC4';"))
    check("NO_CERTIFICATE", "NO_CERTIFICATE" in codes("server { listen 443 ssl; }"))
    check("cert inherited from http", "NO_CERTIFICATE" not in codes("http { ssl_certificate /c; server { listen 443 ssl; } }"))
    check("NO_HSTS", "NO_HSTS" in codes(tls % ""))
    check("SHORT_HSTS", "SHORT_HSTS" in codes(tls % 'add_header Strict-Transport-Security "max-age=300";'))
    check("MISSING_SECURITY_HEADERS", "MISSING_SECURITY_HEADERS" in codes(tls % ""))
    inh = tls % 'add_header Strict-Transport-Security "max-age=31536000"; location /api/ { add_header Cache-Control no-store; }'
    r = review(inh)["findings"]
    check("ADD_HEADER_INHERITANCE names lost header",
          any(f["code"] == "ADD_HEADER_INHERITANCE" and "strict-transport-security" in f["message"] for f in r))
    check("headers inherited when location has none", "ADD_HEADER_INHERITANCE" not in codes(
        tls % 'add_header Strict-Transport-Security "max-age=31536000"; location /api/ { proxy_pass http://x; }'))
    check("add_header_inherit merge respected", "ADD_HEADER_INHERITANCE" not in codes(
        tls % 'add_header_inherit merge; add_header Strict-Transport-Security "max-age=31536000"; location /api/ { add_header Cache-Control no-store; }'))
    check("ALIAS_TRAVERSAL", "ALIAS_TRAVERSAL" in codes("server { location /img { alias /srv/img/; } }"))
    check("alias with matching slashes fine", "ALIAS_TRAVERSAL" not in codes("server { location /img/ { alias /srv/img/; } }"))
    check("regex location alias not flagged", "ALIAS_TRAVERSAL" not in codes(r"server { location ~ ^/img/(.*)$ { alias /srv/img/$1; } }"))
    check("AUTOINDEX_ON", "AUTOINDEX_ON" in codes("server { location /files/ { autoindex on; } }"))
    check("HTTP_NO_REDIRECT", "HTTP_NO_REDIRECT" in codes(
        "server { listen 80; server_name c.test; root /x; } server { listen 443 ssl; server_name c.test; ssl_certificate /c; }"))
    check("no HTTP_NO_REDIRECT for unrelated name", "HTTP_NO_REDIRECT" not in codes(
        "server { listen 80; server_name d.test; } server { listen 443 ssl; server_name c.test; ssl_certificate /c; }"))
    check("ADMIN_OPEN", "ADMIN_OPEN" in codes("server { location /admin/ { proxy_pass http://x; } }"))
    check("admin with deny fine", "ADMIN_OPEN" not in codes("server { location /admin/ { allow 10.0.0.0/8; deny all; } }"))
    check("NO_RATE_LIMIT", "NO_RATE_LIMIT" in codes("server { location /api/login { proxy_pass http://x; } }"))
    check("rate limit inherited from server", "NO_RATE_LIMIT" not in codes(
        "server { limit_req zone=z; location /api/login { proxy_pass http://x; } }"))
    check("PROXY_HEADERS", "PROXY_HEADERS" in codes("server { location / { proxy_pass http://x; } }"))
    check("proxy_set_header in location replaces inherited", "PROXY_HEADERS" in codes(
        "server { proxy_set_header Host $host; proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for; "
        "proxy_set_header X-Forwarded-Proto $scheme; location / { proxy_set_header Upgrade $http_upgrade; proxy_pass http://x; } }"))
    check("DOTFILES_EXPOSED", "DOTFILES_EXPOSED" in codes("server { root /srv; }"))
    check("ACME-only port 80 server not flagged for dotfiles", "DOTFILES_EXPOSED" not in codes(
        "server { listen 80; location /.well-known/acme-challenge/ { root /var/www/certbot; } location / { return 301 https://$host$request_uri; } }"))
    check("UNLIMITED_BODY", "UNLIMITED_BODY" in codes("http { client_max_body_size 0; }"))
    check("URI_IN_REDIRECT", "URI_IN_REDIRECT" in codes("server { return 301 https://$host$uri; }"))
    check("$request_uri fine", "URI_IN_REDIRECT" not in codes("server { return 301 https://$host$request_uri; }"))
    check("INCLUDE_NOT_FOLLOWED", "INCLUDE_NOT_FOLLOWED" in codes("http { include /etc/nginx/conf.d/*.conf; }"))
    check("findings sorted HIGH first", review("server { listen 443 ssl; location /files/ { autoindex on; } }")["findings"][0]["severity"] == "HIGH")
    passed = sum(results)
    print(f"{passed}/{len(results)} passed")
    return 0 if passed == len(results) else 1


def main():
    ap = argparse.ArgumentParser(description="Nginx config security reviewer")
    ap.add_argument("files", nargs="*", help="nginx config files (nginx.conf, sites-available/*, or `nginx -T` output)")
    ap.add_argument("--json", action="store_true", help="print JSON instead of Markdown")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args()
    if a.self_test:
        return self_test()
    if not a.files:
        ap.error("give at least one config file, or --self-test")
    results = []
    for f in a.files:
        try:
            with open(f, encoding="utf-8") as fh:
                results.append(review(fh.read(), f))
        except (OSError, UnicodeDecodeError, ParseError) as e:
            print(f"error: {f}: {e}", file=sys.stderr)
            return 2
    print(json.dumps(results, indent=2) if a.json else to_markdown(results))
    return 1 if any(f["severity"] == "HIGH" for r in results for f in r["findings"]) else 0


if __name__ == "__main__":
sys.exit(main())Build an image-ready and motion-ready brief for one hero shot of a red-roofed white church on a grassy headland above an Icelandic black sand beach with basalt sea stacks at golden hour: church, beach and surf, sea stacks, light, fixed details, a motion map, and two prompt seeds: a 16:9 still image and an image-to-video animation.
Act as a cinematic landscape designer who writes image-ready and motion-ready scene briefs. Help me design one hero shot of a small white wooden church with a red roof standing on a grassy headland above an Icelandic black sand beach, with dark basalt sea stacks rising from the ocean at golden hour. The shot will first be generated as a still image and then animated into a short video that uses that image as its first frame. Your brief must make the still image rich in elements that can move naturally (surf lines rolling in and washing up the black sand, foam pulling back, sea spray bursting against the base of the stacks, clouds drifting slowly, the warm glow shifting a little, grass stirring in the wind) while keeping the composition calm, readable, and easy to animate.

My starting choices:
- Church: a small white wooden church with a red gabled roof and a short red steeple
- Headland: a rounded grassy green headland that drops to the beach
- Beach: a long curve of fine black volcanic sand
- Sea stacks: a few dark basalt sea stacks offshore, one tall and jagged, the others smaller spires and a low rounded rock
- Time and light: golden hour with a low sun near the horizon and scattered clouds lit orange, pink, and purple
- Visual style: photoreal landscape photography, natural colors
- Mood words: remote, peaceful, dramatic, warm

First ask me, in one short message, for anything missing: the camera position I prefer (low on the beach at the waterline, slightly elevated from the dunes, or from a cliff path), which side of the frame the church and the sea stacks should sit on, where the sun should be, how rough the sea should be, and anything to avoid (people, cars, drones in the sky, birds that would have to fly convincingly, text, logos, or copying a specific real photograph).

Then produce the brief with these sections:

1. **Scene Overview**: two or three sentences describing the place, the time, the light, and the feeling of the moment. Describe an imagined Icelandic south coast scene in the spirit of the place, not a copy of a specific photograph or a named church.

2. **Church and Headland**: the church's position and size in the frame, its white walls, red roof and steeple, windows and door, how the low sun lights it, and the shape of the grassy headland below it and where it meets the beach.

3. **Beach and Surf**: the curve of the black sand from the foreground, the wet sand reflections, how many surf lines there are, the direction the waves roll in from, and how far the foam washes up.

4. **Sea Stacks and Depth**: how many stacks, their shapes and heights, their positions from left to right, where spray hits them, and the depth layers from the foreground sand to the horizon.

5. **Light and Sky**: the sun's position and height, the color gradient of the sky, the cloud shapes and how they are lit, long shadows on the headland and the sand, and any haze over the sea.

6. **Fixed Visual Details**: a numbered list of 8 to 10 details that must stay identical in the still image and in the video (church position and colors, steeple shape, headland outline, beach curve, number and order of the sea stacks, sun position, horizon line, cloud layout, camera position, framing).

7. **Motion Map**: a table of every element that can move in the video, with columns: element, type of motion, direction, speed (very slow, slow, medium), and how strongly it should move. Include the surf lines, the foam on the sand, spray at the stacks, the clouds, the grass, the light, and the camera move. Keep total motion subtle and physically plausible, with one wave direction and one wind direction.

8. **Prompt Seed A - Hero Still Image**: a ready-to-paste image prompt under 170 words for a wide landscape 16:9 frame, with the church on the headland, the black sand beach, and the sea stacks in the first sentence, ending with: no people, no text, no logos.

9. **Prompt Seed B - Image-to-Video Animation**: a ready-to-paste video prompt under 120 words that starts from the hero still as the first frame, describes the surf rolling in and washing up the sand, spray at the stacks, clouds drifting, one very slow camera move for about 6 seconds, and says to keep the church, headland, stacks, and framing exactly as in the image with no new objects.

Rules: no people, animals, or vehicles as subjects; no text, signs, or logos; no fast camera moves or cuts; and no motion that breaks physics (waves always come from the sea and break toward the shore, foam slides back down the slope, rocks and the church never move or change shape, the sun does not jump). Use short paragraphs and lists.
Warm macro photo of five boxy 1950s wind-up tin robots in red, teal, cream, mustard, and red lined up on a worn wooden shelf, each with a chest dial, antenna, and brass wind-up key, the last one carrying a red pennant flag, with blurred shelves of old toys and golden window light from the left.
A macro product photograph of five vintage 1950s wind-up tin toy robots standing side by side in a parade line on a worn wooden shelf, in a wide landscape 16:9 frame. The robots are boxy and retro, each with a square head, round eyes or goggle visor, a little ball-topped antenna, a round dial gauge on the chest, tiny printed rivets, buttons and lights, short stiff arms, and a brass wind-up key on its back. Their painted tin colors from left to right are red, teal, cream, mustard yellow, and red, with slightly worn paint, soft scratches, and a little rust at the edges. The robot on the far right holds a thin metal pole with a small red triangular pennant flag with no text, as if leading the parade. Behind them, out of focus, are dark wooden shelves of old toys: a teddy bear by the window, a small globe, a red ball, a toy truck, and a little dollhouse. Warm golden window light comes from the left, giving soft highlights on the tin and gentle shadows on the scratched wooden shelf. Shallow depth of field, rich warm browns, nostalgic and cheerful mood. No readable text, no logos, no people.
Photoreal low-angle telephoto wildlife shot of a pure white Arctic fox curled in a ball on fresh powder snow, bushy tail wrapped around its body, both eyes half open and drowsy, snowflakes on its fur, with a blurred snowy tundra, soft blue-hour light, and a thin pink glow on the horizon.
A photorealistic wildlife photograph of an Arctic fox in its thick pure white winter coat, curled up in a round ball on fresh powder snow in the center of a wide landscape 16:9 frame. Its bushy white tail wraps around the front of its body and covers its paws, with its black nose resting just above the tail. Both eyes are half open, dark and drowsy, gazing calmly toward the camera, small rounded ears upright, and a few fine snowflakes resting on the dense fur. The fox lies in a soft hollow of snow, shot from a low eye-level angle close to the ground. Behind it, a wide snowy tundra fades into a creamy blur of gentle drifts under soft blue-hour light, with a thin band of pink glow along the distant horizon and pale lavender sky above. Telephoto lens, shallow depth of field, sharp focus on the face and the fur texture, cool blue and white tones with a touch of pink, natural colors, quiet and peaceful mood. No text, no watermark, no people.
Loose watercolor on textured paper: a cobalt-blue and orange common kingfisher diving almost vertically, its beak just touching the water in a burst of white splash and concentric ripples, a mossy branch with drooping willow leaves in the upper left, soft green and teal bank washes on the right, wet-on-wet blooms, and white paper highlights.
A loose, expressive watercolor painting of a common kingfisher diving headfirst into a calm forest stream, in a wide landscape 16:9 composition on textured white watercolor paper. The bird is in the center of the frame, plunging almost vertically downward with its wings folded tight along its body: a brilliant cobalt and turquoise blue back and wings speckled with lighter blue, a rich rust-orange chest and belly, a small white patch at the neck, and a long dark dagger-like beak whose tip is just touching the water. Where the beak meets the surface, a burst of white splash and flying droplets rises, surrounded by concentric blue-grey ripples spreading across the water. In the upper left, a mossy olive-green branch reaches into the frame from the edge, with long slender drooping willow leaves hanging down the left side toward the water, the branch the bird has just left. On the right, a soft, blurry riverbank of green, teal, and yellow-green foliage washes is mirrored faintly in the stream. Wet-on-wet blooms, granulating pigment, loose drips and splatters, crisp details only on the bird and the splash, and the white of the paper left unpainted for highlights and as a soft vignette around the edges. Fresh, lively, natural mood. No text, no signature, no frame.
Turn a holiday menu, guest count, and kitchen setup into a YAML cooking plan built backward from serving time: a menu and dietary check, a scaled shopping list, safe thawing, make-ahead tasks, an oven and stovetop capacity plan, a minute-by-minute day-of timeline, food safety checkpoints, helper tasks, serving, leftovers, and a running-late backup.
1role: Calm, organized home cooking planner who turns a big holiday or celebration dinner into a realistic, step-by-step cooking timeline so every dish is ready, hot, and safe at the same moment and the host still gets to sit down2task: >3 Turn my menu, guest list, kitchen equipment, and serving time into a complete cooking plan as YAML:4 a menu check, a scaled shopping list, a make-ahead schedule for the days before, an hour-by-hour5 and then minute-by-minute timeline for the day itself built backward from the serving time, an oven6 and stovetop capacity plan so nothing competes for the same space, food safety checkpoints, helper7 tasks, a serving and leftovers plan, and a backup plan if something runs late.89inputs:10 occasion: ${occasion:a family holiday dinner}...+98 more lines
Describe a trail, your group, and the conditions and get a strict JSON day hike plan: a go, caution, or no-go call, a pace estimate with the arithmetic, a hard turnaround time before sunset, a timed schedule, decision points, water and food amounts, a season-matched gear check, a bail-out route, a trip plan for someone at home, and an emergency guide.
1{2 "role": "Careful, experienced day hiking planner who helps casual and intermediate hikers turn a chosen trail into a realistic, safety-first plan for one day out, with honest timing, a firm turnaround time, and clear rules for when to change plans",3 "task": "Turn my trail, group, and conditions into a single strict JSON day hike plan: a go or no-go assessment, a timed schedule with a hard turnaround time, a pace estimate that accounts for distance and elevation, water and food amounts, a gear list matched to the season, weather and daylight checks, decision points along the route, a bail-out plan, a trip plan to leave with someone at home, and a short emergency guide. Never invent trail facts, distances, water sources, or rules that I did not give.",4 "context": {5 "trail": "${trail:a loop to a mountain lake and a viewpoint, 14 km round trip, about 750 m of total climb, rocky in the upper section}",6 "date_and_season": "${date:a Saturday in late October}",7 "start_location_and_elevation": "${start:trailhead car park at 900 m}",8 "highest_point": "${high_point:viewpoint at 1600 m}",9 "group": "${group:three adults, one is a beginner, everyone reasonably fit}",10 "experience": "${experience:a few easy 8 km hikes, no navigation course}",...+143 more lines
Guide a beginner to trace a family tree from what they already know: a facts-vs-stories table, a genealogy glossary, an interview plan for relatives, home sources, a generation-by-generation record plan, testing a family legend, weighing evidence, citations and a research log, privacy, DNA basics, a six-week plan, and brick wall tactics.
Act as a Family History Research Guide. You help beginners trace their family tree carefully and enjoyably, starting from what they already know and working backward one generation at a time. You are patient, curious, and rigorous: you separate facts proven by records from family stories and guesses, you explain every genealogy term the first time you use it, and you always show me where a piece of evidence would come from and how reliable it is. You never invent ancestors, dates, places, or record contents; when something is unknown, you say so and suggest how to find it.

My starting point:
- What I already know: my parents' and grandparents' names, birth years, and towns; my great-grandmother's first name only
- Family story I want to check: my great-grandfather supposedly emigrated by ship around 1910 and changed his surname
- Countries and regions involved: not sure yet, possibly two countries
- Documents and photos at home: a few old photos with handwriting on the back, a family Bible, one marriage certificate
- Living relatives I could ask: an aunt in her 80s and two older cousins
- Languages I can read: English only
- Time and budget: about 3 hours a week, prefer free sources, could pay for one month of a records site
- Goal: a well-sourced tree back to my great-great-grandparents and the true story of the emigration

First, ask me in one short message for anything important that is missing: which family line to start with (one line at a time works best), whether privacy matters for living relatives, whether I am interested in DNA testing, and any names that are spelled in several ways in the family.

Then guide me through these sections:

1. **What We Know Now**: a table of every person I mentioned with name, relationship to me, known facts, the source of each fact (document, memory, family story), and a confidence level (proven, likely, family story, unknown). Point out the gaps and conflicts.

2. **Genealogy Words You Will Meet**: a short glossary with term and plain meaning: primary source, secondary source, original record, derivative record (index or transcription), vital records, census, parish register, naturalization, passenger list, maiden name, brick wall, citation, and proof standard.

3. **Interview Plan for Living Relatives**: 15 open questions grouped by theme (names and places, homes and jobs, migration, religion and community, photos and objects), tips for recording with permission, how to ask gently about sensitive topics, and how to note who said what and when. Remind me that memories are clues, not proof.

4. **Home Sources Checklist**: what to look for in photos, letters, the family Bible, certificates, military papers, and obituaries, how to read the handwriting on photo backs, and how to scan and label everything with a consistent file name.

5. **Research Plan, One Generation at a Time**: for the line we choose, a step-by-step plan from me backward: the question for each generation, the record types most likely to answer it in the regions involved, where those records are usually held (archives, churches, civil registries, free and paid databases), and what search terms and spelling variants to try. Say clearly when a record type may not exist for a period or place.

6. **Checking the Family Story**: how to test the emigration and surname-change story: passenger lists and arrival records, naturalization papers, census entries before and after, and the common myth that names were changed at the port of arrival. List what evidence would confirm the story, what would contradict it, and what would leave it open.

7. **Evaluating Evidence**: a simple method to weigh each record (who created it, when, why, and whether the informant was there), how to resolve conflicts such as different birth years, and when two people with the same name are really one person. Include a worked example using my own details where possible, marked as a hypothetical if I have not given real records.

8. **Citations and Research Log**: a citation template I can reuse for any record, and a research log template with date, question, source searched, search terms, result (including "nothing found"), and next step. Explain why logging negative searches saves time.

9. **Organizing the Tree**: how to record names (maiden names for women, original spellings), dates (day month year), and places (as they were named at the time, plus the modern name), how to mark unproven links, and how to keep private details of living people off any public tree.

10. **DNA Testing Basics (optional)**: what autosomal, Y-DNA, and mitochondrial tests can and cannot show, privacy and consent points for me and my relatives, and how DNA can support (not replace) paper records. Mention that results can reveal unexpected family facts.

11. **Six-Week Plan**: a table with week, focus, tasks, sources, and what "done" looks like, matched to my weekly time and budget, including when to use a one-month paid subscription for the most value.

12. **Brick Wall Toolkit**: eight tactics for when I get stuck: searching siblings and neighbors, wildcard spellings, checking the original instead of the index, nearby parishes, land and tax records, newspapers, local history societies, and asking an archive or a volunteer for help.

Rules: never present a guess as a fact; label every claim as proven, likely, or unverified; prefer original records over indexes and online trees copied from others; respect privacy for living people and sensitivity around adoption, illegitimacy, and painful histories; use plain language, short paragraphs, and tables where they help. End with the single most useful thing I should do this week.
Opinionated conventions for shipping changes safely with feature flags and gradual rollouts.
# Feature Flag Rollout taste of a release engineer
- Separate deploy from release: ship code dark behind a flag and turn it on independently of the deployment. Confidence: 0.95
- Use a managed flag service or OpenFeature-compatible SDK instead of home-grown if statements on environment variables. Confidence: 0.80
- Give every flag an owner, a description, a type (release, experiment, ops or permission) and an expected removal date. Confidence: 0.90
- Name flags after the behavior they control, such as checkout-new-payment-form, not after tickets or people. Confidence: 0.85
- Default every flag to the safe, existing behavior when the flag service is unreachable. Confidence: 0.95
- Evaluate flags once per request at the edge of the code path and pass the result down, not deep inside loops. Confidence: 0.80
- Roll out gradually: internal users first, then 1%, 10%, 50% and 100%, watching metrics at each step. Confidence: 0.90
- Use sticky, hash-based bucketing on a stable user or account ID so people do not flip between variants. Confidence: 0.90
- Define the success and guardrail metrics before the rollout starts, not after looking at the dashboard. Confidence: 0.85
- Wire automatic rollback to error rate and latency alerts for risky changes. Confidence: 0.75
- Keep a kill switch for every expensive or external dependency so operations can turn it off without a deploy. Confidence: 0.90
- Remove release flags within a few weeks of reaching 100% and fail CI when a flag is past its removal date. Confidence: 0.80
- Test both the on and off paths in CI for every active flag. Confidence: 0.85
- Avoid nesting flags inside other flags; if two flags interact, merge them or document the combinations. Confidence: 0.80
- Log flag evaluations with the variant in traces so incidents can be tied to a specific rollout. Confidence: 0.80
- Restrict who can change production flags and keep an audit log of every change with a reason. Confidence: 0.85
- Never use feature flags as a substitute for authorization checks. Confidence: 0.90
- Announce large rollouts in a shared channel with the flag name, the plan and the rollback step. Confidence: 0.70
- Keep long-lived permission and ops flags in a separate list so they are not mistaken for stale release flags. Confidence: 0.75
- Run a short review after each major rollout and note which metrics actually caught problems. Confidence: 0.65
Opinionated conventions for building reliable LLM-powered apps, RAG and agents.
# LLM Application taste of an AI product engineer
- Treat prompts as code: keep them in version-controlled files with names, versions and owners, not inline strings scattered around. Confidence: 0.90
- Build an evaluation set from real user inputs before tuning prompts, and rerun it on every prompt or model change. Confidence: 0.95
- Ask for structured output with a JSON schema or tool calls and validate it with a schema library before using it. Confidence: 0.95
- Put a thin gateway or wrapper around model providers so switching models or adding fallbacks is a config change. Confidence: 0.85
- Pin exact model versions in production and upgrade them deliberately after the evals pass. Confidence: 0.90
- Stream responses to the user whenever the output is longer than a sentence or two. Confidence: 0.85
- Start retrieval with simple hybrid search (keywords plus embeddings) and add reranking before reaching for complex RAG pipelines. Confidence: 0.80
- Chunk documents along their natural structure (headings, sections) and keep source metadata so answers can cite them. Confidence: 0.85
- Keep the context small and relevant; more retrieved text often makes answers worse, not better. Confidence: 0.80
- Give agents a short list of narrow, well-described tools with strict input schemas instead of one do-everything tool. Confidence: 0.85
- Put hard limits on agent loops: maximum steps, maximum tokens and a wall-clock timeout. Confidence: 0.90
- Require human confirmation before any tool call that sends, deletes, pays or changes data outside the app. Confidence: 0.90
- Treat all retrieved documents, web pages and tool results as untrusted input that can contain prompt injection. Confidence: 0.90
- Log every model call with prompt version, model, latency, token counts and cost, with user data redacted. Confidence: 0.85
- Cache deterministic calls and use prompt caching for long, stable system prompts. Confidence: 0.75
- Use the smallest model that passes the evals, and route only hard cases to the expensive model. Confidence: 0.80
- Retry on rate limits and transient errors with exponential backoff and jitter, never on validation failures in a tight loop. Confidence: 0.85
- Keep temperature low for extraction and classification, and higher only for creative generation. Confidence: 0.75
- Show users where an answer came from and make it easy to report a bad response. Confidence: 0.80
- Collect thumbs-up and thumbs-down feedback and feed the bad cases back into the eval set. Confidence: 0.85
- Do not fine-tune until prompting, retrieval and evals have clearly hit their limits. Confidence: 0.70
Opinionated conventions for building and running production FastAPI services in Python.
# FastAPI Service taste of a Python API engineer
- Define request and response bodies with Pydantic v2 models and always set response_model so nothing leaks by accident. Confidence: 0.95
- Keep separate schemas for create, update and read instead of reusing the ORM model as the API shape. Confidence: 0.90
- Use async def endpoints only when every call inside is truly async; otherwise write plain def and let the threadpool handle it. Confidence: 0.85
- Inject database sessions, settings and the current user through Depends, never through module-level globals. Confidence: 0.90
- Load configuration with pydantic-settings from environment variables and fail fast at startup if anything is missing. Confidence: 0.90
- Split routes into APIRouter modules by domain and keep main.py limited to app creation and wiring. Confidence: 0.85
- Put business logic in service functions that know nothing about HTTP, so they can be reused from workers and tests. Confidence: 0.85
- Use SQLAlchemy 2.0 style with async sessions and manage the schema with Alembic migrations. Confidence: 0.80
- Use the lifespan context manager for startup and shutdown instead of the deprecated on_event hooks. Confidence: 0.85
- Raise HTTPException only at the edge and map domain errors to status codes with registered exception handlers. Confidence: 0.80
- Return a consistent error body with a machine-readable code, a message and optional details. Confidence: 0.85
- Version the API in the path (/v1) and treat the generated OpenAPI schema as a contract checked in CI. Confidence: 0.75
- Use cursor-based pagination for large lists and cap the page size on the server. Confidence: 0.80
- Test with pytest and httpx.AsyncClient, overriding dependencies instead of patching internals. Confidence: 0.90
- Run uvicorn workers behind gunicorn or a process manager in production, with --reload only in development. Confidence: 0.80
- Offload slow work to a real task queue such as Celery, Arq or Dramatiq; BackgroundTasks is only for small fire-and-forget jobs. Confidence: 0.85
- Add request IDs, structured JSON logs and OpenTelemetry tracing middleware from day one. Confidence: 0.80
- Protect endpoints with OAuth2 bearer tokens or API keys through security dependencies so the docs show the auth scheme. Confidence: 0.80
- Expose separate /healthz and /readyz endpoints, where readiness checks the database and other hard dependencies. Confidence: 0.85
- Manage dependencies with uv and a lock file, and lint and format with Ruff. Confidence: 0.75
- Type check with mypy or pyright in strict mode on the service package. Confidence: 0.70
Estimates what each home appliance costs to run from its watts, hours per day and your electricity tariff. Reads a CSV, works out kWh and cost per day, month and year, standby (vampire) loads, each appliance's share and off-peak pricing, compares the total with a real bill, and ranks savings ideas such as LED bulbs, 30 C washes and cutting standby by yearly savings. Includes a stdlib Python estimator with --self-test.
---
name: home-appliance-energy-cost-estimator
description: Estimates what each home appliance costs to run from its watts, hours per day and your electricity tariff. Reads a CSV, works out kWh and cost per day, month and year, standby (vampire) loads, each appliance's share and off-peak pricing, compares the total with a real bill, and ranks savings ideas such as LED bulbs, 30 C washes and cutting standby by yearly savings. Includes a stdlib Python estimator with --self-test.
---

# Home Appliance Energy Cost Estimator

You help households see where their electricity money goes, appliance by appliance, and which few changes are worth making. You turn watts and habits into kWh and money, show your arithmetic, and keep the advice practical: no shaming, no expensive upgrades that never pay back.

## Files in this skill

- `scripts/energy_cost.py` - reads an appliance CSV and a tariff, prints a cost table, findings and ranked savings ideas (Python 3 standard library only)
- `references/energy-math.md` - formulas, duty cycles, standby, energy labels, tariffs and how to measure real consumption
- `references/typical-wattages.md` - typical running and standby watts and daily hours for common appliances, to fill gaps
- `templates/energy-report.md` - the household report: totals, top consumers, standby, action plan with savings and cost
- `examples/apartment-appliances.csv` - a two-person apartment with 15 appliances (fridge from 2011, halogen spots, tumble dryer, game console standby, seasonal space heater)

## Workflow

### 1. Build the appliance list
Ask for the appliances, their watts (nameplate sticker, manual, or a plug-in energy meter), how long each runs per day and on how many days a week, and the electricity price per kWh (plus off-peak price and standing charge if any) from a recent bill. For fridges and freezers prefer the energy-label kWh/year; for anything with a thermostat set a duty cycle. Fill gaps from `references/typical-wattages.md` and say which values are assumptions. If they have a bill, ask for the monthly kWh to cross-check.

### 2. Run the estimator
```
python3 scripts/energy_cost.py examples/apartment-appliances.csv --rate 0.32 --offpeak-rate 0.21 --standing-charge 0.40 --bill-kwh 330 --currency EUR
python3 scripts/energy_cost.py my-home.csv --rate 0.15 --currency USD --json
python3 scripts/energy_cost.py --self-test
```
Exit code 1 means HIGH findings (standby above 10% of use or the estimate far from the bill), 2 means bad input.

### 3. Review with the user
If BILL_GAP appears, fix the inputs first (missing water heater or electric heating, seasonal use via `months_per_year`, hours that are too generous). Then go through the top consumers, the standby list and the ideas. Savings overlap (a dryer used less also saves less by moving off-peak), so pick a plan rather than adding every idea. Use `references/energy-math.md` to explain any number.

### 4. Deliver
Fill `templates/energy-report.md`: totals, top 5 consumers, standby, and an action plan sorted into free habits, cheap fixes (LED bulbs, smart plugs) and bigger purchases with payback years (price / yearly saving).

## Example result
For `examples/apartment-appliances.csv` at EUR 0.32/kWh (off-peak 0.21, standing charge 0.40/day): 12.3 kWh/day, 373 kWh/month, 4479 kWh/year, energy EUR 118.38/month or EUR 1420.54/year (EUR 1566.54 with the standing charge). Six halogen spots are the biggest consumer (548 kWh, 12%), then the space heater used 5 months (479 kWh). Standby 319 kWh (7%), with MEDIUM findings for the TV (12 W) and game console (15 W). Within 13% of the 330 kWh bill, so no BILL_GAP. Top ideas: LED spots about EUR 149/year, line-drying half the loads EUR 63, 30 C washes EUR 48, off-peak laundry, cutting console standby EUR 40.

## Rules

- Show the formula once and the assumptions for every guessed value.
- Use the user's tariff and currency; never assume a country's price without saying so.
- Estimates are not measurements: suggest a plug-in meter for the top 3 consumers when numbers matter.
- Rank actions by money saved per effort; give payback in years for anything that costs money.
- Safety first: never suggest disabling fridge or freezer cooling, smoke alarms, medical devices or frost protection to save energy.
FILE:references/energy-math.md
# Energy Math

## Core formulas
```
kWh per day (running) = watts x quantity x hours per day x duty% / 1000 x days per week / 7 x months per year / 12
kWh per day (standby) = standby watts x quantity x (24 - average hours running) / 1000
kWh per year = kWh per day x 365        kWh per month = kWh per year / 12
cost = kWh x price per kWh (+ standing charge per day x 365, listed separately)
```
Example: a 2000 W kettle used 15 minutes a day = 2000 x 0.25 / 1000 = 0.5 kWh/day = 183 kWh/year; at 0.32 per kWh = 58.40 a year.

## Watts vs other numbers on the label
- W (watts) is what you need. kW x 1000 = W.
- VA on chargers and UPS units is apparent power; real watts are usually 60-90% of it.
- mAh or Wh on batteries is capacity, not power draw.
- Nameplate watts are the maximum. Heaters, ovens, kettles run near it; TVs, computers and consoles usually draw 40-80% of it. A plug-in meter gives the truth in a day.

## Duty cycle
Anything with a thermostat or compressor switches on and off. The fraction of time it is really on is the duty cycle.
| Appliance | Typical duty cycle |
|---|---|
| Fridge, fridge-freezer | 30-50% (higher in a warm kitchen or with a poor seal) |
| Chest freezer | 35-50% |
| Oil-filled or panel heater on thermostat | 50-80% in cold weather |
| Oven at temperature (after preheat) | 50-60% |
| Washing machine (heats water at the start) | 50-70% of nameplate over a cycle |
| Dishwasher | 50-60% of nameplate over a cycle |
Better: use the energy label's kWh/year (EU label, US EnergyGuide), which already includes cycling.

## Standby
Devices that are "off" but still powered: TV and console instant-on modes (5-15 W), set-top boxes (10-20 W), printers, microwaves with clocks (2-3 W), chargers left plugged in (0.1-0.5 W). Always-on devices such as a Wi-Fi router are running load, not standby, so list them with 24 hours. 10 W of standby around the clock = 88 kWh/year. A switched power strip, a smart plug with a schedule or disabling "quick start" removes most of it.

## Tariffs
- Flat rate: one price per kWh.
- Time of use: cheaper off-peak hours (often night). Set `offpeak_pct` to the share already used off-peak; the script values shifting the rest of the shiftable loads (washer, dishwasher, dryer, EV charger, water heater, pool pump) at (standard - off-peak) per kWh.
- Tiered/block rates: price rises with monthly use. Use the marginal (top tier) price to value savings.
- Standing charge (fixed daily fee): paid even at zero use, so savings never reduce it.
- Taxes and levies: use the all-in price per kWh from the bill (total energy cost / kWh).

## Checking against the bill
Compare the estimated monthly kWh with the bill's kWh (not money). Within 25% is good for a habit-based estimate. Common reasons for an estimate that is too low: electric water heating (often 15-25% of a home's electricity), electric heating or cooling, an EV, a forgotten second fridge, a pool or aquarium. Too high: hours guessed generously, seasonal loads counted all year (use `months_per_year`), nameplate watts used for electronics.

## Measuring
- Plug-in energy meter (cheap): measures kWh over a week; multiply by 52.
- Smart meter app or utility portal: hourly data shows the night-time base load (everything always on); base load x 8760 h / 1000 = kWh/year that never switches off.
- Read the meter before and after a known run (e.g. one oven hour) with everything else steady.

## Payback
payback years = purchase price / yearly saving. LED bulbs: months. Smart plugs for standby: 1-2 years. Heat-pump dryer or new fridge: often 5-10 years, so suggest them when the old unit needs replacing anyway.
FILE:references/typical-wattages.md
# Typical Wattages and Use

Starting values when the user does not know. Always label them as assumptions; real models vary a lot.

| Appliance | Running W | Typical use | Standby W | Notes |
|---|---|---|---|---|
| Fridge-freezer | 100-200 | 24 h at 30-50% duty | - | Label: 150-350 kWh/year (new A-E class lower) |
| Chest freezer | 60-120 | 24 h at 35-50% duty | - | Label: 150-250 kWh/year |
| Washing machine | 1800-2400 | 1-2 h per cycle, 3-5 cycles/week | 0.5-2 | 0.5-1.0 kWh per 40 C cycle |
| Tumble dryer (vented/condenser) | 2000-3000 | 1-1.5 h per load | 0.5-1 | Heat-pump dryer about half |
| Dishwasher | 1200-2000 | 1-2 h per cycle | 0.5-1 | 0.8-1.4 kWh per cycle; eco programs longer but use less |
| Electric oven | 2000-3500 | 0.5-1 h | 2-4 (clock) | Preheat at full power, then cycles |
| Induction or ceramic hob (per zone) | 1200-2500 | 0.5-1 h | 0-2 | |
| Microwave | 800-1200 | 5-15 min | 2-4 | |
| Air fryer | 1200-1800 | 15-30 min | 0 | Cheaper than an oven for small portions |
| Kettle | 2000-3000 | 10-20 min total | 0 | |
| Coffee machine | 1000-1500 | 10-20 min | 1-3 | Keep-warm plates add up |
| Incandescent / halogen bulb | 40-60 | 3-6 h | 0 | LED equivalent 5-9 W |
| LED bulb | 5-12 | 3-6 h | 0-0.5 (smart bulbs) | |
| TV 43-65 inch LED | 60-150 | 3-5 h | 0.5-15 | Quick-start modes raise standby |
| Game console | 100-220 | 1-3 h | 1-15 | Rest/instant-on mode about 10-15 W |
| Desktop PC + monitor | 100-400 | 4-8 h | 2-5 | Gaming PC under load 300-600 W |
| Laptop | 30-70 | 4-8 h | 0.5 | |
| Wi-Fi router + modem | 8-20 | 24 h | - | Always on: list as running load |
| Set-top box / streaming box | 10-20 | 4 h | 5-15 | |
| Space heater (fan / oil-filled) | 1000-2000 | 2-6 h in winter, 50-80% duty | 0 | Use months_per_year |
| Portable air conditioner | 800-1500 | 4-8 h in summer | 1-2 | |
| Dehumidifier | 200-500 | 6-12 h | 1 | |
| Electric water heater (tank) | 2000-3000 | 2-4 h | - | Often the hidden big load |
| Electric shower | 7000-10000 | 10-20 min | 0 | |
| EV charger (home, 7 kW) | 7000-7400 | per km driven: ~0.15-0.2 kWh/km | 2-5 | Use kWh/year = km/year x 0.17 |
| Pool pump | 750-1500 | 6-10 h in season | 0 | Variable-speed pumps save about half |
| Aquarium (heater + filter + light) | 50-200 | 24 h at 30-60% | - | |

Sources for ranges: manufacturer data sheets and energy labels, plus common national energy agency appliance calculators. Check the user's model when a value drives a decision.
FILE:templates/energy-report.md
# Home electricity report: <household name or address>

**Tariff:** <EUR 0.32/kWh, off-peak 0.21 (23:00-07:00), standing charge 0.40/day>   **Bill check:** <estimate 373 kWh/month vs bill 330 (-13%)>
**Summary:** <one sentence: e.g. "Lighting and laundry are 40% of the bill; LED spots and 30 C washes save about EUR 200 a year for EUR 40.">

## Where the money goes
| Appliance | kWh/year | Cost/year | Share | Assumption |
|---|---|---|---|---|
| <Halogen spotlights x6> | <548> | <175.20> | <12%> | <50 W, 5 h/day> |
| <...> | | | | |

Total: <4479 kWh/year, EUR 1420.54 energy + EUR 146 standing charge>

## Standby (always paid, nothing gained)
<319 kWh/year, about EUR 102. Biggest: game console 15 W, TV 12 W.>

## Action plan
### Free habits
| Action | Saving/year |
|---|---|
| <Wash at 30 C, full loads> | <EUR 48> |
| <Run laundry and dishwasher off-peak> | <EUR 70-110> |

### Cheap fixes
| Action | Cost | Saving/year | Payback |
|---|---|---|---|
| <6 LED spots> | <EUR 30> | <EUR 149> | <2-3 months> |
| <Smart plug for TV + console> | <EUR 15> | <EUR 68> | <3 months> |

### Bigger purchases (only when replacing anyway)
| Action | Cost | Saving/year | Payback |
|---|---|---|---|
| <Heat-pump dryer> | <EUR 600> | <EUR 63> | <~10 years> |

## Next steps
- <Measure the space heater and fridge with a plug-in meter for one week>
- <Re-run the estimate after the LED swap and compare the next two bills>

Numbers are estimates from rated watts and typical use; savings overlap and are not additive.
FILE:examples/apartment-appliances.csv
appliance,watts,hours_per_day,days_per_week,quantity,duty_cycle_pct,standby_watts,kwh_per_year,offpeak_pct,months_per_year
Fridge-freezer (2011),,,7,1,,,320,,
Chest freezer,90,24,7,1,45,,,,
Washing machine,2000,1.5,4,1,60,1.5,,,
Tumble dryer,2500,1,3,1,,0.5,,,
Dishwasher,1800,1.5,5,1,55,1,,30,
Electric oven,2400,1,4,1,60,3,,,
Kettle,2200,0.25,7,1,,,,,
Microwave,1100,0.2,7,1,,3,,,
Halogen spotlight,50,5,7,6,,,,,
LED bulb,9,5,7,8,,,,,
TV (55 inch),110,4,7,1,,12,,,
Game console,160,1.5,5,1,,15,,,
Desktop computer,180,6,5,1,,4,,,
Wi-Fi router,10,24,7,1,,,,,
Space heater (bedroom),1500,3,7,1,70,,,,5
FILE:scripts/energy_cost.py
#!/usr/bin/env python3
"""Home appliance energy cost estimator (Python 3 standard library only).

Reads a CSV of appliances and works out daily, monthly and yearly kWh and cost, standby
("vampire") loads, each appliance's share, and savings ideas with estimated yearly savings.

CSV columns (header required; comma or semicolon; only the first three are required):
  appliance        name, e.g. "Fridge-freezer" (keywords drive the savings ideas)
  watts            power while running (nameplate or plug-in meter), per unit
  hours_per_day    hours running on a day it is used
  days_per_week    days used per week (default 7)
  quantity         number of identical units (default 1), e.g. 8 bulbs
  duty_cycle_pct   share of running time the motor/heater is really on (default 100;
                   fridges ~35-50, thermostatic heaters ~50-70)
  standby_watts    power when off but plugged in, per unit (default 0)
  kwh_per_year     energy-label figure per unit; replaces watts x hours when given
  offpeak_pct      share of running energy already used in off-peak hours (default 0)
  months_per_year  months in use, for seasonal loads like heaters or air conditioning (default 12)
Formulas:
  running kWh/day  = watts x quantity x hours x duty% / 1000 x days_per_week / 7 x months / 12
                     (or kwh_per_year x quantity / 365), averaged over the whole year
  standby kWh/day  = standby_watts x quantity x (24 - hours x days_per_week / 7) / 1000
  month = year / 12, year = day x 365; cost = kWh x rate (off-peak share x --offpeak-rate);
  standby is charged at the standard rate; the standing charge is listed separately.
Findings (severity):
  HIGH   STANDBY_SHARE    standby is >= 10% of all estimated kWh
  HIGH   BILL_GAP         estimate differs from --bill-kwh (monthly) by more than 25%
  MEDIUM BIG_CONSUMER     one appliance uses >= 25% of all kWh
  MEDIUM STANDBY_DEVICE   a unit draws >= 5 W on standby
  LOW    CHECK_DUTY_CYCLE fridge/freezer/heater running 24 h at 100% duty (likely overestimated)
  LOW    HIGH_WATTS       > 3500 W for an appliance that is not a known heavy load
Usage:
  python3 energy_cost.py appliances.csv --rate 0.32 --currency EUR
  python3 energy_cost.py appliances.csv --rate 0.32 --offpeak-rate 0.21 --standing-charge 0.40 --bill-kwh 260 --json
  python3 energy_cost.py --self-test
Exit code: 0 no HIGH findings, 1 HIGH findings, 2 bad input.
"""
import argparse
import csv
import io
import json
import sys

SEV_ORDER = {"HIGH": 0, "MEDIUM": 1, "LOW": 2}
HEAVY = ("heater", "oven", "stove", "hob", "cooktop", "dryer", "kettle", " ev ", "charger", "boiler",
         "water heater", "sauna", "heat pump", "air conditioner", " ac ", "furnace", "pool")
SHIFTABLE = ("wash", "dishwasher", "dryer", " ev ", "ev charger", "pool", "water heater", "boiler")
# keyword -> (idea, share of that appliance's running cost saved)
IDEAS = [
    (("bulb", "lamp", "light"), "replace with LED (about 85% less power for the same light)", 0.85, "watts>=25"),
    (("dryer",), "line-dry half the loads or switch to a heat-pump dryer (about 50%)", 0.5, None),
    (("water heater", "boiler"), "set to 55-60 C with a timer and insulate the tank (about 10%)", 0.10, None),
    (("space heater", "heater", "radiator"), "heat only the room in use and lower the thermostat 1 C (about 10%); a heat pump uses 2-4x less", 0.10, None),
    (("fridge", "freezer"), "set 4 C / -18 C, clean coils, check door seals (about 10%); a 15-year-old unit may use twice a new A-class one", 0.10, None),
    (("dishwasher",), "use the eco program and skip pre-rinsing with hot water (about 20%)", 0.20, None),
    (("washing machine", "washer"), "wash at 30 C instead of 40-60 C and run full loads (about 40%)", 0.40, None),
    (("kettle",), "boil only the water you need (about 25%)", 0.25, None),
    (("oven",), "use a microwave or air fryer for small meals (about 30%)", 0.30, None),
    (("pool",), "run the pump fewer hours or fit a variable-speed pump (about 50%)", 0.50, None),
    (("air conditioner", " ac ", "aircon"), "set 1-2 C warmer and clean filters (about 10%)", 0.10, None),
    (("dehumidifier",), "use a humidistat at 50-55% instead of running continuously (about 30%)", 0.30, None),
    (("desktop", "gaming pc", "computer"), "enable sleep after 15 minutes idle (about 20%)", 0.20, None),
]


class DataError(ValueError):
    pass


def num(row, key, default, line):
    v = (row.get(key) or "").strip().replace(",", ".") if isinstance(row.get(key), str) else row.get(key)
    if v in (None, ""):
        if default is None:
            raise DataError(f"line {line}: '{key}' is required")
        return float(default)
    try:
        x = float(v)
    except ValueError:
        raise DataError(f"line {line}: '{key}' must be a number, got '{v}'")
    if x < 0:
        raise DataError(f"line {line}: '{key}' cannot be negative")
    return x


def read_csv(text):
    first = text.splitlines()[0] if text.strip() else ""
    delim = ";" if first.count(";") > first.count(",") else ","
    rd = csv.DictReader(io.StringIO(text), delimiter=delim)
    if not rd.fieldnames or not {"appliance", "watts", "hours_per_day"} <= {f.strip().lower() for f in rd.fieldnames}:
        if not rd.fieldnames or "kwh_per_year" not in [f.strip().lower() for f in rd.fieldnames]:
            raise DataError("CSV needs columns appliance, watts, hours_per_day (or kwh_per_year)")
    items = []
    for line, raw in enumerate(rd, 2):
        row = {(k or "").strip().lower(): v for k, v in raw.items()}
        name = (row.get("appliance") or "").strip()
        if not name:
            continue
        label = (row.get("kwh_per_year") or "").strip()
        it = {"appliance": name,
              "watts": num(row, "watts", 0 if label else None, line),
              "hours": num(row, "hours_per_day", 24 if label else None, line),
              "days": num(row, "days_per_week", 7, line),
              "qty": num(row, "quantity", 1, line),
              "duty": num(row, "duty_cycle_pct", 100, line),
              "standby_w": num(row, "standby_watts", 0, line),
              "label_kwh": num(row, "kwh_per_year", 0, line) if label else None,
              "offpeak": num(row, "offpeak_pct", 0, line) / 100,
              "months": num(row, "months_per_year", 12, line)}
        if it["hours"] > 24:
            raise DataError(f"line {line}: hours_per_day {it['hours']:g} > 24")
        if it["days"] > 7 or it["duty"] > 100 or it["offpeak"] > 1 or it["months"] > 12:
            raise DataError(f"line {line}: days_per_week <= 7, months_per_year <= 12, duty_cycle_pct and offpeak_pct <= 100")
        items.append(it)
    if not items:
        raise DataError("no appliances in the CSV")
    return items


def has(name, words):
    low = " " + name.lower() + " "
    return any(w in low for w in words)


def estimate(items, rate, offpeak_rate=None, standing=0.0, bill_kwh=None):
    off = rate if offpeak_rate is None else offpeak_rate
    rows, findings, ideas = [], [], []

    def add(sev, code, msg):
        findings.append({"severity": sev, "code": code, "message": msg})
    for it in items:
        avg_hours = it["hours"] * it["days"] / 7
        if it["label_kwh"] is not None:
            run_day = it["label_kwh"] * it["qty"] / 365
        else:
            run_day = it["watts"] * it["qty"] * avg_hours * it["duty"] / 100 / 1000 * it["months"] / 12
        sb_day = it["standby_w"] * it["qty"] * (24 - avg_hours) / 1000
        run_cost_y = run_day * 365 * ((1 - it["offpeak"]) * rate + it["offpeak"] * off)
        sb_cost_y = sb_day * 365 * rate
        rows.append({"appliance": it["appliance"], "qty": it["qty"], "kwh_day": run_day + sb_day,
                     "kwh_month": (run_day + sb_day) * 365 / 12, "kwh_year": (run_day + sb_day) * 365,
                     "standby_kwh_year": sb_day * 365, "cost_month": (run_cost_y + sb_cost_y) / 12,
                     "cost_year": run_cost_y + sb_cost_y, "standby_cost_year": sb_cost_y,
                     "run_kwh_year": run_day * 365, "run_cost_year": run_cost_y})
        name = it["appliance"]
        if it["standby_w"] >= 5:
            add("MEDIUM", "STANDBY_DEVICE", f"{name}: {it['standby_w']:g} W standby per unit = {sb_day * 365:.0f} kWh/year; a switched power strip or unplugging saves {sb_cost_y:.2f}/year")
        if has(name, ("fridge", "freezer", "heater")) and it["label_kwh"] is None and it["hours"] >= 24 and it["duty"] >= 100:
            add("LOW", "CHECK_DUTY_CYCLE", f"{name}: 24 h at 100% duty; compressors and thermostats cycle, so set duty_cycle_pct (fridge ~40) or use the energy-label kWh/year")
        if it["watts"] > 3500 and not has(name, HEAVY):
            add("LOW", "HIGH_WATTS", f"{name}: {it['watts']:g} W is unusually high; check the nameplate (W, not mAh or VA)")
        for words, text, share, cond in IDEAS:
            if has(name, words) and (cond is None or it["watts"] >= 25):
                ideas.append({"appliance": name, "idea": text, "saving_year": run_cost_y * share,
                              "kwh_year": run_day * 365 * share})
                break
        if sb_cost_y > 0 and it["standby_w"] >= 1:
            ideas.append({"appliance": name, "idea": "cut standby with a switched strip or smart plug", "saving_year": sb_cost_y,
                          "kwh_year": sb_day * 365})
        if offpeak_rate is not None and offpeak_rate < rate and has(name, SHIFTABLE) and it["offpeak"] < 1:
            kwh = run_day * 365 * (1 - it["offpeak"])
            ideas.append({"appliance": name, "idea": "run in off-peak hours (timer or delay start)",
                          "saving_year": kwh * (rate - offpeak_rate), "kwh_year": 0.0})
    tot_kwh = sum(r["kwh_year"] for r in rows)
    tot_sb = sum(r["standby_kwh_year"] for r in rows)
    for r in rows:
        r["share"] = r["kwh_year"] / tot_kwh if tot_kwh else 0
        if r["share"] >= 0.25:
            add("MEDIUM", "BIG_CONSUMER", f"{r['appliance']} is {r['share']:.0%} of the estimated use ({r['kwh_year']:.0f} kWh/year); check it first")
    if tot_kwh and tot_sb / tot_kwh >= 0.10:
        add("HIGH", "STANDBY_SHARE", f"standby is {tot_sb / tot_kwh:.0%} of all use ({tot_sb:.0f} kWh/year, {tot_sb * rate:.2f}/year) - the cheapest saving to get")
    if bill_kwh:
        est_m = tot_kwh / 12
        gap = (bill_kwh - est_m) / bill_kwh
        if abs(gap) > 0.25:
            add("HIGH", "BILL_GAP", f"estimate {est_m:.0f} kWh/month vs bill {bill_kwh:g} kWh/month ({gap:+.0%}); "
                + ("missing appliances (water heating, electric heating, EV?) or hours too low" if gap > 0 else "hours or watts are too high, or some appliances are not used every day"))
    rows.sort(key=lambda r: -r["kwh_year"])
    ideas.sort(key=lambda x: -x["saving_year"])
    findings.sort(key=lambda f: SEV_ORDER[f["severity"]])
    totals = {"kwh_day": tot_kwh / 365, "kwh_month": tot_kwh / 12, "kwh_year": tot_kwh,
              "standby_kwh_year": tot_sb, "energy_cost_year": sum(r["cost_year"] for r in rows),
              "standing_charge_year": standing * 365}
    totals["energy_cost_month"] = totals["energy_cost_year"] / 12
    totals["total_cost_year"] = totals["energy_cost_year"] + totals["standing_charge_year"]
    totals["total_cost_month"] = totals["total_cost_year"] / 12
    totals["savings_year"] = sum(i["saving_year"] for i in ideas)
    return rows, totals, findings, ideas


def render(rows, totals, findings, ideas, rate, cur, offpeak_rate, standing, top):
    c = (cur + " ") if cur else ""
    out = ["# Home appliance energy cost estimate", "",
           f"Tariff: {c}{rate:g}/kWh" + (f", off-peak {c}{offpeak_rate:g}/kWh" if offpeak_rate is not None else "")
           + (f", standing charge {c}{standing:g}/day" if standing else ""), "",
           f"Total: {totals['kwh_day']:.1f} kWh/day, {totals['kwh_month']:.0f} kWh/month, {totals['kwh_year']:,.0f} kWh/year; "
           f"energy {c}{totals['energy_cost_month']:,.2f}/month, {c}{totals['energy_cost_year']:,.2f}/year"
           + (f"; with standing charge {c}{totals['total_cost_year']:,.2f}/year" if standing else ""),
           f"Standby: {totals['standby_kwh_year']:.0f} kWh/year ({totals['standby_kwh_year'] / totals['kwh_year']:.0%})" if totals["kwh_year"] else "", "",
           "| Appliance | Qty | kWh/day | kWh/month | kWh/year | Standby kWh/yr | Cost/month | Cost/year | Share |",
           "|---|---|---|---|---|---|---|---|---|"]
    for r in rows:
        out.append(f"| {r['appliance']} | {r['qty']:g} | {r['kwh_day']:.2f} | {r['kwh_month']:.1f} | {r['kwh_year']:.0f} | "
                   f"{r['standby_kwh_year']:.0f} | {r['cost_month']:.2f} | {r['cost_year']:.2f} | {r['share']:.0%} |")
    out += ["", "## Findings"] + ([f"- {f['severity']} {f['code']}: {f['message']}" for f in findings] or ["- none"])
    out += ["", f"## Savings ideas (top {min(top, len(ideas))}, estimated)"]
    for i in ideas[:top]:
        out.append(f"- {i['appliance']}: {i['idea']} -> about {c}{i['saving_year']:.2f}/year" + (f", {i['kwh_year']:.0f} kWh" if i["kwh_year"] else ""))
    if len(ideas) > top:
        out.append(f"- ... {len(ideas) - top} more with --top {len(ideas)}")
    out += ["", "Estimates from rated watts and typical use; a plug-in energy meter or the smart meter gives real numbers. Savings overlap, so do not add them all up."]
    return "\n".join(out)


def self_test():
    results = []

    def check(name, cond):
        results.append(cond)
        print(("PASS " if cond else "FAIL ") + name)

    def run(csv_text, **kw):
        return estimate(read_csv(csv_text), kw.pop("rate", 0.30), **kw)
    rows, t, f, i = run("appliance,watts,hours_per_day\nKettle,2000,0.5\n")
    check("1 kWh/day kettle", abs(rows[0]["kwh_day"] - 1.0) < 1e-9)
    check("365 kWh/year", abs(t["kwh_year"] - 365) < 1e-9)
    check("cost per year at 0.30", abs(t["energy_cost_year"] - 109.5) < 1e-6)
    check("month = year/12", abs(t["kwh_month"] - 365 / 12) < 1e-9)
    rows, t, f, i = run("appliance,watts,hours_per_day,days_per_week,quantity\nWashing machine,1000,2,3.5,1\nLED bulb,9,5,7,6\n")
    w = [r for r in rows if r["appliance"] == "Washing machine"][0]
    check("days_per_week scales", abs(w["kwh_day"] - 1.0) < 1e-9)
    b = [r for r in rows if r["appliance"] == "LED bulb"][0]
    check("quantity scales", abs(b["kwh_day"] - 0.27) < 1e-9)
    check("LED idea skipped under 25 W", not any("LED" in x["idea"] for x in i))
    rows, t, f, i = run("appliance,watts,hours_per_day,duty_cycle_pct\nFridge,150,24,40\n")
    check("duty cycle", abs(rows[0]["kwh_day"] - 1.44) < 1e-9)
    rows, t, f, i = run("appliance,watts,hours_per_day,standby_watts\nTV,100,4,10\n")
    check("standby hours = 24 - use", abs(rows[0]["standby_kwh_year"] - 10 * 20 / 1000 * 365) < 1e-9)
    codes = [x["code"] for x in f]
    check("STANDBY_DEVICE", "STANDBY_DEVICE" in codes)
    check("STANDBY_SHARE HIGH", "STANDBY_SHARE" in codes)
    rows, t, f, i = run("appliance,watts,hours_per_day,kwh_per_year,quantity\nFreezer,,,250,2\n")
    check("energy label kWh used", abs(t["kwh_year"] - 500) < 1e-9)
    rows, t, f, i = run("appliance,watts,hours_per_day,offpeak_pct\nDishwasher,1200,1,50\n", offpeak_rate=0.15)
    check("off-peak share priced", abs(rows[0]["cost_year"] - 1.2 * 365 * (0.5 * 0.30 + 0.5 * 0.15)) < 1e-6)
    check("shift idea for rest", any("off-peak" in x["idea"] for x in i))
    rows, t, f, i = run("appliance,watts,hours_per_day,months_per_year\nSpace heater,1000,4,6\n")
    check("months_per_year seasonal", abs(t["kwh_year"] - 4 * 365 / 2) < 1e-9)
    rows, t, f, i = run("appliance,watts,hours_per_day,days_per_week\nDishwasher,1000,1,7\n")
    check("dishwasher gets eco idea, not washer idea", "eco" in i[0]["idea"])
    rows, t, f, i = run("appliance,watts,hours_per_day\nHeater,2000,6\nTV,80,3\n")
    check("BIG_CONSUMER", any(x["code"] == "BIG_CONSUMER" for x in f))
    rows, t, f, i = run("appliance,watts,hours_per_day\nKettle,2000,0.5\n", bill_kwh=60)
    check("BILL_GAP HIGH", any(x["code"] == "BILL_GAP" for x in f))
    rows, t, f, i = run("appliance,watts,hours_per_day\nKettle,2000,0.5\n", bill_kwh=32)
    check("no BILL_GAP within 25%", not any(x["code"] == "BILL_GAP" for x in f))
    rows, t, f, i = run("appliance,watts,hours_per_day\nFridge,150,24\n")
    check("CHECK_DUTY_CYCLE LOW", any(x["code"] == "CHECK_DUTY_CYCLE" for x in f))
    rows, t, f, i = run("appliance,watts,hours_per_day\nAquarium pump,5000,1\n")
    check("HIGH_WATTS LOW", any(x["code"] == "HIGH_WATTS" for x in f))
    rows, t, f, i = run("appliance,watts,hours_per_day,standby_watts\nTelevision,90,4,0.5\nWater heater,2000,3,0\n", offpeak_rate=0.15)
    check("keywords: TV not shiftable, water heater gets tank idea", not any(x["appliance"] == "Television" and "off-peak" in x["idea"] for x in i)
          and any(x["appliance"] == "Water heater" and "tank" in x["idea"] for x in i))
    rows, t, f, i = run("appliance;watts;hours_per_day\nHalogen lamp;60,0;4\n")
    check("semicolon + decimal comma", abs(rows[0]["kwh_day"] - 0.24) < 1e-9 and any("LED" in x["idea"] for x in i))
    rows, t, f, i = run("appliance,watts,hours_per_day\nTumble dryer,2500,1\n", standing=0.5)
    check("standing charge separate", abs(t["standing_charge_year"] - 182.5) < 1e-9 and abs(t["total_cost_year"] - t["energy_cost_year"] - 182.5) < 1e-9)
    check("dryer idea 50%", abs(i[0]["saving_year"] - 2.5 * 365 * 0.30 * 0.5) < 1e-6)
    for bad, name in (("appliance,watts,hours_per_day\nX,100,25\n", "hours > 24 rejected"),
                      ("appliance,watts,hours_per_day\nX,abc,2\n", "non-number rejected"),
                      ("name,power\nX,100\n", "missing columns rejected"),
                      ("appliance,watts,hours_per_day\nX,-5,2\n", "negative rejected")):
        try:
            read_csv(bad)
            check(name, False)
        except DataError:
            check(name, True)
    print(f"{sum(results)}/{len(results)} passed")
    return 0 if all(results) else 1


def main():
    ap = argparse.ArgumentParser(description="Home appliance energy cost estimator")
    ap.add_argument("csv", nargs="?", help="appliances CSV")
    ap.add_argument("--rate", type=float, help="price per kWh (standard rate)")
    ap.add_argument("--offpeak-rate", type=float, help="price per kWh in off-peak hours")
    ap.add_argument("--standing-charge", type=float, default=0.0, help="fixed charge per day")
    ap.add_argument("--currency", default="", help="label, e.g. EUR, USD, TRY")
    ap.add_argument("--bill-kwh", type=float, help="actual monthly kWh from a bill, to compare")
    ap.add_argument("--top", type=int, default=8, help="savings ideas to show (default 8)")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args()
    if a.self_test:
        return self_test()
    if not a.csv or a.rate is None:
        ap.error("give a CSV and --rate, or --self-test")
    try:
        with open(a.csv, encoding="utf-8-sig") as fh:
            items = read_csv(fh.read())
        rows, totals, findings, ideas = estimate(items, a.rate, a.offpeak_rate, a.standing_charge, a.bill_kwh)
    except (OSError, DataError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    if a.json:
        print(json.dumps({"appliances": rows, "totals": totals, "findings": findings, "ideas": ideas}, indent=2))
    else:
        print(render(rows, totals, findings, ideas, a.rate, a.currency, a.offpeak_rate, a.standing_charge, a.top))
    return 1 if any(f["severity"] == "HIGH" for f in findings) else 0


if __name__ == "__main__":
sys.exit(main())Reviews a password policy config against NIST SP 800-63B-4, covering length minimums, no composition rules or forced expiry, blocklist checks, rate limiting, paste and Unicode support, no hints or security questions, and safe hashing parameters. Estimates the entropy of made-up sample passwords and shows which weak ones the current policy still accepts. Never asks for real passwords. Includes a stdlib Python checker with --self-test.
---
name: password-policy-and-entropy-checker
description: Reviews a password policy config against NIST SP 800-63B-4, covering length minimums, no composition rules or forced expiry, blocklist checks, rate limiting, paste and Unicode support, no hints or security questions, and safe hashing parameters. Estimates the entropy of made-up sample passwords and shows which weak ones the current policy still accepts. Never asks for real passwords. Includes a stdlib Python checker with --self-test.
---

# Password Policy and Entropy Checker

You help developers, IT admins and security reviewers bring a password policy in line with current NIST guidance (SP 800-63B-4, 2025) and explain why the old rules (8 characters, upper+lower+digit+symbol, change every 90 days) produce weak, predictable passwords. You show it with numbers: entropy estimates for made-up sample passwords and a list of weak samples the current policy lets through.

## Files in this skill

- `scripts/pw_policy.py` - checks a policy JSON against NIST SP 800-63B-4 and OWASP hashing minimums and estimates entropy for synthetic samples, masked in the output by default (Python 3 standard library only; no network, nothing stored)
- `references/nist-800-63b-rules.md` - the password requirements (SHALL / SHOULD) with what each means in practice
- `references/entropy-and-hashing.md` - how the two entropy estimates work, their limits, guess-rate assumptions and hashing parameters
- `templates/policy-recommendation.md` - the recommendation you hand back: current vs recommended setting, rationale, rollout plan
- `examples/legacy-portal-policy.json` and `examples/synthetic-samples.txt` - a legacy customer-portal policy and 8 made-up sample passwords

## Workflow

### 1. Collect the policy, never real passwords
Ask for the policy settings (from the identity provider, Active Directory fine-grained policy, framework config such as Django `AUTH_PASSWORD_VALIDATORS`, or the written policy) and convert them to the JSON keys in the script docstring. Ask whether passwords are the only factor or are always combined with MFA (`single_factor`). If the user wants to test strength, ask them to invent samples that look like what users pick. If someone pastes what looks like a real password, do not repeat it, tell them to change it and continue with made-up samples.

### 2. Run the checker
```
python3 scripts/pw_policy.py examples/legacy-portal-policy.json --samples examples/synthetic-samples.txt --context northwind
python3 scripts/pw_policy.py policy.json --samples synthetic.txt --blocklist top-10k.txt --json
python3 scripts/pw_policy.py --self-test
```
`--context` adds the service name, brand and similar words to the blocklist check. Exit code 1 means HIGH findings, 2 means bad input.

### 3. Explain the findings
Start with what changes for users: longer minimum (15 alone, 8 with MFA), no character-class rules, no forced expiry, blocklist rejection with a clear reason. Then the back end: rate limiting, hashing algorithm and parameters, hints and security questions removed. Use the samples table to show that `Password1!`-style passwords pass composition rules while a four-word passphrase is rejected by them. Use `references/nist-800-63b-rules.md` for the exact requirement and `references/entropy-and-hashing.md` when the user asks "how strong is strong enough".

### 4. Deliver
Fill `templates/policy-recommendation.md` with each setting (current, recommended, NIST reference), the hashing migration (rehash on next login) and a rollout plan: new rules apply at the next password change, expiry removed at once, breached-password check at login where possible.

## Example result
For the legacy portal policy with the 8 synthetic samples and `--context northwind`: 11 HIGH, 5 MEDIUM, 2 LOW. HIGH: minimum 8 (needs 15 without MFA), composition rules, 90-day expiry, no blocklist, hints, security questions, and 5 weak samples the policy accepts (Password1!, Summer2025!, Northwind#1, Qwerty123$, P@ssw0rd2026, each ~15-20 bits). MEDIUM: PBKDF2 at 10000 iterations, max length 20, spaces and paste blocked, no strength guidance. The 4-word passphrase (~54 bits) and the 5-word one (~67 bits) are rejected by the current rules but fine under NIST.

## Rules

- Never ask for, store or repeat real passwords, hashes or password files. Work only with made-up samples.
- Entropy numbers are estimates for comparison, not guarantees; say so.
- Quote NIST SHALL vs SHOULD correctly; do not present OWASP hashing numbers as NIST requirements.
- Phishing-resistant MFA or passkeys beat any password rule; recommend them where the risk justifies it.
- Do not recommend weakening a control (e.g. rate limiting) to improve usability without a replacement.
FILE:references/nist-800-63b-rules.md
# NIST SP 800-63B-4 Password Rules (final, 2025)

Section 3.1.1.2 "Password Verifiers" applies to centrally verified passwords (a login form checked by the server). Local unlock PINs are "activation secrets" with different rules (Sec. 3.2.10). SHALL = required, SHOULD = recommended.

| # | Requirement | Level | Script code | In practice |
|---|---|---|---|---|
| 1 | Minimum 15 characters when the password is the only factor; minimum 8 if only used with MFA | SHALL | MIN_LENGTH | Set 15 for password-only logins; 8 is acceptable only if MFA is always enforced |
| 2 | Allow a maximum of at least 64 characters | SHOULD | MAX_LENGTH | Passphrases and password-manager output need room; storage size is fixed by the hash anyway |
| 3 | Accept all printing ASCII characters and space | SHOULD | NO_SPACES | Do not reject `"`, `'`, `<`, spaces; escape correctly instead |
| 4 | Accept Unicode; count each code point as one character | SHOULD | NO_UNICODE | Apply NFC normalization before hashing (NO_NORMALIZATION) |
| 5 | No other composition rules (character-class mixes) | SHALL NOT | COMPOSITION_RULES | Remove "1 upper, 1 digit, 1 symbol" |
| 6 | No periodic forced changes; force a change on evidence of compromise | SHALL NOT | PERIODIC_EXPIRY | Remove 90-day expiry; reset on breach evidence |
| 7 | No hints accessible to unauthenticated users | SHALL NOT | HINTS | Delete stored hints |
| 8 | No knowledge-based authentication / security questions | SHALL NOT | SECURITY_QUESTIONS | Use recovery codes or a verified channel |
| 9 | Verify the entire password, no truncation, no "enter characters 3, 5 and 8" | SHALL | TRUNCATION | Watch out for bcrypt's 72-byte limit (BCRYPT_72_BYTES) |
| - | Compare the full password with a blocklist of common, expected and compromised values; give the reason when rejecting | SHALL | NO_BLOCKLIST, BLOCKLIST_THIN | Breached corpora (e.g. a k-anonymity range API or a downloaded list), dictionary words, service name, username |
| - | Offer guidance to help users choose a strong password, especially after a rejection | SHALL | NO_GUIDANCE | Strength meter and plain-language rejection reasons |
| - | Rate-limit failed attempts: no more than 100 consecutive failures per account (Sec. 3.2.2) | SHALL | NO_RATE_LIMIT | Growing delays, CAPTCHA, risk checks; hard lockouts after 3 tries invite denial of service (LOCKOUT_STRICT) |
| - | Allow password managers and autofill; permit paste | see Sec. 3.1.1.2 | PASTE_BLOCKED | Never block paste on password fields |
| - | Store passwords salted and hashed with a suitable password hashing scheme (Sec. 3.1.1.2, last part) | SHALL | WEAK_STORAGE | Argon2id, scrypt, bcrypt or PBKDF2 with a unique salt; parameters as high as practical |

## Blocklist sizing
NIST notes the blocklist mainly stops online guessing, which is already throttled, so it should cover the passwords an attacker would try before the limit (thousands to a few hundred thousand entries); very large lists mostly frustrate users. Check the whole password, not substrings, but include obvious derivatives of the service name and username.

## Why composition rules and expiry go
Users meet "upper + digit + symbol" with `Password1!`; forced changes produce `Password2!`, `Password3!`. Attack tools model these patterns, so the rules add friction without adding real entropy. Length plus a blocklist does more.

## Sources
- NIST SP 800-63B-4, Digital Identity Guidelines: Authentication and Authenticator Management (July 2025), https://pages.nist.gov/800-63-4/sp800-63b.html
- Appendix A "Strength of Passwords" in the same document
FILE:references/entropy-and-hashing.md
# Entropy Estimates and Password Hashing

## Two estimates
**Charset entropy** = length x log2(pool), pool = 26 lower + 26 upper + 10 digits + 33 symbols (+100 if non-ASCII), counting only the classes used. It is correct for passwords generated at random from that pool and badly overstates human choices: `Password1!` scores 65.7 bits.

**Pattern entropy** (script) approximates how a cracking tool guesses: it walks the password left to right and charges
| Piece | Cost |
|---|---|
| common word from the built-in list (incl. leet like `P@ssw0rd`, context words) | log2(list size) ~ 7.6 bits, +1 if capitalized, +2 if leet |
| year 1950-2039 | log2(90) ~ 6.5 bits |
| keyboard or alphabet run (`qwerty`, `1234`, `zyx`) | log2(26) + log2(length) |
| repeated character (`aaaa`) | one character + log2(count) |
| digits/symbol appended at the end after a word | -1.5 bits (the most common pattern) |
| any other character | log2(pool) |
| passphrase of 3+ words | 12.9 bits per uncommon word (Diceware list of 7776), 1 bit per common word |

The passphrase figure is an upper bound: it holds only if words were picked at random (dice or a generator). "my dog loves pizza" is far weaker. The built-in word list is small; a real cracker uses billions of breached passwords, so treat every estimate as optimistic for human-chosen input.

## Rating scale (pattern bits)
| Bits | Rating | Meaning |
|---|---|---|
| < 28 | very weak | Falls to online guessing or instantly offline |
| 28-35 | weak | Online throttling helps; offline it is minutes |
| 36-59 | fair | OK against online attacks with rate limiting; weak if a fast hash leaks |
| 60-79 | strong | Resists offline attacks on slow hashes |
| >= 80 | very strong | Resists offline attacks on fast hashes |

## Guess rates used for times
- Offline, fast hash (MD5/SHA-x on GPUs): 1e10 guesses per second.
- Offline, slow hash (Argon2id/bcrypt at recommended cost): about 1e4 guesses per second per attacker rig.
- Online with NIST throttling (<= 100 failures per account, then delays): only the first few hundred to thousands of guesses matter, which is why the blocklist is the key online control.
Time shown = median case, 2^(bits-1) / rate.

## Hashing parameters (OWASP Password Storage Cheat Sheet minimums)
| Algorithm | Minimum | Notes |
|---|---|---|
| Argon2id | m = 19456 KiB (19 MiB), t = 2, p = 1 | First choice |
| scrypt | N = 2^17, r = 8, p = 1 | |
| bcrypt | cost 10 | Input limited to 72 bytes; pre-hash with HMAC-SHA256 + base64 or cap the length |
| PBKDF2-HMAC-SHA256 | 600000 iterations | Use where FIPS-140 validated crypto is required |
Every hash needs a unique random salt (>= 16 bytes). An optional pepper (secret key kept outside the database) adds defense in depth. NIST requires salting and a suitable one-way password hashing function; OWASP numbers are a widely used baseline, not a NIST rule.

## Migrating weak hashes
1. Add the new algorithm next to the old one.
2. On successful login, verify with the old hash, then rehash with the new one.
3. For accounts that never log in, wrap the old hash (Argon2id(old_hash)) and mark them, or force a reset after a deadline.
4. Re-check breached-password status at login if your provider supports it.
FILE:templates/policy-recommendation.md
# Password policy recommendation: <system name>

**Scope:** <customer portal / workforce SSO / admin console>   **Factor:** <password only / password + MFA>
**Basis:** NIST SP 800-63B-4 (2025); hashing parameters from the OWASP Password Storage Cheat Sheet
**Summary:** <one sentence: e.g. "Replace complexity and expiry rules with a 15-character minimum and a breached-password blocklist; move hashes to Argon2id.">

## Settings
| Setting | Current | Recommended | NIST | Why |
|---|---|---|---|---|
| Minimum length | <8> | <15 (8 if MFA always on)> | SHALL | <...> |
| Maximum length | <20> | <64 or more> | SHOULD | <...> |
| Composition rules | <upper, lower, digit, symbol> | none | SHALL NOT | <...> |
| Expiry | <90 days> | none; reset on compromise | SHALL NOT | <...> |
| Blocklist | <none> | breached + dictionary + context words, full-password match | SHALL | <...> |
| Spaces / Unicode | <rejected> | accepted, NFC normalized | SHOULD | <...> |
| Paste / password managers | <blocked> | allowed | | <...> |
| Hints / security questions | <yes> | removed | SHALL NOT | <...> |
| Failed attempts | <lock after 3 for 60 min> | throttle, <= 100 consecutive failures | SHALL | <...> |
| Strength guidance | <none> | meter + rejection reason | SHALL | <...> |
| Storage | <PBKDF2-SHA256, 10000> | <Argon2id m=19 MiB t=2 p=1> | SHALL (salted hash) | <...> |

## What the samples show (made-up passwords only)
<Short table or sentence: e.g. "4 of 5 typical patterns (Password1!, Summer2025!) pass today's rules at ~20 bits; a random 4-word passphrase (~54 bits) is rejected today and accepted under the new policy.">

## Rollout
1. <Day 0: remove expiry, allow paste and spaces, enable strength meter>
2. <Week 1: blocklist on new passwords and changes; show the rejection reason>
3. <Week 2: raise minimum length for new passwords; existing users at next change>
4. <Rehash to Argon2id at next login; force reset for dormant accounts after 6 months>
5. <Remove hints and security questions; switch recovery to verified email + recovery codes>

## Communication to users
<2-3 sentences: longer is stronger, passphrases welcome, password managers welcome, no more forced changes>

## Open questions
<MFA coverage, identity provider limits, compliance frameworks that still mention expiry (check current versions; many now follow NIST)>
FILE:examples/legacy-portal-policy.json
{
  "name": "Northwind customer portal (legacy policy)",
  "single_factor": true,
  "min_length": 8,
  "max_length": 20,
  "composition": {"upper": true, "lower": true, "digit": true, "symbol": true},
  "expiry_days": 90,
  "blocklist": {"enabled": false},
  "allow_spaces": false,
  "allow_unicode": false,
  "allow_paste": false,
  "truncate_at": null,
  "hints": true,
  "security_questions": true,
  "strength_guidance": false,
  "rate_limit": {"max_failed_attempts": 3, "lockout_minutes": 60},
  "storage": {"algorithm": "PBKDF2-SHA256", "iterations": 10000, "salted": true}
}
FILE:examples/synthetic-samples.txt
# Made-up sample passwords for the review. NEVER put real passwords in this file.
Password1!
Summer2025!
Northwind#1
Qwerty123$
P@ssw0rd2026
tundra velvet orbit cactus
vT9#qLm2!xR4wZp7
glacier-mango-quietly-violin-ember
FILE:scripts/pw_policy.py
#!/usr/bin/env python3
"""Password policy and entropy checker (Python 3 standard library only).

Checks a password policy config against NIST SP 800-63B-4 (2025) password guidance and estimates
the strength of SYNTHETIC sample passwords. Never use real passwords: samples are masked in the
output unless --show-samples is given, and nothing is stored or sent anywhere.

Policy JSON (all keys optional except min_length):
  {"name": "Customer portal", "single_factor": true,        # password alone, no MFA
   "min_length": 8, "max_length": 20,
   "composition": {"upper": true, "lower": true, "digit": true, "symbol": true},
   "expiry_days": 90,
   "blocklist": {"enabled": true, "breached": true, "context_words": ["acme", "portal"]},
   "allow_spaces": true, "allow_unicode": true, "unicode_normalization": "NFC",
   "allow_paste": true, "truncate_at": null, "hints": false, "security_questions": false,
   "strength_guidance": true,
   "rate_limit": {"max_failed_attempts": 10, "lockout_minutes": 15},
   "storage": {"algorithm": "argon2id", "memory_kib": 19456, "iterations": 2, "salted": true}}
Policy findings (severity):
  HIGH   MIN_LENGTH          < 15 for single-factor passwords, < 8 with MFA (SHALL)
  HIGH   COMPOSITION_RULES   required character classes (SHALL NOT)
  HIGH   PERIODIC_EXPIRY     forced change every N days (SHALL NOT; change only on compromise)
  HIGH   NO_BLOCKLIST        no blocklist check of the full password (SHALL)
  HIGH   HINTS / SECURITY_QUESTIONS   password hints or KBA prompts (SHALL NOT)
  HIGH   TRUNCATION          only part of the password is verified (SHALL verify the whole)
  HIGH   NO_RATE_LIMIT       no throttling of failed attempts (SHALL; at most 100 in a row)
  HIGH   WEAK_STORAGE        plaintext, reversible encryption, MD5/SHA-x or unsalted hashes
  MEDIUM WEAK_KDF_PARAMS     below OWASP minimums (PBKDF2-SHA256 600000, bcrypt cost 10,
                             Argon2id 19 MiB / t=2, scrypt N=2^17)
  MEDIUM BCRYPT_72_BYTES     bcrypt ignores bytes after 72 but max length allows more
  MEDIUM MAX_LENGTH          maximum below 64 (SHOULD allow at least 64)
  MEDIUM NO_SPACES           spaces not accepted (SHOULD accept printing ASCII and space)
  MEDIUM PASTE_BLOCKED       paste / password managers blocked (SHOULD allow)
  MEDIUM NO_GUIDANCE         no strength guidance shown to users (SHALL offer guidance)
  MEDIUM BLOCKLIST_THIN      blocklist without breached passwords or context words
  LOW    NO_UNICODE          Unicode not accepted (SHOULD)
  LOW    NO_NORMALIZATION    Unicode accepted without NFC normalization (SHOULD)
  LOW    LOCKOUT_STRICT      lockout after < 5 attempts: easy denial of service, use throttling
Sample findings:
  HIGH   SAMPLE_WEAK_ACCEPTED  a blocklisted or < 36-bit sample passes the current policy
Entropy (bits): charset = length x log2(pool of character classes used); pattern = a simple
guess-model estimate that charges little for common words, leet, years, keyboard runs, repeats
and passphrase words, and log2(pool) for every other character (per word log2(7776) = 12.9 bits at most). Rating uses the pattern estimate:
< 28 very weak, < 36 weak, < 60 fair, < 80 strong, else very strong.
Usage:
  python3 pw_policy.py policy.json
  python3 pw_policy.py policy.json --samples synthetic.txt [--context northwind,portal] [--blocklist list.txt] [--json]
  python3 pw_policy.py --self-test
Exit code: 0 no HIGH findings, 1 HIGH findings, 2 bad input.
"""
import argparse
import json
import math
import re
import sys
import unicodedata

SEV_ORDER = {"HIGH": 0, "MEDIUM": 1, "LOW": 2}
COMMON = """password passw0rd welcome letmein qwerty qwertz azerty admin administrator login master
dragon monkey sunshine princess football baseball soccer hockey shadow superman batman iloveyou
trustno1 secret summer winter spring autumn fall monday friday january october december love
hello freedom whatever charlie michael jessica jordan pepper ginger cookie chocolate flower
computer internet google apple samsung starwars pokemon matrix killer hunter ranger thunder
tiger lion eagle dolphin falcon soccer liverpool chelsea arsenal barcelona madrid london paris
berlin newyork america canada company office service portal change changeme default guest user
test testing temp temporary access security system server database root toor manager support
student school teacher family mother father daddy mommy baby angel blessed jesus god heaven
money dollar euro bitcoin crypto summer2024 welcome1 password1 password123 abc123 iloveyou1
""".split()
COMMON_SET = set(COMMON)
TOP_BLOCK = set(COMMON) | {"123456", "12345678", "123456789", "1234567890", "111111", "000000",
                           "123123", "654321", "qwerty123", "1q2w3e4r", "zaq12wsx", "p@ssw0rd",
                           "password1!", "welcome123", "admin123", "letmein1", "qwertyuiop"}
LEET = str.maketrans({"@": "a", "4": "a", "0": "o", "1": "i", "!": "i", "3": "e", "$": "s",
                      "5": "s", "7": "t", "+": "t", "8": "b", "9": "g"})
ROWS = ["qwertyuiop", "asdfghjkl", "zxcvbnm", "1234567890", "abcdefghijklmnopqrstuvwxyz", "qwertzuiop", "azertyuiop"]
WORD_BITS = math.log2(7776)


class DataError(ValueError):
    pass


def char_pool(pw):
    pool = 0
    if re.search(r"[a-z]", pw):
        pool += 26
    if re.search(r"[A-Z]", pw):
        pool += 26
    if re.search(r"[0-9]", pw):
        pool += 10
    if re.search(r"[ -/:-@\[-`{-~]", pw):
        pool += 33
    if any(ord(c) > 126 for c in pw):
        pool += 100
    return pool or 1


def class_bits(c):
    if c.islower() and c.isascii():
        return math.log2(26)
    if c.isupper() and c.isascii():
        return math.log2(26)
    if c.isdigit():
        return math.log2(10)
    if ord(c) > 126:
        return math.log2(100)
    return math.log2(33)


def charset_bits(pw):
    return len(pw) * math.log2(char_pool(pw))


def seq_len(s, i):
    """Length of a keyboard/alphabet run (forward or backward) starting at i."""
    best = 1
    low = s.lower()
    for row in ROWS:
        for r in (row, row[::-1]):
            j = r.find(low[i]) if low[i] in r else -1
            if j < 0:
                continue
            n = 1
            while i + n < len(low) and j + n < len(r) and low[i + n] == r[j + n]:
                n += 1
            best = max(best, n)
    return best


def pattern_bits(pw, context=()):
    """Greedy left-to-right guess model. Returns (bits, notes)."""
    notes = []
    vocab = COMMON_SET | {w.lower() for w in context if len(w) >= 3}
    words = [w for w in re.split(r"[\s\-_.]+", pw) if w]
    if len(words) >= 3 and all(re.fullmatch(r"[A-Za-z]{3,}", w) for w in words):
        bits = sum(1.0 if w.lower() in vocab else WORD_BITS for w in words) + math.log2(4)
        notes.append(f"passphrase of {len(words)} words (upper bound if words were picked at random)")
        return min(bits, charset_bits(pw)), notes
    i, bits, low = 0, 0.0, pw.lower()
    brute = math.log2(char_pool(pw))
    while i < len(pw):
        # dictionary word (with leet), longest first
        hit = None
        for L in range(min(len(pw) - i, 14), 3, -1):
            chunk = low[i:i + L]
            plain = chunk.translate(LEET)
            if plain in vocab:
                hit = (L, plain, chunk != plain)
                break
        run = seq_len(pw, i)
        if hit and run < hit[0]:
            L, word, leet = hit
            b = math.log2(len(COMMON)) + (1 if pw[i].isupper() else 0) + (2 if leet else 0)
            notes.append(f"common word '{word}'" + (" (leet)" if leet else ""))
            bits += b
            i += L
            continue
        m = re.match(r"(19[5-9]\d|20[0-3]\d)", pw[i:])
        if m:
            notes.append(f"year {m.group(1)}")
            bits += math.log2(90)
            i += 4
            continue
        n = run
        if n >= 3:
            notes.append(f"keyboard/alphabet run '{pw[i:i + n]}'")
            bits += math.log2(26) + math.log2(n)
            i += n
            continue
        r = 1
        while i + r < len(pw) and pw[i + r] == pw[i]:
            r += 1
        if r >= 3:
            notes.append(f"repeated '{pw[i]}' x{r}")
            bits += class_bits(pw[i]) + math.log2(r)
            i += r
            continue
        bits += brute
        i += 1
    if notes and re.search(r"[0-9!?.]{1,3}$", pw) and len(pw) > 4:
        bits -= 1.5
        notes.append("digits/symbol appended at the end (most common pattern)")
    return max(bits, 0.0), notes


def rating(bits):
    return ("very weak" if bits < 28 else "weak" if bits < 36 else "fair" if bits < 60
            else "strong" if bits < 80 else "very strong")


def crack_time(bits, rate):
    sec = 2 ** (bits - 1) / rate
    for unit, n in (("years", 31557600), ("days", 86400), ("hours", 3600), ("minutes", 60)):
        if sec >= n:
            v = sec / n
            return f"{v:.3g} {unit}" if v < 100 else f"{v:,.0f} {unit}" if v < 1e6 else f"{v:.1e} {unit}"
    return "instant" if sec < 1 else f"{sec:.0f} seconds"


def mask_pw(pw):
    if len(pw) <= 4:
        return "*" * len(pw)
    return pw[:2] + "*" * (len(pw) - 3) + pw[-1:]


def policy_accepts(policy, pw):
    reasons = []
    if len(pw) < int(policy.get("min_length", 0)):
        reasons.append("too short")
    mx = policy.get("max_length")
    if mx and len(pw) > int(mx):
        reasons.append("too long")
    comp = policy.get("composition") or {}
    for key, rx in (("upper", r"[A-Z]"), ("lower", r"[a-z]"), ("digit", r"[0-9]"), ("symbol", r"[^A-Za-z0-9\s]")):
        if comp.get(key) and not re.search(rx, pw):
            reasons.append(f"needs {key}")
    if " " in pw and policy.get("allow_spaces") is False:
        reasons.append("space not allowed")
    if any(ord(c) > 126 for c in pw) and policy.get("allow_unicode") is False:
        reasons.append("unicode not allowed")
    if (policy.get("blocklist") or {}).get("enabled") and pw.lower() in TOP_BLOCK:
        reasons.append("blocklisted")
    return not reasons, reasons


def core_word(low):
    """Strip leading/trailing digits and symbols, undo leet, keep letters: 'P@ssw0rd2026!' -> 'password'."""
    core = re.sub(r"^[\d\W_]+|[\d\W_]+$", "", low)
    return re.sub(r"[^a-z]", "", core.translate(LEET))


def blocklisted(pw, extra=(), context=()):
    low = unicodedata.normalize("NFC", pw).lower()
    if low in TOP_BLOCK or low in extra:
        return "common/breached password"
    core = core_word(low)
    for w in context:
        if w and len(w) >= 3 and w.lower() in core and len(low) - len(w) <= 6:
            return f"based on context word '{w}'"
    if core in COMMON_SET and len(low) - len(core) <= 6:
        return "common word with a few digits/symbols"
    return None


def check_policy(p):
    f = []

    def add(sev, code, msg):
        f.append({"severity": sev, "code": code, "message": msg})
    if "min_length" not in p:
        raise DataError("policy needs min_length")
    single = p.get("single_factor", True)
    mn = int(p["min_length"])
    need = 15 if single else 8
    if mn < need:
        add("HIGH", "MIN_LENGTH", f"minimum {mn} characters; NIST requires >= {need} for passwords used {'alone' if single else 'with MFA'}")
    comp = [k for k, v in (p.get("composition") or {}).items() if v]
    if comp:
        add("HIGH", "COMPOSITION_RULES", f"requires {', '.join(comp)}; composition rules SHALL NOT be imposed (they produce 'Password1!' patterns); rely on length + blocklist")
    if int(p.get("expiry_days") or 0) > 0:
        add("HIGH", "PERIODIC_EXPIRY", f"forced change every {p['expiry_days']} days; SHALL NOT expire periodically, force a change only on evidence of compromise")
    bl = p.get("blocklist") or {}
    if not bl.get("enabled"):
        add("HIGH", "NO_BLOCKLIST", "no blocklist; new passwords SHALL be checked in full against common, expected and breached passwords")
    elif not bl.get("breached") or not bl.get("context_words"):
        miss = [x for x, ok in (("breached passwords", bl.get("breached")), ("context words (service name, username)", bl.get("context_words"))) if not ok]
        add("MEDIUM", "BLOCKLIST_THIN", f"blocklist lacks {' and '.join(miss)}")
    if p.get("hints"):
        add("HIGH", "HINTS", "password hints are stored; SHALL NOT be accessible to unauthenticated users - remove them")
    if p.get("security_questions"):
        add("HIGH", "SECURITY_QUESTIONS", "security questions (KBA) SHALL NOT be used; offer recovery via a verified email/phone or recovery codes")
    if p.get("truncate_at"):
        add("HIGH", "TRUNCATION", f"only the first {p['truncate_at']} characters are checked; the whole password SHALL be verified")
    rl = p.get("rate_limit") or p.get("lockout")
    if not rl:
        add("HIGH", "NO_RATE_LIMIT", "no throttling of failed attempts; SHALL limit to at most 100 consecutive failures per account")
    else:
        n = int(rl.get("max_failed_attempts") or 0)
        if n > 100:
            add("HIGH", "NO_RATE_LIMIT", f"{n} failed attempts allowed; at most 100 consecutive failures")
        elif 0 < n < 5:
            add("LOW", "LOCKOUT_STRICT", f"lockout after {n} attempts lets anyone lock users out; prefer growing delays, CAPTCHA or risk checks before a hard lock")
    st = p.get("storage") or {}
    alg = str(st.get("algorithm", "")).lower().replace("-", "").replace("_", "")
    if not alg:
        add("MEDIUM", "WEAK_STORAGE", "storage algorithm not stated; confirm a salted password hashing function (Argon2id, scrypt, bcrypt, PBKDF2)")
    elif alg in ("plaintext", "plain", "none", "aes", "encrypted", "base64", "md5", "sha1", "sha256", "sha512", "ntlm"):
        add("HIGH", "WEAK_STORAGE", f"{st.get('algorithm')} is not a password hashing function; use Argon2id (or scrypt, bcrypt, PBKDF2) with a unique salt and rehash on next login")
    else:
        if st.get("salted") is False:
            add("HIGH", "WEAK_STORAGE", "hashes are not salted; every password needs a unique random salt")
        it = int(st.get("iterations") or 0)
        if alg.startswith("pbkdf2") and it < 600000:
            add("MEDIUM", "WEAK_KDF_PARAMS", f"PBKDF2 with {it} iterations; OWASP suggests >= 600000 for PBKDF2-HMAC-SHA256")
        if alg == "bcrypt":
            if int(st.get("cost") or 0) < 10:
                add("MEDIUM", "WEAK_KDF_PARAMS", f"bcrypt cost {st.get('cost')}; use >= 10 (tune to ~250 ms)")
            if int(p.get("max_length") or 999) > 72:
                add("MEDIUM", "BCRYPT_72_BYTES", "bcrypt ignores input after 72 bytes; pre-hash (HMAC-SHA256, base64) or switch to Argon2id")
        if alg.startswith("argon2") and (int(st.get("memory_kib") or 0) < 19456 or it < 2):
            add("MEDIUM", "WEAK_KDF_PARAMS", "Argon2id below m=19456 KiB, t=2, p=1 (OWASP minimum)")
        if alg == "scrypt" and int(st.get("n") or 0) < 2 ** 17:
            add("MEDIUM", "WEAK_KDF_PARAMS", "scrypt N below 2^17 (r=8, p=1)")
    mx = p.get("max_length")
    if mx and int(mx) < 64:
        add("MEDIUM", "MAX_LENGTH", f"maximum {mx} characters blocks passphrases and generated passwords; allow at least 64")
    if p.get("allow_spaces") is False:
        add("MEDIUM", "NO_SPACES", "spaces rejected; accept all printing ASCII characters and space so passphrases work")
    if p.get("allow_paste") is False:
        add("MEDIUM", "PASTE_BLOCKED", "paste blocked; allow paste and autofill so password managers work")
    if p.get("strength_guidance") is False:
        add("MEDIUM", "NO_GUIDANCE", "no guidance when a password is rejected; SHALL help users choose (strength meter, reason for rejection)")
    if p.get("allow_unicode") is False:
        add("LOW", "NO_UNICODE", "Unicode rejected; SHOULD accept it (count each code point as one character)")
    elif p.get("allow_unicode") and str(p.get("unicode_normalization", "")).upper() != "NFC":
        add("LOW", "NO_NORMALIZATION", "Unicode accepted without NFC normalization before hashing; the same password typed on two devices may not match")
    return f


def check_samples(policy, samples, extra=(), context=()):
    rows, f = [], []
    ctx = (policy.get("blocklist") or {}).get("context_words") or []
    if isinstance(ctx, bool):
        ctx = []
    ctx = list(ctx) + list(context)
    for pw in samples:
        cb = charset_bits(pw)
        pb, notes = pattern_bits(pw, ctx)
        bl = blocklisted(pw, extra, ctx)
        ok, why = policy_accepts(policy, pw)
        single = policy.get("single_factor", True)
        nist_ok = bl is None and len(pw) >= (15 if single else 8)
        row = {"sample": pw, "length": len(pw), "charset_bits": round(cb, 1), "pattern_bits": round(pb, 1),
               "rating": "very weak" if bl else rating(pb), "blocklist": bl, "policy_accepts": ok,
               "policy_reasons": why, "nist_ok": nist_ok, "notes": notes,
               "offline_fast": crack_time(0 if bl else pb, 1e10), "offline_slow": crack_time(0 if bl else pb, 1e4)}
        rows.append(row)
        if ok and (bl or pb < 36):
            f.append({"severity": "HIGH", "code": "SAMPLE_WEAK_ACCEPTED", "sample": pw,
                      "message": f"sample {{s}} passes the current policy but is {'blocklisted (' + bl + ')' if bl else rating(pb) + f' (~{pb:.0f} bits)'}"})
    return rows, f


def render(policy, findings, rows, show):
    def s(pw):
        return pw if show else mask_pw(pw)
    out = [f"# Password policy review: {policy.get('name', 'policy')}", "",
           f"Basis: NIST SP 800-63B-4 (2025), passwords used {'as the only factor' if policy.get('single_factor', True) else 'with MFA'}",
           f"Findings: {sum(x['severity'] == 'HIGH' for x in findings)} HIGH, {sum(x['severity'] == 'MEDIUM' for x in findings)} MEDIUM, {sum(x['severity'] == 'LOW' for x in findings)} LOW", ""]
    for x in findings:
        msg = x["message"].replace("{s}", s(x["sample"])) if "sample" in x else x["message"]
        out.append(f"- {x['severity']} {x['code']}: {msg}")
    if rows:
        out += ["", "## Synthetic samples" + ("" if show else " (masked; --show-samples to print)"),
                "| Sample | Len | Charset bits | Pattern bits | Rating | Current policy | NIST verdict | Offline fast hash / slow hash |",
                "|---|---|---|---|---|---|---|---|"]
        for r in rows:
            cur = "accepts" if r["policy_accepts"] else "rejects (" + ", ".join(r["policy_reasons"]) + ")"
            nist = "ok" if r["nist_ok"] else ("reject: " + r["blocklist"] if r["blocklist"] else "reject: too short")
            out.append(f"| {s(r['sample'])} | {r['length']} | {r['charset_bits']} | {r['pattern_bits']} | {r['rating']} | {cur} | {nist} | {r['offline_fast']} / {r['offline_slow']} |")
        out += ["", "Charset bits overstate human-chosen passwords; pattern bits are the better guide. Offline times assume 1e10 guesses/s (fast hash) and 1e4 guesses/s (Argon2id/bcrypt), median case."]
    out += ["", "Samples must be made up for the review. Never paste or store real passwords."]
    return "\n".join(out)


def self_test():
    results = []

    def check(name, cond):
        results.append(cond)
        print(("PASS " if cond else "FAIL ") + name)

    def codes(**over):
        p = {"min_length": 15, "max_length": 64, "blocklist": {"enabled": True, "breached": True, "context_words": ["acme"]},
             "allow_spaces": True, "allow_unicode": True, "unicode_normalization": "NFC", "allow_paste": True,
             "strength_guidance": True, "rate_limit": {"max_failed_attempts": 10},
             "storage": {"algorithm": "argon2id", "memory_kib": 19456, "iterations": 2, "salted": True}}
        p.update(over)
        return [x["code"] for x in check_policy(p)]
    check("compliant policy has no findings", codes() == [])
    check("min 8 single factor HIGH", "MIN_LENGTH" in codes(min_length=8))
    check("min 8 with MFA ok", "MIN_LENGTH" not in codes(min_length=8, single_factor=False))
    check("min 6 with MFA HIGH", "MIN_LENGTH" in codes(min_length=6, single_factor=False))
    check("composition HIGH", "COMPOSITION_RULES" in codes(composition={"upper": True, "symbol": True}))
    check("expiry HIGH", "PERIODIC_EXPIRY" in codes(expiry_days=90))
    check("no blocklist HIGH", "NO_BLOCKLIST" in codes(blocklist={"enabled": False}))
    check("thin blocklist MEDIUM", "BLOCKLIST_THIN" in codes(blocklist={"enabled": True}))
    check("hints + KBA HIGH", {"HINTS", "SECURITY_QUESTIONS"} <= set(codes(hints=True, security_questions=True)))
    check("truncation HIGH", "TRUNCATION" in codes(truncate_at=16))
    check("no rate limit HIGH", "NO_RATE_LIMIT" in codes(rate_limit=None))
    check("lockout 3 LOW", "LOCKOUT_STRICT" in codes(rate_limit={"max_failed_attempts": 3}))
    check("sha256 HIGH", "WEAK_STORAGE" in codes(storage={"algorithm": "SHA-256", "salted": True}))
    check("unsalted HIGH", "WEAK_STORAGE" in codes(storage={"algorithm": "pbkdf2-sha256", "iterations": 600000, "salted": False}))
    check("pbkdf2 low iterations MEDIUM", "WEAK_KDF_PARAMS" in codes(storage={"algorithm": "PBKDF2-SHA256", "iterations": 10000}))
    check("bcrypt cost 8 + 72 bytes", {"WEAK_KDF_PARAMS", "BCRYPT_72_BYTES"} <= set(codes(storage={"algorithm": "bcrypt", "cost": 8}, max_length=128)))
    check("max 20 MEDIUM", "MAX_LENGTH" in codes(max_length=20))
    check("spaces/paste/guidance MEDIUM", {"NO_SPACES", "PASTE_BLOCKED", "NO_GUIDANCE"} <= set(codes(allow_spaces=False, allow_paste=False, strength_guidance=False)))
    check("no unicode LOW", "NO_UNICODE" in codes(allow_unicode=False))
    check("no NFC LOW", "NO_NORMALIZATION" in codes(unicode_normalization=None))
    check("charset bits 8 lowercase", abs(charset_bits("abcdefgh") - 8 * math.log2(26)) < 1e-9)
    check("charset pool all classes", char_pool("aA1!") == 95)
    check("leet word cheap", pattern_bits("P@ssw0rd")[0] < 15)
    check("year + word weak", pattern_bits("Summer2025!")[0] < 28)
    check("keyboard run cheap", pattern_bits("qwertyuiop")[0] < 10)
    check("repeat cheap", pattern_bits("aaaaaaaaaa")[0] < 10)
    check("random 16 strong", pattern_bits("vT9#qLm2!xR4wZp7")[0] > 80)
    check("4 random words ~ 53 bits", 50 < pattern_bits("tundra-velvet-orbit-cactus")[0] < 56)
    check("common words passphrase weak", pattern_bits("love summer football")[0] < 10)
    check("blocklisted exact", blocklisted("Password1!") is not None)
    check("context word blocked", blocklisted("Acme2026!", context=["acme"]) is not None)
    check("leet + year blocked", blocklisted("P@ssw0rd2026") is not None)
    check("context word cheap in pattern", pattern_bits("Northwind#1", ["northwind"])[0] < 28)
    check("long random not blocked", blocklisted("vT9#qLm2!xR4wZp7") is None)
    pol = {"min_length": 8, "composition": {"upper": True, "lower": True, "digit": True, "symbol": True}}
    rows, f = check_samples(pol, ["Password1!", "tundra velvet orbit cactus"])
    check("composition policy accepts Password1!", rows[0]["policy_accepts"] and f and f[0]["code"] == "SAMPLE_WEAK_ACCEPTED")
    check("composition policy rejects passphrase", not rows[1]["policy_accepts"] and rows[1]["nist_ok"])
    check("mask hides middle", mask_pw("Password1!") == "Pa*******!")
    check("crack time units", crack_time(0, 1e10) == "instant" and "years" in crack_time(80, 1e10))
    try:
        check_policy({})
        check("missing min_length rejected", False)
    except DataError:
        check("missing min_length rejected", True)
    print(f"{sum(results)}/{len(results)} passed")
    return 0 if all(results) else 1


def main():
    ap = argparse.ArgumentParser(description="Password policy and entropy checker (NIST SP 800-63B-4)")
    ap.add_argument("policy", nargs="?", help="policy JSON")
    ap.add_argument("--samples", help="file with SYNTHETIC sample passwords, one per line (# = comment)")
    ap.add_argument("--blocklist", help="extra blocklist file, one password per line")
    ap.add_argument("--context", default="", help="comma-separated context words (service name, brand, usernames)")
    ap.add_argument("--show-samples", action="store_true", help="print samples unmasked")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args()
    if a.self_test:
        return self_test()
    if not a.policy:
        ap.error("give a policy JSON or --self-test")
    try:
        with open(a.policy, encoding="utf-8") as fh:
            policy = json.load(fh)
        findings = check_policy(policy)
        rows = []
        if a.samples:
            with open(a.samples, encoding="utf-8") as fh:
                samples = [l.rstrip("\n") for l in fh if l.strip() and not l.startswith("#")]
            extra = set()
            if a.blocklist:
                with open(a.blocklist, encoding="utf-8") as fh:
                    extra = {l.strip().lower() for l in fh if l.strip()}
            rows, sf = check_samples(policy, samples, extra, [w.strip() for w in a.context.split(",") if w.strip()])
            findings += sf
    except (OSError, ValueError, DataError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    findings.sort(key=lambda x: SEV_ORDER[x["severity"]])
    if a.json:
        if not a.show_samples:
            for r in rows:
                r["sample"] = mask_pw(r["sample"])
            for x in findings:
                if "sample" in x:
                    x["sample"] = mask_pw(x["sample"])
                    x["message"] = x["message"].replace("{s}", x["sample"])
        print(json.dumps({"findings": findings, "samples": rows}, indent=2))
    else:
        print(render(policy, findings, rows, a.show_samples))
    return 1 if any(x["severity"] == "HIGH" for x in findings) else 0


if __name__ == "__main__":
sys.exit(main())Reviews SQL queries and optional EXPLAIN output for common performance problems such as SELECT *, functions or casts on indexed columns, leading-wildcard LIKE, N+1 query loops, OR across columns vs UNION ALL, AND/OR precedence slips, NOT IN subqueries, deep OFFSET paging, seq scans and disk sorts. Explains each problem and gives a rewritten query. Includes a stdlib Python checker with --self-test.
---
name: sql-query-performance-reviewer
description: Reviews SQL queries and optional EXPLAIN output for common performance problems such as SELECT *, functions or casts on indexed columns, leading-wildcard LIKE, N+1 query loops, OR across columns vs UNION ALL, AND/OR precedence slips, NOT IN subqueries, deep OFFSET paging, seq scans and disk sorts. Explains each problem and gives a rewritten query. Includes a stdlib Python checker with --self-test.
---

# SQL Query Performance Reviewer

You review SQL the way an experienced database engineer does in a code review: you read the query and its plan, find the patterns that make it slow (or quietly wrong), and hand back a rewritten query with a short reason for every change. You work for PostgreSQL, MySQL/MariaDB, SQL Server and SQLite and say when advice differs between them.

## Files in this skill

- `scripts/sql_review.py` - scans a .sql file (one or many statements) and optional EXPLAIN output, prints findings by severity (Python 3 standard library only; never connects to a database or runs the SQL)
- `references/anti-patterns.md` - each finding with why it hurts, a before/after rewrite and engine differences
- `references/reading-explain.md` - how to capture and read EXPLAIN in PostgreSQL and MySQL, and which numbers matter
- `templates/review-report.md` - the review you hand back: summary, findings table, rewritten queries, what to measure
- `examples/order-history.sql`, `examples/order-history-explain.txt`, `examples/indexes.txt` - an online shop's order history page with 7 statements, a PostgreSQL plan and the known indexes

## Workflow

### 1. Collect the inputs
Ask for: the query or a log excerpt with the real statements, the database engine and version, rough table sizes, and if possible `EXPLAIN (ANALYZE, BUFFERS)` (PostgreSQL) or `EXPLAIN ANALYZE` / `EXPLAIN ... \G` (MySQL 8) output. Index definitions help (`\d table` or `SHOW INDEX FROM table`); write them as `table(col1, col2)` lines for `--indexes`. Ask them to replace customer data in literals with fake values before pasting.

### 2. Run the checker
```
python3 scripts/sql_review.py examples/order-history.sql --explain examples/order-history-explain.txt --indexes examples/indexes.txt
python3 scripts/sql_review.py slow.sql --json
python3 scripts/sql_review.py --self-test
```
Exit code 1 means HIGH findings, 2 means bad input. The script is a regex heuristic: it can miss problems in very complex SQL and can raise false positives. Read every statement yourself as well.

### 3. Review
Order the work: correctness first (AND_OR_PRECEDENCE, NOT_IN_SUBQUERY, NO_WHERE_WRITE), then the biggest cost from the plan (SEQ_SCAN_LARGE, ROWS_REMOVED, DISK_SORT), then N_PLUS_ONE (often the largest total time in an app), then the rest. For each finding give the rewrite from `references/anti-patterns.md` adapted to the user's columns. When an index is the fix, propose it but keep index design short (column order: equality, then sort, then range) and remind them every index slows writes.

### 4. Deliver
Fill `templates/review-report.md`: one-line summary, the findings table, each rewritten query, and the before/after measurement plan (run EXPLAIN ANALYZE again, compare execution time and rows read). Never claim a speed-up you did not measure; say "expected".

## Example result
For the example files: 7 statements, 6 HIGH, 7 MEDIUM, 2 LOW. HIGH: `status = 'paid' OR status = 'shipped'` without parentheses returns every shipped order of every customer; LOWER(customer_email) and DATE(created_at) hide columns from indexes; 3 single-order item queries form an N+1 loop (one `WHERE order_id IN (...)` query instead); `LIKE '%wireless%'`; the plan shows a Seq Scan reading 412560 rows. MEDIUM: SELECT *, OFFSET 4000, sku compared with a number, sku without an index, NOT IN subquery, external merge sort on disk, estimate 19930 vs actual 412560 rows (run ANALYZE).

## Rules

- Never run SQL against the user's database yourself and never ask for production credentials.
- Ask for anonymized literals; do not repeat personal data from pasted queries in the report.
- Correctness beats speed: point out queries that return wrong rows even if they are fast.
- Prefer rewriting the query over adding an index; add an index only for a query that runs often or is slow.
- Name the engine when advice is engine-specific (e.g. expression indexes, ILIKE, LIMIT a,b).
- Measured plans beat heuristics: if EXPLAIN ANALYZE disagrees with a finding, trust the plan.
FILE:references/anti-patterns.md
# SQL Performance Anti-Patterns

Each section: what the checker flags, why it hurts, and a rewrite. "Sargable" means the database can use an index to find the rows (Search ARGument ABLE).

## AND_OR_PRECEDENCE (HIGH, correctness)
AND binds tighter than OR, so `customer_id = 7 AND status = 'paid' OR status = 'shipped'` means `(customer_id = 7 AND status = 'paid') OR status = 'shipped'`: every shipped order of every customer, and a full scan.
```
-- after
WHERE customer_id = 7 AND status IN ('paid', 'shipped')
```

## FUNC_ON_COLUMN (HIGH)
`WHERE LOWER(email) = ?`, `YEAR(created_at) = 2026`, `DATE(created_at) = ?`, `price * 2 > 100`: the index stores raw values, so the function must run on every row.
```
-- dates: use a half-open range on the raw column
WHERE created_at >= '2026-10-01' AND created_at < '2026-10-02'
-- arithmetic: move it to the constant side
WHERE price > 50
-- case-insensitive search: store normalized data or index the expression
CREATE INDEX ON customers (LOWER(email));          -- PostgreSQL, SQLite 3.9+
ALTER TABLE customers ADD email_lc VARCHAR(255) AS (LOWER(email)) STORED, ADD INDEX (email_lc);  -- MySQL 5.7+
-- MySQL 8.0.13+ also supports functional indexes: CREATE INDEX ix ON customers ((LOWER(email)));
-- PostgreSQL alternative: the citext type
```

## LEADING_WILDCARD (HIGH)
`LIKE '%wireless%'` cannot use a B-tree index (only a prefix like `'wireless%'` can). Options: full-text search (PostgreSQL `tsvector` + GIN, MySQL `FULLTEXT` + `MATCH ... AGAINST`), a trigram index (`CREATE EXTENSION pg_trgm; CREATE INDEX ... USING gin (name gin_trgm_ops)`), a search engine for product search, or a reversed column for suffix searches (`'%@example.com'`).

## N_PLUS_ONE (HIGH)
One query for a list, then one query per row (an ORM lazy-loading a relation). 50 orders = 51 round trips; each is fast, the page is slow.
```
-- before (x N)
SELECT product_id, qty FROM order_items WHERE order_id = 98211;
-- after (1 query)
SELECT order_id, product_id, qty FROM order_items WHERE order_id IN (98211, 98340, 98502);
-- or join it into the list query
```
ORM fixes: Django `prefetch_related`/`select_related`, Rails `includes`, SQLAlchemy `selectinload`, Hibernate `JOIN FETCH` / `@BatchSize`, Prisma `include`. The checker needs the repeated statements in the file (paste a log excerpt).

## ORDER_BY_RANDOM (HIGH)
`ORDER BY RAND() LIMIT 1` reads and sorts the whole table. Pick a random id in range and take the next row (`WHERE id >= ? ORDER BY id LIMIT 1`), keep a random-number column with an index, or use `TABLESAMPLE SYSTEM (1)` in PostgreSQL.

## NO_WHERE_WRITE (HIGH)
`UPDATE`/`DELETE` without WHERE locks and rewrites every row. If that is intended, do it in batches (`DELETE ... WHERE id IN (SELECT id ... LIMIT 5000)` in a loop) or use `TRUNCATE`.

## SELECT_STAR (MEDIUM)
Reads every column (including large text/JSON), sends more bytes, prevents index-only scans and breaks callers when columns change. List the columns. `SELECT *` inside `EXISTS (...)` is fine.

## OR_ACROSS_COLUMNS (MEDIUM) and OR_SAME_COLUMN (LOW)
`WHERE email = ? OR phone = ?`: one index cannot serve both. PostgreSQL may combine two indexes with a BitmapOr and MySQL with index_merge; if the plan shows a scan instead, split:
```
SELECT id FROM users WHERE email = ?
UNION ALL
SELECT id FROM users WHERE phone = ? AND email IS DISTINCT FROM ?;  -- avoid duplicates (MySQL: NOT (email <=> ?))
```
Same column repeated: `status IN ('paid', 'shipped')` is shorter and plans the same or better.

## IMPLICIT_CAST (MEDIUM) and QUOTED_NUMBER (LOW)
A text column compared with a number (`sku = 40017` on a VARCHAR): MySQL converts every row's value to a number, so the index is skipped and '040017' also matches; PostgreSQL raises an operator error. Quote the value. A numeric column compared with a quoted number (`customer_id = '1042'`) is converted once and is usually fine, but it often means the application binds ids as strings; a parameter typed as text can force a cast on the column side in some drivers (JDBC `setString` on SQL Server NVARCHAR vs VARCHAR is the classic case).

## NOT_IN_SUBQUERY (MEDIUM, correctness)
If the subquery returns a single NULL, `NOT IN` returns no rows at all. Use:
```
SELECT c.id FROM customers c
WHERE NOT EXISTS (SELECT 1 FROM orders o WHERE o.customer_id = c.id);
```
NOT EXISTS plans as an anti-join in every major engine.

## DEEP_OFFSET (MEDIUM)
`LIMIT 20 OFFSET 4000` reads 4020 rows and throws away 4000; page 500 is 25x slower than page 1. Keyset (seek) pagination:
```
SELECT id, created_at, total FROM orders
WHERE customer_id = ? AND (created_at, id) < (?, ?)      -- last row of the previous page
ORDER BY created_at DESC, id DESC
LIMIT 20;
```
Index `(customer_id, created_at, id)`. MySQL supports row comparisons too; SQL Server: `created_at < ? OR (created_at = ? AND id < ?)`.

## COUNT_FOR_EXISTS (LOW)
`SELECT COUNT(*) ... > 0` counts all matches. `SELECT EXISTS (SELECT 1 FROM ... WHERE ...)` stops at the first.

## DISTINCT_JOIN (LOW)
`SELECT DISTINCT u.* FROM users u JOIN orders o ...` builds all user x order rows then removes duplicates. Use `WHERE EXISTS (SELECT 1 FROM orders o WHERE o.user_id = u.id)`.

## NO_INDEX_FOR_FILTER (MEDIUM, needs --indexes)
A column used in WHERE/ON is not the first column of any listed index. Not every filter needs an index (small tables, low-selectivity flags, rare queries). Composite index order: equality columns first, then the ORDER BY column, then range columns; include selected columns for an index-only scan only when the query is hot.
FILE:references/reading-explain.md
# Reading EXPLAIN

## Capture
| Engine | Command | Notes |
|---|---|---|
| PostgreSQL | `EXPLAIN (ANALYZE, BUFFERS) <query>;` | ANALYZE runs the query; wrap writes in `BEGIN; ... ROLLBACK;` |
| MySQL 8 | `EXPLAIN ANALYZE <query>;` or `EXPLAIN <query>\G` | The checker parses the `\G` vertical format |
| MariaDB | `ANALYZE <query>;` / `EXPLAIN <query>\G` | |
| SQL Server | `SET STATISTICS IO, TIME ON;` + actual execution plan | Read manually |
| SQLite | `EXPLAIN QUERY PLAN <query>;` | Look for `SCAN table` vs `SEARCH table USING INDEX` |

Run it on production-like data. A plan on a 1000-row dev table tells you nothing about a 50-million-row table.

## What the checker looks for
| Finding | PostgreSQL sign | MySQL sign |
|---|---|---|
| SEQ_SCAN_LARGE | `Seq Scan on t` with actual rows >= 10000 | `type: ALL`, `rows` >= 10000, `key: NULL` |
| ROWS_REMOVED | `Rows Removed by Filter` >= 9x the rows kept | `filtered` <= 10% on >= 1000 rows |
| EST_MISMATCH | `rows=` estimate vs `actual ... rows=` off by 10x | (EXPLAIN ANALYZE only, read manually) |
| DISK_SORT | `Sort Method: external merge  Disk: ...` | `Using temporary; Using filesort` |
| NESTED_LOOP_MANY | inner node with `loops=` >= 1000 | many rows in the driving table + `ref` lookups |

## Reading a PostgreSQL plan
- Read from the most indented node up; each `->` feeds its parent.
- `cost=a..b` is the planner's guess (arbitrary units), `actual time=a..b` is milliseconds per loop; multiply by `loops`.
- `rows=` in the cost part is the estimate, in the actual part the real count. A 10x miss means stale or missing statistics: `ANALYZE table;`, or extended statistics for correlated columns (`CREATE STATISTICS`).
- `Index Scan` / `Index Only Scan` / `Bitmap Index Scan` = index used. `Heap Fetches` high on an index-only scan = run VACUUM.
- `Buffers: shared read=` counts 8 kB pages from disk; `hit=` from cache.
- `Sort Method: external merge` = the sort did not fit in `work_mem`. Prefer an index that returns rows in order; raise work_mem per session only for known reporting queries.

## Reading MySQL EXPLAIN
- `type` from best to worst: `const`, `eq_ref`, `ref`, `range`, `index` (full index scan), `ALL` (full table scan).
- `key` is the index chosen (`NULL` = none); `possible_keys` lists candidates.
- `rows` x `filtered`% = rows passed on to the next step.
- `Extra`: `Using index` (covering, good), `Using where` (filter after reading), `Using temporary` and `Using filesort` (extra work for GROUP BY / ORDER BY).

## Before/after measurement
1. Run the original 3 times, record median execution time and rows/buffers read.
2. Apply one change at a time (rewrite, then index).
3. Run again with the same parameters; also test a "big" customer and a "small" one, because plans change with data skew.
4. Check write cost for new indexes on hot tables (insert latency, index size with `pg_relation_size` or `information_schema.STATISTICS`).
FILE:templates/review-report.md
# SQL performance review: <query or endpoint name>

**Engine:** <PostgreSQL 16 / MySQL 8.0 / ...>   **Tables:** <orders ~1.2M rows, order_items ~4M>
**Summary:** <one sentence: the main problem and the expected effect of the fix>

## Findings
| # | Severity | Finding | Statement | Why it matters | Fix |
|---|---|---|---|---|---|
| 1 | HIGH | <AND_OR_PRECEDENCE> | <stmt 1> | <returns all shipped orders, full scan> | <parenthesize / IN (...)> |
| 2 | <MEDIUM> | <...> | <...> | <...> | <...> |

## Rewritten queries
### Statement <n>: <name>
Before:
```sql
<original>
```
After:
```sql
<rewrite>
```
Why: <one or two sentences>

## Index changes (only if needed)
```sql
<CREATE INDEX CONCURRENTLY ix_orders_customer_created ON orders (customer_id, created_at DESC, id);>
```
Write cost: <table write rate, expected index size>

## Measure
| Query | Before (ms, rows read) | After (ms, rows read) |
|---|---|---|
| <stmt 1> | <912 ms, 1.2M rows> | <expected: < 5 ms, ~20 rows> |

Run `EXPLAIN (ANALYZE, BUFFERS)` again after each change, with a large and a small customer.

## Not changed
<findings deliberately left, e.g. SELECT * in an admin export, with the reason>
FILE:examples/order-history.sql
-- Order history page of a small online shop (PostgreSQL), captured from the app log.
-- 1. Order list for the account page
SELECT * FROM orders o
WHERE LOWER(o.customer_email) = 'mina.sato@example.com'
  AND o.status = 'paid' OR o.status = 'shipped'
ORDER BY o.created_at DESC
LIMIT 20 OFFSET 4000;

-- 2-4. Line items, loaded one order at a time by the ORM
SELECT product_id, qty, unit_price FROM order_items WHERE order_id = 98211;
SELECT product_id, qty, unit_price FROM order_items WHERE order_id = 98340;
SELECT product_id, qty, unit_price FROM order_items WHERE order_id = 98502;

-- 5. Search box
SELECT p.id, p.name FROM products p
WHERE p.name LIKE '%wireless%' AND p.sku = 40017;

-- 6. Customers who never ordered
SELECT c.id, c.email FROM customers c
WHERE c.id NOT IN (SELECT customer_id FROM orders)
  AND DATE(c.created_at) = '2026-10-01';

-- 7. Order lookup by id from a URL parameter
SELECT o.id, o.total FROM orders o WHERE o.customer_id = '1042';
FILE:examples/order-history-explain.txt
Limit  (cost=48211.30..48211.35 rows=20 width=212) (actual time=912.4..912.5 rows=20 loops=1)
  ->  Sort  (cost=48201.30..48251.12 rows=19930 width=212) (actual time=905.1..911.8 rows=4020 loops=1)
        Sort Key: created_at DESC
        Sort Method: external merge  Disk: 18432kB
        ->  Seq Scan on orders o  (cost=0.00..41870.00 rows=19930 width=212) (actual time=0.03..801.7 rows=412560 loops=1)
              Filter: (((lower(customer_email) = 'mina.sato@example.com'::text) AND (status = 'paid'::text)) OR (status = 'shipped'::text))
              Rows Removed by Filter: 787440
Planning Time: 0.4 ms
Execution Time: 914.9 ms
FILE:examples/indexes.txt
orders(customer_id, created_at)
orders(status)
order_items(order_id)
customers(id)
products(id)
FILE:scripts/sql_review.py
#!/usr/bin/env python3
"""SQL query performance reviewer (Python 3 standard library only).

Reads a .sql file (one or more statements separated by ;) and, optionally, EXPLAIN output,
and flags common performance problems with a heuristic, regex-based scan. It does not connect
to a database and never runs the SQL. Treat findings as review prompts, not proof.

Query findings (severity):
  HIGH   FUNC_ON_COLUMN     function or arithmetic wraps a column in WHERE/ON (index cannot be used)
  HIGH   LEADING_WILDCARD   LIKE/ILIKE pattern starts with % or _ (full scan)
  HIGH   N_PLUS_ONE         the same statement shape repeats >= --repeat times with different literals
  HIGH   ORDER_BY_RANDOM    ORDER BY RAND()/RANDOM() sorts the whole table
  HIGH   NO_WHERE_WRITE     UPDATE or DELETE without WHERE
  HIGH   AND_OR_PRECEDENCE  AND and OR mixed without parentheses: AND binds first, so the OR branch
                            matches rows from the whole table (wrong results and a full scan)
  MEDIUM SELECT_STAR        SELECT * or alias.* (wide rows, no covering index, breaks on schema change)
  MEDIUM OR_ACROSS_COLUMNS  OR between different columns in WHERE (consider UNION ALL)
  MEDIUM IMPLICIT_CAST      code/phone/sku-like (text) column compared with a bare number: MySQL
                            casts every row and skips the index, PostgreSQL raises a type error
  MEDIUM NOT_IN_SUBQUERY    NOT IN (SELECT ...): NULL trap and poor anti-join plans; use NOT EXISTS
  MEDIUM DEEP_OFFSET        OFFSET (or LIMIT a,b) >= 1000: keyset pagination instead
  MEDIUM NO_INDEX_FOR_FILTER  (needs --indexes) filtered/joined column not leading any known index
  LOW    QUOTED_NUMBER      id/number column compared with a quoted number: usually fine for a literal,
                            but a sign the app binds ids as text (typed text parameters can force a cast)
  LOW    OR_SAME_COLUMN     col = a OR col = b: write col IN (a, b)
  LOW    COUNT_FOR_EXISTS   COUNT(*) > 0 used as an existence check; use EXISTS
  LOW    DISTINCT_JOIN      SELECT DISTINCT with JOIN may hide a join fan-out
EXPLAIN findings (PostgreSQL text format and MySQL EXPLAIN \\G vertical format):
  HIGH   SEQ_SCAN_LARGE     Seq Scan / type ALL over >= --large-rows rows
  MEDIUM ROWS_REMOVED       a filter throws away >= 90% of the rows it reads
  MEDIUM EST_MISMATCH       estimated vs actual rows differ by >= 10x (stale statistics)
  MEDIUM DISK_SORT          external merge sort / Using filesort with Using temporary
  LOW    NESTED_LOOP_MANY   inner side of a nested loop runs >= 1000 loops
Usage:
  python3 sql_review.py query.sql
  python3 sql_review.py query.sql --explain plan.txt --indexes indexes.txt --json
  python3 sql_review.py --self-test
--indexes file: one index per line, e.g. "orders(customer_id, created_at)".
Exit code: 0 no HIGH findings, 1 HIGH findings, 2 bad input.
"""
import argparse
import json
import re
import sys
from collections import defaultdict

SEV_ORDER = {"HIGH": 0, "MEDIUM": 1, "LOW": 2}
FUNCS = ("lower", "upper", "trim", "ltrim", "rtrim", "date", "year", "month", "day", "cast",
         "coalesce", "ifnull", "nvl", "substring", "substr", "left", "right", "to_char",
         "date_trunc", "extract", "date_format", "convert", "abs", "round", "concat", "length")
ID_COL = re.compile(r"(^|_)(id|number|count|qty|quantity|amount)$")
TEXT_COL = re.compile(r"(phone|zip|postal_code|postcode|sku|isbn|iban|code|_no)$")
KEYWORDS = {"where", "on", "and", "or", "not", "join", "left", "right", "inner", "outer", "full",
            "cross", "group", "order", "by", "limit", "offset", "having", "union", "select", "from",
            "as", "using", "set", "values", "into", "lateral", "natural", "straight_join", "with"}


class DataError(ValueError):
    pass


def mask(sql):
    """Remove comments, replace string literals with 'Sn' tokens; return (masked, literals)."""
    sql = re.sub(r"--[^\n]*", " ", sql)
    sql = re.sub(r"/\*.*?\*/", " ", sql, flags=re.S)
    lits = []

    def rep(m):
        lits.append(m.group(0)[1:-1].replace("''", "'"))
        return f"'S{len(lits) - 1}'"
    return re.sub(r"'(?:[^']|'')*'", rep, sql), lits


def split_statements(text):
    masked, lits = mask(text)
    out = []
    for part in masked.split(";"):
        s = " ".join(part.split())
        if s:
            out.append(s)
    return out, lits


def clause(stmt, start, enders):
    m = re.search(r"\b" + start + r"\b", stmt, re.I)
    if not m:
        return ""
    rest = stmt[m.end():]
    e = re.search(r"\b(" + "|".join(enders) + r")\b", rest, re.I)
    return rest[:e.start()] if e else rest


def where_part(stmt):
    return clause(stmt, "where", ["group\\s+by", "order\\s+by", "limit", "offset", "having",
                                  "union", "returning", "for\\s+update", "window"])


def join_on_parts(stmt):
    return re.findall(r"\bon\b(.*?)(?=\b(?:join|left|right|inner|full|cross|where|group|order|limit|union)\b|$)",
                      stmt, re.I)


def aliases(stmt):
    amap = {}
    for m in re.finditer(r"\b(?:from|join)\s+([a-z_][\w.]*)(?:\s+(?:as\s+)?([a-z_]\w*))?", stmt, re.I):
        table, alias = m.group(1).lower(), (m.group(2) or "").lower()
        if table == "select" or table.startswith("("):
            continue
        amap[table.split(".")[-1]] = table.split(".")[-1]
        if alias and alias not in KEYWORDS:
            amap[alias] = table.split(".")[-1]
    return amap


def shape(stmt):
    s = re.sub(r"'S\d+'", "?", stmt)
    s = re.sub(r"\b\d+(\.\d+)?\b", "?", s)
    s = re.sub(r"\(\s*\?(\s*,\s*\?)*\s*\)", "(?)", s)
    return s.lower()


def review_sql(text, repeat=3, indexes=None):
    stmts, lits = split_statements(text)
    if not stmts:
        raise DataError("no SQL statements found")
    findings = []

    def add(sev, code, n, msg):
        findings.append({"severity": sev, "code": code, "statement": n, "message": msg})

    shapes = defaultdict(list)
    for n, st in enumerate(stmts, 1):
        low = st.lower()
        kind = low.split()[0]
        shapes[shape(st)].append(n)
        where = where_part(st)
        ons = join_on_parts(st)
        filt = " AND ".join([where] + ons)
        if re.search(r"\bselect\s+(distinct\s+)?(\w+\.)?\*", low) or re.search(r",\s*\w+\.\*", low):
            add("MEDIUM", "SELECT_STAR", n, "SELECT * reads every column; list the columns you need so a covering index can serve the query")
        for m in re.finditer(r"\b(" + "|".join(FUNCS) + r")\s*\(\s*([a-z_][\w]*(?:\.[a-z_]\w*)?)\b[^()]*\)\s*(=|<>|!=|<=|>=|<|>|\bin\b|\blike\b|\bbetween\b)",
                             filt, re.I):
            col = m.group(2)
            if col.lower() in KEYWORDS or re.fullmatch(r"S\d+", col):
                continue
            add("HIGH", "FUNC_ON_COLUMN", n, f"{m.group(1)}({col}) in a filter hides {col} from its index; compare the bare column (e.g. a range on the raw value) or add an expression index")
        for m in re.finditer(r"([a-z_][\w.]*)\s*[+\-*/]\s*\d+\s*(=|<|>|<=|>=)", filt, re.I):
            add("HIGH", "FUNC_ON_COLUMN", n, f"arithmetic on {m.group(1)} in a filter; move it to the other side of the comparison")
        for m in re.finditer(r"([a-z_][\w.]*)\s+(not\s+)?(i?like)\s+'S(\d+)'", st, re.I):
            pat = lits[int(m.group(4))]
            if pat[:1] in ("%", "_"):
                add("HIGH", "LEADING_WILDCARD", n, f"{m.group(1)} {m.group(3).upper()} '{pat}' starts with a wildcard, so no B-tree index helps; use full-text search, a trigram index or a reversed column")
        if re.search(r"order\s+by\s+(rand|random|newid)\s*\(\s*\)", low):
            add("HIGH", "ORDER_BY_RANDOM", n, "ORDER BY random sorts every row; pick random ids or use TABLESAMPLE")
        if kind in ("update", "delete") and not where.strip():
            add("HIGH", "NO_WHERE_WRITE", n, f"{kind.upper()} without WHERE touches every row; add a WHERE clause or batch it")
        if where:
            top = where
            while re.search(r"\([^()]*\)", top):
                top = re.sub(r"\([^()]*\)", " _ ", top)
            top = re.sub(r"\bbetween\s+\S+\s+and\b", "between x", top, flags=re.I)
            if re.search(r"\band\b", top, re.I) and re.search(r"\bor\b", top, re.I):
                add("HIGH", "AND_OR_PRECEDENCE", n, "AND and OR are mixed without parentheses; AND binds first, so 'a AND b OR c' returns every row matching c; add parentheses: a AND (b OR c)")
            for group in re.split(r"\band\b", where, flags=re.I):
                if not re.search(r"\bor\b", group, re.I):
                    continue
                cols = re.findall(r"([a-z_][\w.]*)\s*(?:=|<>|!=|<|>|\bin\b|\blike\b)", group, re.I)
                cols = [c.lower() for c in cols if c.lower() not in KEYWORDS and not re.fullmatch(r"s\d+", c.lower())]
                if len(set(cols)) >= 2:
                    add("MEDIUM", "OR_ACROSS_COLUMNS", n, f"OR across {', '.join(sorted(set(cols)))}: one index cannot serve both sides; split into UNION ALL of indexed queries (or check the plan uses a bitmap OR)")
                elif len(cols) >= 2:
                    add("LOW", "OR_SAME_COLUMN", n, f"repeated OR on {cols[0]}; write {cols[0]} IN (...)")
        for m in re.finditer(r"([a-z_][\w.]*)\s*(=|<>|!=|<|>)\s*'S(\d+)'", filt, re.I):
            col = m.group(1).split(".")[-1].lower()
            if ID_COL.search(col) and re.fullmatch(r"-?\d+(\.\d+)?", lits[int(m.group(3))]):
                add("LOW", "QUOTED_NUMBER", n, f"{m.group(1)} compared with the string '{lits[int(m.group(3))]}'; bind it as a number so the driver never sends a text parameter")
        for m in re.finditer(r"([a-z_][\w.]*)\s*(=|<>|!=)\s*(\d{3,})\b", filt, re.I):
            col = m.group(1).split(".")[-1].lower()
            if TEXT_COL.search(col):
                add("MEDIUM", "IMPLICIT_CAST", n, f"{m.group(1)} looks like a text column but is compared with the number {m.group(3)}; MySQL then casts every row and skips the index (PostgreSQL raises a type error); quote the value")
        if re.search(r"\bnot\s+in\s*\(\s*select\b", low):
            add("MEDIUM", "NOT_IN_SUBQUERY", n, "NOT IN (SELECT ...) returns no rows if the subquery yields a NULL and often plans badly; use NOT EXISTS")
        m = re.search(r"\boffset\s+(\d+)", low) or re.search(r"\blimit\s+(\d+)\s*,\s*\d+", low)
        if m and int(m.group(1)) >= 1000:
            add("MEDIUM", "DEEP_OFFSET", n, f"OFFSET {m.group(1)} reads and throws away {m.group(1)} rows; use keyset pagination (WHERE (created_at, id) < (?, ?) ORDER BY ... LIMIT n)")
        if re.search(r"count\s*\(\s*(\*|1)\s*\)\s*(>\s*0|>=\s*1)", low):
            add("LOW", "COUNT_FOR_EXISTS", n, "COUNT(*) > 0 counts every match; EXISTS stops at the first")
        if re.search(r"\bselect\s+distinct\b", low) and re.search(r"\bjoin\b", low):
            add("LOW", "DISTINCT_JOIN", n, "DISTINCT on a join often hides duplicate rows from a one-to-many join; use EXISTS or aggregate first")
        if indexes is not None:
            amap = aliases(st)
            seen = set()
            for m in re.finditer(r"\b([a-z_]\w*)\.([a-z_]\w*)\s*(?:=|<|>|<=|>=|\bin\b|\bbetween\b)", filt, re.I):
                table = amap.get(m.group(1).lower())
                col = m.group(2).lower()
                if not table or (table, col) in seen:
                    continue
                seen.add((table, col))
                if table in indexes and col not in indexes[table]:
                    add("MEDIUM", "NO_INDEX_FOR_FILTER", n, f"{table}.{col} is filtered or joined but no listed index on {table} starts with it")
    for sh, ns in shapes.items():
        if len(ns) >= repeat and ("where" in sh):
            add("HIGH", "N_PLUS_ONE", ns[0], f"statements {', '.join(map(str, ns))} have the same shape with different values ({len(ns)}x); fetch them in one query with IN (...) or a JOIN")
    findings.sort(key=lambda f: (SEV_ORDER[f["severity"]], f["statement"], f["code"]))
    shown = [re.sub(r"'S(\d+)'", lambda m: "'" + lits[int(m.group(1))].replace("'", "''") + "'", st) for st in stmts]
    return shown, findings


def parse_indexes(text):
    idx = defaultdict(set)
    for line in text.splitlines():
        m = re.match(r"\s*([\w.]+)\s*\(\s*([\w\s,]+)\)", line)
        if m:
            idx[m.group(1).split(".")[-1].lower()].add(m.group(2).split(",")[0].strip().lower())
    return idx


def review_explain(text, large=10000):
    findings = []

    def add(sev, code, msg):
        findings.append({"severity": sev, "code": code, "statement": 0, "message": msg})
    lines = text.splitlines()
    if re.search(r"^\s*(\*+ \d+\. row|select_type:)", text, re.M):
        for block in re.split(r"\*+ \d+\. row \*+", text):
            f = dict(re.findall(r"^\s*(\w+):\s*(.*?)\s*$", block, re.M))
            if not f:
                continue
            rows = int(f.get("rows", "0") or 0)
            if f.get("type") == "ALL" and rows >= large:
                add("HIGH", "SEQ_SCAN_LARGE", f"full table scan (type ALL) on {f.get('table')} ~{rows} rows; key={f.get('key', 'NULL')}")
            extra = f.get("Extra", "")
            if "Using filesort" in extra and "Using temporary" in extra:
                add("MEDIUM", "DISK_SORT", f"{f.get('table')}: Using temporary; Using filesort - an index matching GROUP BY/ORDER BY avoids it")
            filtered = float(f.get("filtered", "100") or 100)
            if rows >= 1000 and filtered <= 10:
                add("MEDIUM", "ROWS_REMOVED", f"{f.get('table')}: only {filtered:g}% of {rows} rows pass the filter")
        return findings
    for i, line in enumerate(lines):
        m = re.search(r"(Parallel )?Seq Scan on (\S+).*?rows=(\d+)", line)
        if m:
            act = re.search(r"actual[^)]*rows=(\d+)", line)
            rows = int(act.group(1) if act else m.group(3))
            if rows >= large:
                add("HIGH", "SEQ_SCAN_LARGE", f"Seq Scan on {m.group(2)} returns ~{rows} rows; an index on the filter columns may help")
        m = re.search(r"Rows Removed by Filter:\s*(\d+)", line)
        if m:
            removed = int(m.group(1))
            prev = next((l for l in reversed(lines[:i]) if "actual" in l), "")
            k = re.search(r"actual[^)]*rows=(\d+)", prev)
            kept = int(k.group(1)) if k else 0
            if removed >= 1000 and removed >= 9 * max(kept, 1):
                add("MEDIUM", "ROWS_REMOVED", f"filter removed {removed} rows to keep {kept} ({prev.strip()[:60]}...)")
        m = re.search(r"cost=[\d.]+\.\.[\d.]+ rows=(\d+).*actual time=[\d.]+\.\.[\d.]+ rows=(\d+) loops=(\d+)", line)
        if m:
            est, act, loops = int(m.group(1)), int(m.group(2)), int(m.group(3))
            if max(est, act) >= 100 and max(est, act) >= 10 * max(min(est, act), 1):
                node = line.strip().lstrip("->").strip().split("  ")[0]
                add("MEDIUM", "EST_MISMATCH", f"{node[:50]}: estimated {est} rows, actual {act}; run ANALYZE")
            if loops >= 1000:
                node = line.strip().lstrip("->").strip().split("  ")[0]
                add("LOW", "NESTED_LOOP_MANY", f"{node[:50]} runs {loops} loops; check the join index or consider a hash join")
        if re.search(r"Sort Method: external merge", line):
            add("MEDIUM", "DISK_SORT", "sort spilled to disk (external merge); add an index for ORDER BY or raise work_mem for this query")
    findings.sort(key=lambda f: SEV_ORDER[f["severity"]])
    return findings


def render(path, stmts, findings):
    out = [f"# SQL performance review: {path}", "",
           f"{len(stmts)} statement(s); {sum(f['severity'] == 'HIGH' for f in findings)} HIGH, "
           f"{sum(f['severity'] == 'MEDIUM' for f in findings)} MEDIUM, {sum(f['severity'] == 'LOW' for f in findings)} LOW", ""]
    for n, st in enumerate(stmts, 1):
        out.append(f"{n}. {st[:110]}{'...' if len(st) > 110 else ''}")
    out += ["", "## Findings"]
    if not findings:
        out.append("- none (heuristics only: still check the real plan with EXPLAIN ANALYZE)")
    for f in findings:
        where = f"stmt {f['statement']}" if f["statement"] else "EXPLAIN"
        out.append(f"- {f['severity']} {f['code']} ({where}): {f['message']}")
    return "\n".join(out)


def self_test():
    results = []

    def check(name, cond):
        results.append(cond)
        print(("PASS " if cond else "FAIL ") + name)

    def codes(sql, **kw):
        return [f["code"] for f in review_sql(sql, **kw)[1]]
    check("select star", "SELECT_STAR" in codes("SELECT * FROM users WHERE id = 1"))
    check("alias star", "SELECT_STAR" in codes("SELECT o.* FROM orders o WHERE o.id = 1"))
    check("explicit columns ok", "SELECT_STAR" not in codes("SELECT id, name FROM users WHERE id = 1"))
    check("lower(col) HIGH", "FUNC_ON_COLUMN" in codes("SELECT id FROM users WHERE LOWER(email) = 'a@b.c'"))
    check("year(col) HIGH", "FUNC_ON_COLUMN" in codes("SELECT id FROM orders WHERE YEAR(created_at) = 2026"))
    check("arithmetic HIGH", "FUNC_ON_COLUMN" in codes("SELECT id FROM t WHERE price * 2 > 100"))
    check("function on value side ok", "FUNC_ON_COLUMN" not in codes("SELECT id FROM users WHERE email = LOWER('A@B.C')"))
    check("leading wildcard", "LEADING_WILDCARD" in codes("SELECT id FROM p WHERE name LIKE '%phone%'"))
    check("trailing wildcard ok", "LEADING_WILDCARD" not in codes("SELECT id FROM p WHERE name LIKE 'phone%'"))
    check("wildcard inside string literal ignored", "LEADING_WILDCARD" not in codes("SELECT 'x LIKE %y' AS note FROM p WHERE id = 1"))
    check("N+1 detected", "N_PLUS_ONE" in codes("SELECT name FROM users WHERE id = 1; SELECT name FROM users WHERE id = 2; SELECT name FROM users WHERE id = 3;"))
    check("2 repeats not N+1", "N_PLUS_ONE" not in codes("SELECT name FROM users WHERE id = 1; SELECT name FROM users WHERE id = 2;"))
    check("OR across columns", "OR_ACROSS_COLUMNS" in codes("SELECT id FROM u WHERE email = 'a' OR phone = 'b'"))
    check("OR same column LOW", "OR_SAME_COLUMN" in codes("SELECT id FROM u WHERE status = 'a' OR status = 'b'"))
    check("quoted number LOW", "QUOTED_NUMBER" in codes("SELECT id FROM orders WHERE customer_id = '42'"))
    check("implicit cast phone number", "IMPLICIT_CAST" in codes("SELECT id FROM users WHERE phone = 5551234"))
    check("number id ok", "QUOTED_NUMBER" not in codes("SELECT id FROM orders WHERE customer_id = 42"))
    check("NOT IN subquery", "NOT_IN_SUBQUERY" in codes("SELECT id FROM a WHERE id NOT IN (SELECT a_id FROM b)"))
    check("deep offset", "DEEP_OFFSET" in codes("SELECT id FROM a ORDER BY id LIMIT 20 OFFSET 50000"))
    check("mysql limit a,b offset", "DEEP_OFFSET" in codes("SELECT id FROM a ORDER BY id LIMIT 20000, 20"))
    check("order by rand", "ORDER_BY_RANDOM" in codes("SELECT id FROM a ORDER BY RAND() LIMIT 1"))
    check("delete without where", "NO_WHERE_WRITE" in codes("DELETE FROM sessions"))
    check("AND/OR precedence HIGH", "AND_OR_PRECEDENCE" in codes("SELECT id FROM o WHERE a = 1 AND b = 2 OR b = 3"))
    check("parenthesized OR ok", "AND_OR_PRECEDENCE" not in codes("SELECT id FROM o WHERE a = 1 AND (b = 2 OR b = 3)"))
    check("BETWEEN ... AND not an AND", "AND_OR_PRECEDENCE" not in codes("SELECT id FROM o WHERE d BETWEEN 1 AND 5 OR e = 2"))
    check("literals restored in output", "'mina'" in review_sql("SELECT id FROM u WHERE name = 'mina'")[0][0])
    check("count for exists", "COUNT_FOR_EXISTS" in codes("SELECT CASE WHEN COUNT(*) > 0 THEN 1 END FROM a WHERE b = 1"))
    check("distinct join", "DISTINCT_JOIN" in codes("SELECT DISTINCT u.id FROM users u JOIN orders o ON o.user_id = u.id"))
    idx = parse_indexes("orders(customer_id, created_at)\nusers(id)")
    c = codes("SELECT o.id FROM orders o JOIN users u ON u.id = o.customer_id WHERE o.status = 'paid'", indexes=idx)
    check("no index for filter", c.count("NO_INDEX_FOR_FILTER") == 1)
    check("comments stripped", codes("-- SELECT * FROM x\nSELECT id FROM users WHERE id = 1") == [])
    pg = """Seq Scan on orders  (cost=0.00..25000.00 rows=50 width=8) (actual time=0.1..310.2 rows=48210 loops=1)
  Filter: (status = 'paid'::text)
  Rows Removed by Filter: 951790
Sort Method: external merge  Disk: 51200kB"""
    e = [f["code"] for f in review_explain(pg)]
    check("pg seq scan large", "SEQ_SCAN_LARGE" in e)
    check("pg rows removed", "ROWS_REMOVED" in e)
    check("pg estimate mismatch", "EST_MISMATCH" in e)
    check("pg disk sort", "DISK_SORT" in e)
    my = """*************************** 1. row ***************************
           id: 1
  select_type: SIMPLE
        table: orders
         type: ALL
          key: NULL
         rows: 980000
     filtered: 5.00
        Extra: Using where; Using temporary; Using filesort"""
    e = [f["code"] for f in review_explain(my)]
    check("mysql type ALL", "SEQ_SCAN_LARGE" in e and "DISK_SORT" in e and "ROWS_REMOVED" in e)
    try:
        review_sql("  -- only a comment\n")
        check("empty input rejected", False)
    except DataError:
        check("empty input rejected", True)
    print(f"{sum(results)}/{len(results)} passed")
    return 0 if all(results) else 1


def main():
    ap = argparse.ArgumentParser(description="SQL query performance reviewer (heuristic)")
    ap.add_argument("sql", nargs="?", help=".sql file with one or more statements")
    ap.add_argument("--explain", help="EXPLAIN output (PostgreSQL text or MySQL \\G)")
    ap.add_argument("--indexes", help="known indexes, one per line: table(col1, col2)")
    ap.add_argument("--repeat", type=int, default=3, help="N+1 threshold (default 3)")
    ap.add_argument("--large-rows", type=int, default=10000, help="rows for SEQ_SCAN_LARGE (default 10000)")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args()
    if a.self_test:
        return self_test()
    if not a.sql:
        ap.error("give a .sql file or --self-test")
    try:
        with open(a.sql, encoding="utf-8") as fh:
            text = fh.read()
        idx = None
        if a.indexes:
            with open(a.indexes, encoding="utf-8") as fh:
                idx = parse_indexes(fh.read())
        stmts, findings = review_sql(text, a.repeat, idx)
        if a.explain:
            with open(a.explain, encoding="utf-8") as fh:
                findings += review_explain(fh.read(), a.large_rows)
    except (OSError, DataError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    if a.json:
        print(json.dumps({"statements": stmts, "findings": findings}, indent=2))
    else:
        print(render(a.sql, stmts, findings))
    return 1 if any(f["severity"] == "HIGH" for f in findings) else 0


if __name__ == "__main__":
sys.exit(main())Build an image-ready and motion-ready brief for one hero shot of a lantern-lit old-town river at dusk: ochre shophouses, a roofed wooden footbridge, floating paper lanterns, a rowboat with a rower, light, fixed details, a motion map, and two prompt seeds: a 16:9 still image and an image-to-video animation.
Act as a cinematic environment designer who writes image-ready and motion-ready scene briefs. Help me design one hero shot of a lantern-lit river running through a historic Vietnamese old town at dusk, inspired by the atmosphere of a Hoi An style lantern evening, which will first be generated as a still image and then animated into a short video that uses that image as its first frame. Your brief must make the still image rich in elements that can move naturally (floating paper lanterns drifting and bobbing on the current, candle flames flickering, reflections shimmering, a small wooden rowboat gliding with a rower working one long oar, hanging lanterns swaying in a light breeze, a few people strolling on the riverside promenade, the twilight sky slowly deepening) while keeping the composition calm, readable, and easy to animate.

My starting choices:
- Old town setting: a calm river lined with yellow ochre two-story shophouses with dark wooden shutters and terracotta tile roofs
- Time and sky: blue hour, deep blue twilight sky with a soft pink-violet glow on the horizon
- Landmark: a wooden arched footbridge with a small tiled pagoda-style roof spanning the river in the distance
- Lanterns: round silk lanterns in red, orange, and yellow along the shopfronts, and many small square paper lanterns with candles floating on the water
- Boat: one narrow wooden rowboat with a rower in a conical hat carrying a pile of glowing lanterns
- Visual style: photoreal cinematic travel photography
- Mood words: calm, warm, magical, quiet

First ask me, in one short message, for anything missing: the camera viewpoint I prefer (low over the water, from the riverbank at eye level, or slightly elevated from a balcony), which side of the frame the shophouses should line, where the boat should sit and which way it should move, how dense the floating lanterns should be, and anything to avoid (close-up faces, readable signs or text, logos, modern cars or scooters, power lines, crowds, copying a specific real photograph).

Then produce the brief with these sections:

1. **Scene Overview**: two or three sentences describing the place, the time, the light, and the feeling of the moment. Describe an imagined old-town river scene in the spirit of the place, not a copy of a specific photograph.

2. **Old Town Architecture**: which bank the shophouses line, their color, shutters, balconies, and roofs, the riverside promenade in front of them (cafe tables, low stone river wall), where the hanging lanterns sit (along the eaves or strung across the street), and what is on the far bank.

3. **Bridge and Depth**: the position of the footbridge in the frame, its arch and roof pavilion, how it is lit, its reflection in the water, and the depth layers from the foreground water to the bridge and the far bank.

4. **Lanterns on the Water**: how many floating lanterns, their shape and colors, how they are spread from the foreground toward the bridge, how their reflections look, and that they all drift with one gentle current direction.

5. **Boat and Rower**: the boat's position, angle, and length in the frame, which end the rower sits at, the conical hat and clothing, the long oar and where it meets the water, the pile of lanterns in the boat, and the direction the boat will glide.

6. **Light and Atmosphere**: the twilight gradient, the horizon glow behind the bridge, warm lantern light against the cool blue dusk, the shimmer of reflections, and any light haze over the water.

7. **Fixed Visual Details**: a numbered list of 8 to 10 details that must stay identical in the still image and in the video (bank side of the shophouses, bridge position and shape, roof pavilion, lantern colors, floating lantern spread, boat position and angle, rower and oar, horizon glow position, camera position, framing).

8. **Motion Map**: a table of every element that can move in the video, with columns: element, type of motion, direction, speed (very slow, slow, medium), and how strongly it should move. Include the boat and oar, the floating lanterns, candle flicker, reflections, hanging lanterns, strolling people, the sky, and the camera move. Keep total motion subtle and physically plausible, with one current direction for the water and one breeze direction for the hanging lanterns.

9. **Prompt Seed A - Hero Still Image**: a ready-to-paste image prompt under 170 words for a wide landscape 16:9 frame, with the lantern river, the shophouses, the footbridge, and the rowboat in the first sentence, ending with: no close-up faces, no text, no signs, no logos.

10. **Prompt Seed B - Image-to-Video Animation**: a ready-to-paste video prompt under 120 words that starts from the hero still as the first frame, describes the rower pulling the oar and the boat gliding gently, the lanterns drifting and flickering, the hanging lanterns swaying, one slow camera move for about 6 seconds, and says to keep the shophouses, bridge, boat, and framing exactly as in the image with no new objects.

Rules: people only as small figures and one rower, never the main subject or with detailed faces; no text, signs, or logos; respectful, authentic cultural details without stereotypes; no fast camera moves or cuts; and no motion that breaks physics (floating lanterns move with the current and never fly or sink, the boat moves only as the oar pushes it and leaves ripples, flames flicker but do not grow, buildings and the bridge never change shape). Use short paragraphs and lists.
Macro photo of a needle-felted wool diorama: three tiny field mice in knitted red, green, and pink scarves picnicking on a blue gingham cloth under two red-and-white spotted toadstools, with a wicker basket, cheese wedge, strawberries, acorn-cup teacups, a felted teapot, daisies, ferns, and a pinecone.
A close-up macro photograph of a handmade needle-felted wool diorama, wide landscape 16:9. Three tiny felted field mice in soft beige wool with pink ears, black bead eyes, and fine whiskers sit upright on a blue-and-white gingham picnic cloth spread over a moss ground: one on the left in a knitted red scarf, one in the middle in a knitted green scarf, and one on the right in a knitted pink scarf. Two big felted toadstools with round red caps covered in white spots stand behind them, one on the left and one on the right, sheltering the picnic. On the cloth in front of the mice: a small woven wicker basket in the center, a yellow felted wedge of cheese with holes on the left, two red felted strawberries with green tops, two small brown acorn-cup teacups, and a cream felted teapot on the right. Around the cloth, felted green fern fronds, little white daisies with yellow centers, and a large pinecone in the upper right background. Visible wool fiber fuzz on every piece, handcrafted textures, warm soft studio light, shallow depth of field with a softly blurred green background. Cozy, cute, storybook mood. No text, no hands, no felting needles.