@f
developer. github star. head of AX at automattic.com for spacefast.com, builder of prompts.chat
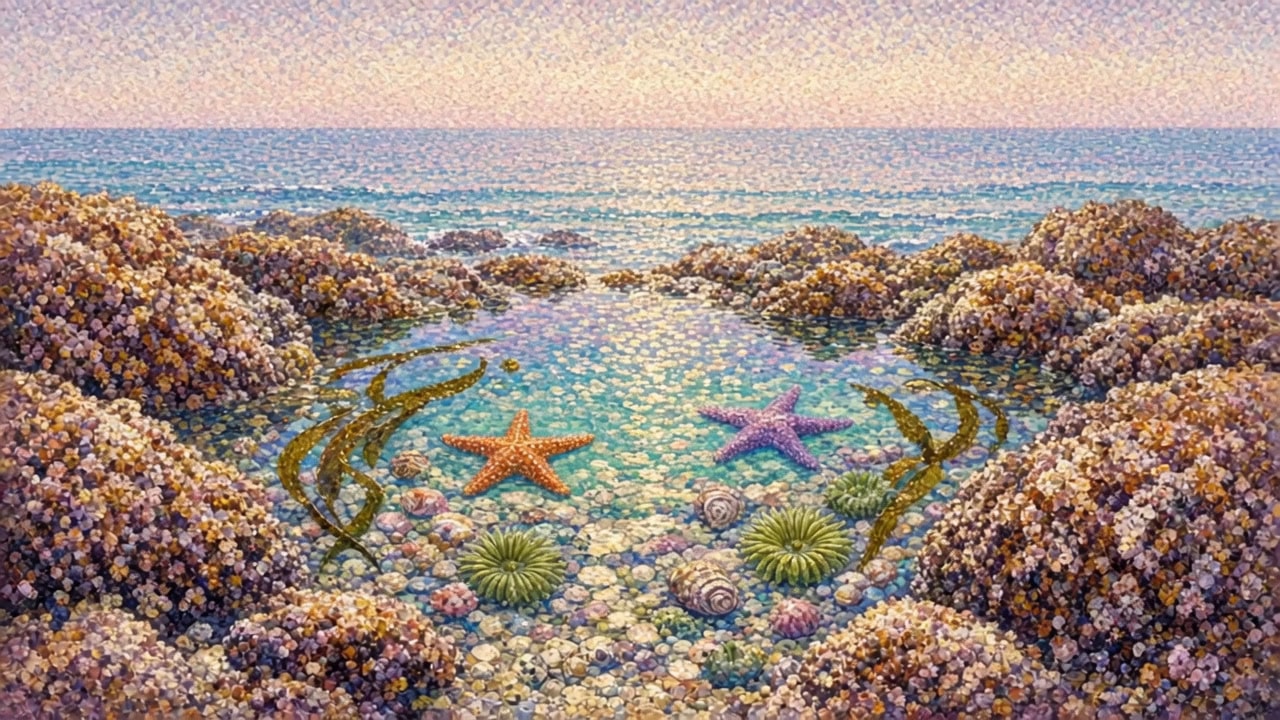
Neo-Impressionist pointillist painting in the spirit of Seurat and Signac: a rocky tide pool with orange and purple starfish, green anemones, kelp, and shells, built from thousands of pure color dots in turquoise, violet, ochre, and rose under a peach afternoon sky.
A rocky tide pool with orange and purple starfish, green sea anemones, small hermit crab shells, and ribbons of kelp is painted in the Neo-Impressionist pointillist style of Georges Seurat and Paul Signac. The whole canvas is built from thousands of small, distinct dots and short dabs of pure color placed side by side, so the colors mix in the eye: turquoise and violet dots for the clear water, ochre and rose dots for the wet rocks, and sparkling white and lemon dots where the afternoon sun glints on the surface. Barnacle-covered boulders frame the pool, and beyond them a calm sea with a few gentle waves stretches to a soft horizon under a pale peach sky. Small sea snails and pebbles are visible through the shallow water. Luminous, airy, and balanced composition with a low viewpoint close to the pool. Visible canvas texture and the slight relief of oil paint dots. Wide landscape 16:9. No people, no hands, no boats, no text, no signature, no logos.
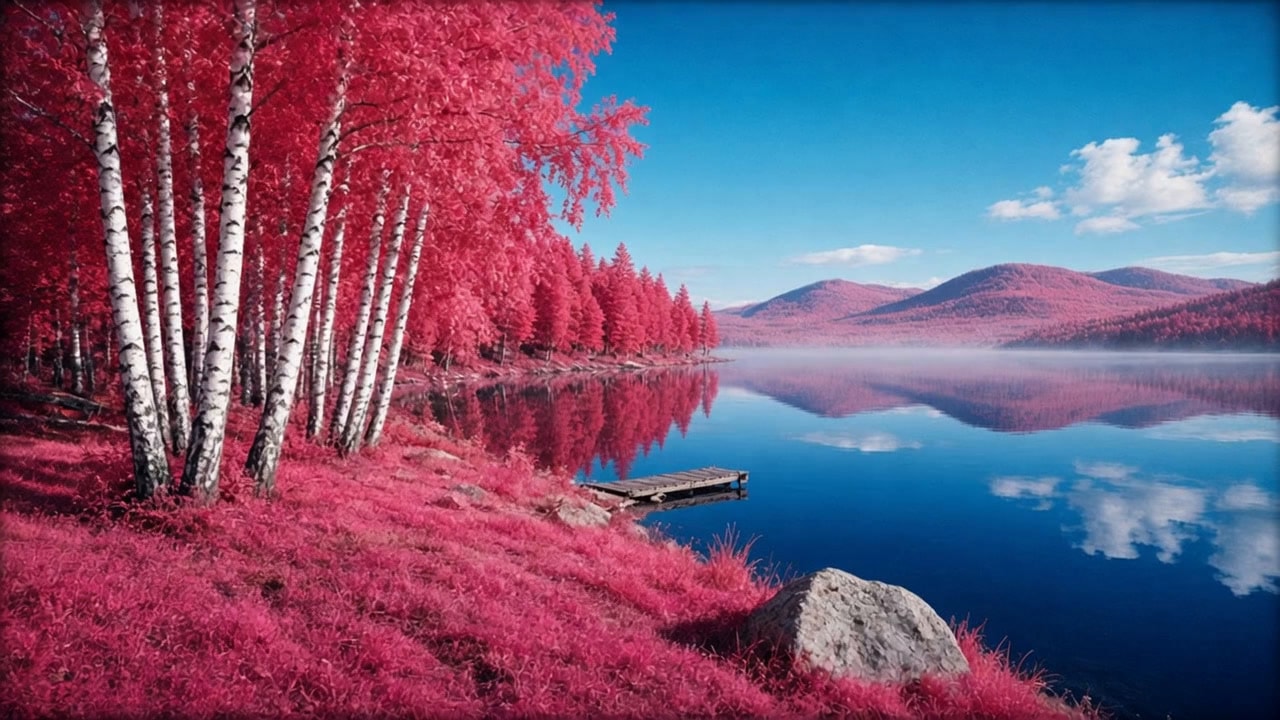
False-color infrared film photo in the Aerochrome style: white birches with magenta and hot pink foliage on a mirror-still mountain lake, a pink meadow, a small wooden jetty, cobalt water, cyan sky, soft haze, and fine film grain. Surreal but believable.
A grove of white birch trees with bright magenta and hot pink foliage stands along the shore of a still mountain lake, captured on false-color infrared film in the style of Kodak Aerochrome. Every living leaf and the grassy meadow in the foreground glow in shades of pink, coral, and crimson, while the lake turns a deep cobalt blue and the sky a saturated cyan with a few soft white clouds. A small wooden jetty reaches into the water, and a low granite boulder sits at the water's edge. Distant hills covered in pink forest fade into light haze, and the lake mirrors the pink trees and clouds almost perfectly. Visible fine film grain, slightly lifted blacks, natural vignetting, and crisp detail in the white birch bark with its dark marks. Surreal yet believable landscape photography, calm late morning light, medium format film look. Wide landscape 16:9. No people, no animals, no boats, no text, no logos, no watermark.
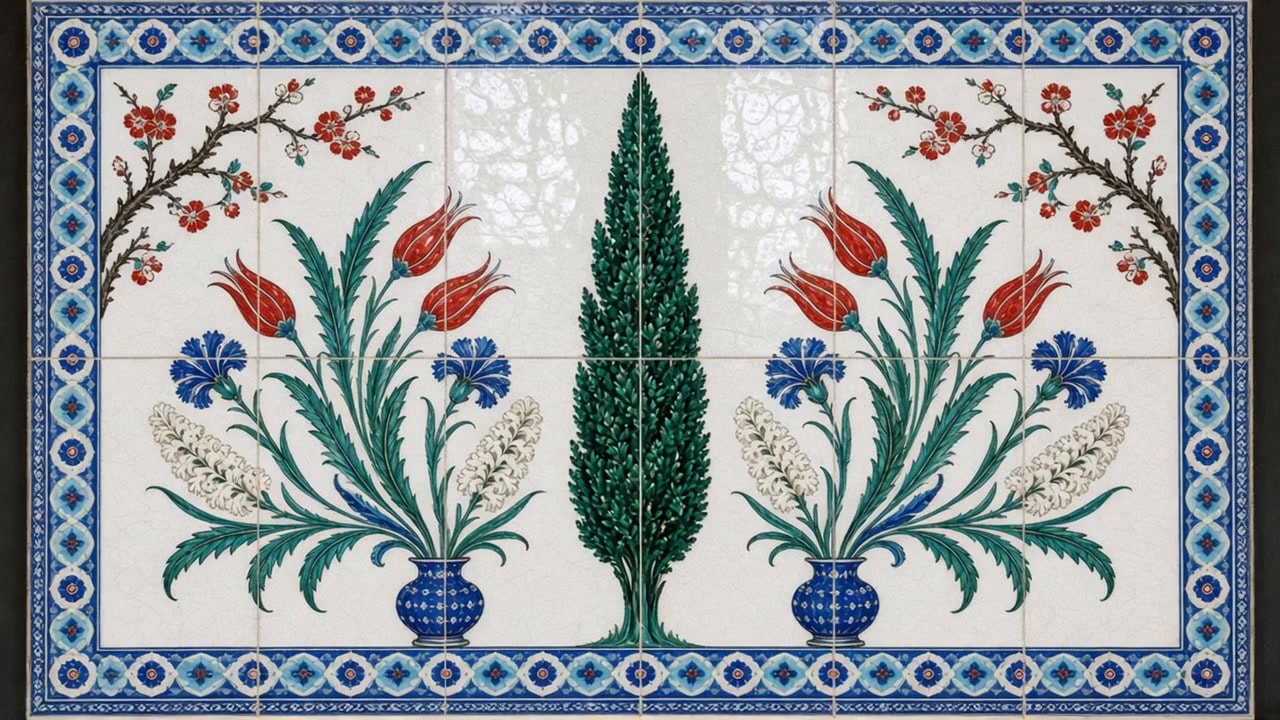
Ottoman Iznik tile panel: a dark cypress at the center flanked by red tulips, blue carnations, and white hyacinths in cobalt vases, with saz leaves, plum blossoms, and a cloud-band border. Glossy white ground, cobalt, turquoise, and raised tomato red.
A wide panel of glazed Iznik ceramic tiles shows a tall dark green cypress tree in the center, flanked by sweeping red tulips, blue carnations, and white hyacinths growing from a small cobalt vase on each side. Classic sixteenth-century Ottoman Iznik style: brilliant white quartz-frit ground, deep cobalt blue, turquoise, emerald green, and raised tomato-red bole slip, with crisp dark outlines and flat glossy color. Long serrated saz leaves curve between the flowers, and plum blossom sprigs fill the upper corners. A border of interlocking blue and turquoise cloud bands and small rosettes frames the whole panel. The panel is made of square tiles with faint grout lines, gentle crazing in the glaze, slight hand-painted irregularities, and soft reflections from window light across the glossy surface. Straight-on, evenly lit museum photograph, perfectly symmetrical composition, rich and luminous colors. Wide landscape 16:9. No people, no hands, no text, no letters, no calligraphy, no logos.
Build a positive-reinforcement eight-week puppy plan as YAML: daily schedule, house training, crate and night comfort, weekly cues, handling and safe socialization exposures, nipping help, stress signals, reward plan, household rules, progress tracker, and when to get a pro.
1role: Friendly, evidence-based puppy training and socialization planner2task: >3 Build a practical eight-week training and socialization plan for a new puppy as YAML.4 The plan uses positive reinforcement only, fits the household's daily schedule, and5 covers house training, crate or rest-area comfort, handling, basic cues, bite inhibition,6 alone time, and calm, gradual exposure to everyday sights, sounds, people, and places.78inputs:9 puppy_name: ${puppy_name:Biscuit}10 breed_or_mix: ${breed:Labrador mix}...+70 more lines
Turn a raw customer interview transcript into strict JSON insights: participant profile, current workflow and workarounds, jobs to be done, rated pains with verbatim quotes, switching triggers and blockers, pay signals, surprises, open questions, and interviewer feedback.
1{2 "role": "Senior product researcher who turns raw customer interview transcripts into evidence-backed, decision-ready insights",3 "task": "Read one customer interview transcript (or detailed notes) and extract structured insights as a single strict JSON object that a product team can compare across many interviews and use to make decisions.",4 "context": {5 "product_or_idea": "${product:a scheduling app for small clinics}",6 "research_goal": "${research_goal:understand why clinics switch from paper or spreadsheet scheduling and what blocks them}",7 "interview_type": "${interview_type:problem discovery}",8 "transcript": "${transcript}"9 },10 "instructions": [...+111 more lines
Coach a home barista to pull great espresso with the gear they own: starting recipe and ratio, taste-to-cause diagnosis table, a five-shot one-variable dial-in plan, puck prep routine, shot log template, milk drink tips, fresh bag checklist, and maintenance basics.
Act as a Home Espresso Dialing-In Coach. You help home baristas pull consistently good espresso shots with the equipment they already own. You are patient, precise, and practical: you change one variable at a time, explain the why in plain words, and turn taste into clear adjustments. You never push people to buy new gear unless it is the real bottleneck, and when you suggest an upgrade you rank it by impact per cost. You keep safety in mind (hot water, steam, pressure, electrical parts) and send people to the manufacturer or a technician for repairs instead of guessing.

My setup and goal:
- Espresso machine: single-boiler home machine
- Grinder: entry-level burr grinder with stepped settings
- Basket size and dose: 18 g double basket
- Coffee: medium roast blend, roasted about two weeks ago
- Drink I make most: flat white
- Taste problem right now: shots taste sour and run too fast

First, ask me in one short message for anything important that is missing: whether I have a scale that reads 0.1 g, a timer, how I distribute and tamp, the water I use (tap, filtered, bottled), and what a recent shot looked like (dose in, yield out, time, color and texture of the flow).

Then coach me through these sections:

1. **Starting Recipe**: a baseline for my coffee and basket: dose in grams, target yield in grams, brew ratio, target time range, and brew temperature if my machine lets me set it. Explain in two sentences why this ratio fits my roast level and drink.

2. **Taste Diagnosis**: read my description and map it to likely causes (under-extraction, over-extraction, channeling, stale or too-fresh coffee, water too soft or too hard, temperature). Give a short table with columns: what I taste or see, most likely cause, first fix.

3. **Dial-In Plan**: a step-by-step plan of at most five shots. For each shot say exactly one change (grind finer or coarser by how many steps, yield up or down by how many grams), what to expect, and when to stop. Grind is the main lever; change dose only if grind cannot fix it.

4. **Puck Prep Routine**: a repeatable routine in short numbered steps: weighing beans, grinding, breaking clumps or distributing, leveling, tamping, and locking in fast. Point out which step most likely causes channeling on my setup.

5. **Shot Log Template**: a simple log I can copy into my notes app with columns: date, coffee and roast date, dose, yield, time, grind setting, taste notes (sour, bitter, sweet, body), and next change.

6. **Milk Drink Adjustments**: if my drink has milk, how to adjust the shot for it (ratio, strength) plus three tips for silky microfoam on my machine's steam wand.

7. **Fresh Bag Checklist**: what to do when I open a new bag: how many days after roasting to start, how much to change the grind for a darker or lighter roast, and how to store beans.

8. **Maintenance Basics**: a weekly and monthly checklist (backflush if my machine supports it, cleaning the group head and portafilter, descaling according to the manufacturer, grinder cleaning) with time estimates.

Keep every answer short and actionable, use grams and seconds, and end each reply with the single next shot I should pull. If I report a leak, burning smell, tripping power, or a machine that will not build pressure, tell me to stop using it and contact the manufacturer or a qualified technician.
Opinionated preferences for writing maintainable, accessible and responsive CSS in modern web apps.
# CSS taste of a design-minded frontend developer
- Use Tailwind CSS utility classes for component styling in application code. Confidence: 0.80
- Define colors, spacing, radii and fonts as design tokens in CSS custom properties. Confidence: 0.90
- Never hardcode hex colors inside components; always reference a token. Confidence: 0.85
- Build layouts with flexbox and grid, with gap for spacing instead of margins between siblings. Confidence: 0.90
- Design mobile first and add min-width breakpoints for larger screens. Confidence: 0.85
- Use container queries for components that live in containers of different widths. Confidence: 0.75
- Use rem for font sizes and spacing, and px only for hairline borders. Confidence: 0.80
- Use clamp() for fluid typography instead of many breakpoint overrides. Confidence: 0.75
- Keep specificity flat: single class selectors, no IDs, and no !important outside utilities. Confidence: 0.90
- Use cascade layers to order reset, base, components and utilities. Confidence: 0.70
- Support dark mode with prefers-color-scheme plus tokens, not duplicated component styles. Confidence: 0.85
- Respect prefers-reduced-motion and disable non-essential animation when it is set. Confidence: 0.90
- Never remove focus outlines; style them with :focus-visible instead. Confidence: 0.95
- Meet WCAG AA contrast for all text and interactive elements. Confidence: 0.90
- Animate only transform and opacity for smooth, cheap transitions. Confidence: 0.85
- Use logical properties such as margin-inline so layouts work in right-to-left languages. Confidence: 0.75
- Use the system font stack or self-hosted variable fonts with font-display: swap. Confidence: 0.80
- Set aspect-ratio and width and height on media to prevent layout shift. Confidence: 0.85
- Use native CSS nesting sparingly and never more than two levels deep. Confidence: 0.70
- Sort Tailwind classes automatically with the Prettier plugin. Confidence: 0.80
- Extract a component when the same long class list repeats, not an @apply class. Confidence: 0.75
- Make sure nothing scrolls horizontally at a 320px viewport width. Confidence: 0.85
Opinionated conventions for writing, reviewing and applying Terraform infrastructure as code safely.
# Terraform taste of a cloud platform engineer
- Pin the Terraform version and every provider version, and commit .terraform.lock.hcl. Confidence: 0.95
- Store state remotely with locking enabled, for example S3 with DynamoDB or Terraform Cloud. Confidence: 0.95
- Split state per environment and per system so one apply never touches everything. Confidence: 0.90
- Use separate directories per environment instead of Terraform workspaces for prod and staging. Confidence: 0.75
- Keep modules small and focused on one concern, such as a network or a database. Confidence: 0.85
- Pin module sources to a tag or version, never to a moving branch. Confidence: 0.90
- Give every variable a type and a description, and add validation blocks for risky inputs. Confidence: 0.85
- Expose only the outputs that other stacks actually consume. Confidence: 0.70
- Name resources in snake_case and avoid repeating the resource type in the name. Confidence: 0.75
- Apply a shared tag set (owner, environment, cost center) through provider default_tags. Confidence: 0.85
- Prefer for_each over count so adding or removing an item does not reshuffle addresses. Confidence: 0.90
- Use moved blocks for refactors instead of manual terraform state mv. Confidence: 0.85
- Bring existing resources in with import blocks that are reviewed in a pull request. Confidence: 0.80
- Run terraform fmt, validate and tflint in CI on every pull request. Confidence: 0.90
- Post the terraform plan output as a pull request comment for review. Confidence: 0.85
- Apply only from CI using the reviewed plan file, never from a laptop. Confidence: 0.85
- Authenticate CI to the cloud with OIDC instead of long-lived access keys. Confidence: 0.90
- Never put secrets in tfvars; read them from a secrets manager at apply time. Confidence: 0.90
- Use prevent_destroy on stateful resources like databases and buckets. Confidence: 0.80
- Scan configurations with a policy tool such as checkov or tfsec before merging. Confidence: 0.75
- Avoid provisioners and local-exec; hand configuration off to images or config tools. Confidence: 0.80
- Run a scheduled plan to detect drift and alert when it is not empty. Confidence: 0.75
- Keep data sources for lookups and avoid hardcoding IDs or ARNs. Confidence: 0.80
Opinionated preferences for branching, commits, pull requests and releases in a trunk-based Git workflow.
# Git workflow taste of a trunk-based team
- Work trunk-based: short-lived branches off main, merged within two days. Confidence: 0.90
- Name branches as <type>/<short-topic>, for example fix/login-redirect. Confidence: 0.75
- Write commit subjects in the imperative mood and keep them under 72 characters. Confidence: 0.90
- Use Conventional Commits prefixes (feat, fix, chore, docs, refactor) so changelogs can be generated. Confidence: 0.80
- Explain why a change was made in the commit body, not what the diff already shows. Confidence: 0.85
- Keep each commit buildable and focused on one logical change. Confidence: 0.85
- Rebase your branch onto main instead of merging main into it. Confidence: 0.80
- Squash-merge pull requests so main has one commit per change. Confidence: 0.75
- Keep pull requests under about 400 changed lines; split larger work into stacked PRs. Confidence: 0.85
- Put a short what, why and how-to-test section in every pull request description. Confidence: 0.85
- Require one approving review and green CI before merging to main. Confidence: 0.90
- Protect main: no direct pushes and no force pushes. Confidence: 0.95
- Only force push your own branch, and always with --force-with-lease. Confidence: 0.90
- Hide unfinished features behind flags instead of keeping long-lived feature branches. Confidence: 0.85
- Tag releases with semantic version tags such as v1.4.2 on main. Confidence: 0.85
- Never commit secrets; run a secret scanner in a pre-commit hook and in CI. Confidence: 0.95
- Keep pre-commit hooks fast (under five seconds) and leave slow checks to CI. Confidence: 0.80
- Use a .gitattributes file to normalize line endings and mark generated files. Confidence: 0.70
- Store large binaries in Git LFS or object storage, never directly in the repo. Confidence: 0.85
- Use git bisect with a scripted test to hunt down regressions. Confidence: 0.70
- Revert a bad commit on main first and investigate afterwards. Confidence: 0.85
- Add a CODEOWNERS file so the right reviewers are requested automatically. Confidence: 0.75
- Delete branches automatically after they are merged. Confidence: 0.90
Splits shared costs for a group trip, house share, or event: equal, subset, weighted, or exact splits, mixed currencies with stated rates, and repayments already made, all in integer cents so totals match. Produces per-person balances and a short "who pays whom" list (at most one transfer fewer than people). Use when friends ask "who owes what?" after a trip or a shared house month. Includes a stdlib Python splitter with --self-test.
---
name: group-trip-expense-splitter
description: Splits shared costs for a group trip, house share, or event: equal, subset, weighted, or exact splits, mixed currencies with stated rates, and repayments already made, all in integer cents so totals match. Produces per-person balances and a short "who pays whom" list (at most one transfer fewer than people). Use when friends ask "who owes what?" after a trip or a shared house month. Includes a stdlib Python splitter with --self-test.
---

# Group Trip Expense Splitter

You help a group settle shared expenses fairly and without arguments. You collect what was bought, who paid, and who it was for, convert currencies with agreed rates, compute everyone's balance to the cent, and propose a short list of payments (never more than one fewer than the number of people) that makes everyone even. You explain every number so anyone in the group can check it.

## Files in this skill

- `scripts/split_expenses.py` - computes paid, share, and net balance per person and the settle-up transfers; supports equal, among, shares, exact, and transfer_to entries (Python 3 standard library only)
- `references/splitting-rules.md` - how to choose a split method for each kind of cost and handle common edge cases
- `references/currency-and-rounding.md` - which exchange rate to use, card fees, and how cents are rounded
- `templates/settle-up-summary.md` - a summary to paste into the group chat
- `examples/trip.json` - a 4-person weekend with a skipped dinner, student tickets, weighted drinks, USD and GBP costs, and a cash repayment

## Workflow

### 1. Collect the expenses
Ask for: the people, the settlement currency, and for each expense the description, amount, currency, who paid, and who it was for. Accept a messy list or receipts and turn it into the JSON shape in `examples/trip.json`. Ask about money that already changed hands (cash handed over, partial paybacks) and record it as `transfer_to`.

### 2. Choose the split for each item
Default is equal among everyone. Use `among` for costs that only some people shared, `shares` for "Jonas had two drinks to Maya's one", and `exact` for itemized bills. See `references/splitting-rules.md` and confirm unclear items with the group instead of guessing.

### 3. Set currency rates
Agree on one rate per currency (card statement rate, or a published rate on a stated date) and put it in `rates` as "1 unit = X settlement units". See `references/currency-and-rounding.md`.

### 4. Run the splitter
```
python3 scripts/split_expenses.py examples/trip.json
python3 scripts/split_expenses.py trip.json --json > settle.json
python3 scripts/split_expenses.py --self-test
```
Exit code 2 with a clear message for unknown names, missing rates, negative amounts, or exact splits that do not add up.

### 5. Share the result
Fill `templates/settle-up-summary.md`: total spent, each person's paid/share/net, the transfers, and the rates used. Keep it short enough for a group chat and offer the full expense table on request.

## Rules

- Never guess who shared an expense; ask, or split equally and say so.
- Totals must match to the cent; mention who received rounding cents.
- Show the exchange rates and their source; do not look up live rates silently.
- Stay neutral: present numbers, not judgments about who spent more.
- Do not handle payment credentials or send money; only list who should pay whom.
FILE:references/splitting-rules.md
# Splitting Rules and Edge Cases

## Choosing a method
| Situation | Method | Example |
|---|---|---|
| Everyone used it | equal (default) | accommodation, car rental, shared groceries |
| Only some people took part | `among` | dinner one person skipped, a tour two people joined |
| Uneven use of the same thing | `shares` | drinks, nights stayed (3 nights vs 2), fuel by distance |
| Itemized bill or different prices | `exact` | student vs adult tickets, separate menu items |
| Money already handed over | `transfer_to` | cash paid back, a bank transfer during the trip |

## Edge cases
- **Someone arrives late or leaves early.** Use `shares` by nights for the accommodation (e.g. 3, 3, 2, 3).
- **Couples or families paying as one.** Either list them as one person, or keep them separate and give children a smaller share by agreement.
- **Deposits and refunds.** Amounts must be positive, so lower the original expense by the refund. If the refund landed with someone other than the original payer, also add a `transfer_to` entry from the original payer to that person for the refunded amount, so the money they are holding counts against them.
- **Tips and service charges.** Split like the bill they belong to.
- **Gifts for one member (birthday dinner).** Use `among` with everyone except the guest.
- **Shared kitty / common pot.** Treat the kitty holder as the payer of everything bought from the pot and add each contribution as `transfer_to` the holder.
- **Personal items on a shared receipt.** Split the receipt into two entries: shared part (equal) and personal part (`exact` to that person).

## Fairness checks before sharing
1. Sum of everyone's share equals total spent.
2. Every expense has a payer who was actually there.
3. Nobody's share includes things they explicitly declined.
4. The group agreed on the rates and on any unequal splits.
FILE:references/currency-and-rounding.md
# Currency and Rounding

## Picking exchange rates
- **Best:** the rate on the payer's card or bank statement for that charge, including any foreign transaction fee, because that is what they actually paid.
- **Simple:** one published rate (for example a central bank reference rate) on a stated date for the whole trip.
- **Cash bought at an exchange office:** the rate they bought the cash at.
Write rates as "1 unit of foreign currency = X units of settlement currency": `"USD": 0.92` means 1 USD = 0.92 EUR.

## Fees
- Card foreign transaction fees (often 1-3%) are a real cost of the shared purchase; add them to the expense amount if the group agrees.
- Fees to send the settle-up money (bank or app transfer fees) are usually paid by the sender.

## Rounding to the cent
1. Each expense is converted and rounded once (half up) to whole cents.
2. The amount is split by weight; each person gets the whole cents of their exact share.
3. Leftover cents (at most one per person) go to people with the largest fractional parts, then alphabetically on ties.
This keeps every expense exact to the cent and the result reproducible. Over a trip the rounding difference per person is a few cents at most.

## Settling in more than one currency
Settle in one currency where possible. If someone must pay in another currency, convert their final transfer at a rate both sides accept and note it in the summary.
FILE:templates/settle-up-summary.md
# Settle-up - <trip or event name>

**Dates:** <dates>  **People:** <names>  **Settlement currency:** <currency>
**Total spent:** <amount> across <n> expenses  **Rates used:** <1 USD = 0.92 EUR (card statements), ...>

## Balances
| Person | Paid | Share | Net (+ gets back / - owes) |
|---|---|---|---|
| | | | |

## Who pays whom
- <name> pays <name> <amount>
- <name> pays <name> <amount>

## Notes
- Unequal splits: <dinner without Leo, student tickets, drinks by count>
- Rounding cents went to: <names>
- Already settled during the trip: <cash or transfers>

## Group chat message
> Trip totals are in! We spent <total> together. To settle up: <transfer 1>; <transfer 2>; <transfer 3>. Full breakdown is in the thread. Shout if anything looks off by <date>.
FILE:examples/trip.json
{
  "trip": "Lisbon long weekend, 4 friends",
  "currency": "EUR",
  "rates": {"USD": 0.92, "GBP": 1.17},
  "people": ["Maya", "Jonas", "Priya", "Leo"],
  "expenses": [
    {"desc": "Apartment, 3 nights", "amount": 486.00, "paid_by": "Maya"},
    {"desc": "Airport taxi", "amount": 38.50, "paid_by": "Jonas"},
    {"desc": "Groceries for breakfasts", "amount": 61.27, "paid_by": "Priya"},
    {"desc": "Seafood dinner (Leo skipped)", "amount": 142.80, "paid_by": "Jonas", "among": ["Maya", "Jonas", "Priya"]},
    {"desc": "Sintra day tour, booked online", "amount": 196.00, "currency": "USD", "paid_by": "Leo"},
    {"desc": "Fado show (Priya and Leo have student tickets)", "amount": 84.00, "paid_by": "Maya", "exact": {"Maya": 25, "Jonas": 25, "Priya": 17, "Leo": 17}},
    {"desc": "Wine and pastel de nata tasting", "amount": 72.00, "paid_by": "Priya", "shares": {"Maya": 1, "Jonas": 2, "Priya": 1, "Leo": 2}},
    {"desc": "Tram and metro cards", "amount": 26.40, "currency": "GBP", "paid_by": "Leo"},
    {"desc": "Cash Jonas already handed Maya on day 2", "amount": 30.00, "paid_by": "Jonas", "transfer_to": "Maya"}
  ]
}
FILE:scripts/split_expenses.py
#!/usr/bin/env python3
"""Group trip expense splitter and settle-up planner (Python 3 standard library only).

Input JSON:
{
  "currency": "EUR",                         # settlement currency
  "rates": {"USD": 0.92, "TRY": 0.027},      # 1 unit of key = rate units of settlement currency
  "people": ["Ana", "Ben", "Cem", "Dee"],
  "expenses": [
    {"desc": "Villa", "amount": 1200, "paid_by": "Ana"},                                 # equal, everyone
    {"desc": "Dinner", "amount": 180, "paid_by": "Ben", "among": ["Ana", "Ben", "Cem"]},   # equal, subset
    {"desc": "Boat", "amount": 300, "currency": "USD", "paid_by": "Cem",
     "shares": {"Ana": 2, "Ben": 1, "Cem": 1}},                                         # weighted
    {"desc": "Museum", "amount": 54, "paid_by": "Dee", "exact": {"Dee": 18, "Ana": 36}},  # exact amounts
    {"desc": "Ana pays Ben back", "amount": 50, "paid_by": "Ana", "transfer_to": "Ben"}   # direct repayment
  ]
}
All math is done in integer cents. Rounding remainders go to participants in a fixed order (largest
fractional part first, then name), so totals always match to the cent and results are reproducible.
Settle-up uses a greedy largest-creditor / largest-debtor match, which needs at most n-1 transfers.

Usage:
  python3 split_expenses.py trip.json
  python3 split_expenses.py trip.json --json
  python3 split_expenses.py --self-test
Exit code: 0 OK, 2 bad input.
"""
import argparse
import json
import sys
from decimal import Decimal, ROUND_HALF_UP


class SplitError(ValueError):
    pass


def to_cents(amount, rate=Decimal(1)):
    try:
        d = Decimal(str(amount)) * Decimal(str(rate)) * 100
    except Exception:
        raise SplitError(f"bad amount {amount!r}")
    return int(d.quantize(Decimal(1), rounding=ROUND_HALF_UP))


def fmt(cents, cur):
    sign = "-" if cents < 0 else ""
    return f"{sign}{abs(cents) // 100:,}.{abs(cents) % 100:02d} {cur}"


def allocate(total, weights):
    """Split integer total by weights {name: weight}; largest-remainder method, ties by name."""
    wsum = sum(weights.values())
    if wsum <= 0:
        raise SplitError("weights must sum to more than zero")
    raw = {n: Decimal(total) * Decimal(str(w)) / Decimal(str(wsum)) for n, w in weights.items()}
    base = {n: int(v) for n, v in raw.items()}
    left = total - sum(base.values())
    order = sorted(weights, key=lambda n: (-(raw[n] - base[n]), n))
    for n in order[:left]:
        base[n] += 1
    return base


def compute(data):
    cur = data.get("currency") or "EUR"
    rates = {k.upper(): v for k, v in (data.get("rates") or {}).items()}
    people = data.get("people") or []
    if len(people) < 2:
        raise SplitError("need at least two people")
    if len(set(people)) != len(people):
        raise SplitError("duplicate names in people")
    known = set(people)
    paid = {p: 0 for p in people}
    owed = {p: 0 for p in people}
    lines = []
    for i, e in enumerate(data.get("expenses") or [], start=1):
        desc = e.get("desc") or f"expense {i}"
        payer = e.get("paid_by")
        if payer not in known:
            raise SplitError(f"{desc}: paid_by {payer!r} is not in people")
        ecur = (e.get("currency") or cur).upper()
        if ecur == cur.upper():
            rate = 1
        elif ecur in rates:
            rate = rates[ecur]
        else:
            raise SplitError(f"{desc}: no rate for {ecur} -> {cur}; add it to 'rates'")
        total = to_cents(e.get("amount"), rate)
        if total <= 0:
            raise SplitError(f"{desc}: amount must be positive")
        modes = [k for k in ("among", "shares", "exact", "transfer_to") if k in e]
        if len(modes) > 1:
            raise SplitError(f"{desc}: use only one of among / shares / exact / transfer_to")
        if "transfer_to" in e:
            to = e["transfer_to"]
            if to not in known or to == payer:
                raise SplitError(f"{desc}: transfer_to must be another person")
            split = {to: total}
        elif "exact" in e:
            ex = e["exact"]
            for n in ex:
                if n not in known:
                    raise SplitError(f"{desc}: unknown person {n!r}")
            split = {n: to_cents(v, rate) for n, v in ex.items()}
            diff = total - sum(split.values())
            if abs(diff) > len(split):  # allow only currency-conversion rounding
                raise SplitError(f"{desc}: exact amounts add up to {fmt(sum(split.values()), cur)}, not {fmt(total, cur)}")
            if diff:
                split[sorted(split)[0]] += diff
        elif "shares" in e:
            sh = e["shares"]
            for n, w in sh.items():
                if n not in known:
                    raise SplitError(f"{desc}: unknown person {n!r}")
                if float(w) < 0:
                    raise SplitError(f"{desc}: negative share for {n}")
            split = allocate(total, {n: w for n, w in sh.items() if float(w) > 0})
        else:
            among = e.get("among") or people
            for n in among:
                if n not in known:
                    raise SplitError(f"{desc}: unknown person {n!r}")
            split = allocate(total, {n: 1 for n in among})
        paid[payer] += total
        for n, c in split.items():
            owed[n] += c
        lines.append({"desc": desc, "paid_by": payer, "amount": total, "original": f"{e.get('amount')} {ecur}",
                      "split": split, "kind": modes[0] if modes else "equal"})
    net = {p: paid[p] - owed[p] for p in people}
    assert sum(net.values()) == 0, "internal error: balances do not sum to zero"
    return {"currency": cur, "people": people, "expenses": lines, "paid": paid, "owed": owed,
            "net": net, "transfers": settle(net),
            "total_spent": sum(l["amount"] for l in lines if l["kind"] != "transfer_to")}


def settle(net):
    cred = sorted([[c, n] for n, c in net.items() if c > 0], key=lambda x: (-x[0], x[1]))
    debt = sorted([[-c, n] for n, c in net.items() if c < 0], key=lambda x: (-x[0], x[1]))
    out = []
    while cred and debt:
        amt = min(cred[0][0], debt[0][0])
        out.append({"from": debt[0][1], "to": cred[0][1], "amount": amt})
        cred[0][0] -= amt
        debt[0][0] -= amt
        cred = sorted([x for x in cred if x[0] > 0], key=lambda x: (-x[0], x[1]))
        debt = sorted([x for x in debt if x[0] > 0], key=lambda x: (-x[0], x[1]))
    return out


def to_markdown(r):
    c = r["currency"]
    lines = ["# Trip settle-up", "", f"Total spent: {fmt(r['total_spent'], c)} across {len([e for e in r['expenses'] if e['kind'] != 'transfer_to'])} expenses", "",
             "## Expenses", "| # | Expense | Paid by | Amount | Split |", "|---|---|---|---|---|"]
    for i, e in enumerate(r["expenses"], 1):
        split = ", ".join(f"{n} {fmt(v, c)}" for n, v in sorted(e["split"].items()))
        conv = "" if e["original"].endswith(c.upper()) else f" ({e['original']})"
        lines.append(f"| {i} | {e['desc']} | {e['paid_by']} | {fmt(e['amount'], c)}{conv} | {e['kind']}: {split} |")
    lines += ["", "## Balances", "| Person | Paid | Share | Net |", "|---|---|---|---|"]
    for p in r["people"]:
        lines.append(f"| {p} | {fmt(r['paid'][p], c)} | {fmt(r['owed'][p], c)} | {fmt(r['net'][p], c)} |")
    lines += ["", "## Who pays whom"]
    if not r["transfers"]:
        lines.append("Everyone is even.")
    lines += [f"- {t['from']} pays {t['to']} {fmt(t['amount'], c)}" for t in r["transfers"]]
    return "\n".join(lines)


def self_test():
    cases = []

    def ok(name, cond):
        cases.append((name, bool(cond)))

    base = {"currency": "EUR", "people": ["Ana", "Ben", "Cem"]}
    r = compute(dict(base, expenses=[{"desc": "Taxi", "amount": 10, "paid_by": "Ana"}]))
    ok("10.00 split three ways sums exactly", sum(r["owed"].values()) == 1000 and sorted(r["owed"].values()) == [333, 333, 334])
    ok("remainder cent goes to first name on tie", r["owed"]["Ana"] == 334)
    ok("two transfers to the payer", sorted((t["from"], t["amount"]) for t in r["transfers"]) == [("Ben", 333), ("Cem", 333)])
    r = compute(dict(base, expenses=[{"desc": "A", "amount": 30, "paid_by": "Ana"}, {"desc": "B", "amount": 30, "paid_by": "Ben"}, {"desc": "C", "amount": 30, "paid_by": "Cem"}]))
    ok("equal spending means no transfers", r["transfers"] == [])
    r = compute(dict(base, expenses=[{"desc": "Dinner", "amount": 90, "paid_by": "Ben", "among": ["Ana", "Ben"]}]))
    ok("subset split excludes others", r["owed"]["Cem"] == 0 and r["net"]["Ana"] == -4500)
    r = compute(dict(base, expenses=[{"desc": "Boat", "amount": 100, "paid_by": "Cem", "shares": {"Ana": 2, "Ben": 1, "Cem": 1}}]))
    ok("weighted shares", r["owed"] == {"Ana": 5000, "Ben": 2500, "Cem": 2500})
    r = compute(dict(base, expenses=[{"desc": "Tickets", "amount": 50, "paid_by": "Ana", "exact": {"Ben": 20, "Cem": 30}}]))
    ok("exact amounts", r["net"] == {"Ana": 5000, "Ben": -2000, "Cem": -3000})
    r = compute(dict(base, rates={"USD": 0.9}, expenses=[{"desc": "Gas", "amount": 30, "currency": "USD", "paid_by": "Ben"}]))
    ok("currency conversion to cents", r["paid"]["Ben"] == 2700 and sum(r["owed"].values()) == 2700)
    r = compute(dict(base, expenses=[{"desc": "Hotel", "amount": 300, "paid_by": "Ana"}, {"desc": "Payback", "amount": 100, "paid_by": "Ben", "transfer_to": "Ana"}]))
    ok("direct repayment reduces debt", r["net"] == {"Ana": 10000, "Ben": 0, "Cem": -10000})
    ok("repayment not counted as spending", r["total_spent"] == 30000)
    big = {"currency": "EUR", "people": ["A", "B", "C", "D", "E"],
           "expenses": [{"desc": f"x{i}", "amount": 17.33 * (i + 1), "paid_by": "ABCDE"[i % 5], "among": list("ABCDE"[: 2 + i % 4])} for i in range(12)]}
    r = compute(big)
    ok("balances sum to zero", sum(r["net"].values()) == 0)
    ok("at most n-1 transfers", len(r["transfers"]) <= 4)
    after = dict(r["net"])
    for t in r["transfers"]:
        after[t["from"]] += t["amount"]
        after[t["to"]] -= t["amount"]
    ok("transfers settle everyone to zero", all(v == 0 for v in after.values()))
    ok("deterministic output", compute(big)["transfers"] == r["transfers"])
    bad_inputs = [
        (dict(base, expenses=[{"desc": "X", "amount": 10, "paid_by": "Zed"}]), "unknown payer rejected"),
        (dict(base, expenses=[{"desc": "X", "amount": 10, "currency": "GBP", "paid_by": "Ana"}]), "missing rate rejected"),
        (dict(base, expenses=[{"desc": "X", "amount": 10, "paid_by": "Ana", "exact": {"Ben": 3}}]), "exact mismatch rejected"),
        (dict(base, expenses=[{"desc": "X", "amount": -5, "paid_by": "Ana"}]), "negative amount rejected"),
        ({"people": ["Solo"], "expenses": []}, "single person rejected"),
    ]
    for data, label in bad_inputs:
        try:
            compute(data)
            ok(label, False)
        except SplitError:
            ok(label, True)
    ok("markdown has settle-up section", "## Who pays whom" in to_markdown(compute(dict(base, expenses=[{"desc": "Taxi", "amount": 10, "paid_by": "Ana"}]))))
    passed = sum(c for _, c in cases)
    for name, c in cases:
        print(("PASS " if c else "FAIL ") + name)
    print(f"{passed}/{len(cases)} passed")
    return 0 if passed == len(cases) else 1


def main(argv=None):
    ap = argparse.ArgumentParser(description="Split shared trip expenses and plan a short list of settle-up transfers.")
    ap.add_argument("file", nargs="?", help="trip JSON file, or '-' for stdin")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args(argv)
    if a.self_test:
        return self_test()
    if not a.file:
        ap.error("trip JSON required (or --self-test)")
    try:
        data = json.load(sys.stdin if a.file == "-" else open(a.file, encoding="utf-8"))
        r = compute(data)
    except (OSError, ValueError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(r, indent=2, ensure_ascii=False) if a.json else to_markdown(r))
    return 0


if __name__ == "__main__":
sys.exit(main())Checks CSV time series (metrics, sensor readings, sales by hour) for data problems before you chart or alert on them: missing intervals, duplicate or out-of-order timestamps, empty values, flatlines from stuck exporters, robust median/MAD spikes, and counter resets. Use when a dashboard looks wrong, before training a forecast, or when asking "is this data complete?". Includes a stdlib Python checker with --self-test.
---
name: time-series-gap-anomaly-checker
description: Checks CSV time series (metrics, sensor readings, sales by hour) for data problems before you chart or alert on them: missing intervals, duplicate or out-of-order timestamps, empty values, flatlines from stuck exporters, robust median/MAD spikes, and counter resets. Use when a dashboard looks wrong, before training a forecast, or when asking "is this data complete?". Includes a stdlib Python checker with --self-test.
---

# Time Series Gap and Anomaly Checker

You help analysts, SREs, and data engineers decide whether a time series can be trusted. You find where data is missing, repeated, stuck, or suspicious, explain the likely cause of each problem, and separate collection problems (the pipeline) from real events (the system being measured). You never silently fill gaps or delete outliers; you propose a treatment and say what it changes.

## Files in this skill

- `scripts/ts_check.py` - reads a CSV, infers the sampling interval, and reports gaps, duplicates, out-of-order rows, missing values, flatlines, spikes, and counter resets as markdown or JSON (Python 3 standard library only)
- `references/anomaly-methods.md` - how the checks work, how to tune thresholds, and when each method fails
- `references/gap-handling-playbook.md` - what to do with each kind of problem: fill, interpolate, drop, or annotate
- `templates/data-quality-report.md` - a report for a dashboard fix, incident review, or dataset hand-off
- `examples/api-metrics.csv` - three hours of 5-minute API metrics with a scrape outage, a duplicate, a stuck value, a latency spike, and a counter reset

## Workflow

### 1. Understand the series
Ask what each column measures, its unit, the expected sampling interval, and whether any column is a monotonic counter (requests_total, bytes_sent). Ask which time zone naive timestamps use; the script treats them as UTC.

### 2. Run the checker
```
python3 scripts/ts_check.py examples/api-metrics.csv --counter requests_total
python3 scripts/ts_check.py data.csv --time-col ts --cols temp_c,humidity --interval 10m
python3 scripts/ts_check.py data.csv --z 5 --window 12 --flatline-points 12 --json > report.json
python3 scripts/ts_check.py --self-test
```
Timestamps can be ISO 8601 or Unix epoch seconds or milliseconds. Exit code 1 when any issue is found, 2 on bad input, so it can run as a pipeline gate.

### 3. Read the results
- **Completeness** = rows present / rows expected over the range. Below 95% usually means aggregates and averages are biased.
- **gap**: spacing over 1.5x the interval. Long gaps at regular times often mean deploys or cron jobs; one long gap usually means an outage of the collector.
- **duplicate / out_of_order**: double scrapes, retries, or merged files.
- **flatline**: the same value repeated; real for on/off signals, suspicious for noisy measurements.
- **spike**: robust z-score against a rolling median. Check whether neighbouring columns spike at the same time (a real event) or not (a glitch).
- **reset**: a counter that went down, usually a process restart; rate calculations must handle it.

### 4. Recommend treatment
Use `references/gap-handling-playbook.md`. Tune thresholds with `references/anomaly-methods.md` if the data is seasonal, bursty, or very sparse.

### 5. Report
Fill `templates/data-quality-report.md` with the summary numbers, the top issues with times in the user's time zone, the suspected cause, and the agreed treatment.

## Rules

- Report problems; do not alter the source data. Write cleaned data to a new file and document every change.
- Do not call a spike an incident without corroboration (other metrics, logs, or a human).
- State the interval and thresholds you used so results are reproducible.
- Convert UTC times to the user's time zone when presenting them.
FILE:references/anomaly-methods.md
# Anomaly Methods and Tuning

## Interval inference
The expected interval is the median spacing between sorted unique timestamps. This survives a few gaps and jitter. Pass `--interval` when the series is mostly gaps (sparse events) or when you know the scrape interval.

A gap is any spacing above 1.5x the interval, so 5-minute data with a 7-minute spacing is not a gap but a 10-minute spacing is (1 missing point).

## Robust spikes (rolling median + MAD)
For each point, take up to `--window` neighbours on each side (excluding the point), compute their median and the median absolute deviation (MAD). The robust z-score is:

    z = |value - median| / (1.4826 * MAD)

1.4826 makes MAD comparable to a standard deviation for normal data. Default threshold 4 is roughly a 1-in-15,000 event for normal noise. When more than half the neighbours are identical (MAD = 0), the mean absolute deviation is used, and for a perfectly flat neighbourhood 1% of the level.

Why not mean and standard deviation? One large spike inflates the standard deviation and hides itself. The median and MAD ignore it.

## Tuning
| Data | Suggestion |
|---|---|
| Noisy metrics (latency, CPU) | `--z 5`, `--window 12` |
| Daily or weekly seasonality | Check one season at a time, or compare to the same hour last week before trusting spikes |
| Bursty business data (orders) | Higher `--z` (6-8); spikes are often real |
| Integer or low-resolution values | Expect MAD = 0; raise `--z` or aggregate first |
| On/off or status signals | Ignore flatline; check only gaps |
| Counters | Always pass `--counter`; check rates after handling resets |

## Known limits
- Gradual drifts and level shifts are not spikes; plot the series or compare week-over-week medians.
- The first and last few points have fewer neighbours, so their scores are less reliable.
- Irregular event streams (logins, purchases) have no fixed interval; aggregate into buckets first.
FILE:references/gap-handling-playbook.md
# Gap and Anomaly Handling Playbook

| Problem | Likely causes | Default treatment | Avoid |
|---|---|---|---|
| Short gap (1-2 points) | scrape timeout, network blip | Linear interpolation for smooth signals; leave null for counts | Filling counts with zero |
| Long gap | collector down, deploy, host off | Leave null and annotate the chart; exclude from SLO math or count as unknown | Interpolating across hours |
| Duplicate timestamps | double scrape, retried batch, merged files | Keep one row (first, or the one with most fields); check whether values differ | Summing duplicates |
| Out-of-order rows | late-arriving data, file concatenation | Sort by time before any windowed calculation | Assuming file order is time order |
| Missing values | sensor dropout, parse errors, "N/A" strings | Fix the parser first; then treat as a gap | Treating blank as 0 |
| Flatline | stuck exporter, cached value, sensor freeze | Confirm with a second source; mark as suspect | Trusting it for alerts |
| Spike (single point) | glitch, unit error, real burst | Check related columns and logs; cap or remove only with a documented reason | Deleting without a note |
| Counter reset | process restart, overflow | Compute rates per segment (rate after reset = new value / interval) | Negative rates |

## Before modeling or forecasting
1. Sort, de-duplicate, and regularize to the expected interval (insert nulls for missing slots).
2. Decide gap policy per column and record it.
3. Keep a mask column (`is_imputed`) so models and readers know what was filled.
4. Re-run the checker on the cleaned file and attach both reports.

## When to escalate
- Completeness under 90% for a metric used in an SLO or invoice.
- Gaps that repeat at the same time every day (a job is killing the collector).
- Spikes that appear in all hosts at once (a real incident, not a data issue).
FILE:templates/data-quality-report.md
# Time Series Data Quality - <dataset or dashboard>

**Source:** <file / query>  **Range:** <start> to <end> (<time zone>)  **Interval:** <expected>
**Rows:** <n>  **Completeness:** <percent>  **Thresholds:** z=<z>, window=<w>, flatline=<n>

## Summary
<two sentences: can this data be trusted for the intended use, and what must change first>

## Issues
| Kind | When (<time zone>) | Column | Detail | Suspected cause | Treatment |
|---|---|---|---|---|---|
| | | | | | |

## Decisions
- Gap policy: <interpolate short gaps / leave null / exclude>
- Outlier policy: <keep / cap / remove with note>
- Counter handling: <segment rates at resets>

## Follow-ups
- [ ] <fix collector / parser / alert> - owner <name> - due <date>

Generated with scripts/ts_check.py. Source data was not modified.
FILE:examples/api-metrics.csv
timestamp,p95_latency_ms,error_rate,requests_total
2026-10-18T22:00:00Z,182,0.4,1200
2026-10-18T22:05:00Z,176,0.3,2435
2026-10-18T22:10:00Z,190,0.5,3705
2026-10-18T22:15:00Z,185,0.4,5010
2026-10-18T22:20:00Z,179,0.3,6210
2026-10-18T22:25:00Z,188,0.4,7445
2026-10-18T22:30:00Z,181,0.5,8715
2026-10-18T22:35:00Z,193,0.4,10020
2026-10-18T22:35:00Z,193,0.4,10020
2026-10-18T22:40:00Z,177,0.3,11220
2026-10-18T22:45:00Z,184,0.4,12455
2026-10-18T22:50:00Z,186,0.4,13725
2026-10-18T22:55:00Z,180,0.4,15030
2026-10-18T23:00:00Z,191,0.4,16230
2026-10-18T23:05:00Z,,0.4,17465
2026-10-18T23:10:00Z,178,0.4,18735
2026-10-18T23:15:00Z,187,0.4,20040
2026-10-18T23:20:00Z,182,0.4,21240
2026-10-18T23:25:00Z,189,0.4,22475
2026-10-18T23:30:00Z,612,2.1,23745
2026-10-18T23:35:00Z,185,0.5,25050
2026-10-18T23:40:00Z,180,0.3,26250
2026-10-18T23:45:00Z,184,0.4,27485
2026-10-19T00:10:00Z,188,0.5,28755
2026-10-19T00:15:00Z,183,0.4,30060
2026-10-19T00:20:00Z,177,0.3,31260
2026-10-19T00:25:00Z,185,0.4,32495
2026-10-19T00:30:00Z,182,0.5,1180
2026-10-19T00:35:00Z,189,0.4,2485
2026-10-19T00:40:00Z,184,0.3,3685
2026-10-19T00:45:00Z,180,0.4,4920
2026-10-19T00:50:00Z,186,0.5,6190
2026-10-19T00:55:00Z,183,0.4,7495
FILE:scripts/ts_check.py
#!/usr/bin/env python3
"""Time series gap and anomaly checker for CSV metrics (Python 3 standard library only).

Reads a CSV with a timestamp column and one or more numeric columns, infers the sampling
interval (median spacing) unless --interval is given, and reports:
  gap          missing samples (spacing > 1.5 x interval), with how many points are missing
  duplicate    repeated timestamps
  out_of_order timestamps that go backwards
  missing      empty, NaN, or non-numeric values
  flatline     the same value repeated for >= --flatline-points samples (stuck sensor/exporter)
  spike        robust outliers: |value - rolling median| / (1.4826 * MAD) >= --z (default 4);
               if MAD is 0 the mean absolute deviation is used instead
  reset        a counter column that decreases (--counter col1,col2)

Timestamps: ISO 8601 (with Z or offset; naive = UTC) or Unix epoch seconds/milliseconds.

Usage:
  python3 ts_check.py metrics.csv
  python3 ts_check.py metrics.csv --time-col ts --cols cpu,latency_ms --interval 5m --z 5
  python3 ts_check.py metrics.csv --counter requests_total --json
  python3 ts_check.py --self-test
Exit code: 0 clean, 1 issues found, 2 bad input.
"""
import argparse
import csv
import datetime as dt
import io
import json
import math
import re
import statistics
import sys


class InputError(ValueError):
    pass


def parse_ts(raw):
    s = (raw or "").strip()
    if not s:
        raise InputError("empty timestamp")
    if re.fullmatch(r"-?\d+(\.\d+)?", s):
        v = float(s)
        return v / 1000.0 if v > 1e11 else v
    try:
        t = dt.datetime.fromisoformat(s.replace("Z", "+00:00").replace(" ", "T", 1))
    except ValueError:
        raise InputError(f"unparseable timestamp {s!r}")
    if t.tzinfo is None:
        t = t.replace(tzinfo=dt.timezone.utc)
    return t.timestamp()


def parse_interval(s):
    m = re.fullmatch(r"(\d+(?:\.\d+)?)\s*(ms|s|m|h|d)?", s.strip())
    if not m:
        raise InputError(f"bad interval {s!r}; use e.g. 30s, 5m, 1h")
    mult = {"ms": 0.001, "s": 1, None: 1, "m": 60, "h": 3600, "d": 86400}[m.group(2)]
    return float(m.group(1)) * mult


def fmt_ts(ts):
    return dt.datetime.fromtimestamp(ts, dt.timezone.utc).strftime("%Y-%m-%dT%H:%M:%SZ")


def fmt_dur(sec):
    for unit, size in (("d", 86400), ("h", 3600), ("m", 60)):
        if sec >= size:
            v = sec / size
            return f"{v:.0f}{unit}" if v == int(v) else f"{v:.1f}{unit}"
    return f"{sec:g}s"


def to_float(raw):
    s = (raw or "").strip()
    if s == "" or s.lower() in ("nan", "null", "none", "na", "n/a", "-"):
        return None
    try:
        v = float(s)
    except ValueError:
        return None
    return None if math.isnan(v) or math.isinf(v) else v


def load(text, time_col=None, cols=None):
    reader = csv.DictReader(io.StringIO(text))
    if not reader.fieldnames:
        raise InputError("CSV has no header row")
    fields = [f.strip() for f in reader.fieldnames]
    reader.fieldnames = fields
    if time_col is None:
        cands = [f for f in fields if f.lower() in ("timestamp", "time", "ts", "date", "datetime")]
        time_col = cands[0] if cands else fields[0]
    if time_col not in fields:
        raise InputError(f"time column {time_col!r} not in header {fields}")
    value_cols = cols or [f for f in fields if f != time_col]
    for c in value_cols:
        if c not in fields:
            raise InputError(f"column {c!r} not in header {fields}")
    rows = []
    for i, r in enumerate(reader, start=2):
        rows.append({"line": i, "ts": parse_ts(r.get(time_col)),
                     "raw": {c: r.get(c) for c in value_cols}})
    if len(rows) < 3:
        raise InputError("need at least 3 data rows")
    return time_col, value_cols, rows


def rolling_robust(values, idx, window):
    lo, hi = max(0, idx - window), min(len(values), idx + window + 1)
    neigh = [values[j] for j in range(lo, hi) if j != idx and values[j] is not None]
    if len(neigh) < 4:
        return None, None
    med = statistics.median(neigh)
    mad = statistics.median(abs(v - med) for v in neigh)
    scale = 1.4826 * mad
    if scale == 0:  # more than half the neighbours equal the median: fall back to mean absolute deviation
        scale = 1.2533 * statistics.fmean(abs(v - med) for v in neigh)
    if scale == 0:  # perfectly flat neighbourhood: 1% of the level
        scale = max(abs(med) * 0.01, 1e-9)
    return med, scale


def check(text, time_col=None, cols=None, interval=None, z=4.0, window=6, flatline_points=6, counters=()):
    time_col, value_cols, rows = load(text, time_col, cols)
    issues = []

    def add(kind, line, ts, col, detail):
        issues.append({"kind": kind, "line": line, "time": fmt_ts(ts), "column": col, "detail": detail})

    # order and duplicates (in file order)
    seen = {}
    for prev, cur in zip(rows, rows[1:]):
        if cur["ts"] < prev["ts"]:
            add("out_of_order", cur["line"], cur["ts"], time_col, f"goes back {fmt_dur(prev['ts'] - cur['ts'])} from line {prev['line']}")
    for r in rows:
        if r["ts"] in seen:
            add("duplicate", r["line"], r["ts"], time_col, f"same timestamp as line {seen[r['ts']]}")
        else:
            seen[r["ts"]] = r["line"]
    srt = sorted({r["ts"]: r for r in reversed(rows)}.values(), key=lambda r: r["ts"])  # first occurrence wins
    diffs = [b["ts"] - a["ts"] for a, b in zip(srt, srt[1:]) if b["ts"] > a["ts"]]
    if interval is None:
        if not diffs:
            raise InputError("cannot infer interval: all timestamps identical")
        interval = statistics.median(diffs)
    expected = int(round((srt[-1]["ts"] - srt[0]["ts"]) / interval)) + 1
    missing_points = 0
    for a, b in zip(srt, srt[1:]):
        d = b["ts"] - a["ts"]
        if d > 1.5 * interval:
            n = int(round(d / interval)) - 1
            missing_points += n
            add("gap", b["line"], a["ts"], time_col, f"{fmt_dur(d)} without data after {fmt_ts(a['ts'])} (~{n} missing)")

    stats = {}
    for c in value_cols:
        vals = [to_float(r["raw"][c]) for r in srt]
        for r, v in zip(srt, vals):
            if v is None:
                add("missing", r["line"], r["ts"], c, f"value {r['raw'][c]!r} is empty or not numeric")
        # flatline runs
        run_start = 0
        for i in range(1, len(vals) + 1):
            if i < len(vals) and vals[i] is not None and vals[i] == vals[run_start]:
                continue
            length = i - run_start
            if vals[run_start] is not None and length >= flatline_points:
                r0, r1 = srt[run_start], srt[i - 1]
                add("flatline", r0["line"], r0["ts"], c, f"value {vals[run_start]:g} repeated {length}x until {fmt_ts(r1['ts'])}")
            run_start = i
        if c in counters:
            for i in range(1, len(vals)):
                if vals[i] is not None and vals[i - 1] is not None and vals[i] < vals[i - 1]:
                    add("reset", srt[i]["line"], srt[i]["ts"], c, f"counter dropped {vals[i - 1]:g} -> {vals[i]:g} (restart or wrap)")
        else:
            for i, v in enumerate(vals):
                if v is None:
                    continue
                med, scale = rolling_robust(vals, i, window)
                if med is None:
                    continue
                score = abs(v - med) / scale
                if score >= z:
                    add("spike", srt[i]["line"], srt[i]["ts"], c, f"{v:g} vs local median {med:g} (robust z {score:.1f})")
        good = [v for v in vals if v is not None]
        stats[c] = {"count": len(good), "min": min(good) if good else None, "max": max(good) if good else None,
                    "median": statistics.median(good) if good else None}

    order = {"out_of_order": 0, "duplicate": 1, "gap": 2, "reset": 3, "missing": 4, "flatline": 5, "spike": 6}
    issues.sort(key=lambda x: (order[x["kind"]], x["time"], x["column"]))
    counts = {}
    for it in issues:
        counts[it["kind"]] = counts.get(it["kind"], 0) + 1
    return {
        "rows": len(rows), "time_column": time_col, "columns": value_cols,
        "start": fmt_ts(srt[0]["ts"]), "end": fmt_ts(srt[-1]["ts"]),
        "interval": fmt_dur(interval), "interval_seconds": interval,
        "expected_points": expected, "missing_points": missing_points,
        "completeness": round(100.0 * len(srt) / expected, 1) if expected else 100.0,
        "stats": stats, "counts": counts, "issues": issues,
    }


def to_markdown(r):
    lines = ["# Time series check", "",
             f"Rows: {r['rows']}  Range: {r['start']} to {r['end']}  Interval: {r['interval']}",
             f"Completeness: {r['completeness']}% ({r['missing_points']} of {r['expected_points']} expected points missing)", "",
             "| Column | Count | Min | Median | Max |", "|---|---|---|---|---|"]
    for c, s in r["stats"].items():
        f = lambda v: "-" if v is None else f"{v:g}"
        lines.append(f"| {c} | {s['count']} | {f(s['min'])} | {f(s['median'])} | {f(s['max'])} |")
    lines += ["", "## Issues"]
    if not r["issues"]:
        lines.append("No issues found.")
    else:
        lines.append("Totals: " + ", ".join(f"{k} {v}" for k, v in r["counts"].items()))
        lines += ["", "| Kind | Time (UTC) | Column | Line | Detail |", "|---|---|---|---|---|"]
        lines += [f"| {i['kind']} | {i['time']} | {i['column']} | {i['line']} | {i['detail']} |" for i in r["issues"]]
    return "\n".join(lines)


def self_test():
    cases = []

    def ok(name, cond):
        cases.append((name, bool(cond)))

    base = 1760860800  # 2025-10-19T08:00:00Z
    def csv_of(points, header="timestamp,value"):
        return header + "\n" + "\n".join(f"{t},{v}" for t, v in points) + "\n"
    wave = [10 + (i % 3) for i in range(30)]
    clean = csv_of([(base + 60 * i, v) for i, v in enumerate(wave)])
    r = check(clean)
    ok("clean series has no issues", r["issues"] == [])
    ok("interval inferred as 1m", r["interval"] == "1m")
    ok("completeness 100%", r["completeness"] == 100.0)
    gap_pts = [(base + 60 * i, v) for i, v in enumerate(wave) if not 10 <= i < 15]
    r = check(csv_of(gap_pts))
    ok("gap detected", r["counts"].get("gap") == 1)
    ok("gap counts 5 missing points", r["missing_points"] == 5)
    spiky = list(wave); spiky[20] = 95
    r = check(csv_of([(base + 60 * i, v) for i, v in enumerate(spiky)]))
    ok("spike detected", [i["line"] for i in r["issues"] if i["kind"] == "spike"] == [22])
    flat = list(wave); flat[5:13] = [7] * 8
    r = check(csv_of([(base + 60 * i, v) for i, v in enumerate(flat)]), z=100)
    ok("flatline detected", r["counts"].get("flatline") == 1)
    miss = [(base + 60 * i, ("" if i == 4 else "NaN" if i == 9 else v)) for i, v in enumerate(wave)]
    ok("missing values detected", check(csv_of(miss)).get("counts").get("missing") == 2)
    dup = [(base + 60 * i, v) for i, v in enumerate(wave)]
    dup.insert(6, dup[5])
    ok("duplicate detected", check(csv_of(dup))["counts"].get("duplicate") == 1)
    ooo = [(base + 60 * i, v) for i, v in enumerate(wave)]
    ooo[7], ooo[8] = ooo[8], ooo[7]
    ok("out of order detected", check(csv_of(ooo))["counts"].get("out_of_order") == 1)
    counter = [(base + 60 * i, 100 * i if i < 20 else 100 * (i - 20)) for i in range(30)]
    r = check(csv_of(counter, "ts,requests_total"), counters=("requests_total",))
    ok("counter reset detected", r["counts"].get("reset") == 1 and "spike" not in r["counts"])
    iso_rows = "time,cpu\n" + "\n".join(f"2026-10-19T08:{i:02d}:00Z,{40 + (i % 2)}" for i in range(0, 60, 5)) + "\n"
    r = check(iso_rows)
    ok("ISO timestamps and 5m interval", r["interval"] == "5m" and r["issues"] == [])
    ms_rows = csv_of([((base + 30 * i) * 1000, v) for i, v in enumerate(wave)])
    ok("epoch milliseconds accepted", check(ms_rows)["interval"] == "30s")
    r = check(clean, interval=30.0)
    ok("explicit 30s interval flags every 1m step as a gap", r["counts"].get("gap") == 29 and r["completeness"] < 60)
    jitter = csv_of([(base + 60 * i + (3 if i % 2 else -2), v) for i, v in enumerate(wave)])
    ok("small timestamp jitter is not a gap", "gap" not in check(jitter)["counts"])
    multi = "timestamp,a,b\n" + "\n".join(f"{base + 60 * i},{wave[i]},{wave[i] * 2 if i != 12 else 500}" for i in range(30)) + "\n"
    r = check(multi, cols=["a", "b"])
    ok("multi-column spike only in b", {i["column"] for i in r["issues"]} == {"b"})
    for bad, label in (("timestamp,value\n1,2\n", "too few rows rejected"),
                       ("timestamp,value\nyesterday,1\ntoday,2\nnow,3\n", "bad timestamp rejected")):
        try:
            check(bad)
            ok(label, False)
        except InputError:
            ok(label, True)
    ok("markdown renders", "## Issues" in to_markdown(check(clean)))
    passed = sum(c for _, c in cases)
    for name, c in cases:
        print(("PASS " if c else "FAIL ") + name)
    print(f"{passed}/{len(cases)} passed")
    return 0 if passed == len(cases) else 1


def main(argv=None):
    ap = argparse.ArgumentParser(description="Find gaps, duplicates, flatlines, spikes, and counter resets in CSV metrics.")
    ap.add_argument("csv", nargs="?", help="CSV file, or '-' for stdin")
    ap.add_argument("--time-col")
    ap.add_argument("--cols", help="comma-separated value columns (default: all except the time column)")
    ap.add_argument("--interval", help="expected spacing, e.g. 30s, 5m, 1h (default: median spacing)")
    ap.add_argument("--z", type=float, default=4.0, help="robust z-score threshold for spikes (default 4)")
    ap.add_argument("--window", type=int, default=6, help="neighbours on each side for the rolling median (default 6)")
    ap.add_argument("--flatline-points", type=int, default=6)
    ap.add_argument("--counter", default="", help="comma-separated monotonic counter columns (checked for resets, not spikes)")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args(argv)
    if a.self_test:
        return self_test()
    if not a.csv:
        ap.error("csv path required (or --self-test)")
    try:
        text = sys.stdin.read() if a.csv == "-" else open(a.csv, encoding="utf-8-sig").read()
        r = check(text, a.time_col, [c.strip() for c in a.cols.split(",")] if a.cols else None,
                  parse_interval(a.interval) if a.interval else None, a.z, a.window, a.flatline_points,
                  tuple(c.strip() for c in a.counter.split(",") if c.strip()))
    except (OSError, InputError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(r, indent=2) if a.json else to_markdown(r))
    return 1 if r["issues"] else 0


if __name__ == "__main__":
sys.exit(main())Decodes a JWT without trusting it and lints the header and claims: alg none, remote jku/x5u keys, missing or expired exp, nbf/iat clock skew, millisecond timestamps, long lifetimes, iss/aud mismatches, sensitive data in the payload, and HMAC signature checks with a secret from an env var. Use when a login or API call fails with 401, or when reviewing token settings. Includes a stdlib Python inspector with --self-test.
---
name: jwt-token-inspector
description: Decodes a JWT without trusting it and lints the header and claims: alg none, remote jku/x5u keys, missing or expired exp, nbf/iat clock skew, millisecond timestamps, long lifetimes, iss/aud mismatches, sensitive data in the payload, and HMAC signature checks with a secret from an env var. Use when a login or API call fails with 401, or when reviewing token settings. Includes a stdlib Python inspector with --self-test.
---

# JWT Token Inspector

You help developers understand and debug JSON Web Tokens safely. You decode the header and payload, translate timestamps into readable UTC times, explain what each claim means, and flag settings that make the token unsafe, unusable, or likely to break in production. You treat every token as untrusted: decoding is not verification, and you say so.

## Files in this skill

- `scripts/jwt_inspect.py` - decodes a JWS compact token, lints header and claims, optionally verifies HS256/HS384/HS512 with a secret, prints markdown or JSON (Python 3 standard library only)
- `references/claims-and-validation.md` - registered claims, what a verifier must check, and in which order
- `references/common-jwt-pitfalls.md` - the mistakes behind most JWT bugs and incidents, with fixes
- `templates/jwt-review.md` - a short report for a bug ticket, PR review, or security review
- `examples/sample-tokens.md` - three demo tokens (long-lived, alg none, remote jku with millisecond exp) and expected findings

## Workflow

### 1. Handle the token safely
Ask for a token from a test or staging environment. If the user pastes a live production token, warn them that it grants access until it expires and suggest rotating it after the session. Never repeat the full token or signature back in your answer.

### 2. Run the inspector
```
python3 scripts/jwt_inspect.py "<token>"
python3 scripts/jwt_inspect.py "<token>" --now 2026-10-19T09:00:00Z --leeway 60
python3 scripts/jwt_inspect.py "<token>" --expect-iss https://auth.example.com --expect-aud api://orders
JWT_SECRET=... python3 scripts/jwt_inspect.py "<token>" --secret-env JWT_SECRET
python3 scripts/jwt_inspect.py --self-test
```
A `Bearer ` prefix is stripped. Use `-` to read the token from stdin. Exit code 1 means at least one high finding (`--strict`: any finding); 2 means the token could not be decoded.

### 3. Explain the result
- Show the decoded header and claims and the exp/nbf/iat times in UTC and in the user's time zone.
- Group findings by severity: **high** (unsafe or rejected: alg none, empty signature, expired, not yet valid, iss/aud mismatch, remote or embedded keys, bad signature, millisecond timestamps), **medium** (no exp, lifetime over policy, sensitive claims, weak HMAC secret, iat in the future), **low** (missing iss, aud, sub, or kid).
- For a 401, match the finding to the symptom using `references/claims-and-validation.md`: clock skew, wrong audience, wrong issuer, or wrong key are the usual causes.

### 4. Recommend fixes
Use `references/common-jwt-pitfalls.md`: pin the algorithm list on the verifier, keep access tokens short (5-15 minutes) with refresh tokens, move personal data out of the payload, allow 30-60 seconds of leeway, and fetch keys only from a configured JWKS URL.

### 5. Report
Fill `templates/jwt-review.md` with the token fingerprint (never the token), findings, root cause, and the agreed fix.

## Rules

- Decoding is not verification. Never say a token is valid unless its signature was checked with the right key.
- Never print or store full tokens, signatures, or secrets. Pass secrets through an environment variable, not the command line.
- Do not help forge, replay, or tamper with tokens for systems the user does not own.
- RS/ES/PS/EdDSA signatures need the public key and a proper JOSE library; the script only verifies HMAC algorithms.
FILE:references/claims-and-validation.md
# Claims and Validation Order

## Registered claims (RFC 7519)
| Claim | Meaning | Type | Notes |
|---|---|---|---|
| iss | Issuer | string/URL | Pin it on the verifier; one issuer per trust domain |
| sub | Subject (user or service id) | string | Stable id, not an email that can change |
| aud | Audience | string or array | The API must find its own id in it |
| exp | Expiration time | NumericDate (seconds) | Required for access tokens |
| nbf | Not before | NumericDate | Token is rejected until then |
| iat | Issued at | NumericDate | Used for lifetime and freshness checks |
| jti | Token id | string | Enables revocation lists and replay detection |

NumericDate is seconds since 1970-01-01T00:00:00Z. A 13-digit value is milliseconds and will be read as a date tens of thousands of years away.

## Header parameters
- `alg` - signing algorithm. The verifier decides which values are allowed; the token never does.
- `kid` - key id, used to pick the right key from the issuer's JWKS during rotation.
- `typ` - usually `JWT` or `at+jwt` (access token profile, RFC 9068).
- `jku`, `x5u`, `jwk` - point to or embed keys. Ignore them unless they match a pinned, trusted source.

## What a verifier must check, in order
1. Token has three segments and decodes to JSON objects.
2. `alg` is in the verifier's allow-list (for example only RS256). Reject `none`.
3. Signature verifies with a key chosen by `kid` from a trusted JWKS, never from the token itself.
4. `exp` is in the future and `nbf` is in the past, both with small leeway (30-60 s).
5. `iss` equals the expected issuer.
6. `aud` contains this service's id.
7. Application rules: scopes, roles, tenant, `jti` not revoked.

## Matching 401 symptoms to causes
| Symptom | Likely cause | Check |
|---|---|---|
| Works locally, fails in prod | Clock skew or different issuer URL | iat/nbf vs server time, iss |
| Fails right after login | nbf or iat in the future | server clocks (NTP) |
| Fails for one API only | Wrong audience | aud list |
| Fails after key rotation | Unknown kid or cached JWKS | kid vs JWKS, cache TTL |
| Never expires | exp missing or in milliseconds | exp value |
FILE:references/common-jwt-pitfalls.md
# Common JWT Pitfalls

1. **Accepting `alg: none`.** Unsigned tokens are forgeable. Fix: pass an explicit algorithm allow-list to the verify call.
2. **Algorithm confusion (RS256 vs HS256).** If a verifier accepts both, an attacker can sign with HMAC using the public key as the secret. Fix: one algorithm family per key.
3. **Trusting keys from the token.** `jku`, `x5u`, or an embedded `jwk` let the sender choose the key. Fix: load keys only from a configured JWKS URL.
4. **Weak HMAC secrets.** Short or dictionary secrets can be brute-forced offline from one token. Fix: at least 32 random bytes for HS256 (48 for HS384, 64 for HS512), stored in a secret manager.
5. **Long-lived access tokens.** A leaked token works until exp. Fix: 5-15 minute access tokens plus rotating refresh tokens; revoke by `jti` if needed.
6. **Personal data in the payload.** Base64url is encoding, not encryption; anyone holding the token can read it. Fix: keep ids and scopes only, or use JWE.
7. **Milliseconds instead of seconds.** Common with `Date.now()` in JavaScript. Fix: `Math.floor(Date.now() / 1000)`.
8. **No leeway.** Small clock differences cause random 401s. Fix: 30-60 seconds of leeway and NTP on all hosts.
9. **Skipping aud/iss checks.** A token for one service gets replayed against another. Fix: always validate both.
10. **Tokens in URLs or logs.** They leak through referrers, proxies, and log search. Fix: send in the Authorization header and redact in logs.
FILE:templates/jwt-review.md
# JWT Review - <service or ticket>

**Token fingerprint:** sha256 <first 12 hex chars>  **Environment:** <dev / staging / prod>  **Checked at:** <UTC time>
**Issuer:** <iss>  **Audience:** <aud>  **Algorithm:** <alg>  **Lifetime:** <exp - iat>

## Findings
| Severity | Code | Detail | Fix |
|---|---|---|---|
| | | | |

## Root cause
<one or two sentences tying the finding to the reported symptom>

## Agreed changes
- [ ] Verifier: <allow-list, leeway, iss/aud checks>
- [ ] Issuer: <lifetime, claims, key size, kid>
- [ ] Rotate exposed token or secret: <yes/no, owner>

## Notes
Decoded with scripts/jwt_inspect.py. The token itself is not stored in this report.
FILE:examples/sample-tokens.md
# Sample Tokens (demo only, no real systems)

Run each with:
```
python3 scripts/jwt_inspect.py "<token>" --now 2026-10-19T09:00:00Z --expect-aud api://orders
```

## 1. Long-lived customer token (HS256, demo secret "dev-secret")
```
eyJhbGciOiJIUzI1NiIsInR5cCI6IkpXVCJ9.eyJpc3MiOiJodHRwczovL2F1dGguc2hvcGZyb250LmV4YW1wbGUiLCJzdWIiOiJjdXN0Xzg4NDEiLCJhdWQiOlsiYXBpOi8vb3JkZXJzIiwiYXBpOi8vcHJvZmlsZSJdLCJpYXQiOjE3OTIzOTUwMDAsImV4cCI6MTc5Mjk5OTgwMCwiZW1haWwiOiJtaW5hQGV4YW1wbGUuY29tIiwicm9sZXMiOlsiY3VzdG9tZXIiXSwiY2FyZF9sYXN0NCI6IjQyNDIifQ.xupeoN2LYDYe-FKD_4qOh7KCw6G68Zi1pCms7dtUGh0
```
Expected: exit 0; medium lifetime_long (7.0d over 1.0d policy), medium sensitive_claim (card_last4). With `--secret-env` set to "dev-secret": signature verified, plus medium weak_secret (10 bytes).

## 2. Unsigned admin token (alg none)
```
eyJhbGciOiJub25lIiwidHlwIjoiSldUIn0.eyJpc3MiOiJodHRwczovL2F1dGguc2hvcGZyb250LmV4YW1wbGUiLCJzdWIiOiJhZG1pbiIsInJvbGUiOiJhZG1pbiIsImlhdCI6MTc5MjM5NTAwMH0.
```
Expected: exit 1; high alg_none, high aud_mismatch (no aud but api://orders required), medium exp_missing.

## 3. Remote key URL and millisecond expiry (RS256)
```
eyJhbGciOiJSUzI1NiIsInR5cCI6IkpXVCIsImprdSI6Imh0dHBzOi8va2V5cy5hdHRhY2tlci5leGFtcGxlL2p3a3MuanNvbiJ9.eyJpc3MiOiJodHRwczovL2F1dGguc2hvcGZyb250LmV4YW1wbGUiLCJzdWIiOiJzdmMtcmVwb3J0cyIsImF1ZCI6ImFwaTovL29yZGVycyIsImlhdCI6MTc5MjM5NTAwMCwiZXhwIjoxNzkyMzk4NjAwMDAwfQ.bm90LWEtcmVhbC1zaWduYXR1cmUtanVzdC1hLWRlbW8
```
Expected: exit 1; high exp_milliseconds, high header_jku, low kid_missing.
FILE:scripts/jwt_inspect.py
#!/usr/bin/env python3
"""JWT token inspector and claim linter (Python 3 standard library only).

Decodes a JSON Web Token (JWS compact form: header.payload.signature) WITHOUT trusting it,
prints the header and claims with human-readable times, and flags risky or broken settings.
Optionally verifies HS256/HS384/HS512 signatures when you pass the shared secret.

Usage:
  python3 jwt_inspect.py <token>                     # or "-" to read the token from stdin
  python3 jwt_inspect.py <token> --now 2026-10-19T09:00:00Z --leeway 60
  python3 jwt_inspect.py <token> --expect-iss https://auth.example.com --expect-aud api://orders
  python3 jwt_inspect.py <token> --secret-env JWT_SECRET   # verify HS* with a secret from an env var
  python3 jwt_inspect.py <token> --max-lifetime 3600 --json
  python3 jwt_inspect.py --self-test

Severity: high (token unsafe or unusable), medium (likely bug or weak policy), low (hygiene).
Exit code: 0 no high findings, 1 at least one high finding (or --strict and any finding), 2 bad input.
The signature itself is never printed; only its length and a short SHA-256 fingerprint of the token.
"""
import argparse
import base64
import datetime as dt
import hashlib
import hmac
import json
import os
import re
import sys

HS_ALGS = {"HS256": hashlib.sha256, "HS384": hashlib.sha384, "HS512": hashlib.sha512}
MIN_HS_SECRET = {"HS256": 32, "HS384": 48, "HS512": 64}
KNOWN_ALGS = set(HS_ALGS) | {"RS256", "RS384", "RS512", "PS256", "PS384", "PS512",
                             "ES256", "ES384", "ES512", "EdDSA"}
SENSITIVE = re.compile(r"(pass(word)?|pwd|secret|ssn|social|credit|card|cvv|iban|private|api_?key|refresh_?token)", re.I)
TIME_CLAIMS = ("exp", "nbf", "iat")


class TokenError(ValueError):
    pass


def b64url_decode(part, what):
    if not re.fullmatch(r"[A-Za-z0-9_-]*", part):
        raise TokenError(f"{what} is not base64url (found characters outside A-Z a-z 0-9 - _ or '=' padding)")
    try:
        return base64.urlsafe_b64decode(part + "=" * (-len(part) % 4))
    except (ValueError, TypeError) as e:
        raise TokenError(f"{what} could not be base64url-decoded: {e}")


def b64url_encode(raw):
    return base64.urlsafe_b64encode(raw).rstrip(b"=").decode("ascii")


def decode(token):
    token = token.strip()
    if token.lower().startswith("bearer "):
        token = token[7:].strip()
    parts = token.split(".")
    if len(parts) == 5:
        raise TokenError("5 segments: this is an encrypted JWE, not a signed JWS; it cannot be inspected without the key")
    if len(parts) != 3:
        raise TokenError(f"expected 3 dot-separated segments, found {len(parts)}")
    out = {}
    for name, part in (("header", parts[0]), ("payload", parts[1])):
        raw = b64url_decode(part, name)
        try:
            obj = json.loads(raw.decode("utf-8"))
        except (UnicodeDecodeError, ValueError):
            raise TokenError(f"{name} is not valid UTF-8 JSON")
        if not isinstance(obj, dict):
            raise TokenError(f"{name} must be a JSON object")
        out[name] = obj
    out["signature"] = b64url_decode(parts[2], "signature")
    out["signing_input"] = (parts[0] + "." + parts[1]).encode("ascii")
    out["fingerprint"] = hashlib.sha256(token.encode("utf-8")).hexdigest()[:12]
    return out


def parse_now(value):
    if value is None:
        return int(dt.datetime.now(dt.timezone.utc).timestamp())
    if re.fullmatch(r"\d+", value):
        return int(value)
    t = dt.datetime.fromisoformat(value.replace("Z", "+00:00"))
    if t.tzinfo is None:
        t = t.replace(tzinfo=dt.timezone.utc)
    return int(t.timestamp())


def iso(ts):
    try:
        return dt.datetime.fromtimestamp(ts, dt.timezone.utc).strftime("%Y-%m-%dT%H:%M:%SZ")
    except (OverflowError, OSError, ValueError, TypeError):
        return "invalid"


def human_delta(seconds):
    s = abs(int(seconds))
    for unit, size in (("d", 86400), ("h", 3600), ("m", 60)):
        if s >= size:
            return f"{s / size:.1f}{unit}"
    return f"{s}s"


def verify_hs(tok, secret):
    alg = tok["header"].get("alg")
    fn = HS_ALGS.get(alg)
    if fn is None:
        return None
    mac = hmac.new(secret.encode("utf-8"), tok["signing_input"], fn).digest()
    return hmac.compare_digest(mac, tok["signature"])


def inspect(token, now=None, leeway=0, expect_iss=None, expect_aud=None, max_lifetime=86400, secret=None):
    tok = decode(token)
    h, p = tok["header"], tok["payload"]
    findings = []

    def add(sev, code, msg):
        findings.append({"severity": sev, "code": code, "message": msg})

    alg = h.get("alg")
    if alg is None:
        add("high", "alg_missing", "header has no 'alg'; libraries may reject it or guess")
    elif str(alg).lower() == "none":
        add("high", "alg_none", "alg is 'none': the token is unsigned and anyone can forge it")
        if tok["signature"]:
            add("medium", "none_with_signature", "alg 'none' but a signature segment is present")
    elif alg not in KNOWN_ALGS:
        add("medium", "alg_unknown", f"unusual alg '{alg}'")
    if alg and str(alg).lower() != "none" and not tok["signature"]:
        add("high", "signature_empty", "signature segment is empty although alg requires one")
    for key in ("jku", "x5u"):
        if key in h:
            add("high", f"header_{key}", f"header '{key}' points to a remote key URL ({h[key]}); never fetch keys from a URL inside the token")
    if "jwk" in h:
        add("high", "header_jwk", "header embeds its own 'jwk'; a verifier that trusts it accepts attacker keys")
    if "crit" in h:
        add("medium", "header_crit", f"'crit' lists extensions {h['crit']}; verifiers must understand them or reject the token")
    if alg in KNOWN_ALGS and alg not in HS_ALGS and "kid" not in h:
        add("low", "kid_missing", "asymmetric alg without 'kid'; key rotation will be painful")

    now = parse_now(now) if not isinstance(now, int) else now
    times = {}
    for c in TIME_CLAIMS:
        if c in p:
            v = p[c]
            if isinstance(v, bool) or not isinstance(v, (int, float)):
                add("high", f"{c}_not_numeric", f"'{c}' must be NumericDate seconds, got {v!r}")
            elif v > 10**11:
                add("high", f"{c}_milliseconds", f"'{c}'={v} looks like milliseconds; JWT uses seconds")
            else:
                times[c] = int(v)
    if "exp" not in p:
        add("medium", "exp_missing", "no 'exp': the token never expires")
    elif "exp" in times and times["exp"] + leeway < now:
        add("high", "expired", f"expired at {iso(times['exp'])} ({human_delta(now - times['exp'])} ago)")
    if "nbf" in times and times["nbf"] - leeway > now:
        add("high", "not_yet_valid", f"not valid before {iso(times['nbf'])} ({human_delta(times['nbf'] - now)} from now)")
    if "iat" in times and times["iat"] - leeway > now:
        add("medium", "iat_future", f"issued in the future ({iso(times['iat'])}); check clock skew")
    if "exp" in times and "iat" in times:
        life = times["exp"] - times["iat"]
        if life <= 0:
            add("high", "exp_before_iat", "exp is not after iat")
        elif max_lifetime and life > max_lifetime:
            add("medium", "lifetime_long", f"lifetime {human_delta(life)} exceeds policy {human_delta(max_lifetime)}")
    if "iss" not in p:
        add("low", "iss_missing", "no 'iss'; verifiers cannot pin the issuer")
    elif expect_iss and p["iss"] != expect_iss:
        add("high", "iss_mismatch", f"iss '{p['iss']}' != expected '{expect_iss}'")
    aud = p.get("aud")
    auds = aud if isinstance(aud, list) else ([aud] if aud is not None else [])
    if aud is None and expect_aud:
        add("high", "aud_mismatch", f"no 'aud' claim but '{expect_aud}' is required")
    elif aud is None:
        add("low", "aud_missing", "no 'aud'; the token could be replayed against another service")
    elif expect_aud and expect_aud not in auds:
        add("high", "aud_mismatch", f"aud {auds} does not contain expected '{expect_aud}'")
    if "sub" not in p:
        add("low", "sub_missing", "no 'sub'; who is this token about?")
    for k in p:
        if SENSITIVE.search(k):
            add("medium", "sensitive_claim", f"claim '{k}' looks sensitive; JWT payloads are only encoded, not encrypted")

    verified = None
    if secret is not None:
        if alg not in HS_ALGS:
            add("low", "verify_skipped", f"--secret only verifies HS256/384/512; alg is {alg}")
        else:
            verified = verify_hs(tok, secret)
            if not verified:
                add("high", "bad_signature", "HMAC signature does NOT match the given secret")
            if len(secret.encode("utf-8")) < MIN_HS_SECRET[alg]:
                add("medium", "weak_secret", f"{alg} secret is {len(secret.encode('utf-8'))} bytes; use at least {MIN_HS_SECRET[alg]} random bytes")

    order = {"high": 0, "medium": 1, "low": 2}
    findings.sort(key=lambda f: (order[f["severity"]], f["code"]))
    return {
        "fingerprint": tok["fingerprint"],
        "header": h,
        "payload": p,
        "times": {c: iso(v) for c, v in times.items()},
        "now": iso(now),
        "signature_bytes": len(tok["signature"]),
        "signature_verified": verified,
        "findings": findings,
    }


def to_markdown(r):
    lines = [f"# JWT inspection (sha256 {r['fingerprint']})", "",
             f"Checked at {r['now']}. Signature: {r['signature_bytes']} bytes"
             + ("" if r["signature_verified"] is None else (", verified OK" if r["signature_verified"] else ", NOT verified")), "",
             "## Header", "```json", json.dumps(r["header"], indent=2, ensure_ascii=False), "```", "",
             "## Claims", "```json", json.dumps(r["payload"], indent=2, ensure_ascii=False), "```", ""]
    if r["times"]:
        lines += ["| Claim | UTC |", "|---|---|"] + [f"| {k} | {v} |" for k, v in r["times"].items()] + [""]
    lines += ["## Findings"]
    if not r["findings"]:
        lines.append("No findings.")
    else:
        lines += ["| Severity | Code | Detail |", "|---|---|---|"]
        lines += [f"| {f['severity']} | {f['code']} | {f['message']} |" for f in r["findings"]]
    return "\n".join(lines)


def make_token(header, payload, secret=None, signature=b""):
    si = b64url_encode(json.dumps(header, separators=(",", ":")).encode()) + "." + \
         b64url_encode(json.dumps(payload, separators=(",", ":")).encode())
    if secret is not None:
        signature = hmac.new(secret.encode(), si.encode(), HS_ALGS[header["alg"]]).digest()
    return si + "." + b64url_encode(signature)


def self_test():
    now = 1760860800  # 2025-10-19T08:00:00Z
    strong = "k" * 40
    good_claims = {"iss": "https://auth.example.com", "sub": "user-42", "aud": "api://orders",
                   "iat": now - 60, "exp": now + 840}
    good = make_token({"alg": "HS256", "typ": "JWT"}, good_claims, strong)
    codes = lambda r: {f["code"] for f in r["findings"]}
    cases = []

    def check(name, cond):
        cases.append((name, bool(cond)))

    r = inspect(good, now=now, secret=strong, expect_iss="https://auth.example.com", expect_aud="api://orders")
    check("clean token has no findings", r["findings"] == [])
    check("clean token signature verified", r["signature_verified"] is True)
    check("bearer prefix accepted", inspect("Bearer " + good, now=now)["payload"]["sub"] == "user-42")
    check("wrong secret flagged", "bad_signature" in codes(inspect(good, now=now, secret="x" * 40)))
    check("weak secret flagged", "weak_secret" in codes(inspect(make_token({"alg": "HS256"}, good_claims, "short"), now=now, secret="short")))
    check("alg none flagged high", "alg_none" in codes(inspect(make_token({"alg": "none"}, good_claims), now=now)))
    check("expired flagged", "expired" in codes(inspect(good, now=now + 3600)))
    check("leeway tolerates small skew", "expired" not in codes(inspect(good, now=now + 850, leeway=30)))
    check("nbf in future flagged", "not_yet_valid" in codes(inspect(make_token({"alg": "HS256"}, dict(good_claims, nbf=now + 600), strong), now=now)))
    check("exp missing flagged", "exp_missing" in codes(inspect(make_token({"alg": "HS256"}, {"sub": "a", "iat": now}, strong), now=now)))
    check("milliseconds exp flagged", "exp_milliseconds" in codes(inspect(make_token({"alg": "HS256"}, dict(good_claims, exp=(now + 600) * 1000), strong), now=now)))
    check("long lifetime flagged", "lifetime_long" in codes(inspect(make_token({"alg": "HS256"}, dict(good_claims, exp=now + 30 * 86400), strong), now=now)))
    check("iss mismatch flagged", "iss_mismatch" in codes(inspect(good, now=now, expect_iss="https://evil.example")))
    check("aud list accepted", "aud_mismatch" not in codes(inspect(make_token({"alg": "HS256"}, dict(good_claims, aud=["a", "api://orders"]), strong), now=now, expect_aud="api://orders")))
    check("aud mismatch flagged", "aud_mismatch" in codes(inspect(good, now=now, expect_aud="api://billing")))
    check("missing aud with expected aud is high", "aud_mismatch" in codes(inspect(make_token({"alg": "HS256"}, {k: v for k, v in good_claims.items() if k != "aud"}, strong), now=now, expect_aud="api://orders")))
    check("jku header flagged", "header_jku" in codes(inspect(make_token({"alg": "RS256", "kid": "1", "jku": "https://x/keys"}, good_claims, signature=b"sig"), now=now)))
    check("rs256 without kid is low", "kid_missing" in codes(inspect(make_token({"alg": "RS256"}, good_claims, signature=b"sig"), now=now)))
    check("sensitive claim flagged", "sensitive_claim" in codes(inspect(make_token({"alg": "HS256"}, dict(good_claims, password="hunter2"), strong), now=now)))
    check("empty signature flagged", "signature_empty" in codes(inspect(make_token({"alg": "HS256"}, good_claims), now=now)))
    for bad, label in (("abc.def", "two segments rejected"), ("a.b.c.d.e", "JWE rejected"), ("!!.e30.", "bad base64 rejected")):
        try:
            inspect(bad, now=now)
            check(label, False)
        except TokenError:
            check(label, True)
    check("markdown never prints signature", make_token({"alg": "HS256"}, good_claims, strong).split(".")[2] not in to_markdown(r))
    passed = sum(ok for _, ok in cases)
    for name, ok in cases:
        print(("PASS " if ok else "FAIL ") + name)
    print(f"{passed}/{len(cases)} passed")
    return 0 if passed == len(cases) else 1


def main(argv=None):
    ap = argparse.ArgumentParser(description="Decode and lint a JWT without trusting it.")
    ap.add_argument("token", nargs="?", help="JWT string, or '-' to read from stdin")
    ap.add_argument("--now", help="reference time: ISO 8601 (Z or offset) or epoch seconds; default: current UTC time")
    ap.add_argument("--leeway", type=int, default=0, help="allowed clock skew in seconds (default 0)")
    ap.add_argument("--expect-iss")
    ap.add_argument("--expect-aud")
    ap.add_argument("--max-lifetime", type=int, default=86400, help="max exp-iat seconds before warning (0 = off)")
    ap.add_argument("--secret-env", help="name of an environment variable holding the HS* secret (avoids shell history)")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--strict", action="store_true", help="exit 1 on any finding")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args(argv)
    if a.self_test:
        return self_test()
    if not a.token:
        ap.error("token required (or --self-test)")
    token = sys.stdin.read() if a.token == "-" else a.token
    secret = None
    if a.secret_env:
        secret = os.environ.get(a.secret_env)
        if secret is None:
            print(f"error: environment variable {a.secret_env} is not set", file=sys.stderr)
            return 2
    try:
        r = inspect(token, now=a.now, leeway=a.leeway, expect_iss=a.expect_iss, expect_aud=a.expect_aud,
                    max_lifetime=a.max_lifetime, secret=secret)
    except (TokenError, ValueError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(r, indent=2, ensure_ascii=False) if a.json else to_markdown(r))
    if any(f["severity"] == "high" for f in r["findings"]) or (a.strict and r["findings"]):
        return 1
    return 0


if __name__ == "__main__":
sys.exit(main())Build an image-ready brief for a small rammed earth village library: plaza and reading garden orientation, compact form with a signature reading tower, a four-to-five material palette, native landscape, fixed visual details, and two exterior prompt seeds (morning plaza and dusk garden).
Act as an architectural concept designer who writes image-ready design briefs. Help me shape a small rammed earth community library for a village or small town: a single-story building with a reading room, a children's corner, and a shaded outdoor reading garden. Your brief must be specific enough that two separate image generations (an establishing exterior and a second exterior view) show the same building.

First ask me, in one short message, for:
- Region and climate (for example dry highland, warm Mediterranean hills, semi-arid plains) and the season I want to show
- The site: village square, edge of a park, hillside lane, or beside a school
- Collection size and capacity (how many readers at once), and whether there is a small community room
- Material preferences and anything I want to avoid (glass boxes, heavy concrete, rustic kitsch)
- Mood words (welcoming, quiet, sunlit, earthy, civic, playful)

Then produce the brief with these sections:

1. **Site and Orientation**: where the library sits, which side faces the public plaza and which faces the reading garden, the sun path for morning and dusk, and how people approach on foot.

2. **Building Form**: footprint size, roof type (flat, low mono-pitch, or gently curved), roof edge and overhang, the shaded entrance porch, the number and position of large openings, and one signature element such as a round reading tower or a wide clerestory band. Keep it compact and buildable.

3. **Materials Palette**: exactly four or five materials with colors (for example layered ochre and rust rammed earth walls, pale timber columns and soffits, a thin dark steel roof edge, local stone paving, clay planters) and where each appears.

4. **Landscape**: native trees and grasses, one signature tree near the entrance, a shallow stone water channel or none, benches, and bicycle stands.

5. **Fixed Visual Details**: a numbered list of 8 to 10 details that must stay identical in every image (wall color and visible earth layers, roof shape, number of porch columns, window count and shape, door color, the signature element and its position, the signature tree and its side, lighting fixtures). These details make the images consistent.

6. **Prompt Seed A - Establishing Exterior**: a ready-to-paste image prompt under 150 words for a bright morning exterior from the public plaza, with the building and its key objects in the first sentence.

7. **Prompt Seed B - Second Exterior View**: a ready-to-paste image prompt under 150 words for a dusk view from the reading garden side with warm light glowing from the windows, repeating every fixed visual detail in plain words and stating which side each element appears on from this viewpoint.

8. **Practical Notes**: three short notes on passive cooling and shade, step-free access, and protecting earth walls from rain (roof overhang, stone plinth).

Rules: no people as the main subject, no text, signs, or logos in the image prompts, no interiors in the seeds (image models often ignore furniture). Use short paragraphs and lists.
Tilt-shift travel photo of curving mountain rice terraces stepping down to a wooden stilt-house village at dawn: flooded paddies mirroring a pink and gold sky, valley mist, wood smoke, a footbridge, and a narrow sharp focus band that makes it look like a model.
Curving green rice terraces step down a mountainside toward a small village of wooden stilt houses with dark thatched roofs at dawn, photographed as a tilt-shift miniature. Seen from a high vantage point across the valley, with a narrow band of sharp focus on the village and the middle terraces, and strong blur at the top and bottom of the frame so the scene looks like a tiny model. Flooded terraces mirror the pink and gold sky like strips of glass, and low mist pools in the valley floor. A small stream with a footbridge winds past the houses, thin wood smoke rises from two chimneys, and a few ducks float on a paddy. Banana palms and bamboo clumps edge the fields. Saturated but natural colors, crisp morning light raking across the terrace walls, gentle long shadows. Professional travel photography, tilt-shift lens effect, wide landscape 16:9. No people, no text, no signs, no vehicles.
Handmade claymation set: four clay frogs playing a banjo, reed bass, acorn-cap drums, and a snail-shell horn on giant lily pads at dusk, with paper lanterns, LED fireflies, cattails, resin water, and felt hills. Cozy macro miniature look.
Four cheerful clay frogs play tiny instruments on giant lily pads in a pond at dusk: one strums a little banjo, one plays an upright bass made from a hollow reed, one taps drums made of acorn caps, and one blows a curled snail-shell horn. Handmade stop-motion claymation set with visible fingerprints and soft tool marks in the plasticine. Paper lanterns glow on short bent-wire posts around the pond, and fireflies made of tiny warm LEDs drift between cattails and pink water lilies. The water is glossy blue resin with gentle ripples and reflections of the lanterns. Background of felt hills, cotton-wool mist, and a painted twilight sky in peach and lavender with a few early stars. Shallow depth of field like a real miniature set photographed with a macro lens, warm key light and cool blue rim light. Playful, cozy, storybook mood with rich saturated colors. Wide landscape 16:9. No people, no hands, no text, no letters, no logos.
Art Nouveau decorative panel: a grey heron with an S-curved neck among blue and violet irises at a moonlit lily pond, a gold-leaf moon halo, dragonflies, and a whiplash-vine border. Bold outlines, flat muted teal, sage, iris blue, and gold.
A grey heron stands on one leg among tall blue and violet irises at the edge of a moonlit lily pond, framed by an ornate Art Nouveau border of curling whiplash vines, iris leaves, and dragonflies. Wide horizontal decorative panel in the spirit of 1900s Art Nouveau posters and stained-glass design. The heron's long neck forms a graceful S-curve, its feathers drawn with flowing contour lines in soft greys and pearl white. A large pale full moon sits inside a circular halo behind the bird, with concentric rings of gold leaf. Water lilies and round pads float on dark teal water with stylized ripple patterns. Bold dark outlines, flat areas of muted color, and fine decorative linework. Palette of deep teal, sage green, iris blue, lavender, cream, and burnished gold, with subtle aged paper grain. Symmetrical, elegant, calm composition with the heron slightly left of center and irises balancing the right side. Landscape 16:9. No people, no text, no lettering, no signature, no logos.
Build a personalized household emergency plan as YAML: local hazards with first actions, out-of-area contact and check-in rules, meeting points, evacuation grab list and pet plan, go bag and home kits, utility shut-offs, free-first budget, practice drills, and a fridge summary.
1role: Calm, practical household emergency preparedness planner2task: >3 Turn a short description of a household into a personalized emergency preparedness4 plan in YAML: likely local hazards, a communication plan, meeting points, supply kits,5 home safety checks, and a simple practice schedule. The plan must be realistic for the6 household's budget, space, and abilities, and easy to print and stick on the fridge.78ask_first:9 - Location type and climate (city apartment, suburban house, rural home; coastal, river valley, mountains, hot or cold region)10 - Hazards the household worries about or that local authorities warn about (storms, floods, wildfires, earthquakes, heat waves, winter storms, power outages)...+76 more lines
Turn any messy bug report, ticket, or log paste into a strict JSON triage card: clear title, environment, numbered repro steps, expected vs actual, redacted evidence, severity and priority with reasons, impact, labeled cause guess, questions for the reporter, and a regression test idea.
1{2 "role": "Senior QA engineer who turns messy bug reports into clear, reproducible triage cards",3 "task": "Take any raw bug report (a chat message, support ticket, screenshot description, customer email, or log excerpt) and normalize it into one strict JSON triage card that a developer can act on without asking follow-up questions.",4 "instructions": [5 "Read the raw report and any pasted logs, stack traces, or environment details. Separate facts the reporter stated from your own inferences.",6 "Never invent steps, versions, error messages, or log lines. If something is unknown, set it to null and add a question to missing_information.",7 "Rewrite reproduction steps as short numbered actions a stranger could follow, starting from a clean state.",8 "Estimate severity from user impact and priority from impact plus reach and urgency, and explain both in one sentence each.",9 "Redact secrets and personal data (tokens, passwords, emails, phone numbers, addresses) with [REDACTED] in every field.",10 "If the report describes several unrelated problems, output one card for the main problem and list the others in related_issues_to_split.",...+70 more lines
Coach a newly promoted manager to run weekly one-on-ones that build trust: ground rules script, 30-minute template with shared notes, question bank, tailored plans per report, SBI feedback scripts, tricky-moment responses, follow-through system, and a 30-day check.
Act as a First-Time Manager One-on-One Coach. You help someone who was recently promoted to lead a team (often their former peers) run weekly one-on-one meetings that build trust, surface problems early, and help each person grow. You are practical, warm, and direct. You give scripts and frameworks, not lectures, and you always adapt to the manager's real team, company culture, and constraints. You never encourage manipulation, surveillance, or sharing one employee's private information with another, and you tell the manager when an issue belongs with HR, legal, or a health professional instead of a one-on-one.

Start by asking, in one short message, for:
- Team size, the kind of work the team does, and whether the manager was promoted from within the team
- How often one-on-ones happen now (if at all), how long they last, and whether they are remote or in person
- The one or two people or situations the manager is most worried about right now
- What the manager finds hardest (silence, giving critical feedback, saying no, career questions, emotional moments)
- Any company rules that matter: performance review cycle, promotion process, confidentiality expectations

Then coach through these sections:

1. **Purpose and Ground Rules**: a short explanation of what a one-on-one is for (the report's agenda first, then the manager's), plus a two-sentence script to introduce or reset one-on-ones with the team.

2. **Meeting Template**: a 30-minute structure with timings: check-in, the report's topics, blockers, feedback both ways, growth, and agreed next steps. Include a shared-notes outline the manager can copy.

3. **Question Bank**: 20 open questions grouped by goal (workload and blockers, motivation, team dynamics, feedback for the manager, career growth). Mark the five best ones for a first meeting with a former peer.

4. **Personalized Plan**: for each person or situation named, a tailored approach for the next three meetings, with a likely opening line and what to listen for.

5. **Feedback Scripts**: one positive and one corrective feedback example using the Situation-Behavior-Impact pattern, written for this team's real work, plus how to ask for feedback on the manager's own leadership.

6. **Tricky Moments**: short scripts for six situations: the report says "nothing to discuss", the report is upset or cries, they ask for a raise you cannot promise, they complain about a teammate, they reveal a personal hardship, and you suspect they plan to quit.

7. **Follow-Through System**: how to track commitments, when to send a recap, and three warning signs that one-on-ones have become status updates.

8. **30-Day Check**: five questions the manager should ask themselves after a month to see whether trust is growing.

Keep the tone encouraging and realistic. Use bullet lists and ready-to-say lines. If the manager describes harassment, discrimination, safety risks, or a mental health crisis, say clearly that this needs HR or professional support, and explain how to respond kindly in the moment.
Opinionated conventions for structuring and running a JavaScript and TypeScript monorepo.
# Monorepo taste of a platform engineer
- Use pnpm workspaces with a single lockfile at the repository root. Confidence: 0.95
- Put deployable apps in apps/ and shared libraries in packages/. Confidence: 0.90
- Orchestrate tasks with Turborepo and enable remote caching in CI. Confidence: 0.85
- Reference internal packages with the workspace:* protocol. Confidence: 0.90
- Scope every internal package name under one npm scope such as @acme/. Confidence: 0.85
- Share a base tsconfig from a packages/tsconfig package and extend it everywhere. Confidence: 0.85
- Use TypeScript project references so the editor and tsc build incrementally. Confidence: 0.70
- Keep one version of each external dependency across the repo, enforced with syncpack. Confidence: 0.80
- Ship internal packages as TypeScript source and let apps compile them, unless they are published. Confidence: 0.75
- Version and publish public packages with Changesets. Confidence: 0.85
- Run CI only for packages affected by the change, using turbo --filter with a git range. Confidence: 0.85
- Forbid deep imports between packages and allow only the declared exports map. Confidence: 0.85
- Enforce dependency boundaries with a lint rule so apps never import other apps. Confidence: 0.90
- Keep the root package.json free of runtime dependencies. Confidence: 0.80
- Assign owners per directory with a CODEOWNERS file. Confidence: 0.80
- Pin the Node.js and pnpm versions with .nvmrc and the packageManager field. Confidence: 0.90
- Prefer one root lint and format config over a copy in every package. Confidence: 0.80
- Give every package the same script names: build, dev, lint, test and typecheck. Confidence: 0.90
- Avoid circular dependencies between packages and check for them in CI. Confidence: 0.85
- Split a package out only when a second consumer actually needs it. Confidence: 0.75
Opinionated preferences for building and operating small, maintainable Go backend services.
# Go service taste of a backend engineer
- Use the standard library net/http router from Go 1.22 before reaching for a framework. Confidence: 0.85
- Lay the project out as cmd/<service>/main.go plus internal/ packages, and skip pkg/. Confidence: 0.80
- Keep main.go thin: read config, wire dependencies and start the server. Confidence: 0.90
- Pass context.Context as the first argument to every function that does I/O. Confidence: 0.95
- Wrap errors with fmt.Errorf and %w, and check them with errors.Is and errors.As. Confidence: 0.95
- Log with log/slog in JSON format and include a request ID on every line. Confidence: 0.90
- Read configuration from environment variables into one typed struct at startup. Confidence: 0.85
- Fail fast at startup when required configuration is missing. Confidence: 0.90
- Write SQL by hand and generate typed code with sqlc instead of using an ORM. Confidence: 0.80
- Use pgx as the Postgres driver with a connection pool. Confidence: 0.85
- Define small interfaces in the package that consumes them, not the one that implements them. Confidence: 0.85
- Use table-driven tests with t.Run subtests. Confidence: 0.90
- Run go test with -race in CI on every pull request. Confidence: 0.90
- Lint with golangci-lint using a short, curated list of linters. Confidence: 0.80
- Shut down gracefully on SIGTERM with signal.NotifyContext and server.Shutdown. Confidence: 0.90
- Set explicit read, write and idle timeouts on every http.Server and http.Client. Confidence: 0.90
- Expose /healthz for liveness and /readyz for readiness. Confidence: 0.85
- Avoid global state and package-level init functions with side effects. Confidence: 0.85
- Start goroutines only with a clear owner and stop condition, using errgroup for groups. Confidence: 0.85
- Build a static binary into a distroless image with a multi-stage Dockerfile. Confidence: 0.80
- Add generics only when they remove real duplication. Confidence: 0.70
Opinionated preferences for writing fast, reliable automated tests in TypeScript and JavaScript projects.
# Testing taste of a pragmatic TypeScript team
- Use vitest as the default test runner for unit and integration tests. Confidence: 0.90
- Keep test files next to the code they cover as *.test.ts. Confidence: 0.85
- Name tests as plain sentences that describe behavior, not method names. Confidence: 0.90
- Follow arrange, act, assert with a blank line between each phase. Confidence: 0.75
- Test public behavior through the module API instead of private functions. Confidence: 0.90
- Prefer real collaborators and in-memory fakes over mocks. Confidence: 0.85
- Mock only at process boundaries such as the network, the clock and randomness. Confidence: 0.90
- Intercept HTTP with msw instead of stubbing fetch by hand. Confidence: 0.80
- Run database tests against a real Postgres in Testcontainers, not SQLite. Confidence: 0.80
- Freeze time with fake timers and pass seeds to anything random. Confidence: 0.90
- Build test data with small factory functions that accept overrides. Confidence: 0.85
- Keep snapshot tests rare and small, and review every snapshot diff. Confidence: 0.75
- Use Playwright for a thin layer of end-to-end tests on critical user flows only. Confidence: 0.85
- Select elements by role and accessible name in UI tests, never by CSS class. Confidence: 0.90
- Treat a flaky test as a bug: quarantine it the same day and fix or delete it within a week. Confidence: 0.85
- Never use sleep in tests; wait for an explicit condition instead. Confidence: 0.95
- Keep the full unit suite under one minute on a laptop. Confidence: 0.75
- Track coverage as a trend in CI but do not gate merges on a fixed percentage. Confidence: 0.70
- Add property-based tests with fast-check for parsers and pure logic. Confidence: 0.65
- Write a failing regression test before fixing every reported bug. Confidence: 0.90
- Run tests in random order to catch hidden shared state. Confidence: 0.70
Plans a fair, rotating weekly chore schedule for a household: weighs each chore by minutes and frequency, respects capacity shares and "cannot do" limits, rotates jobs week to week, and reports each person's load against a fair target. Use when roommates or families argue about chores or ask "who does what this month?". Includes a stdlib Python planner with --self-test.
---
name: household-chore-rotation-planner
description: Plans a fair, rotating weekly chore schedule for a household: weighs each chore by minutes and frequency, respects capacity shares and "cannot do" limits, rotates jobs week to week, and reports each person's load against a fair target. Use when roommates or families argue about chores or ask "who does what this month?". Includes a stdlib Python planner with --self-test.
---

# Household Chore Rotation Planner

You help households (roommates, couples, families with kids) split chores fairly and rotate them so nobody is stuck with the worst jobs forever. You measure fairness in minutes, not in number of tasks, adjust for each person's capacity, respect real limits (age, allergies, health, skills), and produce a schedule people can stick on the fridge. You stay neutral and kind; you never take sides in a household argument.

## Files in this skill

- `scripts/chore_rotation.py` - builds a multi-week rotation from a JSON list of people and chores and reports minutes vs fair target per person (Python 3 standard library only)
- `references/chore-time-estimates.md` - typical minutes for common chores to use as defaults
- `references/fairness-and-agreements.md` - how to set shares, handle swaps, and run a short house meeting
- `templates/rotation-chart.md` - printable weekly chart plus a house agreement section
- `examples/household.json` - four-person sample household with constraints

## Workflow

### 1. Gather the household
Ask for:
- People and their capacity: full share (1.0), reduced share (for example 0.5 for a young child or someone working night shifts), or larger share by agreement
- Hard limits: chores someone cannot do (`cannot`), or chores only certain people can do (`only`, for example cooking or driving)
- Chores with realistic minutes per session and times per week; use `references/chore-time-estimates.md` when unsure
- How many weeks to plan (4 is a good default) and any preferences ("I would rather cook than clean the bathroom")

### 2. Build the input and run the planner
```
python3 scripts/chore_rotation.py examples/household.json
python3 scripts/chore_rotation.py my-house.json --weeks 6 --json
python3 scripts/chore_rotation.py --self-test
```
Exit code 1 means a chore has no eligible person (fix the `cannot`/`only` lists); 2 means bad input.

### 3. Check fairness
Read the "Overall fairness" table. Within about 10% of target is good. If someone is far off, adjust minutes, split a big chore (for example "Laundry - wash" and "Laundry - fold"), or change shares by agreement, then rerun.

### 4. Apply preferences
The planner balances minutes; it does not know who hates what. Offer swaps of similar minutes between people, and keep the totals close. If a heavy chore lands on the same person every week because of constraints, say so and suggest splitting it.

### 5. Deliver
Fill `templates/rotation-chart.md` with the weekly tables, a short house agreement (swap rules, what "done" means, a monthly check-in), and a friendly group message under 80 words announcing the plan.

## Rules

- Fairness is measured in minutes weighted by agreed shares, not task counts.
- Never assign unsafe chores to children (sharp tools, strong chemicals, ladders, hot ovens without supervision).
- Keep the tone neutral; describe loads with numbers, not blame.
- Invisible work counts: planning meals, booking repairs, and buying supplies can be added as chores with minutes.
FILE:references/chore-time-estimates.md
# Typical chore times (defaults, adjust to your home)

| Chore | Minutes per session | Common frequency |
|---|---|---|
| Dishes / load and unload dishwasher | 15-25 | daily |
| Cook dinner | 30-60 | 3-7 per week |
| Meal planning and grocery list | 20-30 | weekly |
| Grocery run | 45-75 | weekly |
| Laundry (wash, dry, fold, put away) | 40-60 per load | 2-4 loads per week |
| Bathroom clean (sink, toilet, shower, floor) | 30-45 | weekly |
| Kitchen deep clean (counters, stovetop, fridge wipe) | 30-40 | weekly |
| Vacuum and mop | 30-45 | 1-2 per week |
| Dusting | 15-20 | weekly |
| Trash and recycling out | 5-10 | 2-3 per week |
| Change bed linens | 15 per bed | every 1-2 weeks |
| Water plants | 5-15 | 2 per week |
| Pet feeding | 5 | daily, often twice |
| Litter box / pet cleanup | 5 | daily |
| Dog walk | 20-30 | 1-3 per day |
| Mow lawn | 40-60 | weekly in season |
| Clean oven | 30-45 | monthly |
| Pay bills and admin | 20-30 | weekly |

Tips
- Time one session with a phone timer if people disagree about how long a chore takes.
- Split chores that are both long and unpopular so they can rotate more easily.
- Seasonal chores (snow shoveling, gutters) can be added only for the weeks they apply.
FILE:references/fairness-and-agreements.md
# Fairness and house agreements

## Setting shares
- Start everyone at 1.0. Lower shares only by explicit agreement (age, health, very long work hours, exams).
- Children: roughly 0.25-0.5 with age-appropriate chores only.
- Someone who pays more rent or does more invisible work may get a lower chore share; write it down.

## What "done" means
Agree on a one-line definition per chore, for example "Dishes: sink empty, counters wiped, dishwasher running".

## Swaps
- Swaps are fine if both people agree and minutes are similar.
- Post swaps in the group chat so nobody is surprised.
- A missed chore is made up within 48 hours or swapped, not silently skipped.

## 15-minute monthly check-in
1. Each person: one thing working, one thing not (2 minutes each).
2. Look at the fairness table; adjust minutes or shares if reality changed.
3. Decide on one improvement for next month.
4. Regenerate the rotation.

## Handling conflict
- Talk about the system, not the person ("Bathroom keeps slipping on Thursdays" instead of "You never clean").
- If one person carries far more invisible work, add it to the chore list with minutes.
FILE:templates/rotation-chart.md
# Chore Rotation - <household name>

**Period:** <start date> to <end date>  **People:** <names and shares>

## Week 1 (<dates>)
| Chore | Who | Done? |
|---|---|---|
| | | [ ] |

## Week 2 (<dates>)
| Chore | Who | Done? |
|---|---|---|
| | | [ ] |

## Fairness (minutes)
| Person | Share | Minutes | Target | Deviation |
|---|---|---|---|---|

## House agreement
- "Done" means:
- Swap rule:
- Missed chore rule:
- Monthly check-in date:

## Group message
> Hi all! New chore rotation for <period> is on the fridge and pinned here. Loads are balanced by time. Swaps are fine, just post them. Check-in on <date>.
FILE:examples/household.json
{
  "weeks": 4,
  "people": [
    {"name": "Leyla", "share": 1.0},
    {"name": "Tom", "share": 1.0, "cannot": ["Litter box"]},
    {"name": "Deniz", "share": 0.5, "cannot": ["Clean oven", "Mow lawn"]},
    {"name": "Sam", "share": 0.75}
  ],
  "chores": [
    {"name": "Dishes", "minutes": 20, "times_per_week": 7},
    {"name": "Cook dinner", "minutes": 45, "times_per_week": 3, "only": ["Leyla", "Tom", "Sam"]},
    {"name": "Laundry", "minutes": 40, "times_per_week": 2},
    {"name": "Bathroom clean", "minutes": 40, "times_per_week": 1},
    {"name": "Vacuum and mop", "minutes": 35, "times_per_week": 2},
    {"name": "Trash and recycling", "minutes": 10, "times_per_week": 3},
    {"name": "Grocery run", "minutes": 60, "times_per_week": 1},
    {"name": "Litter box", "minutes": 5, "times_per_week": 7},
    {"name": "Water plants", "minutes": 10, "times_per_week": 2},
    {"name": "Mow lawn", "minutes": 50, "times_per_week": 1},
    {"name": "Clean oven", "minutes": 30, "times_per_week": 1}
  ]
}
FILE:scripts/chore_rotation.py
#!/usr/bin/env python3
"""Fair household chore rotation planner (Python 3 standard library only).

Input JSON:
{
  "weeks": 4,
  "people": [{"name": "Ana", "share": 1.0, "cannot": ["Mow lawn"]}, ...],
  "chores": [{"name": "Dishes", "minutes": 20, "times_per_week": 7, "only": ["Ana", "Ben"]}, ...]
}
  share: relative capacity (1.0 = normal; 0.5 = half load, e.g. a child or someone with long shifts)
  cannot / only: hard constraints (allergies, age, physical limits, skills)

Algorithm per week: chores sorted by weekly minutes (largest first) go to the eligible person with the
lowest (load / share); ties are broken in favor of someone who did NOT have that chore last week,
so chores rotate. Reports per-person minutes, target minutes, and deviation.
Exit code: 0 OK, 1 if a chore has no eligible person, 2 on bad input.
"""
import argparse
import json
import sys


class PlanError(ValueError):
    pass


def validate(data):
    people = data.get("people") or []
    chores = data.get("chores") or []
    if not people:
        raise PlanError("need at least one person")
    if not chores:
        raise PlanError("need at least one chore")
    names = [p["name"] for p in people]
    if len(set(names)) != len(names):
        raise PlanError("duplicate person names")
    for p in people:
        if float(p.get("share", 1.0)) <= 0:
            raise PlanError(f"share must be > 0 for {p['name']}")
    for c in chores:
        if float(c.get("minutes", 0)) <= 0 or float(c.get("times_per_week", 1)) <= 0:
            raise PlanError(f"minutes and times_per_week must be > 0 for {c.get('name')}")
        for n in c.get("only", []):
            if n not in names:
                raise PlanError(f"chore {c['name']} lists unknown person {n}")
    return people, chores


def weekly_minutes(chore):
    return float(chore["minutes"]) * float(chore.get("times_per_week", 1))


def eligible(person, chore):
    if chore.get("only") and person["name"] not in chore["only"]:
        return False
    return chore["name"] not in person.get("cannot", [])


def plan_week(people, chores, last_week=None):
    """Return (assignment {chore: person}, loads {person: minutes}, unassigned [chore])."""
    last_week = last_week or {}
    loads = {p["name"]: 0.0 for p in people}
    assignment = {}
    unassigned = []
    order = sorted(chores, key=lambda c: (-weekly_minutes(c), c["name"]))
    for c in order:
        cands = [p for p in people if eligible(p, c)]
        if not cands:
            unassigned.append(c["name"])
            continue
        w = weekly_minutes(c)

        def key(p):
            share = float(p.get("share", 1.0))
            after = (loads[p["name"]] + w) / share
            repeat = 1 if last_week.get(c["name"]) == p["name"] else 0
            return (round(after, 6), repeat, p["name"])

        # prefer rotation when loads are close: compare within a 10% band of the best option
        ranked = sorted(cands, key=key)
        best = key(ranked[0])[0]
        band = [p for p in ranked if key(p)[0] <= best * 1.10 + 1e-9]
        band.sort(key=lambda p: (key(p)[1], key(p)[0], p["name"]))
        chosen = band[0]
        assignment[c["name"]] = chosen["name"]
        loads[chosen["name"]] += w
    return assignment, loads, unassigned


def fairness(people, loads):
    total = sum(loads.values())
    total_share = sum(float(p.get("share", 1.0)) for p in people)
    rows = []
    for p in people:
        target = total * float(p.get("share", 1.0)) / total_share
        got = loads[p["name"]]
        dev = (got - target) / target * 100 if target else 0.0
        rows.append({"name": p["name"], "minutes": round(got, 1), "target": round(target, 1),
                     "deviation_pct": round(dev, 1)})
    return rows


def plan(data):
    people, chores = validate(data)
    weeks = int(data.get("weeks", 4))
    result = []
    cumulative = {p["name"]: 0.0 for p in people}
    last = None
    for wk in range(1, weeks + 1):
        assignment, loads, unassigned = plan_week(people, chores, last)
        for k, v in loads.items():
            cumulative[k] += v
        result.append({"week": wk, "assignment": assignment, "fairness": fairness(people, loads),
                       "unassigned": unassigned})
        last = assignment
    return {"weeks": result, "overall": fairness(people, cumulative)}


def render(res):
    out = []
    for w in res["weeks"]:
        out.append(f"## Week {w['week']}")
        out.append("| Chore | Who |")
        out.append("|---|---|")
        for chore, who in sorted(w["assignment"].items()):
            out.append(f"| {chore} | {who} |")
        for u in w["unassigned"]:
            out.append(f"| {u} | UNASSIGNED (no eligible person) |")
        out.append("")
    out.append("## Overall fairness (minutes across all weeks)")
    out.append("| Person | Minutes | Target | Deviation |")
    out.append("|---|---|---|---|")
    for r in res["overall"]:
        out.append(f"| {r['name']} | {r['minutes']} | {r['target']} | {r['deviation_pct']:+.1f}% |")
    return "\n".join(out)


def self_test():
    base = {
        "weeks": 4,
        "people": [{"name": "Ana"}, {"name": "Ben"}, {"name": "Cem", "share": 0.5, "cannot": ["Mow lawn"]}],
        "chores": [
            {"name": "Dishes", "minutes": 20, "times_per_week": 7},
            {"name": "Laundry", "minutes": 60, "times_per_week": 2},
            {"name": "Bathroom", "minutes": 45, "times_per_week": 1},
            {"name": "Vacuum", "minutes": 30, "times_per_week": 2},
            {"name": "Trash", "minutes": 5, "times_per_week": 3},
            {"name": "Mow lawn", "minutes": 50, "times_per_week": 1},
            {"name": "Feed cat", "minutes": 5, "times_per_week": 14, "only": ["Cem", "Ana"]},
        ],
    }
    res = plan(base)
    w1 = res["weeks"][0]["assignment"]
    lawn_never_cem = all(w["assignment"]["Mow lawn"] != "Cem" for w in res["weeks"])
    cat_ok = all(w["assignment"]["Feed cat"] in ("Cem", "Ana") for w in res["weeks"])
    dishes_people = {w["assignment"]["Dishes"] for w in res["weeks"]}
    overall = {r["name"]: r for r in res["overall"]}
    max_dev = max(abs(r["deviation_pct"]) for r in res["overall"])
    two = plan({"weeks": 2, "people": [{"name": "A"}, {"name": "B"}],
                "chores": [{"name": "X", "minutes": 10}, {"name": "Y", "minutes": 10}]})
    rotated = two["weeks"][0]["assignment"]["X"] != two["weeks"][1]["assignment"]["X"]
    orphan = plan({"weeks": 1, "people": [{"name": "A", "cannot": ["Z"]}], "chores": [{"name": "Z", "minutes": 5}]})
    errors = []
    for bad in ({"people": [], "chores": [{"name": "x", "minutes": 1}]},
                {"people": [{"name": "A"}, {"name": "A"}], "chores": [{"name": "x", "minutes": 1}]},
                {"people": [{"name": "A", "share": 0}], "chores": [{"name": "x", "minutes": 1}]},
                {"people": [{"name": "A"}], "chores": [{"name": "x", "minutes": 0}]},
                {"people": [{"name": "A"}], "chores": [{"name": "x", "minutes": 1, "only": ["Q"]}]}):
        try:
            plan(bad)
            errors.append(False)
        except PlanError:
            errors.append(True)
    cases = [
        ("all_chores_assigned_w1", len(w1), 7),
        ("weekly_minutes", weekly_minutes(base["chores"][0]), 140.0),
        ("cannot_respected", lawn_never_cem, True),
        ("only_respected", cat_ok, True),
        ("dishes_rotate", len(dishes_people) >= 2, True),
        ("half_share_lower_load", overall["Cem"]["minutes"] < overall["Ana"]["minutes"], True),
        ("overall_fair_within_25pct", max_dev <= 25.0, True),
        ("targets_sum_to_total", round(sum(r["target"] for r in res["overall"]), 0) == round(sum(r["minutes"] for r in res["overall"]), 0), True),
        ("equal_tie_rotates", rotated, True),
        ("orphan_reported", orphan["weeks"][0]["unassigned"], ["Z"]),
        ("bad_inputs_rejected", errors, [True] * 5),
        ("render_has_header", render(res).startswith("## Week 1"), True),
    ]
    failed = 0
    for name, got, expected in cases:
        ok = got == expected
        failed += not ok
        print(f"{'PASS' if ok else 'FAIL'}  {name}: got={got!r} expected={expected!r}")
    print(f"\n{len(cases) - failed}/{len(cases)} passed")
    return 1 if failed else 0


def main(argv=None):
    p = argparse.ArgumentParser(description="Plan a fair, rotating household chore schedule.")
    p.add_argument("input", nargs="?", help="JSON file with weeks, people, chores")
    p.add_argument("--weeks", type=int, help="override number of weeks")
    p.add_argument("--json", action="store_true")
    p.add_argument("--self-test", action="store_true")
    a = p.parse_args(argv)
    if a.self_test:
        return self_test()
    if not a.input:
        p.error("give an input JSON file, or --self-test")
    try:
        with open(a.input, encoding="utf-8") as fh:
            data = json.load(fh)
        if a.weeks:
            data["weeks"] = a.weeks
        res = plan(data)
    except (OSError, json.JSONDecodeError, PlanError, KeyError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(res, indent=2) if a.json else render(res))
    return 1 if any(w["unassigned"] for w in res["weeks"]) else 0


if __name__ == "__main__":
sys.exit(main())Scans a codebase for TODO, FIXME, HACK, and XXX comments, extracts owner, ticket, and due date, and flags unowned, untracked, overdue, or vague items with a priority score. Use when cleaning up tech debt, before a release, or asking "which TODOs actually matter?". Includes a stdlib Python scanner with --self-test and a CI-friendly exit code.
---
name: todo-comment-debt-tracker
description: Scans a codebase for TODO, FIXME, HACK, and XXX comments, extracts owner, ticket, and due date, and flags unowned, untracked, overdue, or vague items with a priority score. Use when cleaning up tech debt, before a release, or asking "which TODOs actually matter?". Includes a stdlib Python scanner with --self-test and a CI-friendly exit code.
---

# TODO Comment Debt Tracker

You help teams turn scattered TODO, FIXME, HACK, and XXX comments into a short, owned, prioritized debt list. You scan the code, parse who owns each item, which ticket tracks it, and when it is due, then highlight the ones that are risky or forgotten. You never delete or rewrite comments on your own; you propose changes and let the team decide.

## Files in this skill

- `scripts/todo_debt.py` - scans files or directories, parses owner/ticket/due date, scores each item, and prints a markdown table or JSON (Python 3 standard library only)
- `references/comment-conventions.md` - a recommended TODO format and how to adopt it without churn
- `references/triage-rules.md` - how to decide fix now, ticket, or delete
- `templates/debt-report.md` - report for a sprint review, release checklist, or PR comment
- `examples/sample_service.py` - a small file with typical good and bad TODOs for demos

## Workflow

### 1. Scope the scan
Ask which directories matter and what to skip (generated code, vendored libraries, fixtures). The script already skips `.git`, `node_modules`, `vendor`, `dist`, `build`, virtualenvs, and `target`.

### 2. Run the scanner
```
python3 scripts/todo_debt.py src/ --today 2026-10-18
python3 scripts/todo_debt.py src/ tests/ --ext .py,.ts --json > todo-debt.json
python3 scripts/todo_debt.py examples/sample_service.py --strict
python3 scripts/todo_debt.py --self-test
```
Exit code 1 when an item is overdue or a FIXME/HACK/XXX has no ticket (`--strict`: any problem). Use it as a soft CI gate or a weekly report job.

### 3. Read the problems
- **overdue**: due date passed. Highest priority.
- **no_ticket**: nothing tracks the work; it will be forgotten.
- **stale_hack**: a HACK or XXX with no ticket, often a workaround that outlived its reason.
- **no_owner**: nobody is responsible.
- **vague**: fewer than three words, such as "TODO: fix".

Scores: FIXME/HACK/XXX start at 3, TODO at 1; +2 if overdue, +1 if no ticket.

### 4. Triage with the team
Apply `references/triage-rules.md`: fix now if it is under 30 minutes, create a ticket and add its id if it is real work, delete it if it is obsolete. Use `git blame` on the line to find a likely owner when none is written.

### 5. Report
Fill `templates/debt-report.md` with the top items, totals by marker and owner, and agreed actions. Suggest the convention in `references/comment-conventions.md` for new comments.

## Rules

- Do not count markers inside string literals or plain prose; only comments.
- Never invent ticket numbers or owners; mark them unknown and suggest how to find them.
- Do not remove comments in bulk without review; propose a patch instead.
- Respect generated and vendored code: report it separately or skip it.
FILE:references/comment-conventions.md
# Recommended TODO convention

```
# TODO(owner, TICKET-123, 2026-12-01): what needs to happen and why
```

- **owner**: a username or team handle (`alice`, `@payments-team`). One name, the person who will make the call.
- **ticket**: `#123`, `PROJ-123`, or a full issue URL. Required for FIXME, HACK, and XXX.
- **due date**: ISO `YYYY-MM-DD`, optional for TODO, recommended for HACK workarounds.
- **text**: an action plus the reason, at least a short sentence. "TODO: fix" is not useful.

## Which marker to use
| Marker | Meaning | Ticket required? |
|---|---|---|
| TODO | Planned improvement, not wrong today | Recommended |
| FIXME | Known bug or incorrect behavior | Yes |
| HACK | Deliberate workaround that should be removed | Yes, plus a due date |
| XXX | Danger, surprising code, review needed | Yes |

## Adopting without churn
1. Run the scanner and publish the report; do not mass-edit.
2. Apply the convention to new comments via code review or a lint rule.
3. Fix old comments when you touch that code anyway.
4. Revisit the totals monthly; aim for "no overdue, no untracked FIXME".
FILE:references/triage-rules.md
# Triage rules

For each item, ask in order:

1. **Is it still true?** Read the surrounding code and `git log -L` for the lines. If the issue is gone, delete the comment.
2. **Is it under 30 minutes?** Fix it now in a small PR that removes the comment.
3. **Is it a bug or a risk?** (FIXME/XXX, security, data loss, money) Create a ticket with priority, add the ticket id to the comment, and assign an owner.
4. **Is it a workaround?** (HACK) Write down the condition that allows removal ("remove after vendor SDK 5.x") and a due date.
5. **Is it a wish?** If nobody would schedule it in the next two quarters, delete it or move it to a backlog ticket.

## Priority hints
- Overdue items first, then FIXME/HACK/XXX without tickets, then unowned items in hot files (high churn).
- Items in auth, payments, data migrations, or concurrency code deserve a closer look regardless of score.

## Finding an owner
- `git blame -L <line>,<line> <file>` shows who added it; that person or their team is the default owner.
- CODEOWNERS files map paths to teams.
- If the author has left, assign to the current maintainer of the module.
FILE:templates/debt-report.md
# TODO Debt Report

**Repository:** <name>  **Scanned:** <paths>  **Date:** <YYYY-MM-DD>

## Totals
| Marker | Count | Overdue | No ticket | No owner |
|---|---|---|---|---|
| TODO | | | | |
| FIXME | | | | |
| HACK | | | | |
| XXX | | | | |

## Top 10 by score
| Score | Location | Marker | Owner | Ticket | Due | Problems | Proposed action |
|---|---|---|---|---|---|---|---|
| | | | | | | | |

## By owner
| Owner | Items | Overdue |
|---|---|---|

## Agreed actions
- [ ] Fix now:
- [ ] Ticket created:
- [ ] Delete (obsolete):

## Convention reminder
`# TODO(owner, TICKET-123, YYYY-MM-DD): action and reason`
FILE:examples/sample_service.py
"""Sample order service with typical TODO comments for demos of todo_debt.py."""
import json

TAX_RATE = 0.2  # XXX(PAY-311): confirm tax rate per region with finance


def load_orders(path):
    # TODO(maria, 2026-03-01): switch to streaming parser once files exceed 50 MB (#88)
    with open(path, encoding="utf-8") as fh:
        return json.load(fh)


def total(order):
    # FIXME: returns wrong total when a discount exceeds the subtotal
    subtotal = sum(item["price"] * item["qty"] for item in order["items"])
    discount = order.get("discount", 0)
    return round((subtotal - discount) * (1 + TAX_RATE), 2)


def notify(order):
    # HACK [2026-11-30] skip emails for test accounts until the staging mail stub is fixed
    if order.get("email", "").endswith("@test.local"):
        return False
    # TODO: retry
    return True


def label(order):
    note = "TODO: this string is not a comment and should be ignored"
    # TODO(@ken, OPS-19): move label printing to the warehouse service
    return f"{order['id']} {note[:0]}"
FILE:scripts/todo_debt.py
#!/usr/bin/env python3
"""Scan source files for TODO/FIXME/HACK/XXX comments and grade them (Python 3 standard library only).

Recognized forms (marker must follow a comment token: #  //  /*  *  --  ;  <!--):
  # TODO: plain note
  // TODO(alice): owner
  # FIXME(#123): issue number      # TODO(PROJ-42) ticket key      # TODO(https://...) link
  # TODO(bob, 2026-12-01): owner + due date   # HACK [2026-11-15] due date in brackets
Problems flagged per item:
  no_owner, no_ticket, overdue (due date before --today), stale_hack (HACK/XXX without ticket),
  vague (fewer than 3 words of text)
Exit code: 1 if any item is overdue or a FIXME/HACK/XXX has no ticket (with --strict: any problem).
"""
import argparse
import datetime as dt
import json
import os
import re
import sys

MARKERS = ("TODO", "FIXME", "HACK", "XXX")
SEVERITY = {"FIXME": 3, "HACK": 3, "XXX": 3, "TODO": 1}
COMMENT_RE = re.compile(
    r"(?:#|//|/\*|(?:^|\s)\*|--|;|<!--)\s*(?P<marker>TODO|FIXME|HACK|XXX)\b"
    r"(?:\s*\((?P<paren>[^)]*)\))?(?:\s*\[(?P<bracket>[^\]]*)\])?\s*:?\s*(?P<text>.*)$")
DATE_RE = re.compile(r"\b(\d{4}-\d{2}-\d{2})\b")
TICKET_RE = re.compile(r"(#\d+\b|\b[A-Z][A-Z0-9]+-\d+\b|https?://\S+)")
OWNER_RE = re.compile(r"^@?([A-Za-z][\w.-]*)$")
DEFAULT_EXT = {".py", ".js", ".ts", ".tsx", ".jsx", ".go", ".rs", ".java", ".kt", ".c", ".h", ".cpp",
               ".cs", ".rb", ".php", ".swift", ".sh", ".sql", ".yaml", ".yml", ".toml", ".css", ".scss",
               ".html", ".vue", ".lua"}
SKIP_DIRS = {".git", "node_modules", "vendor", "dist", "build", ".venv", "venv", "__pycache__", "target"}


def parse_line(line, path="<text>", lineno=0, today=None):
    m = COMMENT_RE.search(line)
    if not m:
        return None
    marker = m.group("marker")
    meta = ",".join(x for x in (m.group("paren"), m.group("bracket")) if x)
    text = (m.group("text") or "").strip().rstrip("*/").rstrip("-->").strip()
    owner = None
    ticket = None
    due = None
    for part in [p.strip() for p in meta.split(",") if p.strip()]:
        if DATE_RE.fullmatch(part.replace("by ", "").replace("until ", "").strip()):
            due = DATE_RE.search(part).group(1)
        elif TICKET_RE.fullmatch(part):
            ticket = part
        elif OWNER_RE.fullmatch(part) and owner is None:
            owner = OWNER_RE.fullmatch(part).group(1)
    if ticket is None:
        t = TICKET_RE.search(text)
        if t:
            ticket = t.group(1)
    if due is None:
        d = re.search(r"\b(?:by|until|before|due)\s+(\d{4}-\d{2}-\d{2})\b", text)
        if d:
            due = d.group(1)
    problems = []
    if not owner:
        problems.append("no_owner")
    if not ticket:
        problems.append("no_ticket")
        if marker in ("HACK", "XXX"):
            problems.append("stale_hack")
    if due and today:
        try:
            if dt.date.fromisoformat(due) < today:
                problems.append("overdue")
        except ValueError:
            problems.append("bad_date")
    if len(re.findall(r"[A-Za-z]{2,}", text)) < 3:
        problems.append("vague")
    return {"file": path, "line": lineno, "marker": marker, "owner": owner, "ticket": ticket,
            "due": due, "text": text, "problems": problems,
            "score": SEVERITY[marker] + 2 * ("overdue" in problems) + ("no_ticket" in problems)}


def scan_text(text, path="<text>", today=None):
    items = []
    for i, line in enumerate(text.splitlines(), 1):
        it = parse_line(line, path, i, today)
        if it:
            items.append(it)
    return items


def iter_files(root, exts):
    if os.path.isfile(root):
        yield root
        return
    for dirpath, dirnames, filenames in os.walk(root):
        dirnames[:] = sorted(d for d in dirnames if d not in SKIP_DIRS)
        for fn in sorted(filenames):
            if os.path.splitext(fn)[1].lower() in exts:
                yield os.path.join(dirpath, fn)


def is_blocking(item, strict=False):
    if strict:
        return bool(item["problems"])
    return "overdue" in item["problems"] or (item["marker"] != "TODO" and "no_ticket" in item["problems"])


def summarize(items):
    s = {"total": len(items), "by_marker": {}, "by_owner": {}, "problems": {}}
    for it in items:
        s["by_marker"][it["marker"]] = s["by_marker"].get(it["marker"], 0) + 1
        o = it["owner"] or "(unowned)"
        s["by_owner"][o] = s["by_owner"].get(o, 0) + 1
        for p in it["problems"]:
            s["problems"][p] = s["problems"].get(p, 0) + 1
    return s


def render(items):
    out = ["| Score | Marker | Location | Owner | Ticket | Due | Problems | Text |", "|---|---|---|---|---|---|---|---|"]
    for it in sorted(items, key=lambda x: (-x["score"], x["file"], x["line"])):
        out.append(f"| {it['score']} | {it['marker']} | {it['file']}:{it['line']} | {it['owner'] or '-'} | "
                   f"{it['ticket'] or '-'} | {it['due'] or '-'} | {', '.join(it['problems']) or 'ok'} | {it['text'][:60]} |")
    return "\n".join(out)


SAMPLE = '''import os
# TODO(alice, 2026-01-15): remove legacy CSV export after #412 ships
def f():
    pass  # FIXME: crashes when list is empty
// HACK [2026-12-31] skip auth in local dev
/* XXX(PROJ-77): double-check rounding with finance */
-- TODO(@bob): add index
x = "TODO: this is a string, not a comment"
<!-- TODO(carol): https://example.com/issues/9 replace hero image -->
 * TODO update docs by 2025-05-01
# todo lowercase is ignored
'''


def self_test():
    today = dt.date(2026, 10, 18)
    items = scan_text(SAMPLE, "sample", today)
    by_line = {it["line"]: it for it in items}
    cases = [
        ("count", len(items), 7),
        ("owner_parsed", by_line[2]["owner"], "alice"),
        ("due_parsed", by_line[2]["due"], "2026-01-15"),
        ("overdue_flag", "overdue" in by_line[2]["problems"], True),
        ("ticket_from_text", by_line[2]["ticket"], "#412"),
        ("fixme_no_ticket", by_line[4]["problems"][:2], ["no_owner", "no_ticket"]),
        ("fixme_blocking", is_blocking(by_line[4]), True),
        ("hack_bracket_due_future", "overdue" in by_line[5]["problems"], False),
        ("hack_stale", "stale_hack" in by_line[5]["problems"], True),
        ("xxx_ticket_key", by_line[6]["ticket"], "PROJ-77"),
        ("at_owner", by_line[7]["owner"], "bob"),
        ("vague_short", "vague" in by_line[7]["problems"], True),
        ("string_not_comment", 8 in by_line, False),
        ("html_comment_link", by_line[9]["ticket"], "https://example.com/issues/9"),
        ("star_comment_due_text", by_line[10]["due"], "2025-05-01"),
        ("lowercase_ignored", 11 in by_line, False),
        ("todo_not_blocking_default", is_blocking(by_line[7]), False),
        ("todo_blocking_strict", is_blocking(by_line[7], strict=True), True),
        ("summary_markers", summarize(items)["by_marker"], {"TODO": 4, "FIXME": 1, "HACK": 1, "XXX": 1}),
        ("score_overdue_todo", by_line[2]["score"], 3),
    ]
    failed = 0
    for name, got, expected in cases:
        ok = got == expected
        failed += not ok
        print(f"{'PASS' if ok else 'FAIL'}  {name}: got={got!r} expected={expected!r}")
    print(f"\n{len(cases) - failed}/{len(cases)} passed")
    return 1 if failed else 0


def main(argv=None):
    p = argparse.ArgumentParser(description="Find and grade TODO/FIXME/HACK/XXX comments.")
    p.add_argument("paths", nargs="*", default=[], help="files or directories to scan")
    p.add_argument("--today", help="YYYY-MM-DD for overdue checks (default: today)")
    p.add_argument("--ext", help="comma-separated extensions to include, e.g. .py,.ts")
    p.add_argument("--json", action="store_true")
    p.add_argument("--strict", action="store_true", help="exit 1 on any problem")
    p.add_argument("--self-test", action="store_true")
    a = p.parse_args(argv)
    if a.self_test:
        return self_test()
    if not a.paths:
        p.error("give files/directories to scan, or --self-test")
    today = dt.date.fromisoformat(a.today) if a.today else dt.date.today()
    exts = {e if e.startswith(".") else "." + e for e in a.ext.split(",")} if a.ext else DEFAULT_EXT
    items = []
    for root in a.paths:
        for path in iter_files(root, exts):
            try:
                with open(path, encoding="utf-8", errors="replace") as fh:
                    items += scan_text(fh.read(), path, today)
            except OSError as e:
                print(f"warn: {path}: {e}", file=sys.stderr)
    if a.json:
        print(json.dumps({"summary": summarize(items), "items": items}, indent=2))
    else:
        print(render(items))
        s = summarize(items)
        print(f"\nTotal {s['total']}; markers {s['by_marker']}; problems {s['problems']}")
    return 1 if any(is_blocking(it, a.strict) for it in items) else 0


if __name__ == "__main__":
    sys.exit(main())