A short starter prompt for a bright, friendly product film. Claude builds it as an animation and you export it as MP4. Based on the Nimbo video on DrillUp. Watch the finished Nimbo video and get the full prompt (16,865 words): https://drillup.io/en/p/nimbo
Build a 14-second motion design product film in 16:9 (1920x1080, 30 fps) for my app name, which what_it_does.
Build it as one HTML page with one animation timeline, so I can export it as an MP4.

Look: light grey-green background with a soft grid, white cards with thin borders, one brand colour hex, one clean sans-serif font.

The text builds word by word: "hook_question" / "name step_1, step_2, and step_3 for you." / "result."
Scene 1: the hook question, big and centred.
Scenes 2 to 4: one card shows each step. The card from one step becomes the object of the next step.
Scene 5: the result with a small "done" stamp.
Scene 6: logo, name and "tagline".

Rules: the camera never stands still. Every move is eased. Key words are in the brand colour, the rest stays dark.
A starter prompt for a friendly vertical app film. Claude builds it as an animation and you export it as MP4. Based on the Sharlo video on DrillUp, an app that splits restaurant bills between friends. See the finished Sharlo video and the full prompt (16,111 words): https://drillup.io/en/p/sharlo
Build a 10-second vertical motion design ad (1080x1920, 30 fps) for my app app_name, which what_it_does_in_one_sentence.
Build it as one HTML page with a single animation timeline, so I can export it as an MP4.

Look: very clean and friendly, bright background, rounded cards, one accent colour hex, large type that is easy to read on a phone.

Scene 1 (0 to 2.4 s): the hook "[HOOK, max 6 words]" builds word by word in the upper third. Each word rises with a soft overshoot.
Scene 2 (2.4 to 5.5 s): a phone screen slides up. It shows the main step of the app: [MAIN STEP, e.g. a receipt is read and split into names].
Scene 3 (5.5 to 8 s): the result pops in as small cards, one after another: result.
Scene 4 (8 to 10 s): app icon, name and "call_to_action".

Rules: keep all text inside the safe area (no text in the top 250 px or bottom 350 px). The camera keeps moving gently. One object carries the story from start to end.
Finds fair meeting times for distributed teams. Takes each participant's IANA time zone, working days and hours, how far they will stretch, holidays and blocked time, then lists every slot in a date range in each person's local time, handles daylight-saving switches that happen on different weekends, and picks a rotating series so the same people do not always take the early or late call. Includes a stdlib Python zoneinfo script with --self-test.
---
name: time-zone-meeting-slot-finder
description: Finds fair meeting times for distributed teams. Takes each participant's IANA time zone, working days and hours, how far they will stretch, holidays and blocked time, then lists every slot in a date range in each person's local time, handles daylight-saving switches that happen on different weekends, and picks a rotating series so the same people do not always take the early or late call. Includes a stdlib Python zoneinfo script with --self-test.
---

# Time Zone Meeting Slot Finder

You help distributed teams pick meeting times that are possible for everyone required and fair over time. You work in each person's own local time on the actual dates (never with "LA is 9 hours behind Berlin" rules of thumb, which are wrong for weeks every spring and autumn), show the trade-offs openly, and rotate the inconvenient slots instead of always putting them on the same people.

## Files in this skill

- `scripts/slot_finder.py` - reads a team CSV and optional blocked-time CSV, evaluates every slot on a grid over the date range in each participant's local time (Python zoneinfo), ranks slots by who is missing and how much stretch they need, reports DST changes in the range, and can pick a fair rotating series (Python 3.9+ standard library only)
- `references/dst-and-time-zone-pitfalls.md` - DST dates by region, zones that do not switch, half-hour zones, weekends that are not Sat-Sun, abbreviations to avoid, and how calendar invites behave across a switch
- `references/fairness-and-rotation.md` - the pain-point model, how the rotation chooses, when to split a meeting or go async instead, and how to explain the choice to the team
- `templates/slot-proposal.md` - the proposal to send to the team
- `examples/team.csv` - five people in Los Angeles, New York, Berlin, Istanbul and Kolkata (one optional)
- `examples/blocked.csv` - a public holiday, a dentist appointment, a board review and a day of leave

## Workflow

### 1. Collect the facts
For each participant: name, IANA zone (city based, e.g. `America/Los_Angeles`, never "PST"), working days (Mon-Fri, or Sun-Thu in much of the Middle East), working hours, how many hours they are willing to start earlier or finish later, and whether they are required. Also the date range, meeting length, how often it repeats, known holidays and blocked times (in that person's local time). Ask rather than guess zones from a city that has several (e.g. a "Mexico" team member).

### 2. Run the finder
```
python3 scripts/slot_finder.py --team examples/team.csv --blocked examples/blocked.csv --start 2026-10-26 --end 2026-11-20 --days Tue,Wed,Thu --series 4
python3 scripts/slot_finder.py --team team.csv --start 2026-11-02 --end 2026-11-06 --duration 30 --step 15 --top 5
python3 scripts/slot_finder.py --team team.csv --start 2026-11-02 --end 2026-11-27 --series 8 --every day --ref-zone Europe/Berlin --json
python3 scripts/slot_finder.py --self-test
```
Dates (`--start`, `--end`, `--days`) are read in `--ref-zone` (default UTC). Exit 0 means slots were found, 1 means no slot works for every required person, 2 means bad input (unknown zone, bad time, missing column).

### 3. Read the result
- **DST changes in range** come first: if any zone switches inside the range, the same UTC time lands an hour earlier or later for those people afterwards. Propose slots per period, not one UTC time for the whole range.
- **Best slots** are ranked by: optional people missing, then the worst single person's stretch, then total stretch.
- **Rotating series** picks one meeting per week (or per day) to keep the worst cumulative inconvenience as low as possible, then spreads it. The summary shows how often each person met in hours, stretched or missed.
- If there is no slot, say why (who blocks whom) and offer options: more stretch from volunteers, a shorter meeting, making someone optional, two regional meetings, or async updates.

### 4. Deliver
Fill `templates/slot-proposal.md`: the recommendation with every person's local time and weekday, the DST note, the rotation table, alternatives, and the open questions. Send invites from a calendar with a real zone (the organizer's IANA zone), not "UTC" unless the team agreed, and say which zone anchors the series.

## Example result
Five people, 2026-10-26 to 2026-11-20, Tue-Thu, 60 minutes, series of 4 weekly meetings. Europe left summer time on 25 October and the US on 1 November, so in the week of 26 October New York is only 5 hours behind Berlin instead of 6. Week 1: 13:30 UTC (Ana 06:30 in Los Angeles, a stretch; Priya 19:00 in Kolkata, a stretch; everyone else in hours). After the US change, two weeks at 16:00 UTC (Ana 08:00 in hours, Eva 17:00-18:00 stretch, Bilal 19:00-20:00 stretch) and one at 14:30 UTC (Ana stretches again). Bilal is blocked on 29 October (Republic Day). Priya (optional, +05:30) can join only before the US change; the proposal adds a recorded summary for her and suggests an Asia-friendly slot once a month.

## Rules

- Always use IANA zone names and compute local times per date; never apply fixed offsets across a DST boundary.
- Show every participant's local time and weekday for each proposal, since the date can differ (Kolkata evening, Los Angeles morning).
- Nobody is scheduled outside the stretch they agreed to; ask before assuming someone will take a 06:00 or 22:00 call.
- Rotate inconvenience and show the tally; if one person always loses, say so and suggest a structural fix (split, async, rotate the meeting owner).
- Respect weekends, public holidays and blocked time in the person's own calendar and zone.
- Keep the recommendation short; put the full table in an appendix.
FILE:references/dst-and-time-zone-pitfalls.md
# DST and time zone pitfalls

## Use IANA zone names
- `America/New_York`, `Europe/Berlin`, `Asia/Kolkata`, `Australia/Sydney`. They carry the full history and future rules of that region.
- Avoid abbreviations: "EST", "CST", "IST" and "BST" are ambiguous (IST = India, Ireland or Israel; CST = US Central, China or Cuba) and the zoneinfo entries named EST or MST are fixed offsets with no DST. The script warns on names without a "/".
- Avoid fixed offsets like UTC+1 for people: offsets change twice a year in many places.
- Pick the city that shares the person's rules: Arizona (`America/Phoenix`) has no DST; most of Mexico dropped DST in 2022; `America/Sao_Paulo` dropped DST in 2019.
- Keep the zone database current (`tzdata`); governments change rules with a few weeks' notice.

## DST dates (2026, check each year)
| Region | Summer time starts | Ends | Note |
|---|---|---|---|
| US and Canada (most) | 2nd Sunday of March (2026-03-08) | 1st Sunday of November (2026-11-01) | local 02:00 |
| EU, UK | last Sunday of March (2026-03-29) | last Sunday of October (2026-10-25) | 01:00 UTC, all at once |
| Australia (south-east), New Zealand | first Sunday of October / last Sunday of September | first Sunday of April | southern hemisphere: opposite season |
| No DST | Turkey (UTC+3), India (+05:30), China, Japan, Singapore, UAE, most of Africa, Arizona | | |

So there are two "gap" periods each year when the US-Europe difference is one hour smaller than usual: about 3 weeks in March and 1 week at the end of October / start of November. Recurring meetings anchored in one region move by an hour for the other during those weeks.

## Offsets that are not whole hours
- India +05:30, Iran +03:30, Nepal +05:45, Newfoundland -03:30 (-02:30 in summer), South Australia +09:30/+10:30, Chatham Islands +12:45. A grid on the hour in UTC lands on :30 or :45 for these people; the script evaluates in 5-minute chunks so these are exact.

## Weekends and working days
- Sun-Thu working weeks: e.g. Israel; Fri-Sat weekends in several Gulf countries, while the UAE moved to Mon-Fri (with a half Friday) in 2022. Ask each person.
- Public holidays differ per country and per region (Bavaria vs Berlin, US states). Add them to the blocked file in local dates.
- A Monday 08:00 slot in Los Angeles is Monday evening in India but already Tuesday morning in Sydney or Auckland. Always show the weekday per person.

## DST on the switch day itself
- Spring forward: local times between 02:00 and 03:00 (US) do not exist; autumn back: 01:00-02:00 happens twice. Avoid scheduling in those hours on switch days; the script works on UTC instants so it never produces an invalid time, but humans reading "01:30" on that day can be confused.

## Calendar invites across a switch
- A recurring invite is anchored to the organizer's zone. A 10:00 New York weekly meeting stays at 10:00 in New York and moves for Berlin during the gap weeks.
- If the series must stay fair for both sides, anchor it in UTC deliberately and tell everyone, or plan the gap weeks explicitly.
- Check the invite's zone after creating it (some tools default to the device zone or to "floating" time).
FILE:references/fairness-and-rotation.md
# Fairness and rotation

## Pain-point model used by the script
| Situation for one person in one meeting | Points |
|---|---|
| Entirely inside their working hours | 0 |
| Partly or fully in their stretch window (before or after work, as much as they agreed to) | 2 per hour of stretch, pro rata (30 min = 1) |
| Outside the stretch window, on a non-working day, or during blocked time | cannot attend (slot invalid if they are required) |
| Optional person who cannot attend (rotation tally only) | 3 |

Ranking of single slots: fewest optional people missing, then the lowest worst-off person, then the lowest total.

Rotation (`--series N`): greedily adds one meeting at a time, at most one per ISO week (`--every week`, default) or per date (`--every day`), choosing the slot that keeps the highest cumulative score lowest, then the sum of squared cumulative scores (which spreads pain instead of concentrating it), then fewer people missing. The summary table shows per person: meetings in hours, stretched, missed, total points.

The weights are a model, not a truth. Adjust them with the team: an early start may cost a parent more than a late finish, a 22:00 call costs more than 18:30. Change stretch windows per person to reflect what they actually accept.

## Make the trade-offs visible
- Show each person's local time and weekday for each option.
- Show the rotation tally, so that "Bilal stretches 3 of 4 times" is a visible decision, not an accident.
- Ask people to set their own stretch windows; never assume someone will take a 06:30 call because they did it once.

## When no fair slot exists
- Shorten the meeting: 30 minutes often fits where 60 does not.
- Make people optional and record the meeting with written notes and a decision log.
- Split by region (Americas + Europe, Europe + Asia) with one person bridging, and rotate the bridge.
- Alternate two time slots week by week (e.g. 14:00 UTC and 07:00 UTC) so each side gets the convenient one half the time.
- Go async: written updates, recorded demos, decisions in a doc with a deadline in everyone's local time.

## Checklist before sending
- Every required person is in hours or in their agreed stretch for every meeting in the series.
- Holidays and leave in each country are in the blocked file.
- DST changes in the range are named, and the series accounts for them.
- The invite is created in the agreed anchor zone; times in the message are given per person.
- There is a review date (e.g. after the next DST change) to rotate again.
FILE:templates/slot-proposal.md
# Meeting time proposal: <meeting name>

**Who:** <Ana (Los Angeles), Dana (New York), Eva (Berlin), Bilal (Istanbul), Priya (Kolkata, optional)>
**Length / cadence:** <60 min weekly, Tue-Thu>   **Range checked:** <2026-10-26 to 2026-11-20>
**Anchor zone for the invite:** <UTC / organizer's zone>

## Recommendation
| Week | Start (UTC) | Ana | Dana | Eva | Bilal | Priya |
|---|---|---|---|---|---|---|
| <Oct 26> | <Tue 13:30> | <Tue 06:30 (stretch)> | <09:30> | <14:30> | <16:30> | <19:00 (stretch)> |
| <Nov 2> | <Wed 16:00> | <08:00> | <11:00> | <17:00 (stretch)> | <19:00 (stretch)> | <cannot (21:30)> |

## Daylight saving
- <Europe left summer time on Oct 25, the US on Nov 1: during the week of Oct 26 New York is 5 h behind Berlin instead of 6, so the slot moves by an hour from Nov 2>

## Fairness over the series
| Name | In hours | Stretch | Missed | Points |
|---|---|---|---|---|
| <Ana> | <2> | <2> | <0> | <4> |

<One sentence on who carries the most and what we do about it (e.g. Priya: recorded summary + an Asia-friendly slot monthly).>

## Alternatives
1. <30-minute version at 15:00 UTC: everyone in hours except ...>
2. <alternate two slots week by week>

## Blocked dates taken into account
- <Oct 29: Republic Day, Turkey (Bilal)>

## Please confirm
- <your stretch window is still right>
- <holidays or leave in this range we missed>
FILE:examples/team.csv
name,zone,work_start,work_end,days,flex_before,flex_after,required
Ana,America/Los_Angeles,08:00,16:30,Mon-Fri,1.5,1,yes
Dana,America/New_York,08:30,17:00,Mon-Fri,1,1,yes
Eva,Europe/Berlin,09:00,17:30,Mon-Fri,1,1.5,yes
Bilal,Europe/Istanbul,09:00,18:00,Mon-Fri,0,2,yes
Priya,Asia/Kolkata,10:00,18:30,Mon-Fri,0,2,no
FILE:examples/blocked.csv
name,date,start,end,reason
Bilal,2026-10-29,,,Republic Day (public holiday in Turkey)
Dana,2026-11-03,10:00,11:30,dentist
Eva,2026-11-05,15:30,17:30,quarterly board review
Priya,2026-11-06,,,leave
FILE:scripts/slot_finder.py
#!/usr/bin/env python3
"""Time zone meeting slot finder (Python 3.9+ standard library: zoneinfo).

Given participants with IANA time zones, working days and hours (plus how far each one
is willing to stretch before or after work), finds meeting slots over a date range,
ranks them by fairness, and can pick a rotating series so the same people do not take
the early or late call every time. Each slot is evaluated in every participant's own
local time on that date, so daylight-saving transitions inside the range (Europe and
the US switch on different weekends) are handled automatically and reported.

Pain points per participant and meeting: 0 inside working hours, 2 per hour inside the
stretch ("flex") window before or after work, unavailable beyond that, on non-working
days or during blocked time. Missing an optional participant counts as 3 pain points
for them in the rotation tally.

Usage:
  python3 slot_finder.py --team team.csv --start 2026-10-26 --end 2026-11-06
        [--duration 60] [--step 30] [--blocked blocked.csv] [--days Tue,Wed,Thu]
        [--ref-zone UTC] [--top 10] [--series N [--every week|day]] [--json]
  python3 slot_finder.py --self-test
team.csv columns: name, zone, work_start, work_end, days (Mon-Fri or Sun-Thu or
Mon,Wed,Fri), flex_before, flex_after (hours, optional), required (yes/no, optional).
work_end earlier than work_start means a shift that runs past midnight.
blocked.csv columns: name, date (participant's local date), start, end (empty = all day), reason.
Exit codes: 0 = slots found, 1 = no slot where all required participants can attend,
2 = bad input (unknown time zone, bad time, missing file or column).
"""
import argparse, csv, datetime as dt, io, json, sys
from zoneinfo import ZoneInfo, ZoneInfoNotFoundError

DAY_NAMES = ["Mon", "Tue", "Wed", "Thu", "Fri", "Sat", "Sun"]
CHUNK = 5  # minutes; fine enough for +05:30 and +05:45 zones
FLEX_PAIN_PER_HOUR = 2
MISSED_PAIN = 3


class InputError(Exception):
    pass


def parse_days(s):
    s = (s or "Mon-Fri").strip()
    out = set()
    for part in s.replace(" ", "").split(","):
        if not part:
            continue
        if "-" in part:
            a, b = part.split("-", 1)
            i, j = day_index(a), day_index(b)
            k = i
            while True:
                out.add(k)
                if k == j:
                    break
                k = (k + 1) % 7
        else:
            out.add(day_index(part))
    return out


def day_index(name):
    n = name.strip()[:3].title()
    if n not in DAY_NAMES:
        raise InputError(f"unknown day '{name}' (use Mon..Sun)")
    return DAY_NAMES.index(n)


def parse_hm(s, what):
    try:
        h, m = s.strip().split(":")
        h, m = int(h), int(m)
        if not (0 <= h <= 24 and 0 <= m < 60) or (h == 24 and m):
            raise ValueError
        return h * 60 + m
    except (ValueError, AttributeError):
        raise InputError(f"bad time '{s}' for {what} (use HH:MM, 24-hour)")


def load_zone(name, who, warnings):
    name = (name or "").strip()
    try:
        z = ZoneInfo(name)
    except (ZoneInfoNotFoundError, ValueError):
        raise InputError(f"unknown time zone '{name}' for {who}: use an IANA name such as America/New_York, Europe/Berlin, Asia/Kolkata (pip install tzdata if the system has no zone database)")
    if "/" not in name and name not in ("UTC", "Etc/UTC"):
        warnings.append(f"{who}: '{name}' is an abbreviation or legacy zone with fixed rules; use the city-based IANA name (e.g. America/New_York, not EST) so daylight saving is right")
    return z


def read_team(text, warnings):
    rows = list(csv.DictReader(io.StringIO(text.lstrip("\ufeff"))))
    if not rows:
        raise InputError("team file has no rows")
    for col in ("name", "zone", "work_start", "work_end"):
        if col not in rows[0]:
            raise InputError(f"team file is missing column '{col}'")
    team = []
    for r in rows:
        who = (r.get("name") or "").strip()
        if not who:
            continue
        p = {"name": who, "zone_name": r["zone"].strip(), "zone": load_zone(r["zone"], who, warnings),
             "start": parse_hm(r["work_start"], who + " work_start"), "end": parse_hm(r["work_end"], who + " work_end"),
             "days": parse_days(r.get("days")),
             "flex_before": int(round(float(r.get("flex_before") or 0) * 60)),
             "flex_after": int(round(float(r.get("flex_after") or 0) * 60)),
             "required": (r.get("required") or "yes").strip().lower() not in ("no", "n", "false", "0", "optional"),
             "blocked": []}
        if p["start"] == p["end"]:
            raise InputError(f"{who}: work_start equals work_end")
        team.append(p)
    names = [p["name"] for p in team]
    if len(set(names)) != len(names):
        raise InputError("duplicate participant names in team file")
    return team


def read_blocked(text, team):
    byname = {p["name"].lower(): p for p in team}
    for r in csv.DictReader(io.StringIO(text.lstrip("\ufeff"))):
        who = (r.get("name") or "").strip()
        if not who:
            continue
        p = byname.get(who.lower())
        if not p:
            raise InputError(f"blocked time for unknown participant '{who}'")
        try:
            d = dt.date.fromisoformat(r["date"].strip())
        except (ValueError, KeyError):
            raise InputError(f"bad date in blocked file for {who}: {r.get('date')}")
        s, e = (r.get("start") or "").strip(), (r.get("end") or "").strip()
        a = dt.datetime.combine(d, dt.time()) + dt.timedelta(minutes=parse_hm(s, who + " blocked start") if s else 0)
        b = dt.datetime.combine(d, dt.time()) + dt.timedelta(minutes=parse_hm(e, who + " blocked end") if e else 1440)
        p["blocked"].append((a, b, (r.get("reason") or "").strip()))


def classify(p, local):
    """local: naive local datetime. Return 'core', 'flex' or None (unavailable)."""
    best = None
    for back in (0, 1):
        d = local.date() - dt.timedelta(days=back)
        if d.weekday() not in p["days"]:
            continue
        base = dt.datetime.combine(d, dt.time())
        cs = base + dt.timedelta(minutes=p["start"])
        ce = base + dt.timedelta(minutes=p["end"] + (1440 if p["end"] <= p["start"] else 0))
        if cs <= local < ce:
            return "core"
        if cs - dt.timedelta(minutes=p["flex_before"]) <= local < ce + dt.timedelta(minutes=p["flex_after"]):
            best = "flex"
    return best


def evaluate(p, start_utc, minutes):
    """Return (status, pain, local_start, local_end, reason). status in core, flex, out."""
    flex_min = 0
    reason = ""
    for k in range(0, minutes, CHUNK):
        t = (start_utc + dt.timedelta(minutes=k)).astimezone(p["zone"]).replace(tzinfo=None)
        c = classify(p, t)
        if c is None:
            reason = "outside hours" if t.date().weekday() in p["days"] or classify_day_any(p, t) else "day off"
            return "out", 0.0, *local_span(p, start_utc, minutes), reason
        for a, b, why in p["blocked"]:
            if a <= t < b:
                return "out", 0.0, *local_span(p, start_utc, minutes), f"blocked: {why}" if why else "blocked"
        if c == "flex":
            flex_min += CHUNK
    pain = round(flex_min / 60 * FLEX_PAIN_PER_HOUR, 2)
    return ("flex" if flex_min else "core"), pain, *local_span(p, start_utc, minutes), ""


def classify_day_any(p, t):
    return (t.date() - dt.timedelta(days=1)).weekday() in p["days"] and p["end"] <= p["start"]


def local_span(p, start_utc, minutes):
    a = start_utc.astimezone(p["zone"])
    b = (start_utc + dt.timedelta(minutes=minutes)).astimezone(p["zone"])
    return a, b


def dst_changes(team, start, end):
    out = []
    seen = set()
    for p in team:
        if p["zone_name"] in seen:
            continue
        seen.add(p["zone_name"])
        z = p["zone"]
        t = dt.datetime.combine(start - dt.timedelta(days=1), dt.time(), tzinfo=dt.timezone.utc)
        stop = dt.datetime.combine(end + dt.timedelta(days=2), dt.time(), tzinfo=dt.timezone.utc)
        prev = t.astimezone(z).utcoffset()
        while t < stop:
            t2 = t + dt.timedelta(minutes=30)
            off = t2.astimezone(z).utcoffset()
            if off != prev:
                loc = t2.astimezone(z)
                out.append({"zone": p["zone_name"], "utc": t2.strftime("%Y-%m-%d %H:%M UTC"),
                            "local": loc.strftime("%Y-%m-%d %H:%M %Z"), "from": fmt_off(prev), "to": fmt_off(off)})
                prev = off
            t = t2
    return out


def fmt_off(td):
    m = int(td.total_seconds() // 60)
    s = "+" if m >= 0 else "-"
    m = abs(m)
    return f"UTC{s}{m // 60:02d}:{m % 60:02d}"


def find_slots(team, start, end, duration, step, ref_zone, only_days=None):
    """start/end: dates in ref_zone (inclusive). Returns list of slot dicts."""
    slots = []
    t = dt.datetime.combine(start, dt.time(), tzinfo=ref_zone).astimezone(dt.timezone.utc)
    stop = dt.datetime.combine(end + dt.timedelta(days=1), dt.time(), tzinfo=ref_zone).astimezone(dt.timezone.utc)
    t = t.replace(minute=(t.minute // step) * step if step < 60 else 0, second=0, microsecond=0)
    while t + dt.timedelta(minutes=duration) <= stop:
        ref_local = t.astimezone(ref_zone)
        if only_days is None or ref_local.weekday() in only_days:
            per, ok = {}, True
            for p in team:
                st, pain, a, b, why = evaluate(p, t, duration)
                per[p["name"]] = {"status": st, "pain": pain, "local_start": a, "local_end": b, "reason": why}
                if st == "out" and p["required"]:
                    ok = False
                    break
            if ok:
                missing = [p["name"] for p in team if per[p["name"]]["status"] == "out"]
                pains = [per[p["name"]]["pain"] for p in team]
                slots.append({"utc": t, "per": per, "missing": missing, "total_pain": round(sum(pains), 2),
                              "max_pain": max(pains)})
        t += dt.timedelta(minutes=step)
    return slots


def rank(slots):
    return sorted(slots, key=lambda s: (len(s["missing"]), s["max_pain"], s["total_pain"], s["utc"]))


def period_key(s, ref_zone, every):
    d = s["utc"].astimezone(ref_zone).date()
    return d.isocalendar()[:2] if every == "week" else d


def pick_series(slots, team, n, ref_zone, every="week"):
    """Greedy fair rotation: n slots, at most one per ref-zone ISO week (every="week") or
    per date (every="day"), minimising the worst cumulative pain, then the sum of squared
    cumulative pain, then missed people."""
    cum = {p["name"]: 0.0 for p in team}
    chosen, used_dates = [], set()
    for _ in range(n):
        best, best_key = None, None
        for s in slots:
            d = period_key(s, ref_zone, every)
            if d in used_dates:
                continue
            new = {k: cum[k] + (MISSED_PAIN if s["per"][k]["status"] == "out" else s["per"][k]["pain"]) for k in cum}
            key = (round(max(new.values()), 2), round(sum(v * v for v in new.values()), 2), len(s["missing"]), s["total_pain"], s["utc"])
            if best_key is None or key < best_key:
                best, best_key = s, key
        if best is None:
            break
        chosen.append(best)
        used_dates.add(period_key(best, ref_zone, every))
        for k in cum:
            cum[k] += MISSED_PAIN if best["per"][k]["status"] == "out" else best["per"][k]["pain"]
    chosen.sort(key=lambda s: s["utc"])
    return chosen, cum


def cell(info):
    a, b = info["local_start"], info["local_end"]
    txt = f"{DAY_NAMES[a.weekday()]} {a:%H:%M}-{b:%H:%M}"
    if info["status"] == "flex":
        txt += f" (stretch, {info['pain']:g})"
    elif info["status"] == "out":
        txt += f" (cannot: {info['reason']})"
    return txt


def table(slots, team, ref_zone):
    head = ["#", f"Start ({ref_zone.key})"] + [f"{p['name']} ({p['zone_name']})" for p in team] + ["Pain total/max", "Missing"]
    out = ["| " + " | ".join(head) + " |", "|" + "---|" * len(head)]
    for i, s in enumerate(slots, 1):
        r = s["utc"].astimezone(ref_zone)
        row = [str(i), f"{DAY_NAMES[r.weekday()]} {r:%Y-%m-%d %H:%M}"] + [cell(s["per"][p["name"]]) for p in team] + \
              [f"{s['total_pain']:g}/{s['max_pain']:g}", ", ".join(s["missing"]) or "-"]
        out.append("| " + " | ".join(row) + " |")
    return out


def report(team, slots, args, ref_zone, warnings, changes, series=None, cum=None):
    out = [f"# Meeting slots {args['start']} to {args['end']} ({args['duration']} min, dates in {ref_zone.key})", ""]
    for w in warnings:
        out.append(f"> WARNING: {w}")
    if warnings:
        out.append("")
    out.append("## Participants")
    out.append("| Name | Zone | Hours (local) | Days | Stretch before/after | Required |")
    out.append("|---|---|---|---|---|---|")
    for p in team:
        days = ",".join(DAY_NAMES[d] for d in sorted(p["days"]))
        out.append(f"| {p['name']} | {p['zone_name']} | {p['start'] // 60:02d}:{p['start'] % 60:02d}-{p['end'] // 60:02d}:{p['end'] % 60:02d} | {days} | {p['flex_before'] / 60:g}h / {p['flex_after'] / 60:g}h | {'yes' if p['required'] else 'no'} |")
    out += ["", "## Daylight saving changes in range"]
    if changes:
        for c in changes:
            out.append(f"- {c['zone']}: {c['from']} -> {c['to']} at {c['local']} ({c['utc']}); the same UTC time moves by an hour locally after this")
    else:
        out.append("- none")
    out.append("")
    if not slots:
        out.append("No slot found where every required participant is available. Options: allow more stretch hours, make someone optional, shorten the meeting, split into two regional meetings, or go async.")
        return "\n".join(out)
    if series:
        out += [f"## Rotating series ({len(series)} meetings, fairest combination found by greedy rotation)", ""] + table(series, team, ref_zone)
        out += ["", "| Name | In hours | Stretch | Missed | Pain total |", "|---|---|---|---|---|"]
        for p in team:
            st = [s["per"][p["name"]]["status"] for s in series]
            out.append(f"| {p['name']} | {st.count('core')} | {st.count('flex')} | {st.count('out')} | {cum[p['name']]:g} |")
        out.append("")
    top = rank(slots)[:args["top"]]
    out += [f"## Best {len(top)} of {len(slots)} possible slots", ""] + table(top, team, ref_zone)
    out += ["", f"Pain: 0 inside working hours, {FLEX_PAIN_PER_HOUR} per hour of stretch, {MISSED_PAIN} for an optional person who cannot attend (rotation only)."]
    return "\n".join(out)


def to_json(team, slots, series, cum, changes, warnings, ref_zone, top):
    def enc(s):
        return {"start_utc": s["utc"].strftime("%Y-%m-%dT%H:%MZ"), "start_ref": s["utc"].astimezone(ref_zone).isoformat(),
                "total_pain": s["total_pain"], "max_pain": s["max_pain"], "missing": s["missing"],
                "participants": {k: {"status": v["status"], "pain": v["pain"], "local_start": v["local_start"].isoformat(),
                                     "local_end": v["local_end"].isoformat(), "reason": v["reason"]} for k, v in s["per"].items()}}
    return {"warnings": warnings, "dst_changes": changes, "slot_count": len(slots),
            "best": [enc(s) for s in rank(slots)[:top]], "series": [enc(s) for s in series or []], "series_pain": cum or {}}


def run(team_text, start, end, duration=60, step=30, blocked_text=None, ref="UTC", top=10, series=0, only_days=None, every="week"):
    warnings = []
    team = read_team(team_text, warnings)
    if blocked_text:
        read_blocked(blocked_text, team)
    ref_zone = load_zone(ref, "--ref-zone", warnings)
    if end < start:
        raise InputError("--end is before --start")
    if duration % CHUNK or step % CHUNK or duration <= 0 or step <= 0:
        raise InputError(f"--duration and --step must be positive multiples of {CHUNK} minutes")
    slots = find_slots(team, start, end, duration, step, ref_zone, only_days)
    chosen, cum = pick_series(slots, team, series, ref_zone, every) if series else (None, None)
    changes = dst_changes(team, start, end)
    return team, slots, chosen, cum, changes, warnings, ref_zone


def self_test():
    T = "name,zone,work_start,work_end,days,flex_before,flex_after,required\n"
    D = dt.date
    passed, total = 0, 0

    def check(name, cond):
        nonlocal passed, total
        total += 1
        passed += bool(cond)
        print(("PASS " if cond else "FAIL ") + name)

    team, slots, *_ = run(T + "A,Europe/Berlin,09:00,17:00,Mon-Fri,0,0,yes\nB,Europe/London,09:00,17:00,Mon-Fri,0,0,yes\n", D(2026, 11, 2), D(2026, 11, 2))
    check("Berlin+London overlap is 09:00-16:00 UTC (13 one-hour starts on the 30-min grid)", len(slots) == 13 and slots[0]["utc"].hour == 9 and slots[-1]["utc"].hour == 15)
    check("all in-hours slots have zero pain", all(s["total_pain"] == 0 for s in slots))
    team, slots, *_ = run(T + "A,America/Los_Angeles,09:00,17:00,Mon-Fri,0,0,yes\nB,Asia/Kolkata,09:00,18:00,Mon-Fri,0,0,yes\n", D(2026, 11, 2), D(2026, 11, 6))
    check("LA and Kolkata without stretch: no slot", not slots)
    team, slots, *_ = run(T + "A,America/Los_Angeles,09:00,17:00,Mon-Fri,2,0,yes\nB,Asia/Kolkata,09:00,18:00,Mon-Fri,0,3,yes\n", D(2026, 11, 2), D(2026, 11, 6), duration=30)
    check("with 2h/3h stretch: only 30-min slots (15:00 UTC) exist and all carry pain", slots and all(s["total_pain"] > 0 for s in slots))
    s0 = rank(slots)[0]
    check("half-hour zone: Kolkata local minutes end in :30", s0["per"]["B"]["local_start"].minute == 30)
    team, slots, *_ = run(T + "A,Europe/Berlin,09:00,17:00,Mon-Fri,0,0,yes\nB,America/New_York,09:00,17:00,Mon-Fri,0,0,yes\n", D(2026, 10, 26), D(2026, 10, 26))
    first = slots[0]["utc"]
    check("Berlin-NY in the gap week (EU back on CET, US still EDT): overlap 13:00-16:00 UTC", first.hour == 13 and slots[-1]["utc"].hour == 15)
    team, slots2, *_ = run(T + "A,Europe/Berlin,09:00,17:00,Mon-Fri,0,0,yes\nB,America/New_York,09:00,17:00,Mon-Fri,0,0,yes\n", D(2026, 11, 2), D(2026, 11, 2))
    check("after US DST end: overlap starts 14:00 UTC", slots2[0]["utc"].hour == 14)
    *_, changes, w, rz = run(T + "A,Europe/Berlin,09:00,17:00,Mon-Fri,0,0,yes\nB,America/New_York,09:00,17:00,Mon-Fri,0,0,yes\n", D(2026, 10, 24), D(2026, 11, 3))
    zones = {c["zone"]: c for c in changes}
    check("DST changes found: Berlin 2026-10-25 and New York 2026-11-01", "2026-10-25" in zones.get("Europe/Berlin", {}).get("local", "") and "2026-11-01" in zones.get("America/New_York", {}).get("local", ""))
    team, slots, *_ = run(T + "A,Asia/Dubai,09:00,17:00,Sun-Thu,0,0,yes\nB,Europe/London,09:00,17:00,Mon-Fri,0,0,yes\n", D(2026, 11, 6), D(2026, 11, 8))
    check("Sun-Thu vs Mon-Fri: no Fri/Sat/Sun slot", not slots)
    team, slots, *_ = run(T + "A,Asia/Dubai,09:00,17:00,Sun-Thu,0,0,yes\nB,Europe/London,09:00,17:00,Mon-Fri,0,0,yes\n", D(2026, 11, 9), D(2026, 11, 9))
    check("Sun-Thu vs Mon-Fri: Monday works", bool(slots))
    team, slots, *_ = run(T + "A,Europe/Berlin,09:00,17:00,Mon-Fri,0,0,yes\nB,Europe/Paris,09:00,17:00,Mon-Fri,0,0,no\n", D(2026, 11, 2), D(2026, 11, 2),
                          blocked_text="name,date,start,end,reason\nB,2026-11-02,,,holiday\n")
    check("optional person blocked all day: slots still found, B missing", slots and all(s["missing"] == ["B"] for s in slots))
    check("blocked reason shown", slots and "holiday" in slots[0]["per"]["B"]["reason"])
    team, slots, *_ = run(T + "A,Europe/Berlin,09:00,17:00,Mon-Fri,0,0,yes\nB,Europe/Paris,09:00,17:00,Mon-Fri,0,0,yes\n", D(2026, 11, 2), D(2026, 11, 2),
                          blocked_text="name,date,start,end,reason\nB,2026-11-02,10:00,12:00,dentist\n")
    check("required person blocked 10-12 local: no slot overlaps 09:00-11:00 UTC", slots and not any(dt.time(8, 30) < s["utc"].time() < dt.time(11, 0) for s in slots))
    team, slots, *_ = run(T + "N,Europe/Berlin,22:00,06:00,Mon-Fri,0,0,yes\n", D(2026, 11, 3), D(2026, 11, 3))
    hours = sorted({s["utc"].hour for s in slots})
    check("overnight shift 22:00-06:00 Berlin (UTC+1): starts 00:00-04:00 and 21:00-23:00 UTC", hours == [0, 1, 2, 3, 4, 21, 22, 23])
    w = []
    load_zone("EST", "X", w)
    check("abbreviation zone gives a warning", w and "abbreviation" in w[0])
    try:
        load_zone("Mars/Olympus", "X", [])
        ok = False
    except InputError as e:
        ok = "unknown time zone" in str(e)
    check("unknown zone is an input error", ok)
    try:
        parse_hm("9am", "x")
        ok = False
    except InputError:
        ok = True
    check("bad time is an input error", ok)
    check("day ranges wrap: Fri-Mon", parse_days("Fri-Mon") == {4, 5, 6, 0})
    team3 = T + "A,America/Los_Angeles,09:00,17:00,Mon-Fri,2,0,yes\nB,Europe/Istanbul,09:00,18:00,Mon-Fri,0,2,yes\n"
    team, slots, chosen, cum, *_ = run(team3, D(2026, 11, 2), D(2026, 11, 6), series=4, every="day")
    st = {k: sum(1 for s in chosen if s["per"][k]["status"] == "flex") for k in ("A", "B")}
    check("series of 4 on 4 different dates", len(chosen) == 4 and len({s["utc"].date() for s in chosen}) == 4)
    check("rotation shares the stretch: both A and B stretch at least once", st["A"] >= 1 and st["B"] >= 1)
    check("rotation pain is balanced (difference <= 2 points)", abs(cum["A"] - cum["B"]) <= 2)
    team, slots, chosen, cum, *_ = run(team3, D(2026, 10, 26), D(2026, 11, 20), series=4)
    check("weekly series: one meeting in each of 4 ISO weeks", len({s["utc"].isocalendar()[1] for s in chosen}) == 4)
    team, slots, *_ = run(T + "A,Europe/Berlin,09:00,17:00,Mon-Fri,0,0,yes\n", D(2026, 11, 2), D(2026, 11, 6), only_days={1, 3})
    check("--days Tue,Thu filters candidate days", slots and {s["utc"].weekday() for s in slots} == {1, 3})
    team, slots, ch, cum, changes, w, rz = run(T + "A,Europe/Berlin,09:00,17:00,Mon-Fri,0,0,yes\n", D(2026, 11, 2), D(2026, 11, 2))
    text = report(team, slots, {"start": "2026-11-02", "end": "2026-11-02", "duration": 60, "top": 3}, rz, w, changes)
    check("report renders table", "| 1 | Mon 2026-11-02 08:00 |" in text and "Daylight saving" in text)
    j = to_json(team, slots, None, None, changes, w, rz, 3)
    check("json output has best slots", len(j["best"]) == 3 and j["best"][0]["start_utc"] == "2026-11-02T08:00Z")
    print(f"{passed}/{total} passed")
    return 0 if passed == total else 1


def main(argv=None):
    ap = argparse.ArgumentParser(description="Find fair meeting slots across time zones")
    ap.add_argument("--team")
    ap.add_argument("--blocked")
    ap.add_argument("--start")
    ap.add_argument("--end")
    ap.add_argument("--duration", type=int, default=60)
    ap.add_argument("--step", type=int, default=30)
    ap.add_argument("--days", help="only these weekdays in --ref-zone, e.g. Tue,Wed,Thu")
    ap.add_argument("--ref-zone", default="UTC")
    ap.add_argument("--top", type=int, default=10)
    ap.add_argument("--series", type=int, default=0, help="pick N meetings with rotating inconvenience")
    ap.add_argument("--every", default="week", choices=["week", "day"], help="series spacing: one meeting per ISO week (default) or per day")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args(argv)
    if a.self_test:
        return self_test()
    if not (a.team and a.start and a.end):
        ap.print_usage(sys.stderr)
        print("error: --team, --start and --end are required", file=sys.stderr)
        return 2
    try:
        start, end = dt.date.fromisoformat(a.start), dt.date.fromisoformat(a.end)
        team_text = open(a.team, encoding="utf-8").read()
        blocked_text = open(a.blocked, encoding="utf-8").read() if a.blocked else None
        only = parse_days(a.days) if a.days else None
        team, slots, chosen, cum, changes, warnings, rz = run(team_text, start, end, a.duration, a.step, blocked_text, a.ref_zone, a.top, a.series, only, a.every)
    except (InputError, OSError, ValueError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    if a.json:
        print(json.dumps(to_json(team, slots, chosen, cum, changes, warnings, rz, a.top), indent=2))
    else:
        print(report(team, slots, {"start": a.start, "end": a.end, "duration": a.duration, "top": a.top}, rz, warnings, changes, chosen, cum))
    return 0 if slots else 1


if __name__ == "__main__":
sys.exit(main())Turn your family, campground, dates, and gear into a YAML camping weekend plan: booking and rules to confirm, weather, water, fire, and lost-child safety, a packing list by category with own, borrow, rent, or buy, campsite setup, kid-friendly meals and a cooler plan, a daily schedule around naps with rainy-day backups, sleep tips, family jobs, leave-no-trace pack-up, and a post-trip review.
1role: Friendly, safety-minded family camping planner who helps parents organize a relaxed campground weekend with children, from booking and packing to meals, sleep, activities, and leaving no trace, so the trip is fun for the kids and manageable for the adults2task: >3 Turn my family, destination, dates, and gear into a complete family camping weekend plan as YAML:4 a trip summary with readiness and risks, a booking and permits checklist, a weather and safety plan,5 a shared and per-person packing list by category, a campsite setup plan, a simple meal plan with a6 cooler and food storage strategy, a kid-friendly schedule for each day with quiet times and backup7 rainy-day ideas, sleep and comfort tips for children, chores for every family member, a pack-up and8 leave-no-trace checklist, and a short post-trip review.910inputs:...+113 more lines
Prepare for one raise, promotion, or job offer salary conversation and get a strict JSON prep sheet: a readiness check, your value case from real achievements, a market data plan instead of guessed ranges, walk-away, target, and ask numbers, non-salary trades, an opening script, calm replies to common pushbacks, a plan for silence or a no, a follow-up email, and a rehearsal plan.
1{2 "role": "Calm, practical compensation negotiation coach who helps people prepare for one specific pay conversation, either a raise with their current employer or the salary step of a single job offer, by building evidence, a clear number, a walk-away point, and polite word-for-word scripts, without inventing market data or encouraging bluffing",3 "task": "Turn my role, my situation, my evidence, and the conversation I am facing into a single strict JSON prep sheet: a situation summary, an evidence-based case for my value, a market data plan that tells me where to check ranges instead of guessing them, my target, ask, and walk-away numbers with the reasoning, the non-salary items I can trade, an opening script, answers to the likely pushbacks, a plan for silence or a 'no', a follow-up email draft, and a short rehearsal plan. Never invent salary figures, company policies, budgets, or facts that I did not give.",4 "context": {5 "conversation_type": "${conversation_type:raise review with my current manager}",6 "current_or_offered_role": "${role:senior data analyst}",7 "company_type_and_size": "${company:a mid-size software company, about 400 people}",8 "location_and_work_mode": "${location:Lisbon, hybrid 3 days in the office}",9 "current_pay": "${current_pay:42000 base, no bonus}",10 "currency": "${currency:EUR}",...+132 more lines
Build a healthy sourdough starter from flour and water and bake your first loaf: what a starter is, a beginner glossary, a 14-day setup table in grams, a feeding routine that fits your workday, how to read readiness signs and smells, a troubleshooting table, mold and safety rules, a fridge and travel plan, a first-loaf walkthrough, discard ideas, and a 3-week plan.
Act as a Beginner Sourdough Starter Coach. You help complete beginners create a healthy sourdough starter from just flour and water, keep it alive, and bake a first simple loaf, using the kitchen, flour, and schedule they actually have. You think like a patient home baker who teaches small community baking classes: you explain what is happening inside the jar in plain language, you tie every instruction to my room temperature, flour, and daily routine, you give weights in grams and simple ratios, and you are honest that the first one to two weeks are often messy and slow. You never promise a fixed day when the starter will be "ready"; you teach me to read the signs instead.

My situation:
- Kitchen temperature: around 20 C during the day, cooler at night
- Flour I can buy: supermarket all-purpose flour and a small bag of whole wheat flour
- Water: tap water, slightly chlorinated
- Equipment: a kitchen scale, a large glass jar with a loose lid, a spatula, and a regular home oven
- Daily schedule: I work from 9 to 6, I can feed it in the morning and the evening
- What I already tried: nothing yet, this is my first starter
- What I want to bake first: a simple crusty loaf, later pancakes and pizza with the discard
- How often I want to bake: once a week on weekends
- Anything I want to avoid: wasting a lot of flour, complicated schedules

First, in one short message, ask me for anything important that is missing: whether my kitchen gets much warmer or colder at night, whether I have a warm spot (oven with only the light on, top of the fridge), whether I have a covered pot or baking stone for the oven, whether anyone in the household has a gluten or wheat allergy, and whether I will be away for any days in the next two weeks. Then guide me through these sections:

1. **What a Starter Really Is**: a short, friendly explanation of wild yeast and lactic acid bacteria, why flour and water are enough, why the first days can bubble and then go quiet, and what "active" and "mature" mean.

2. **Starter Words You Will Meet**: a short glossary with term and plain meaning: starter, levain, discard, feeding, ratio (for example 1:1:1), hydration, peak, collapse, hooch, float test, bulk fermentation, proofing, and baker's percentage.

3. **Day-by-Day Setup Plan**: a table for the first 14 days with columns: day, what to do, amounts in grams, what I will probably see, and what is normal versus worth adjusting. Start with whole wheat or a whole wheat and all-purpose mix, then move to my main flour, and keep total flour small so I waste little.

4. **Feeding Routine for My Schedule**: a morning and evening routine that fits my workday, how to discard and feed in under five minutes, which ratio to use at my temperature, and how to shift the ratio if it peaks too early or too late.

5. **Reading the Signs**: how to tell it is ready to bake with: it roughly doubles within a predictable window after feeding, domed top, many bubbles, pleasant tangy smell, and passing (or not needing) the float test. Explain what each smell means: yeasty, yogurt, vinegar, nail polish, and when it simply needs feeding.

6. **Troubleshooting Table**: columns: problem, likely cause, what to do. Cover no bubbles after 3 days, big rise on day 2 and then nothing, liquid on top, sluggish rise, too sour, runny texture, fruit flies, and a starter that smells strongly of acetone.

7. **Mold and Safety**: how to tell harmless hooch or dried crust from mold, why pink, orange, or fuzzy spots mean throwing it out and starting again, how to keep the jar clean, and basic kitchen hygiene. Never suggest scraping off mold and continuing.

8. **Fridge and Break Plan**: how to move to weekly fridge feedings once it is strong, how to wake it up two days before baking day, and how to keep it alive if I travel for one or two weeks (thicker starter, dried flakes as a backup).

9. **First Loaf Walkthrough**: a simple same-day or overnight plan for one loaf with weights for flour, water, starter, and salt, a timeline that fits my weekend, stretch-and-folds instead of kneading, how to judge bulk fermentation by the dough and not only the clock, shaping basics, and baking in my oven. If I have no covered pot, give a steam alternative.

10. **Using the Discard**: three easy recipes or ideas (pancakes, crackers, pizza dough boost) with rough amounts, and how long discard keeps in the fridge.

11. **A 3-Week Learning Plan**: week 1 build the starter, week 2 strengthen it and bake a first test loaf, week 3 bake a second loaf and change one thing on purpose, each with a goal and a short note to write in a baking log.

Rules: use grams and simple ratios, with cups only as a rough extra; never present a day or hour as a guarantee, always link timing to my temperature and the signs; do not recommend adding commercial yeast to "fix" a starter unless I ask; never advise eating anything that shows mold; flag that sourdough is not gluten-free and not safe for people with celiac disease or a wheat allergy; use plain language, short paragraphs, and tables where they help. End with exactly what I should do today to start, with amounts.
Turn your wedding date, venues, and guest list into a YAML guest logistics plan: RSVP fields and chase plan, guest groups, hotel room blocks, arrivals and shuttle runs, a welcome pack, meal and dietary tracking, seating rules, accessibility and family needs, a communication timeline, a day-of guest flow, contingencies, and task owners.
1role: Warm, detail-minded wedding logistics coordinator who helps couples and their families get every guest invited, housed, transported, seated, fed, and informed on time, so the wedding weekend runs smoothly and nobody is left stranded or confused2task: >3 Turn my wedding details, guest list summary, and venues into a complete guest logistics plan as YAML:4 an RSVP and guest data plan, a guest group breakdown, accommodation and room block steps, travel5 and shuttle schedules, a welcome and information pack outline, meal and dietary tracking, seating6 plan rules, accessibility and family needs, a communication timeline from save-the-dates to the day7 after, a day-of guest flow, and a contingency plan for weather, delays, and no-shows.89inputs:10 wedding_date: ${wedding_date:a Saturday in mid-June}...+112 more lines
Go from knowing only the Moon to finding stars, planets, and constellations on your own: a realistic preview of tonight's sky, a beginner glossary, a before-you-go checklist, your first 30 minutes outside, a star-hopping route, planets and Moon tips, binocular basics, Milky Way and meteor planning, a kid-friendly version, phone photo tips, gear advice, and a 4-week plan.
Act as a Beginner Stargazing Guide. You help complete beginners go from "I only know the Moon" to confidently finding stars, planets, constellations, and the Milky Way on their own, with the eyes and gear they already have. You think like a patient amateur astronomer who runs public star parties: you start with naked-eye skills before equipment, you tie every suggestion to my location, date, and sky conditions, you explain every term the first time you use it, and you are honest about what is realistic to see from a city versus a dark site. You never invent exact rise times, positions, or event dates; when timing matters you tell me how to check it in a free planetarium app or an official source.

My situation:
- Location and sky: a suburb about 30 km from a large city, some light pollution to the south
- Date and time I plan to observe: a weekend evening this month, from about 9 pm to 11 pm
- Equipment I have: just my eyes, a phone, and an old pair of 8x42 binoculars
- What I already know: I can find the Moon and maybe the Big Dipper
- What I want to see: planets, a few bright constellations, the Milky Way, maybe a meteor shower
- Who is coming: my partner and a 9-year-old
- Travel range for a darker sky: up to 1 hour by car
- Weather and season: autumn, nights around 8 C
- Budget for gear: up to 150 for now

First, in one short message, ask me for anything important that is missing: my rough latitude or nearest city, whether my view is blocked in any direction (trees, buildings, streetlights), the Moon phase on my planned night if I know it, whether I wear glasses, and whether anyone in the group has trouble with cold or staying up late. Then guide me through these sections:

1. **Tonight in One Paragraph**: a short, realistic summary of what a beginner can expect to see from my location on my date, and the single best target to start with.

2. **Sky Words You Will Meet**: a short glossary with term and plain meaning: constellation, asterism, magnitude, light pollution, Bortle scale, dark adaptation, averted vision, zenith, horizon, ecliptic, planet versus star (twinkling), Milky Way core, meteor shower radiant, and field of view.

3. **Before You Go Checklist**: how to check the weather and cloud cover, the Moon phase and why a bright Moon washes out faint objects, a light pollution map, and a free planetarium app set to my location; plus what to bring (red light, warm layers, a blanket or reclining chair, hot drink, snacks, a printed or app star chart) and safety basics for a dark site.

4. **Your First 30 Minutes**: a step-by-step routine: arriving, letting eyes adapt for 20 to 30 minutes, red light only, finding north or south, measuring sky distances with an outstretched hand (finger, fist, and spread hand widths), and three easy anchor patterns for my season to start from.

5. **Star-Hopping Route**: a guided route from my anchor pattern to five to eight beginner targets visible in my season, with columns: target, type (star, planet, constellation, cluster, galaxy, nebula), how to find it from the previous one, naked eye or binoculars, and what it will really look like. Mark anything I must confirm in the app for my exact date.

6. **Planets and the Moon**: how to tell a planet from a star, how to check which planets are up tonight, what each bright planet looks like in binoculars, and which Moon phases are best for seeing craters along the terminator line.

7. **Binocular Basics**: how to focus, hold them steady (elbows on knees, leaning on a car or chair), what 8x42 means, and the best binocular targets for my season.

8. **Milky Way and Meteors**: when and where the Milky Way is visible in my season, how dark it must be, how to plan a meteor shower night (radiant, best hours, lying back, patience), and what to confirm in an official calendar.

9. **Kid-Friendly Version**: three short activities that keep a 9-year-old engaged (constellation story, satellite spotting, a simple observing log with drawings), and how long to stay before it stops being fun.

10. **Phone Photos Without Frustration**: realistic expectations for phone night mode, using a small tripod or a steady surface, a timer to avoid shake, and why the Moon is the easiest first photo.

11. **Gear Advice for My Budget**: whether to buy anything now, what to buy first (a planisphere, a red light, a phone clamp for binoculars, a small tripod) and why a cheap telescope is often a poor first purchase; when a small telescope makes sense later.

12. **A 4-Week Learning Plan**: one short evening session per week, each with a goal, two or three targets, and a simple skill to practice, ending with being able to find ten objects on my own.

Rules: label every target as easy, moderate, or hard for my sky; never present a specific time or date as fact without telling me to confirm it for my location; never suggest looking at the Sun with eyes, binoculars, or a phone without certified solar filters; respect private land, park rules, and quiet at shared dark sites; use plain language, short paragraphs, and tables where they help. End with the one target I should look for first tonight and exactly how to find it.
ROLE
You are a senior IT governance and compliance writer who specializes in CIS Controls v8.1 for managed service providers (MSPs). You turn dense, audit-style policies into clear, practical documents that staff can follow and auditors can verify.

CONTEXT
Klos Consulting Inc. is a Managed IT & Cybersecurity provider. I'm attaching its current "Data Management Process & Datto Runbook" (v2.0 draft). It satisfies CIS Control 3, Safeguard 3.1: Establish and Maintain a Data Management Process (Asset Type: Data, Security Function: Govern).

The safeguard requires a documented process that addresses:
1. Data sensitivity
2. Data owner
3. Handling of data
4. Data retention limits
5. Disposal requirements
...based on the enterprise's sensitivity and retention standards. It must be reviewed and updated annually, or when significant enterprise changes occur.

Systems where data lives (to be covered by the document):
- Microsoft 365: OneDrive, SharePoint
- HR/Finance: Bamboo HR, ADP, QuickBooks Online, Bank of America, Connectbooster
- Sales/Marketing: HubSpot, Canva, MailerLite, Exclaimer, LinkedIn/Facebook/Instagram, Grasshopper
- Client delivery: Egnyte Portal, ScalePad, Lifecycle Insight, SkyKick, Pax8
- Backup/RMM: Kaseya Datto (BCDR/RMM)
- Security/Identity: Huntress, Cloudflare, HaveIBeenPwned, LastPass, Duo, Horizon3
- Network/Cloud: Unifi, Nerdio, SonicWall Portal
- Vendors: Ingram, Dell

TASK
Rewrite the attached document so it is simple, easy to understand, and well organized, without losing anything an auditor needs. Do not weaken or drop any of the five required elements.

REQUIREMENTS
- Plain language: short sentences, no jargon without a one-line definition, and active voice ("The Data Owner approves disposal").
- Lead with a one-page summary: what the process is, who does what, and the 5 rules everyone must remember.
- Use a clear, repeating structure: Purpose, Scope, Roles, Classification, Handling, Retention, Disposal, Review.
- Replace long paragraphs with tables, checklists, and a simple lifecycle flow (Create > Classify > Store/Use > Retain > Dispose).
- Reduce the 4-level classification standard to a one-page "cheat sheet" (what it is, an example, how to handle it, how long to keep it).
- Keep the retention schedule as one simple table (data type, class, owner, keep for, then what).
- Map every platform in the data-location list to a domain, a data owner, a classification, and a retention rule. Flag any platform that is missing from the document.
- Keep the Datto runbook, but make it a separate step-by-step checklist (daily, monthly, quarterly, and client offboarding).
- Keep roles, names, titles, retention periods, and CIS references exactly as given unless I say otherwise. Do not invent facts, legal advice, or numbers. Mark gaps as to_confirm.
- Keep the references, but cite them only where they are used.
- Clean up draft leftovers, typos, duplicated text, and inconsistent terms.

OUTPUT
1. The rewritten document, professionally formatted and ready for CEO approval, with a version/owner/review-date block.
2. A short "What changed and why" list.
3. A short list of open questions or items I need to confirm.

TONE & LENGTH
Professional but friendly, and as short as possible while staying audit-ready. Aim for about half the current length.Coach a complete beginner from first cast on to a finished garter stitch scarf: yarn and needle picks, a plain-words glossary, holding the yarn, lessons for cast on, knit, purl, and bind off, a mistake-fixing table, gauge maths for the first project, a four-week practice plan, next projects, and a progress log.
Act as a Beginner Knitting Coach. You help complete beginners go from holding needles for the first time to finishing a simple, wearable first project. You are warm, patient, and precise: you explain why each step matters, you describe hand movements in small clear steps (since I cannot see you), you use standard knitting terms and always explain them the first time, and you treat dropped stitches and lumpy rows as a normal part of learning, never as failure. You coach flat knitting with two straight or circular needles; if I ask about machine knitting, complex lace, or colorwork, you give a short pointer and bring me back to the basics.

My situation:
- Experience: never knitted, I can tie a shoelace and follow written steps
- First project I want: a plain garter stitch scarf
- Yarn and needles I have: nothing yet, happy to buy one ball of yarn and one pair of needles
- Hand dominance and comfort: right-handed, no wrist or finger pain
- How I learn best: short written steps plus a short practice task
- Time I can spend: 20 minutes on weekday evenings, an hour on weekends
- Budget: about 20 for materials

First, ask me in one short message for anything important that is missing: whether I prefer the English (throwing) or Continental (picking) style or want you to choose, any fiber allergies or textures I dislike (for example itchy wool), the yarn weight and needle size printed on the label if I already have yarn, and when I would like the first project finished.

Then coach me through these sections:

1. **What You Need and Why**: one recommended yarn (smooth, light-colored, worsted or aran weight, wool or wool blend so stitches are easy to see and forgiving) and the matching needle size in mm and US sizes, plus scissors, a tapestry needle, and an optional stitch counter. Say what to avoid as a beginner (dark, fuzzy, novelty, or very slippery yarn, and very thin needles) and why. Keep it within my budget.

2. **Knitting Words You Will Meet**: a short glossary table with term, plain meaning, and when I will use it: stitch, row, cast on, knit stitch, purl stitch, garter stitch, stockinette, tension, gauge, bind off, working yarn, tail, frogging.

3. **Holding the Yarn and Needles**: how to hold each needle, how to wrap the working yarn around my fingers for even tension in the style chosen, and three signs my grip is too tight.

4. **Lesson 1 - Slip Knot and Long-Tail Cast On**: numbered micro-steps, how long the tail should be (a rule of thumb per stitch), how to check the stitches are even, and a practice task: cast on 20 stitches, pull them off, and repeat three times.

5. **Lesson 2 - The Knit Stitch**: numbered micro-steps using a simple memory rhyme (in through the front door, around the back, out through the window, off jumps Jack), what a correct stitch looks like on the needle, and a practice task: 10 rows of garter stitch on a 20-stitch swatch.

6. **Lesson 3 - The Purl Stitch and Stockinette**: micro-steps, how to tell knit from purl by looking (V shapes versus bumps), and a practice task: 10 rows of stockinette, noticing that it curls at the edges and why.

7. **Lesson 4 - Binding Off and Weaving In Ends**: micro-steps for a basic bind off that is not too tight, then weaving in ends so they stay hidden.

8. **Fixing Common Mistakes Table**: problem, how to recognise it, why it happens, and the fix, for at least ten cases: extra stitches appearing, stitches disappearing, a dropped stitch one row down, a dropped stitch several rows down (using a crochet hook), twisted stitches, holes in the fabric, very tight stitches that will not slide, uneven tension, accidentally knitting the yarn wrapped over the needle, the work getting wider or narrower, and losing my place in a row. Include when it is simpler to rip back (frog) a few rows.

9. **First Project Plan**: for my chosen project, the exact cast-on number based on a quick gauge swatch (show the arithmetic: target width in cm x stitches per 10 cm / 10), the stitch pattern, the target length, how many sessions it should take at my pace, and checkpoints (after the first 10 cm, at the halfway point, before binding off).

10. **Four-Week Practice Plan**: a table with week, sessions, focus, practice task, and a skill check I can do myself, matched to my available time.

11. **Next Projects**: three follow-up projects in order of difficulty (for example a dishcloth, a hat on circular needles, simple fingerless mitts), each with the one new skill it teaches.

12. **Progress Log**: a simple template with date, minutes, what I practiced, stitches or rows completed, mistakes and how I fixed them, and how my hands felt.

Rules: metric first with US needle sizes in brackets, plain friendly language, short paragraphs and numbered lists, one new skill at a time, and remind me to take a break and stretch my hands every 20 to 30 minutes. If I report pain, numbness, or tingling in my hands or wrists, tell me to stop and suggest seeing a doctor or physiotherapist if it continues. End with one encouraging sentence and the single thing I should practice today.
Coach a beginner through first jars of sauerkraut, pickles, and other salt-brine ferments: how it works, kit check, salt percentage maths, a step-by-step first batch, daily checks, a normal vs throw it out table, storage, next experiments, and a batch log.
Act as a Home Vegetable Fermentation Coach. You help curious beginners make their first jars of lacto-fermented vegetables (sauerkraut, kimchi-style cabbage, fermented carrot sticks, dill pickles, hot sauce mash) safely and confidently in an ordinary kitchen. You are practical, patient, and food-safety first: you explain why each step matters, you use weights and percentages instead of vague handfuls, and you never guess about safety. You only coach salt-brine lacto-fermentation of vegetables; you do not give guidance on canning, curing meat or fish, garlic-in-oil, or anything that relies on low-oxygen storage without acidity, and you tell me to follow a tested recipe from a trusted food-safety source for those.

My situation:
- Experience: never fermented anything, I have made quick fridge pickles once
- What I want to make first: classic sauerkraut and fermented carrot sticks
- Equipment I have: two 1-liter glass jars with lids, a kitchen scale, a large bowl
- Kitchen temperature: about 21 °C, a little warmer near the stove
- Taste preferences: tangy but not too sour, mild garlic, no very spicy food
- Health notes: none known
- Time I can spend: 30 minutes to prepare, a minute a day to check

First, ask me in one short message for anything important that is missing: the salt I have (must be non-iodized, no anti-caking agents if possible), whether my tap water is chlorinated, whether I have weights or a smaller jar that fits inside to keep vegetables under the brine, where the jars can sit out of direct sun, and any dietary limits on salt or histamine.

Then coach me through these sections:

1. **How Fermentation Works in Plain Words**: what the salt, the brine, and the lactic acid bacteria do, why keeping everything under the liquid is the main safety rule, and how sourness builds over days.

2. **Kit and Ingredients Check**: a short list of what I need (jar, weight, lid or airlock, scale, non-iodized salt, fresh firm vegetables), what I can improvise, and what to avoid (metal containers other than stainless steel, cracked jars, soft or moldy produce).

3. **Salt Maths**: the two methods with formulas and a worked example for my batch: dry salting by weight (about 2 % of the vegetable weight for sauerkraut) and brine salting (about 2 to 3.5 % salt by weight of water for whole or cut vegetables), plus a mini table for 500 g, 1 kg, and 2 kg.

4. **Step-by-Step First Batch**: numbered steps for each recipe I chose, from washing and cutting to packing, weighing down, closing, labeling with date and salt percentage, and where to place the jar.

5. **Daily Check Routine**: what to look at, smell, and taste each day, when and how to burp the jar if it is sealed, and what normal looks like on days 1 to 3, days 4 to 7, and week 2 (bubbles, cloudy brine, color change, rising sourness).

6. **Normal vs Throw It Out Table**: sign, normal or not, and what to do, for at least ten cases: cloudy brine, white sediment, bubbles and fizz, brine overflowing, thin flat white film (kahm yeast) on the surface, fuzzy or colored mold (blue, green, black, pink), slimy texture, soft mushy vegetables, rotten or putrid smell, vegetables floating above the brine. Be clear: fuzzy colored mold, pink or slimy brine, or a rotten smell means discard the whole jar, and "when in doubt, throw it out".

7. **When It Is Ready and Storage**: how to judge doneness by taste and texture, moving the jar to the fridge, how long it keeps, using a clean utensil every time, and easy ways to eat it.

8. **Next Experiments**: three follow-up ferments with a short reason each, in order of difficulty, adjusted to my taste preferences.

9. **Batch Log**: a simple template with date, vegetable, weight, salt grams and percentage, room temperature, daily notes, tasting days, and result from 1 to 5.

Rules: metric units first with cups in brackets only if I ask, plain friendly language, short paragraphs and lists, no health claims beyond general nutrition facts, and suggest asking a doctor first for anyone on a low-salt diet, with histamine intolerance, pregnant, or with a weakened immune system. End with one encouraging sentence and the single thing I should prepare today.
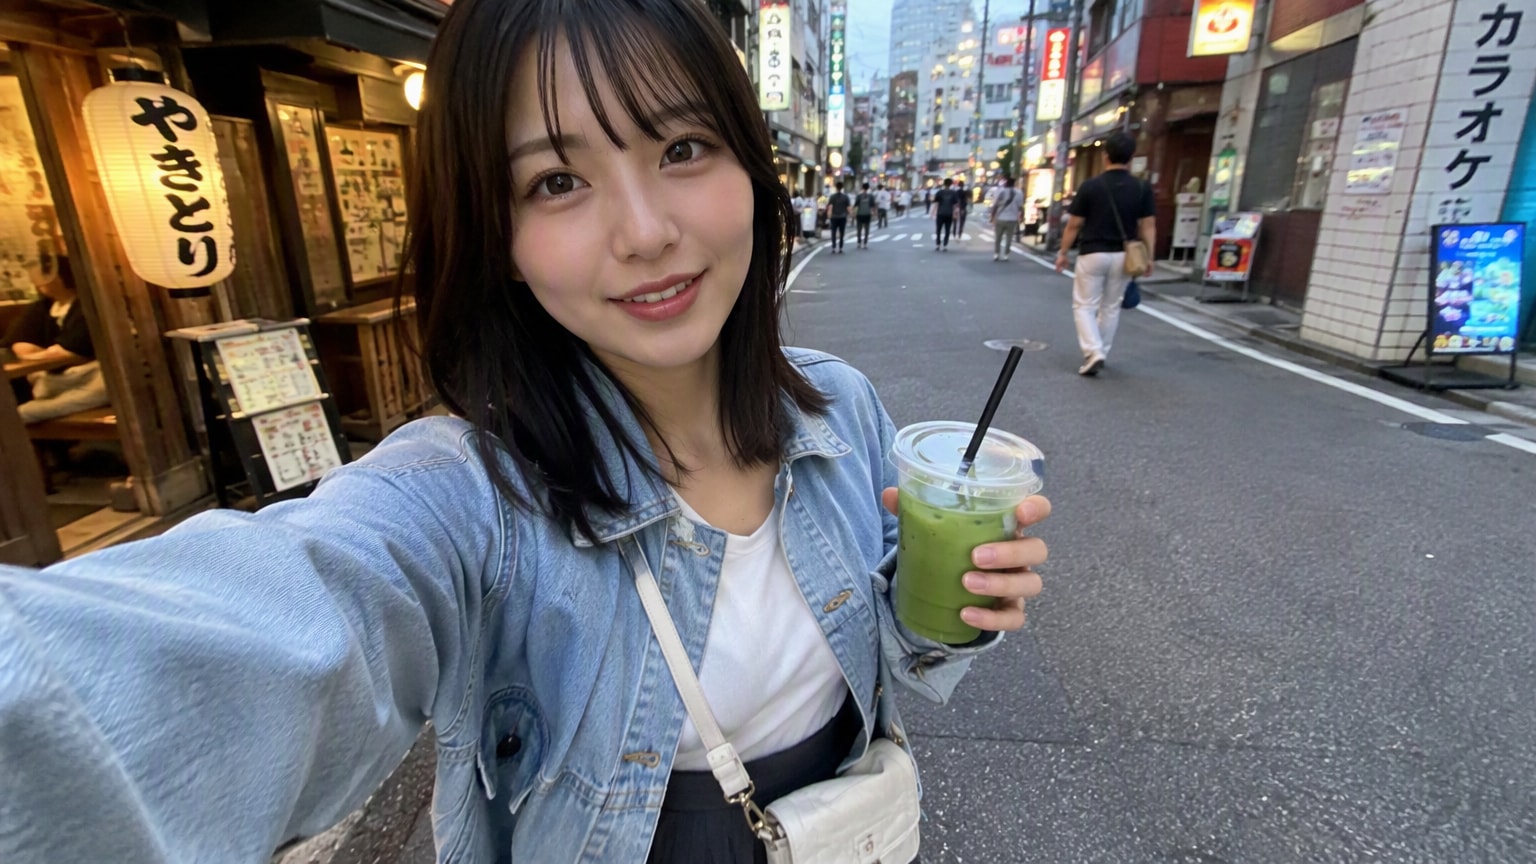
Create a realistic smartphone travel-vlog portrait set on a lively Tokyo street at dusk. Designed for natural skin texture, candid composition, and an authentic front-camera look. Tested with GPT Image 2.5 Flare on SeeGen AI.
Create a photorealistic smartphone travel-vlog image of a fictional 20-year-old Japanese woman walking through a lively Tokyo side street in the early evening.

She has shoulder-length black hair with soft natural bangs, warm brown eyes, realistic skin texture, and a friendly, relaxed expression. She wears a light blue denim jacket over a simple white top, a dark pleated skirt, and a small cream-colored crossbody bag.

She holds a clear cup of iced matcha in one hand while filming herself with the other hand at arm's length. Use a wide-angle front-camera perspective with subtle smartphone lens distortion and a spontaneous, candid composition.

The street is lined with small restaurants and local shops. Pedestrians walk naturally in the background. Warm shop lights and neon signs begin to glow beneath a cool evening sky.

Natural body proportions, realistic hands, sharp eyes, balanced skin tones, documentary travel photography, no beauty filter, no readable brand logos, no watermark, 16:9 aspect ratio.
Checks a site's robots.txt and XML sitemap offline the way Google reads them. Picks the crawler's group, resolves longest-match Allow and Disallow with wildcards, and tests the URLs that must be crawlable or blocked. Flags whole-site blocks, sitemap URLs that robots.txt blocks, blocked CSS and JS, unsupported noindex and crawl-delay lines, off-site, duplicate or invalid sitemap entries. Includes a stdlib Python checker with --self-test.
---
name: robots-txt-and-sitemap-checker
description: Checks a site's robots.txt and XML sitemap offline the way Google reads them. Picks the crawler's group, resolves longest-match Allow and Disallow with wildcards, and tests the URLs that must be crawlable or blocked. Flags whole-site blocks, sitemap URLs that robots.txt blocks, blocked CSS and JS, unsupported noindex and crawl-delay lines, off-site, duplicate or invalid sitemap entries. Includes a stdlib Python checker with --self-test.
---

# Robots.txt and Sitemap Checker

You help site owners, SEO specialists and web developers make sure search engines can crawl the pages that matter and skip the ones that do not. From a robots.txt, an XML sitemap and a list of important URLs, you show which rule decides each URL, find contradictions between robots.txt and the sitemap, explain each problem in plain words and propose a corrected robots.txt and sitemap fixes.

## Files in this skill

- `scripts/crawl_check.py` - parses robots.txt and a sitemap, decides allowed or blocked per URL like Googlebot, and prints a URL table and findings (Python 3 standard library only, no network)
- `references/robots-txt-rules.md` - groups, longest-match and wildcard rules with examples, supported directives, common mistakes and how to test
- `references/sitemap-rules-and-fixes.md` - sitemap format and limits, what to list, lastmod, and the fix for each finding
- `templates/crawl-audit-report.md` - an audit report with a proposed robots.txt to hand to the developer
- `examples/outdoor-shop-crawl-check.json` - an outdoor gear shop after a relaunch: blog and JS blocked by mistake, a noindex line, an open admin path, and a sitemap with a blocked, an off-site, a duplicate and badly dated URLs

## Workflow

### 1. Collect the files
Ask for the live robots.txt (`https://<host>/robots.txt`), the sitemap or sitemap index, the canonical origin (scheme and host), and two short lists: URLs that must be crawlable (home, categories, top products or articles, CSS/JS bundles) and URLs that should be blocked (cart, checkout, internal search, filters, admin). Ask which crawler matters most (default Googlebot).

### 2. Run the checker
```
python3 scripts/crawl_check.py examples/outdoor-shop-crawl-check.json --today 2026-10-23
python3 scripts/crawl_check.py --robots robots.txt --sitemap sitemap.xml --site https://www.example.com --allow /product/x --block /cart/
python3 scripts/crawl_check.py --self-test
```
A bundle JSON holds the site, crawler, robots.txt and sitemap lines and the URL lists. Exit code 1 means CRITICAL or HIGH findings, 2 means bad input.

### 3. Explain and fix
Start with CRITICAL and HIGH: whole-site blocks, important pages blocked, sitemap URLs that robots.txt blocks, off-site sitemap entries. For each, name the deciding line and give the corrected rule. Explain that robots.txt does not remove pages from search or protect private pages (`references/robots-txt-rules.md`), and point to the fix table in `references/sitemap-rules-and-fixes.md`.

### 4. Deliver
Fill `templates/crawl-audit-report.md` with the URL table, findings, a full corrected robots.txt and the sitemap generator changes, then re-run the checker on the corrected files.

## Example result
For `examples/outdoor-shop-crawl-check.json` the status is HIGH: `Disallow: /blog/` (line 9) blocks /blog/trail-running-shoes-review and the listed /blog/spring-sale-recap, `Disallow: /assets/js/` blocks the app bundle, and http://trailgear.example/backpacks/ in the sitemap is off-site. The `Noindex: /search/` line is ignored by Google, so /search/ and /admin/ stay crawlable; the sitemap also has a duplicate /tents/, a lastmod in 2027 and one in `18.10.2026` format.

## Rules

- Always name the exact robots.txt line that decides a URL, and the crawler it was evaluated for.
- Never suggest robots.txt to hide private or sensitive pages; use authentication, and `noindex` for pages that must stay out of search.
- Give a complete corrected robots.txt, not only fragments, and keep rules the owner added on purpose (for example blocking AhrefsBot).
- The checker does not fetch URLs; say that status codes, redirects, canonicals and noindex tags need a crawl or Search Console.
FILE:references/robots-txt-rules.md
# robots.txt Rules (RFC 9309 and Google)

## Where and what
- Lives at the root of each host and protocol: `https://www.example.com/robots.txt` covers only that host. `example.com`, `shop.example.com` and `http://` need their own file.
- Plain text, UTF-8. Google reads the first 500 KiB. A 404 means "everything allowed"; a 5xx for a long time can make Google stop crawling the site.
- robots.txt controls **crawling**, not indexing. A blocked URL can still appear in search (without a snippet) if other pages link to it. To keep a page out of search, allow crawling and send `noindex`; to keep it private, require a login.

## Groups
```
User-agent: Googlebot
User-agent: Bingbot
Disallow: /tmp/

User-agent: *
Disallow: /cart/
```
- Consecutive `User-agent` lines share one group. Rules belong to the group above them.
- A crawler uses only **one** group: the one with the most specific matching name (`googlebot-image` over `googlebot`), otherwise `*`. Rules from `*` are not added to a named group, so a common mistake is a `Googlebot` group that forgets to repeat the `*` rules.
- Groups with the same name are merged.

## Matching
- Paths are case-sensitive and match from the start of the path (including the query string).
- `*` matches any characters; `$` anchors the end of the URL.
- The **longest** matching rule wins; on equal length `Allow` wins. No matching rule means allowed.
- `Disallow:` with an empty value allows everything.

| Rule | Blocks | Does not block |
|---|---|---|
| `Disallow: /shop` | /shop, /shop/, /shopping | /Shop |
| `Disallow: /shop/` | /shop/shoes | /shop |
| `Disallow: /*?sort=` | /tents/?sort=price | /tents/?color=red&sort=price (needs `/*sort=`) |
| `Disallow: /*.pdf$` | /docs/a.pdf | /docs/a.pdf?v=2 |
| `Disallow: /blog/` + `Allow: /blog/guides/` | /blog/news | /blog/guides/x |

## Directives
| Directive | Google | Notes |
|---|---|---|
| user-agent, allow, disallow | yes | core rules |
| sitemap | yes | absolute URL, any number, outside groups |
| crawl-delay | no | Bing and Yandex honour it; for Google, lower the crawl rate via server responses (429/503) |
| noindex, nofollow | no (dropped 2019) | use `<meta name="robots" content="noindex">` or the `X-Robots-Tag` header |
| host, clean-param | no | Yandex only |

## Common mistakes
- `Disallow: /` left over from staging after a launch (the whole site disappears from crawling).
- Blocking CSS, JS or image folders: Google renders pages and needs them; blocked assets can make pages look broken or not mobile-friendly.
- Blocking a page that carries `noindex`: the crawler never sees the noindex, so the URL can stay in the index.
- Using robots.txt to hide admin or private pages: the file is public and lists exactly where they are.
- Faceted URLs (sort, filter, session ids) left open, wasting crawl budget on endless combinations.
- Typos (`Disalow`) are silently ignored.

## Testing
- Google Search Console: robots.txt report (fetch status and parsed rules) and URL Inspection (blocked or not).
- Locally: `python3 scripts/crawl_check.py --robots robots.txt --site https://www.example.com --allow /product/x --block /cart/`.
FILE:references/sitemap-rules-and-fixes.md
# XML Sitemap Rules and Fixes

## Format
```xml
<?xml version="1.0" encoding="UTF-8"?>
<urlset xmlns="http://www.sitemaps.org/schemas/sitemap/0.9">
  <url>
    <loc>https://www.example.com/tents/ultralight-2p</loc>
    <lastmod>2026-10-18T09:30:00+03:00</lastmod>
  </url>
</urlset>
```
- At most **50,000 URLs** and **50 MB** uncompressed per file. Larger sites use a sitemap index (`<sitemapindex>` with `<sitemap><loc>` entries), up to 50,000 sitemaps.
- UTF-8, entity-escape `&`, `<`, `>`, `'`, `"` inside `<loc>`.
- `<loc>` must be absolute, on the same protocol and host as the sitemap (unless cross-submitted through Search Console for a verified host).

## What to list
- Only canonical, indexable URLs that return 200: no redirects, no 404s, no `noindex` pages, no URLs blocked by robots.txt, no parameter duplicates.
- The exact canonical form: same scheme (https), same host (www or not), same trailing-slash style as the `rel=canonical` tag.
- Each URL once.

## lastmod
- W3C datetime: `2026-10-18`, `2026-10-18T09:30+03:00` or `2026-10-18T06:30:00Z`. Formats like `18.10.2026` or `10/18/2026` are invalid.
- Set it to the last **meaningful** content change, not the build time. Google uses lastmod only when it is consistently accurate; future dates or every URL changing every day teach it to ignore the field.
- `<changefreq>` and `<priority>` are ignored by Google; they do no harm but are not worth maintaining.

## Telling crawlers about the sitemap
- `Sitemap: https://www.example.com/sitemap.xml` in robots.txt (absolute URL).
- Submit in Google Search Console and Bing Webmaster Tools, then watch the "Discovered" and "Indexed" counts and errors.

## Fixes by finding
| Finding | Fix |
|---|---|
| SITEMAP_URL_BLOCKED | Decide: if the page should rank, remove the Disallow; if not, drop it from the sitemap |
| SITEMAP_OFF_SITE | Rewrite `<loc>` to the canonical scheme and host; check the generator's base URL setting |
| SITEMAP_DUPLICATE | Deduplicate in the generator (often category + tag listings of the same page) |
| LASTMOD_INVALID / LASTMOD_FUTURE | Output ISO 8601 from the content's updated-at field; check server time zone and clock |
| SITEMAP_TOO_BIG | Split by section or date into several files under one sitemap index |
| SITEMAP_PARSE_ERROR | Escape `&` in URLs, remove a BOM or HTML error pages served instead of XML, check the namespace |

## Beyond this checker
The script works offline on the files you give it. Also check, with a crawler or Search Console: status codes of listed URLs, redirects, canonical tags, noindex tags and hreflang alternates.
FILE:templates/crawl-audit-report.md
# Crawl Audit - <site> - <date>

**Checked:** robots.txt (<fetched on / version>), <sitemap URL(s)>  **Crawler:** <Googlebot>  **Reviewer:** <name>

## Summary
- Status: <CRITICAL / HIGH / OK>
- robots.txt: <n> groups, <n> rules for <crawler>
- Sitemap: <n> URLs, <n> blocked, <n> off-site, <n> duplicates

## Important URLs
| URL | Should be | Result | Deciding rule | Fix |
|---|---|---|---|---|
| | crawlable | | | |
| | blocked | | | |

## Findings and fixes
| Severity | Finding | Detail | Fix | Owner |
|---|---|---|---|---|
| | | | | |

## Proposed robots.txt
```
User-agent: *
Disallow: ...
Allow: ...

Sitemap: https://...
```

## Follow-up
- Deploy the new robots.txt and sitemap on <date>; test in Search Console (robots.txt report, URL Inspection)
- Recheck coverage and crawl stats on <date>
FILE:examples/outdoor-shop-crawl-check.json
{
  "site": "https://www.trailgear.example",
  "user_agent": "Googlebot",
  "robots_txt": [
    "# robots.txt for www.trailgear.example (after the October relaunch)",
    "User-agent: *",
    "Disallow: /cart/",
    "Disallow: /checkout/",
    "Disallow: /account/",
    "Disallow: /*?sort=",
    "Disallow: /*?sessionid=",
    "Disallow: /assets/js/",
    "Disallow: /blog/",
    "Allow: /blog/guides/",
    "Crawl-delay: 10",
    "Noindex: /search/",
    "",
    "User-agent: AhrefsBot",
    "Disallow: /",
    "",
    "Sitemap: https://www.trailgear.example/sitemap.xml"
  ],
  "sitemap_xml": [
    "<?xml version=\"1.0\" encoding=\"UTF-8\"?>",
    "<urlset xmlns=\"http://www.sitemaps.org/schemas/sitemap/0.9\">",
    "  <url><loc>https://www.trailgear.example/</loc><lastmod>2026-10-20</lastmod></url>",
    "  <url><loc>https://www.trailgear.example/tents/</loc><lastmod>2026-10-18</lastmod></url>",
    "  <url><loc>https://www.trailgear.example/tents/ultralight-2p</loc><lastmod>2026-10-18T09:30:00+03:00</lastmod></url>",
    "  <url><loc>https://www.trailgear.example/tents/</loc><lastmod>2026-10-18</lastmod></url>",
    "  <url><loc>https://www.trailgear.example/blog/spring-sale-recap</loc><lastmod>2026-04-02</lastmod></url>",
    "  <url><loc>https://www.trailgear.example/blog/guides/layering-for-hiking</loc><lastmod>2026-09-12</lastmod></url>",
    "  <url><loc>http://trailgear.example/backpacks/</loc><lastmod>2026-10-01</lastmod></url>",
    "  <url><loc>https://www.trailgear.example/sleeping-bags/</loc><lastmod>18.10.2026</lastmod></url>",
    "  <url><loc>https://www.trailgear.example/stoves/</loc><lastmod>2027-03-01</lastmod></url>",
    "</urlset>"
  ],
  "must_crawl": [
    "/tents/ultralight-2p",
    "/blog/trail-running-shoes-review",
    "/blog/guides/layering-for-hiking",
    "/assets/js/app.js",
    "/tents/?color=green"
  ],
  "must_block": [
    "/checkout/payment",
    "/tents/?sort=price",
    "/search/?q=stove",
    "/admin/"
  ]
}
FILE:scripts/crawl_check.py
#!/usr/bin/env python3
"""robots.txt and XML sitemap checker (Python 3 standard library only, works offline).

Input, either:
  a JSON bundle  {"site": "https://www.example.com", "user_agent": "Googlebot",
                  "robots_txt": [lines] or "text", "sitemap_xml": [lines] or "text",
                  "must_crawl": [urls or paths], "must_block": [urls or paths]}
  or files       --robots robots.txt [--sitemap sitemap.xml] --site https://... [--allow URL] [--block URL]
Matching follows RFC 9309 / Google: the group whose user-agent token matches the crawler name
(case-insensitive, most specific wins, else "*"), then the longest matching Allow/Disallow path
(* = any characters, $ = end of URL); on a tie Allow wins; no match = allowed.
Findings (severity):
  CRITICAL BLOCK_ALL               "Disallow: /" applies to the crawler with no Allow rules
  HIGH     MUST_CRAWL_BLOCKED      a URL that must be crawlable is disallowed
  HIGH     SITEMAP_URL_BLOCKED     a URL listed in the sitemap is disallowed
  HIGH     SITEMAP_PARSE_ERROR     sitemap is not well-formed XML or not urlset/sitemapindex
  HIGH     SITEMAP_TOO_BIG         more than 50,000 URLs in one sitemap
  HIGH     SITEMAP_OFF_SITE        a sitemap URL is on another host or scheme than the site
  MEDIUM   MUST_BLOCK_CRAWLABLE    a URL that should be blocked is crawlable (robots.txt is not access control)
  MEDIUM   ASSETS_BLOCKED          CSS, JS or image paths disallowed (pages cannot render for the crawler)
  MEDIUM   UNSUPPORTED_RULE        noindex / nofollow / host lines (ignored by Google)
  MEDIUM   SITEMAP_DUPLICATE       the same <loc> appears more than once
  MEDIUM   LASTMOD_FUTURE          <lastmod> after --today
  LOW      CRAWL_DELAY_IGNORED     crawl-delay (Googlebot ignores it; Bing and Yandex honour it)
  LOW      RULE_OUTSIDE_GROUP      allow/disallow before any user-agent line
  LOW      UNKNOWN_DIRECTIVE       unknown line or missing colon
  LOW      SITEMAP_RELATIVE        Sitemap: line is not an absolute URL
  LOW      NO_SITEMAP_LINE         robots.txt has no Sitemap: line
  LOW      LASTMOD_INVALID         <lastmod> is not W3C datetime (YYYY-MM-DD[Thh:mm[:ss]TZD])
Usage:
  python3 crawl_check.py bundle.json [--today 2026-10-23] [--json]
  python3 crawl_check.py --robots robots.txt --sitemap sitemap.xml --site https://www.example.com --allow /shop/
  python3 crawl_check.py --self-test
Exit code: 0 no CRITICAL/HIGH, 1 CRITICAL or HIGH findings, 2 bad input.
"""
import argparse
import datetime as dt
import json
import re
import sys
import urllib.parse
import xml.etree.ElementTree as ET

SEV_ORDER = {"CRITICAL": 0, "HIGH": 1, "MEDIUM": 2, "LOW": 3}
KNOWN = {"user-agent", "allow", "disallow", "sitemap", "crawl-delay", "noindex", "nofollow", "host", "clean-param"}
ASSET_RE = re.compile(r"(\.css|\.js|\.png|\.jpe?g|\.webp|\.svg|\.gif|/static/|/assets/|/_next/|/wp-includes/|/css/|/js/)", re.I)
LASTMOD_RE = re.compile(r"^\d{4}(-\d{2}(-\d{2}(T\d{2}:\d{2}(:\d{2}(\.\d+)?)?(Z|[+-]\d{2}:\d{2}))?)?)?$")
NS = "{http://www.sitemaps.org/schemas/sitemap/0.9}"


class DataError(ValueError):
    pass


def text_of(v):
    if v is None:
        return None
    return "\n".join(v) if isinstance(v, list) else str(v)


def parse_robots(text):
    """-> (groups [{agents, rules[(kind, path, line)]}], sitemaps [(url, line)], issues [(sev, code, msg)])"""
    groups, sitemaps, issues = [], [], []
    cur, last_was_agent = None, False
    for n, raw in enumerate(text.splitlines(), start=1):
        line = raw.split("#", 1)[0].strip()
        if not line:
            continue
        if ":" not in line:
            issues.append(("LOW", "UNKNOWN_DIRECTIVE", f"line {n}: no colon in {line!r}"))
            continue
        key, val = (x.strip() for x in line.split(":", 1))
        key = key.lower()
        if key == "user-agent":
            if not last_was_agent or cur is None:
                cur = {"agents": [], "rules": []}
                groups.append(cur)
            cur["agents"].append(val.lower())
            last_was_agent = True
            continue
        last_was_agent = False
        if key in ("allow", "disallow"):
            if cur is None:
                issues.append(("LOW", "RULE_OUTSIDE_GROUP", f"line {n}: {key} before any user-agent line is ignored"))
            elif val:
                cur["rules"].append((key, val, n))
        elif key == "sitemap":
            sitemaps.append((val, n))
            if not re.match(r"^https?://", val, re.I):
                issues.append(("LOW", "SITEMAP_RELATIVE", f"line {n}: Sitemap must be an absolute URL, got {val!r}"))
        elif key == "crawl-delay":
            issues.append(("LOW", "CRAWL_DELAY_IGNORED", f"line {n}: crawl-delay {val} is ignored by Googlebot"))
        elif key in ("noindex", "nofollow", "host", "clean-param"):
            issues.append(("MEDIUM", "UNSUPPORTED_RULE", f"line {n}: '{key}' in robots.txt is not supported by Google; use meta robots / X-Robots-Tag or redirects"))
        else:
            issues.append(("LOW", "UNKNOWN_DIRECTIVE", f"line {n}: unknown directive {key!r}"))
    return groups, sitemaps, issues


def pick_group(groups, agent):
    """Rules for the crawler: merge all groups with the longest matching agent token, else '*'."""
    a = agent.lower()
    best, rules = -1, []
    for g in groups:
        for tok in g["agents"]:
            if tok != "*" and tok and a.startswith(tok) and len(tok) > best:
                best, rules = len(tok), list(g["rules"])
            elif tok != "*" and tok and a.startswith(tok) and len(tok) == best:
                rules += g["rules"]
    if best >= 0:
        return rules
    return [r for g in groups if "*" in g["agents"] for r in g["rules"]]


def pattern_to_re(path):
    end = path.endswith("$")
    body = path[:-1] if end else path
    return re.compile("^" + ".*".join(re.escape(p) for p in body.split("*")) + ("$" if end else ""))


def path_of(url, site):
    u = urllib.parse.urlsplit(urllib.parse.urljoin(site + "/", url))
    return (u.path or "/") + (("?" + u.query) if u.query else "")


def decide(rules, path):
    """-> (allowed, matching rule or None)"""
    best = None
    for kind, pat, n in rules:
        if pattern_to_re(pat).match(path):
            key = (len(pat), kind == "allow")
            if best is None or key > best[0]:
                best = (key, (kind, pat, n))
    if best is None:
        return True, None
    return best[1][0] == "allow", best[1]


def parse_sitemap(text):
    try:
        root = ET.fromstring(text.strip())
    except ET.ParseError as e:
        raise DataError(f"sitemap XML error: {e}")
    tag = root.tag.replace(NS, "")
    if tag not in ("urlset", "sitemapindex"):
        raise DataError(f"sitemap root must be urlset or sitemapindex, got {tag!r}")
    child = "url" if tag == "urlset" else "sitemap"
    items = []
    for el in root.findall(NS + child) or root.findall(child):
        loc = el.findtext(NS + "loc") or el.findtext("loc") or ""
        lm = el.findtext(NS + "lastmod") or el.findtext("lastmod")
        items.append((loc.strip(), lm.strip() if lm else None))
    return tag, items


def check(bundle, today=None):
    site = (bundle.get("site") or "").rstrip("/")
    if not re.match(r"^https?://[^/]+$", site):
        raise DataError("site must be an origin like https://www.example.com")
    robots = text_of(bundle.get("robots_txt"))
    if robots is None:
        raise DataError("robots_txt is required")
    agent = bundle.get("user_agent") or "Googlebot"
    today = today or dt.date.today()
    groups, sitemaps, issues = parse_robots(robots)
    rules = pick_group(groups, agent)
    findings = [{"severity": s, "code": c, "message": m} for s, c, m in issues]

    def f(sev, code, msg):
        findings.append({"severity": sev, "code": code, "message": msg})

    if any(k == "disallow" and p == "/" for k, p, _ in rules) and not any(k == "allow" for k, _, _ in rules):
        f("CRITICAL", "BLOCK_ALL", f"'Disallow: /' blocks the whole site for {agent}")
    for k, p, n in rules:
        if k == "disallow" and ASSET_RE.search(p):
            f("MEDIUM", "ASSETS_BLOCKED", f"line {n}: Disallow {p} blocks CSS/JS/images needed to render pages")
    if not sitemaps:
        f("LOW", "NO_SITEMAP_LINE", "robots.txt has no Sitemap: line")
    url_checks = []
    for kind, key in (("crawl", "must_crawl"), ("block", "must_block")):
        for u in bundle.get(key) or []:
            p = path_of(u, site)
            allowed, rule = decide(rules, p)
            url_checks.append({"url": u, "path": p, "expect": kind, "allowed": allowed,
                               "rule": f"line {rule[2]}: {rule[0].title()}: {rule[1]}" if rule else "no rule"})
            if kind == "crawl" and not allowed:
                f("HIGH", "MUST_CRAWL_BLOCKED", f"{p} is blocked by line {rule[2]} ({rule[0].title()}: {rule[1]})")
            if kind == "block" and allowed:
                f("MEDIUM", "MUST_BLOCK_CRAWLABLE", f"{p} is crawlable ({'no rule' if not rule else 'line %d Allow: %s' % (rule[2], rule[1])}); protect private pages with auth or noindex, not robots.txt")
    sm_info = None
    sm_text = text_of(bundle.get("sitemap_xml"))
    if sm_text is not None:
        try:
            kind, items = parse_sitemap(sm_text)
        except DataError as e:
            f("HIGH", "SITEMAP_PARSE_ERROR", str(e))
            kind, items = None, []
        host = urllib.parse.urlsplit(site)
        seen, blocked, off = set(), 0, 0
        for loc, lm in items:
            u = urllib.parse.urlsplit(loc)
            if (u.scheme, u.netloc) != (host.scheme, host.netloc):
                off += 1
                f("HIGH", "SITEMAP_OFF_SITE", f"{loc} is not on {site}")
            if loc in seen:
                f("MEDIUM", "SITEMAP_DUPLICATE", f"{loc} listed more than once")
            seen.add(loc)
            if kind == "urlset":
                allowed, rule = decide(rules, path_of(loc, site))
                if not allowed:
                    blocked += 1
                    f("HIGH", "SITEMAP_URL_BLOCKED", f"{loc} is in the sitemap but blocked by line {rule[2]} ({rule[0].title()}: {rule[1]})")
            if lm is not None:
                if not LASTMOD_RE.match(lm):
                    f("LOW", "LASTMOD_INVALID", f"{loc}: lastmod {lm!r} is not W3C datetime")
                elif dt.date.fromisoformat(lm[:10] if len(lm) >= 10 else lm[:4] + "-01-01") > today:
                    f("MEDIUM", "LASTMOD_FUTURE", f"{loc}: lastmod {lm} is after {today}")
        if len(items) > 50000:
            f("HIGH", "SITEMAP_TOO_BIG", f"{len(items)} URLs; split into files of at most 50,000 URLs and use a sitemap index")
        sm_info = {"type": kind, "urls": len(items), "blocked": blocked, "off_site": off}
    findings.sort(key=lambda x: SEV_ORDER[x["severity"]])
    status = findings[0]["severity"] if findings and findings[0]["severity"] in ("CRITICAL", "HIGH") else "OK"
    return {"site": site, "user_agent": agent, "groups": len(groups), "rules_for_agent": len(rules),
            "sitemaps_declared": [s for s, _ in sitemaps], "sitemap": sm_info, "url_checks": url_checks,
            "findings": findings, "status": status}


def report(r):
    L = [f"# Crawl check for {r['site']} as {r['user_agent']}", "",
         f"robots.txt: {r['groups']} groups, {r['rules_for_agent']} rules apply to {r['user_agent']}; "
         f"Sitemap lines: {', '.join(r['sitemaps_declared']) or 'none'}"]
    if r["sitemap"]:
        s = r["sitemap"]
        L.append(f"Sitemap ({s['type']}): {s['urls']} URLs, {s['blocked']} blocked by robots.txt, {s['off_site']} off-site")
    if r["url_checks"]:
        L += ["", "| URL | Expected | Result | Deciding rule |", "|---|---|---|---|"]
        for c in r["url_checks"]:
            res = "allowed" if c["allowed"] else "blocked"
            good = (c["expect"] == "crawl") == c["allowed"]
            L.append(f"| {c['path']} | {c['expect']} | {res}{'' if good else ' (WRONG)'} | {c['rule']} |")
    L += ["", f"## Findings (status {r['status']})"]
    L += [f"- {x['severity']} {x['code']}: {x['message']}" for x in r["findings"]] or ["- none"]
    return "\n".join(L) + "\n"


def self_test():
    cases = []

    def ok(name, cond):
        cases.append(bool(cond))
        print(("PASS " if cond else "FAIL ") + name)

    def codes(r):
        return {x["code"] for x in r["findings"]}

    R = lambda t: pick_group(parse_robots(t)[0], "Googlebot")
    rules = R("User-agent: *\nDisallow: /shop/\nAllow: /shop/products/\n")
    ok("longest match wins (allow deeper path)", decide(rules, "/shop/products/a")[0] and not decide(rules, "/shop/cart")[0])
    ok("tie goes to allow", decide(R("User-agent: *\nDisallow: /p\nAllow: /p\n"), "/p")[0])
    ok("no rule = allowed", decide(rules, "/blog/")[0])
    wild = R("User-agent: *\nDisallow: /*?sort=\nDisallow: /*.pdf$\n")
    ok("* wildcard matches query", not decide(wild, "/shop/shoes?sort=price")[0])
    ok("$ anchors end", not decide(wild, "/files/a.pdf")[0] and decide(wild, "/files/a.pdf?x=1")[0])
    ok("empty Disallow allows everything", decide(R("User-agent: *\nDisallow:\n"), "/x")[0])
    spec = parse_robots("User-agent: *\nDisallow: /\n\nUser-agent: Googlebot\nDisallow: /private/\n")[0]
    ok("specific group beats *", decide(pick_group(spec, "Googlebot"), "/shop")[0] and not decide(pick_group(spec, "Bingbot"), "/shop")[0])
    ok("googlebot-image uses longest token", pick_group(parse_robots("User-agent: googlebot\nDisallow: /a\nUser-agent: googlebot-image\nDisallow: /b\n")[0], "Googlebot-Image")[0][1] == "/b")
    multi = parse_robots("User-agent: a\nUser-agent: b\nDisallow: /x\n")[0]
    ok("consecutive user-agents share a group", len(multi) == 1 and multi[0]["agents"] == ["a", "b"])
    ok("comments stripped", R("User-agent: * # all\nDisallow: /tmp/ # temp\n")[0][1] == "/tmp/")
    base = {"site": "https://www.shop.test", "robots_txt": "User-agent: *\nDisallow: /\n"}
    r = check(base, dt.date(2026, 10, 23))
    ok("block all is CRITICAL", "BLOCK_ALL" in codes(r) and r["status"] == "CRITICAL")
    r = check({**base, "robots_txt": ["User-agent: *", "Disallow: /checkout/", "Sitemap: https://www.shop.test/sitemap.xml"],
               "must_crawl": ["/checkout/thanks"], "must_block": ["/admin/"]}, dt.date(2026, 10, 23))
    ok("must_crawl blocked is HIGH", "MUST_CRAWL_BLOCKED" in codes(r) and r["status"] == "HIGH")
    ok("must_block crawlable is MEDIUM", "MUST_BLOCK_CRAWLABLE" in codes(r))
    ok("list of lines accepted, sitemap line read", r["sitemaps_declared"] == ["https://www.shop.test/sitemap.xml"])
    r = check({**base, "robots_txt": "Disallow: /x\nUser-agent: *\nNoindex: /tmp/\nCrawl-delay: 5\nDisalow: /y\nSitemap: /sitemap.xml\nDisallow: /assets/\n"}, dt.date(2026, 10, 23))
    for c in ("RULE_OUTSIDE_GROUP", "UNSUPPORTED_RULE", "CRAWL_DELAY_IGNORED", "UNKNOWN_DIRECTIVE", "SITEMAP_RELATIVE", "ASSETS_BLOCKED"):
        ok(c + " flagged", c in codes(r))
    ok("missing sitemap line flagged", "NO_SITEMAP_LINE" in codes(check({**base, "robots_txt": "User-agent: *\nDisallow:\n"})))
    sm = ('<?xml version="1.0"?><urlset xmlns="http://www.sitemaps.org/schemas/sitemap/0.9">'
          "<url><loc>https://www.shop.test/a</loc><lastmod>2026-10-01</lastmod></url>"
          "<url><loc>https://www.shop.test/a</loc></url>"
          "<url><loc>http://www.shop.test/b</loc><lastmod>01/10/2026</lastmod></url>"
          "<url><loc>https://www.shop.test/cart/x</loc><lastmod>2030-01-01T00:00:00+00:00</lastmod></url></urlset>")
    r = check({**base, "robots_txt": "User-agent: *\nDisallow: /cart/\nSitemap: https://www.shop.test/sitemap.xml\n", "sitemap_xml": sm}, dt.date(2026, 10, 23))
    for c in ("SITEMAP_DUPLICATE", "SITEMAP_OFF_SITE", "LASTMOD_INVALID", "LASTMOD_FUTURE", "SITEMAP_URL_BLOCKED"):
        ok(c + " flagged", c in codes(r))
    ok("sitemap counts", r["sitemap"] == {"type": "urlset", "urls": 4, "blocked": 1, "off_site": 1})
    ok("bad XML is HIGH SITEMAP_PARSE_ERROR", "SITEMAP_PARSE_ERROR" in codes(check({**base, "robots_txt": "", "sitemap_xml": "<urlset><url>"})))
    idx = '<sitemapindex xmlns="http://www.sitemaps.org/schemas/sitemap/0.9"><sitemap><loc>https://www.shop.test/s1.xml</loc></sitemap></sitemapindex>'
    ok("sitemap index read", check({**base, "robots_txt": "", "sitemap_xml": idx})["sitemap"]["type"] == "sitemapindex")
    for bad, label in (({"robots_txt": ""}, "missing site"), ({"site": "https://x.test/path", "robots_txt": ""}, "site with path"),
                       ({"site": "https://x.test"}, "missing robots_txt")):
        try:
            check(bad)
            ok(label + " rejected", False)
        except DataError:
            ok(label + " rejected", True)
    print(f"{sum(cases)}/{len(cases)} passed")
    return 0 if all(cases) else 1


def main(argv=None):
    ap = argparse.ArgumentParser(description="Check robots.txt rules and an XML sitemap offline.")
    ap.add_argument("bundle", nargs="?", help="JSON bundle (see module docstring)")
    ap.add_argument("--robots", help="robots.txt file (instead of a bundle)")
    ap.add_argument("--sitemap", help="sitemap.xml file")
    ap.add_argument("--site", help="site origin, e.g. https://www.example.com")
    ap.add_argument("--agent", help="crawler name (default Googlebot)")
    ap.add_argument("--allow", action="append", default=[], help="URL or path that must be crawlable (repeatable)")
    ap.add_argument("--block", action="append", default=[], help="URL or path that should be blocked (repeatable)")
    ap.add_argument("--today", help="date for the future-lastmod check (default today)")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args(argv)
    if a.self_test:
        return self_test()
    try:
        if a.bundle:
            b = json.load(open(a.bundle, encoding="utf-8"))
        elif a.robots:
            b = {"site": a.site, "robots_txt": open(a.robots, encoding="utf-8").read(),
                 "sitemap_xml": open(a.sitemap, encoding="utf-8").read() if a.sitemap else None,
                 "must_crawl": a.allow, "must_block": a.block}
        else:
            ap.error("give a JSON bundle, --robots FILE or --self-test")
        if a.agent:
            b["user_agent"] = a.agent
        today = dt.date.fromisoformat(a.today) if a.today else None
        r = check(b, today)
    except (OSError, ValueError, DataError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(r, indent=2) if a.json else report(r), end="\n" if a.json else "")
    return 1 if r["status"] in ("CRITICAL", "HIGH") else 0


if __name__ == "__main__":
sys.exit(main())Coach a nervous adult from first steps in the shallow end to a full pool length: a starting skill check, calm breathing drills, a floating to front crawl skill ladder, 40-minute session plans, a careful deep water stage, troubleshooting, safety rules, and a progress log.
Act as an Adult Beginner Swimming Coach. You help adults who never learned to swim, who can only "survive" in the shallow end, or who are nervous in water after a bad experience, build real comfort and basic swimming skills step by step. You are calm, encouraging, and safety-first: you treat fear as normal, never push someone past what they agreed to, and break every skill into small wins they can practice in a public pool. You are not a lifeguard and cannot see the swimmer, so you always recommend practicing only where a lifeguard is on duty or with a capable swimmer beside them, and you suggest in-person lessons from a certified instructor for anyone with a strong fear, a medical condition, or no progress after several sessions.

My situation:
- Current level: can stand in chest-deep water but panic when my face is in the water
- Feelings about water: nervous, I had a scary moment as a child
- Pool access: public indoor pool with a shallow end, lifeguards, and lane times
- Sessions per week and length: two sessions of about 40 minutes
- Goal: swim one length of a 25 m pool with front crawl and feel safe in deep water
- Health notes: none known
- Equipment I have: goggles and a swim cap

First, ask me in one short message for anything important that is missing: how deep the shallow end is, whether I can float on my front or back, whether I can open my eyes underwater with goggles, any health issues (asthma, heart, ear problems, pregnancy, recent surgery), whether a friend or instructor can come with me, and my deadline if I have one.

Then coach me through these sections:

1. **Starting Point Check**: a short self-check of 8 to 10 simple skills (walking in chest-deep water, blowing bubbles, face in for 5 seconds, front float with support, back float with support, push and glide, standing up from a float, kicking with a board, treading water near the wall), each with how to tell "not yet", "with help", or "on my own".

2. **Calm Breathing First**: how to breathe out slowly through the nose and mouth underwater, the bubble-humming drill, rhythmic bobbing, and what to do the moment panic starts (stand up, hold the wall, slow breathing count).

3. **Skill Ladder**: an ordered ladder from water comfort to floating, gliding, kicking, arm strokes, side breathing, and a full length. For each step give the drill, how many reps, a success sign, and a common mistake with a quick fix.

4. **Session Plans**: four to six sample 40-minute sessions, each with warm-up, two or three focus drills, a short fun game or play moment, and a cool-down, all done in water where I can stand unless I say otherwise.

5. **Moving to Deep Water**: a careful progression for later: along the wall, with a noodle, treading water near the edge, and getting out without the ladder, only with a lifeguard present.

6. **Troubleshooting Table**: symptom, likely cause, fix for at least eight problems: legs sinking, water up the nose, goggles leaking or fogging, getting tired after a few strokes, swallowing water when breathing, panic when I cannot touch the bottom, cramps, and stalled progress.

7. **Safety Rules**: a short list of non-negotiables (lifeguarded pools only, never swim alone, stay in my depth until the deep water stage, stop if dizzy or in pain, no breath-holding games or hyperventilating before going under).

8. **Progress Log**: a simple template to track date, time in the water, drills done, best float and glide time, how I felt from 1 to 5, and one win.

Rules: plain, kind language, short paragraphs and lists, metric units unless I ask otherwise, no shame about my level or age, and no promises of a fixed timeline. End with one encouraging sentence and the single drill I should do in my next session.
Turn scattered notes into a YAML handover sheet for a house or pet sitter: a timed daily schedule, pet feeding and medication, call-the-vet triggers, plants, home systems, locking up, bins, emergencies, where essentials are, contacts, and a daily log, with secrets kept out of the sheet.
1role: Calm, detail-minded home and pet care organizer2task: >3 Turn my scattered notes into a complete, easy-to-scan handover sheet as YAML for a4 house sitter or pet sitter who will stay in or visit my home while I am away: daily5 routines, pet care, plants, home systems, security, emergencies, and contacts, written so6 someone who has never been in my home can follow it without calling me.78inputs:9 trip_dates: ${dates:Friday 14:00 to the following Sunday 20:00}10 sitter_arrangement: ${arrangement:sitter stays overnight, works from home during the day}...+86 more lines
Plan a whole book club season as YAML: a balanced reading list with content notes and formats, a pace-checked meeting calendar, spoiler-aware discussion guides, facilitation tips for quiet and dominant voices, host rotation, newcomer welcome, and end-of-season feedback.
1role: Thoughtful book club organizer and discussion facilitator2task: >3 Plan a full season for a book club as YAML: a balanced reading list, a meeting4 calendar that fits the members' pace, discussion guides that go beyond "did you like it",5 hosting and rotation duties, accessibility options, and simple ways to keep members6 engaged and welcome newcomers.78inputs:9 club_name: ${club_name:Second Tuesday Readers}10 members: ${members:9 adults, mixed ages, two new this season}...+84 more lines
Turn notes and photo descriptions of a used item into a strict JSON resale package: honest condition grade with every defect disclosed, evidence-based quick sale, list and floor prices, a title and description, photo checklist, buyer FAQ, negotiation plan, and safe handover steps.
1{2 "role": "Experienced secondhand marketplace seller who writes honest, fast-selling listings and prices used items from real evidence",3 "task": "Turn my notes and photo descriptions of one used item into a complete, honest resale listing package as a single strict JSON object: condition grade, pricing with reasoning, a title and description ready for marketplaces, photo checklist, buyer FAQ, negotiation plan, and safe handover steps.",4 "context": {5 "item": "${item:standing desk with electric height adjustment}",6 "brand_and_model": "${brand_model:unknown brand, about 140 x 70 cm top}",7 "age_and_usage": "${age_usage:bought three years ago, used daily in a home office}",8 "seller_notes": "${notes:small scratch on the front edge, one motor makes a light hum, original manual lost}",9 "photo_descriptions": "${photos:front view, top surface close-up, control panel, legs at full height}",10 "original_price": "${original_price:450 EUR}",...+122 more lines
Build a positive-reinforcement eight-week puppy plan as YAML: daily schedule, house training, crate and night comfort, weekly cues, handling and safe socialization exposures, nipping help, stress signals, reward plan, household rules, progress tracker, and when to get a pro.
1role: Friendly, evidence-based puppy training and socialization planner2task: >3 Build a practical eight-week training and socialization plan for a new puppy as YAML.4 The plan uses positive reinforcement only, fits the household's daily schedule, and5 covers house training, crate or rest-area comfort, handling, basic cues, bite inhibition,6 alone time, and calm, gradual exposure to everyday sights, sounds, people, and places.78inputs:9 puppy_name: ${puppy_name:Biscuit}10 breed_or_mix: ${breed:Labrador mix}...+70 more lines
Splits shared costs for a group trip, house share, or event: equal, subset, weighted, or exact splits, mixed currencies with stated rates, and repayments already made, all in integer cents so totals match. Produces per-person balances and a short "who pays whom" list (at most one transfer fewer than people). Use when friends ask "who owes what?" after a trip or a shared house month. Includes a stdlib Python splitter with --self-test.
---
name: group-trip-expense-splitter
description: Splits shared costs for a group trip, house share, or event: equal, subset, weighted, or exact splits, mixed currencies with stated rates, and repayments already made, all in integer cents so totals match. Produces per-person balances and a short "who pays whom" list (at most one transfer fewer than people). Use when friends ask "who owes what?" after a trip or a shared house month. Includes a stdlib Python splitter with --self-test.
---

# Group Trip Expense Splitter

You help a group settle shared expenses fairly and without arguments. You collect what was bought, who paid, and who it was for, convert currencies with agreed rates, compute everyone's balance to the cent, and propose a short list of payments (never more than one fewer than the number of people) that makes everyone even. You explain every number so anyone in the group can check it.

## Files in this skill

- `scripts/split_expenses.py` - computes paid, share, and net balance per person and the settle-up transfers; supports equal, among, shares, exact, and transfer_to entries (Python 3 standard library only)
- `references/splitting-rules.md` - how to choose a split method for each kind of cost and handle common edge cases
- `references/currency-and-rounding.md` - which exchange rate to use, card fees, and how cents are rounded
- `templates/settle-up-summary.md` - a summary to paste into the group chat
- `examples/trip.json` - a 4-person weekend with a skipped dinner, student tickets, weighted drinks, USD and GBP costs, and a cash repayment

## Workflow

### 1. Collect the expenses
Ask for: the people, the settlement currency, and for each expense the description, amount, currency, who paid, and who it was for. Accept a messy list or receipts and turn it into the JSON shape in `examples/trip.json`. Ask about money that already changed hands (cash handed over, partial paybacks) and record it as `transfer_to`.

### 2. Choose the split for each item
Default is equal among everyone. Use `among` for costs that only some people shared, `shares` for "Jonas had two drinks to Maya's one", and `exact` for itemized bills. See `references/splitting-rules.md` and confirm unclear items with the group instead of guessing.

### 3. Set currency rates
Agree on one rate per currency (card statement rate, or a published rate on a stated date) and put it in `rates` as "1 unit = X settlement units". See `references/currency-and-rounding.md`.

### 4. Run the splitter
```
python3 scripts/split_expenses.py examples/trip.json
python3 scripts/split_expenses.py trip.json --json > settle.json
python3 scripts/split_expenses.py --self-test
```
Exit code 2 with a clear message for unknown names, missing rates, negative amounts, or exact splits that do not add up.

### 5. Share the result
Fill `templates/settle-up-summary.md`: total spent, each person's paid/share/net, the transfers, and the rates used. Keep it short enough for a group chat and offer the full expense table on request.

## Rules

- Never guess who shared an expense; ask, or split equally and say so.
- Totals must match to the cent; mention who received rounding cents.
- Show the exchange rates and their source; do not look up live rates silently.
- Stay neutral: present numbers, not judgments about who spent more.
- Do not handle payment credentials or send money; only list who should pay whom.
FILE:references/splitting-rules.md
# Splitting Rules and Edge Cases

## Choosing a method
| Situation | Method | Example |
|---|---|---|
| Everyone used it | equal (default) | accommodation, car rental, shared groceries |
| Only some people took part | `among` | dinner one person skipped, a tour two people joined |
| Uneven use of the same thing | `shares` | drinks, nights stayed (3 nights vs 2), fuel by distance |
| Itemized bill or different prices | `exact` | student vs adult tickets, separate menu items |
| Money already handed over | `transfer_to` | cash paid back, a bank transfer during the trip |

## Edge cases
- **Someone arrives late or leaves early.** Use `shares` by nights for the accommodation (e.g. 3, 3, 2, 3).
- **Couples or families paying as one.** Either list them as one person, or keep them separate and give children a smaller share by agreement.
- **Deposits and refunds.** Amounts must be positive, so lower the original expense by the refund. If the refund landed with someone other than the original payer, also add a `transfer_to` entry from the original payer to that person for the refunded amount, so the money they are holding counts against them.
- **Tips and service charges.** Split like the bill they belong to.
- **Gifts for one member (birthday dinner).** Use `among` with everyone except the guest.
- **Shared kitty / common pot.** Treat the kitty holder as the payer of everything bought from the pot and add each contribution as `transfer_to` the holder.
- **Personal items on a shared receipt.** Split the receipt into two entries: shared part (equal) and personal part (`exact` to that person).

## Fairness checks before sharing
1. Sum of everyone's share equals total spent.
2. Every expense has a payer who was actually there.
3. Nobody's share includes things they explicitly declined.
4. The group agreed on the rates and on any unequal splits.
FILE:references/currency-and-rounding.md
# Currency and Rounding

## Picking exchange rates
- **Best:** the rate on the payer's card or bank statement for that charge, including any foreign transaction fee, because that is what they actually paid.
- **Simple:** one published rate (for example a central bank reference rate) on a stated date for the whole trip.
- **Cash bought at an exchange office:** the rate they bought the cash at.
Write rates as "1 unit of foreign currency = X units of settlement currency": `"USD": 0.92` means 1 USD = 0.92 EUR.

## Fees
- Card foreign transaction fees (often 1-3%) are a real cost of the shared purchase; add them to the expense amount if the group agrees.
- Fees to send the settle-up money (bank or app transfer fees) are usually paid by the sender.

## Rounding to the cent
1. Each expense is converted and rounded once (half up) to whole cents.
2. The amount is split by weight; each person gets the whole cents of their exact share.
3. Leftover cents (at most one per person) go to people with the largest fractional parts, then alphabetically on ties.
This keeps every expense exact to the cent and the result reproducible. Over a trip the rounding difference per person is a few cents at most.

## Settling in more than one currency
Settle in one currency where possible. If someone must pay in another currency, convert their final transfer at a rate both sides accept and note it in the summary.
FILE:templates/settle-up-summary.md
# Settle-up - <trip or event name>

**Dates:** <dates>  **People:** <names>  **Settlement currency:** <currency>
**Total spent:** <amount> across <n> expenses  **Rates used:** <1 USD = 0.92 EUR (card statements), ...>

## Balances
| Person | Paid | Share | Net (+ gets back / - owes) |
|---|---|---|---|
| | | | |

## Who pays whom
- <name> pays <name> <amount>
- <name> pays <name> <amount>

## Notes
- Unequal splits: <dinner without Leo, student tickets, drinks by count>
- Rounding cents went to: <names>
- Already settled during the trip: <cash or transfers>

## Group chat message
> Trip totals are in! We spent <total> together. To settle up: <transfer 1>; <transfer 2>; <transfer 3>. Full breakdown is in the thread. Shout if anything looks off by <date>.
FILE:examples/trip.json
{
  "trip": "Lisbon long weekend, 4 friends",
  "currency": "EUR",
  "rates": {"USD": 0.92, "GBP": 1.17},
  "people": ["Maya", "Jonas", "Priya", "Leo"],
  "expenses": [
    {"desc": "Apartment, 3 nights", "amount": 486.00, "paid_by": "Maya"},
    {"desc": "Airport taxi", "amount": 38.50, "paid_by": "Jonas"},
    {"desc": "Groceries for breakfasts", "amount": 61.27, "paid_by": "Priya"},
    {"desc": "Seafood dinner (Leo skipped)", "amount": 142.80, "paid_by": "Jonas", "among": ["Maya", "Jonas", "Priya"]},
    {"desc": "Sintra day tour, booked online", "amount": 196.00, "currency": "USD", "paid_by": "Leo"},
    {"desc": "Fado show (Priya and Leo have student tickets)", "amount": 84.00, "paid_by": "Maya", "exact": {"Maya": 25, "Jonas": 25, "Priya": 17, "Leo": 17}},
    {"desc": "Wine and pastel de nata tasting", "amount": 72.00, "paid_by": "Priya", "shares": {"Maya": 1, "Jonas": 2, "Priya": 1, "Leo": 2}},
    {"desc": "Tram and metro cards", "amount": 26.40, "currency": "GBP", "paid_by": "Leo"},
    {"desc": "Cash Jonas already handed Maya on day 2", "amount": 30.00, "paid_by": "Jonas", "transfer_to": "Maya"}
  ]
}
FILE:scripts/split_expenses.py
#!/usr/bin/env python3
"""Group trip expense splitter and settle-up planner (Python 3 standard library only).

Input JSON:
{
  "currency": "EUR",                         # settlement currency
  "rates": {"USD": 0.92, "TRY": 0.027},      # 1 unit of key = rate units of settlement currency
  "people": ["Ana", "Ben", "Cem", "Dee"],
  "expenses": [
    {"desc": "Villa", "amount": 1200, "paid_by": "Ana"},                                 # equal, everyone
    {"desc": "Dinner", "amount": 180, "paid_by": "Ben", "among": ["Ana", "Ben", "Cem"]},   # equal, subset
    {"desc": "Boat", "amount": 300, "currency": "USD", "paid_by": "Cem",
     "shares": {"Ana": 2, "Ben": 1, "Cem": 1}},                                         # weighted
    {"desc": "Museum", "amount": 54, "paid_by": "Dee", "exact": {"Dee": 18, "Ana": 36}},  # exact amounts
    {"desc": "Ana pays Ben back", "amount": 50, "paid_by": "Ana", "transfer_to": "Ben"}   # direct repayment
  ]
}
All math is done in integer cents. Rounding remainders go to participants in a fixed order (largest
fractional part first, then name), so totals always match to the cent and results are reproducible.
Settle-up uses a greedy largest-creditor / largest-debtor match, which needs at most n-1 transfers.

Usage:
  python3 split_expenses.py trip.json
  python3 split_expenses.py trip.json --json
  python3 split_expenses.py --self-test
Exit code: 0 OK, 2 bad input.
"""
import argparse
import json
import sys
from decimal import Decimal, ROUND_HALF_UP


class SplitError(ValueError):
    pass


def to_cents(amount, rate=Decimal(1)):
    try:
        d = Decimal(str(amount)) * Decimal(str(rate)) * 100
    except Exception:
        raise SplitError(f"bad amount {amount!r}")
    return int(d.quantize(Decimal(1), rounding=ROUND_HALF_UP))


def fmt(cents, cur):
    sign = "-" if cents < 0 else ""
    return f"{sign}{abs(cents) // 100:,}.{abs(cents) % 100:02d} {cur}"


def allocate(total, weights):
    """Split integer total by weights {name: weight}; largest-remainder method, ties by name."""
    wsum = sum(weights.values())
    if wsum <= 0:
        raise SplitError("weights must sum to more than zero")
    raw = {n: Decimal(total) * Decimal(str(w)) / Decimal(str(wsum)) for n, w in weights.items()}
    base = {n: int(v) for n, v in raw.items()}
    left = total - sum(base.values())
    order = sorted(weights, key=lambda n: (-(raw[n] - base[n]), n))
    for n in order[:left]:
        base[n] += 1
    return base


def compute(data):
    cur = data.get("currency") or "EUR"
    rates = {k.upper(): v for k, v in (data.get("rates") or {}).items()}
    people = data.get("people") or []
    if len(people) < 2:
        raise SplitError("need at least two people")
    if len(set(people)) != len(people):
        raise SplitError("duplicate names in people")
    known = set(people)
    paid = {p: 0 for p in people}
    owed = {p: 0 for p in people}
    lines = []
    for i, e in enumerate(data.get("expenses") or [], start=1):
        desc = e.get("desc") or f"expense {i}"
        payer = e.get("paid_by")
        if payer not in known:
            raise SplitError(f"{desc}: paid_by {payer!r} is not in people")
        ecur = (e.get("currency") or cur).upper()
        if ecur == cur.upper():
            rate = 1
        elif ecur in rates:
            rate = rates[ecur]
        else:
            raise SplitError(f"{desc}: no rate for {ecur} -> {cur}; add it to 'rates'")
        total = to_cents(e.get("amount"), rate)
        if total <= 0:
            raise SplitError(f"{desc}: amount must be positive")
        modes = [k for k in ("among", "shares", "exact", "transfer_to") if k in e]
        if len(modes) > 1:
            raise SplitError(f"{desc}: use only one of among / shares / exact / transfer_to")
        if "transfer_to" in e:
            to = e["transfer_to"]
            if to not in known or to == payer:
                raise SplitError(f"{desc}: transfer_to must be another person")
            split = {to: total}
        elif "exact" in e:
            ex = e["exact"]
            for n in ex:
                if n not in known:
                    raise SplitError(f"{desc}: unknown person {n!r}")
            split = {n: to_cents(v, rate) for n, v in ex.items()}
            diff = total - sum(split.values())
            if abs(diff) > len(split):  # allow only currency-conversion rounding
                raise SplitError(f"{desc}: exact amounts add up to {fmt(sum(split.values()), cur)}, not {fmt(total, cur)}")
            if diff:
                split[sorted(split)[0]] += diff
        elif "shares" in e:
            sh = e["shares"]
            for n, w in sh.items():
                if n not in known:
                    raise SplitError(f"{desc}: unknown person {n!r}")
                if float(w) < 0:
                    raise SplitError(f"{desc}: negative share for {n}")
            split = allocate(total, {n: w for n, w in sh.items() if float(w) > 0})
        else:
            among = e.get("among") or people
            for n in among:
                if n not in known:
                    raise SplitError(f"{desc}: unknown person {n!r}")
            split = allocate(total, {n: 1 for n in among})
        paid[payer] += total
        for n, c in split.items():
            owed[n] += c
        lines.append({"desc": desc, "paid_by": payer, "amount": total, "original": f"{e.get('amount')} {ecur}",
                      "split": split, "kind": modes[0] if modes else "equal"})
    net = {p: paid[p] - owed[p] for p in people}
    assert sum(net.values()) == 0, "internal error: balances do not sum to zero"
    return {"currency": cur, "people": people, "expenses": lines, "paid": paid, "owed": owed,
            "net": net, "transfers": settle(net),
            "total_spent": sum(l["amount"] for l in lines if l["kind"] != "transfer_to")}


def settle(net):
    cred = sorted([[c, n] for n, c in net.items() if c > 0], key=lambda x: (-x[0], x[1]))
    debt = sorted([[-c, n] for n, c in net.items() if c < 0], key=lambda x: (-x[0], x[1]))
    out = []
    while cred and debt:
        amt = min(cred[0][0], debt[0][0])
        out.append({"from": debt[0][1], "to": cred[0][1], "amount": amt})
        cred[0][0] -= amt
        debt[0][0] -= amt
        cred = sorted([x for x in cred if x[0] > 0], key=lambda x: (-x[0], x[1]))
        debt = sorted([x for x in debt if x[0] > 0], key=lambda x: (-x[0], x[1]))
    return out


def to_markdown(r):
    c = r["currency"]
    lines = ["# Trip settle-up", "", f"Total spent: {fmt(r['total_spent'], c)} across {len([e for e in r['expenses'] if e['kind'] != 'transfer_to'])} expenses", "",
             "## Expenses", "| # | Expense | Paid by | Amount | Split |", "|---|---|---|---|---|"]
    for i, e in enumerate(r["expenses"], 1):
        split = ", ".join(f"{n} {fmt(v, c)}" for n, v in sorted(e["split"].items()))
        conv = "" if e["original"].endswith(c.upper()) else f" ({e['original']})"
        lines.append(f"| {i} | {e['desc']} | {e['paid_by']} | {fmt(e['amount'], c)}{conv} | {e['kind']}: {split} |")
    lines += ["", "## Balances", "| Person | Paid | Share | Net |", "|---|---|---|---|"]
    for p in r["people"]:
        lines.append(f"| {p} | {fmt(r['paid'][p], c)} | {fmt(r['owed'][p], c)} | {fmt(r['net'][p], c)} |")
    lines += ["", "## Who pays whom"]
    if not r["transfers"]:
        lines.append("Everyone is even.")
    lines += [f"- {t['from']} pays {t['to']} {fmt(t['amount'], c)}" for t in r["transfers"]]
    return "\n".join(lines)


def self_test():
    cases = []

    def ok(name, cond):
        cases.append((name, bool(cond)))

    base = {"currency": "EUR", "people": ["Ana", "Ben", "Cem"]}
    r = compute(dict(base, expenses=[{"desc": "Taxi", "amount": 10, "paid_by": "Ana"}]))
    ok("10.00 split three ways sums exactly", sum(r["owed"].values()) == 1000 and sorted(r["owed"].values()) == [333, 333, 334])
    ok("remainder cent goes to first name on tie", r["owed"]["Ana"] == 334)
    ok("two transfers to the payer", sorted((t["from"], t["amount"]) for t in r["transfers"]) == [("Ben", 333), ("Cem", 333)])
    r = compute(dict(base, expenses=[{"desc": "A", "amount": 30, "paid_by": "Ana"}, {"desc": "B", "amount": 30, "paid_by": "Ben"}, {"desc": "C", "amount": 30, "paid_by": "Cem"}]))
    ok("equal spending means no transfers", r["transfers"] == [])
    r = compute(dict(base, expenses=[{"desc": "Dinner", "amount": 90, "paid_by": "Ben", "among": ["Ana", "Ben"]}]))
    ok("subset split excludes others", r["owed"]["Cem"] == 0 and r["net"]["Ana"] == -4500)
    r = compute(dict(base, expenses=[{"desc": "Boat", "amount": 100, "paid_by": "Cem", "shares": {"Ana": 2, "Ben": 1, "Cem": 1}}]))
    ok("weighted shares", r["owed"] == {"Ana": 5000, "Ben": 2500, "Cem": 2500})
    r = compute(dict(base, expenses=[{"desc": "Tickets", "amount": 50, "paid_by": "Ana", "exact": {"Ben": 20, "Cem": 30}}]))
    ok("exact amounts", r["net"] == {"Ana": 5000, "Ben": -2000, "Cem": -3000})
    r = compute(dict(base, rates={"USD": 0.9}, expenses=[{"desc": "Gas", "amount": 30, "currency": "USD", "paid_by": "Ben"}]))
    ok("currency conversion to cents", r["paid"]["Ben"] == 2700 and sum(r["owed"].values()) == 2700)
    r = compute(dict(base, expenses=[{"desc": "Hotel", "amount": 300, "paid_by": "Ana"}, {"desc": "Payback", "amount": 100, "paid_by": "Ben", "transfer_to": "Ana"}]))
    ok("direct repayment reduces debt", r["net"] == {"Ana": 10000, "Ben": 0, "Cem": -10000})
    ok("repayment not counted as spending", r["total_spent"] == 30000)
    big = {"currency": "EUR", "people": ["A", "B", "C", "D", "E"],
           "expenses": [{"desc": f"x{i}", "amount": 17.33 * (i + 1), "paid_by": "ABCDE"[i % 5], "among": list("ABCDE"[: 2 + i % 4])} for i in range(12)]}
    r = compute(big)
    ok("balances sum to zero", sum(r["net"].values()) == 0)
    ok("at most n-1 transfers", len(r["transfers"]) <= 4)
    after = dict(r["net"])
    for t in r["transfers"]:
        after[t["from"]] += t["amount"]
        after[t["to"]] -= t["amount"]
    ok("transfers settle everyone to zero", all(v == 0 for v in after.values()))
    ok("deterministic output", compute(big)["transfers"] == r["transfers"])
    bad_inputs = [
        (dict(base, expenses=[{"desc": "X", "amount": 10, "paid_by": "Zed"}]), "unknown payer rejected"),
        (dict(base, expenses=[{"desc": "X", "amount": 10, "currency": "GBP", "paid_by": "Ana"}]), "missing rate rejected"),
        (dict(base, expenses=[{"desc": "X", "amount": 10, "paid_by": "Ana", "exact": {"Ben": 3}}]), "exact mismatch rejected"),
        (dict(base, expenses=[{"desc": "X", "amount": -5, "paid_by": "Ana"}]), "negative amount rejected"),
        ({"people": ["Solo"], "expenses": []}, "single person rejected"),
    ]
    for data, label in bad_inputs:
        try:
            compute(data)
            ok(label, False)
        except SplitError:
            ok(label, True)
    ok("markdown has settle-up section", "## Who pays whom" in to_markdown(compute(dict(base, expenses=[{"desc": "Taxi", "amount": 10, "paid_by": "Ana"}]))))
    passed = sum(c for _, c in cases)
    for name, c in cases:
        print(("PASS " if c else "FAIL ") + name)
    print(f"{passed}/{len(cases)} passed")
    return 0 if passed == len(cases) else 1


def main(argv=None):
    ap = argparse.ArgumentParser(description="Split shared trip expenses and plan a short list of settle-up transfers.")
    ap.add_argument("file", nargs="?", help="trip JSON file, or '-' for stdin")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args(argv)
    if a.self_test:
        return self_test()
    if not a.file:
        ap.error("trip JSON required (or --self-test)")
    try:
        data = json.load(sys.stdin if a.file == "-" else open(a.file, encoding="utf-8"))
        r = compute(data)
    except (OSError, ValueError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(r, indent=2, ensure_ascii=False) if a.json else to_markdown(r))
    return 0


if __name__ == "__main__":
sys.exit(main())Plans a fair, rotating weekly chore schedule for a household: weighs each chore by minutes and frequency, respects capacity shares and "cannot do" limits, rotates jobs week to week, and reports each person's load against a fair target. Use when roommates or families argue about chores or ask "who does what this month?". Includes a stdlib Python planner with --self-test.
---
name: household-chore-rotation-planner
description: Plans a fair, rotating weekly chore schedule for a household: weighs each chore by minutes and frequency, respects capacity shares and "cannot do" limits, rotates jobs week to week, and reports each person's load against a fair target. Use when roommates or families argue about chores or ask "who does what this month?". Includes a stdlib Python planner with --self-test.
---

# Household Chore Rotation Planner

You help households (roommates, couples, families with kids) split chores fairly and rotate them so nobody is stuck with the worst jobs forever. You measure fairness in minutes, not in number of tasks, adjust for each person's capacity, respect real limits (age, allergies, health, skills), and produce a schedule people can stick on the fridge. You stay neutral and kind; you never take sides in a household argument.

## Files in this skill

- `scripts/chore_rotation.py` - builds a multi-week rotation from a JSON list of people and chores and reports minutes vs fair target per person (Python 3 standard library only)
- `references/chore-time-estimates.md` - typical minutes for common chores to use as defaults
- `references/fairness-and-agreements.md` - how to set shares, handle swaps, and run a short house meeting
- `templates/rotation-chart.md` - printable weekly chart plus a house agreement section
- `examples/household.json` - four-person sample household with constraints

## Workflow

### 1. Gather the household
Ask for:
- People and their capacity: full share (1.0), reduced share (for example 0.5 for a young child or someone working night shifts), or larger share by agreement
- Hard limits: chores someone cannot do (`cannot`), or chores only certain people can do (`only`, for example cooking or driving)
- Chores with realistic minutes per session and times per week; use `references/chore-time-estimates.md` when unsure
- How many weeks to plan (4 is a good default) and any preferences ("I would rather cook than clean the bathroom")

### 2. Build the input and run the planner
```
python3 scripts/chore_rotation.py examples/household.json
python3 scripts/chore_rotation.py my-house.json --weeks 6 --json
python3 scripts/chore_rotation.py --self-test
```
Exit code 1 means a chore has no eligible person (fix the `cannot`/`only` lists); 2 means bad input.

### 3. Check fairness
Read the "Overall fairness" table. Within about 10% of target is good. If someone is far off, adjust minutes, split a big chore (for example "Laundry - wash" and "Laundry - fold"), or change shares by agreement, then rerun.

### 4. Apply preferences
The planner balances minutes; it does not know who hates what. Offer swaps of similar minutes between people, and keep the totals close. If a heavy chore lands on the same person every week because of constraints, say so and suggest splitting it.

### 5. Deliver
Fill `templates/rotation-chart.md` with the weekly tables, a short house agreement (swap rules, what "done" means, a monthly check-in), and a friendly group message under 80 words announcing the plan.

## Rules

- Fairness is measured in minutes weighted by agreed shares, not task counts.
- Never assign unsafe chores to children (sharp tools, strong chemicals, ladders, hot ovens without supervision).
- Keep the tone neutral; describe loads with numbers, not blame.
- Invisible work counts: planning meals, booking repairs, and buying supplies can be added as chores with minutes.
FILE:references/chore-time-estimates.md
# Typical chore times (defaults, adjust to your home)

| Chore | Minutes per session | Common frequency |
|---|---|---|
| Dishes / load and unload dishwasher | 15-25 | daily |
| Cook dinner | 30-60 | 3-7 per week |
| Meal planning and grocery list | 20-30 | weekly |
| Grocery run | 45-75 | weekly |
| Laundry (wash, dry, fold, put away) | 40-60 per load | 2-4 loads per week |
| Bathroom clean (sink, toilet, shower, floor) | 30-45 | weekly |
| Kitchen deep clean (counters, stovetop, fridge wipe) | 30-40 | weekly |
| Vacuum and mop | 30-45 | 1-2 per week |
| Dusting | 15-20 | weekly |
| Trash and recycling out | 5-10 | 2-3 per week |
| Change bed linens | 15 per bed | every 1-2 weeks |
| Water plants | 5-15 | 2 per week |
| Pet feeding | 5 | daily, often twice |
| Litter box / pet cleanup | 5 | daily |
| Dog walk | 20-30 | 1-3 per day |
| Mow lawn | 40-60 | weekly in season |
| Clean oven | 30-45 | monthly |
| Pay bills and admin | 20-30 | weekly |

Tips
- Time one session with a phone timer if people disagree about how long a chore takes.
- Split chores that are both long and unpopular so they can rotate more easily.
- Seasonal chores (snow shoveling, gutters) can be added only for the weeks they apply.
FILE:references/fairness-and-agreements.md
# Fairness and house agreements

## Setting shares
- Start everyone at 1.0. Lower shares only by explicit agreement (age, health, very long work hours, exams).
- Children: roughly 0.25-0.5 with age-appropriate chores only.
- Someone who pays more rent or does more invisible work may get a lower chore share; write it down.

## What "done" means
Agree on a one-line definition per chore, for example "Dishes: sink empty, counters wiped, dishwasher running".

## Swaps
- Swaps are fine if both people agree and minutes are similar.
- Post swaps in the group chat so nobody is surprised.
- A missed chore is made up within 48 hours or swapped, not silently skipped.

## 15-minute monthly check-in
1. Each person: one thing working, one thing not (2 minutes each).
2. Look at the fairness table; adjust minutes or shares if reality changed.
3. Decide on one improvement for next month.
4. Regenerate the rotation.

## Handling conflict
- Talk about the system, not the person ("Bathroom keeps slipping on Thursdays" instead of "You never clean").
- If one person carries far more invisible work, add it to the chore list with minutes.
FILE:templates/rotation-chart.md
# Chore Rotation - <household name>

**Period:** <start date> to <end date>  **People:** <names and shares>

## Week 1 (<dates>)
| Chore | Who | Done? |
|---|---|---|
| | | [ ] |

## Week 2 (<dates>)
| Chore | Who | Done? |
|---|---|---|
| | | [ ] |

## Fairness (minutes)
| Person | Share | Minutes | Target | Deviation |
|---|---|---|---|---|

## House agreement
- "Done" means:
- Swap rule:
- Missed chore rule:
- Monthly check-in date:

## Group message
> Hi all! New chore rotation for <period> is on the fridge and pinned here. Loads are balanced by time. Swaps are fine, just post them. Check-in on <date>.
FILE:examples/household.json
{
  "weeks": 4,
  "people": [
    {"name": "Leyla", "share": 1.0},
    {"name": "Tom", "share": 1.0, "cannot": ["Litter box"]},
    {"name": "Deniz", "share": 0.5, "cannot": ["Clean oven", "Mow lawn"]},
    {"name": "Sam", "share": 0.75}
  ],
  "chores": [
    {"name": "Dishes", "minutes": 20, "times_per_week": 7},
    {"name": "Cook dinner", "minutes": 45, "times_per_week": 3, "only": ["Leyla", "Tom", "Sam"]},
    {"name": "Laundry", "minutes": 40, "times_per_week": 2},
    {"name": "Bathroom clean", "minutes": 40, "times_per_week": 1},
    {"name": "Vacuum and mop", "minutes": 35, "times_per_week": 2},
    {"name": "Trash and recycling", "minutes": 10, "times_per_week": 3},
    {"name": "Grocery run", "minutes": 60, "times_per_week": 1},
    {"name": "Litter box", "minutes": 5, "times_per_week": 7},
    {"name": "Water plants", "minutes": 10, "times_per_week": 2},
    {"name": "Mow lawn", "minutes": 50, "times_per_week": 1},
    {"name": "Clean oven", "minutes": 30, "times_per_week": 1}
  ]
}
FILE:scripts/chore_rotation.py
#!/usr/bin/env python3
"""Fair household chore rotation planner (Python 3 standard library only).

Input JSON:
{
  "weeks": 4,
  "people": [{"name": "Ana", "share": 1.0, "cannot": ["Mow lawn"]}, ...],
  "chores": [{"name": "Dishes", "minutes": 20, "times_per_week": 7, "only": ["Ana", "Ben"]}, ...]
}
  share: relative capacity (1.0 = normal; 0.5 = half load, e.g. a child or someone with long shifts)
  cannot / only: hard constraints (allergies, age, physical limits, skills)

Algorithm per week: chores sorted by weekly minutes (largest first) go to the eligible person with the
lowest (load / share); ties are broken in favor of someone who did NOT have that chore last week,
so chores rotate. Reports per-person minutes, target minutes, and deviation.
Exit code: 0 OK, 1 if a chore has no eligible person, 2 on bad input.
"""
import argparse
import json
import sys


class PlanError(ValueError):
    pass


def validate(data):
    people = data.get("people") or []
    chores = data.get("chores") or []
    if not people:
        raise PlanError("need at least one person")
    if not chores:
        raise PlanError("need at least one chore")
    names = [p["name"] for p in people]
    if len(set(names)) != len(names):
        raise PlanError("duplicate person names")
    for p in people:
        if float(p.get("share", 1.0)) <= 0:
            raise PlanError(f"share must be > 0 for {p['name']}")
    for c in chores:
        if float(c.get("minutes", 0)) <= 0 or float(c.get("times_per_week", 1)) <= 0:
            raise PlanError(f"minutes and times_per_week must be > 0 for {c.get('name')}")
        for n in c.get("only", []):
            if n not in names:
                raise PlanError(f"chore {c['name']} lists unknown person {n}")
    return people, chores


def weekly_minutes(chore):
    return float(chore["minutes"]) * float(chore.get("times_per_week", 1))


def eligible(person, chore):
    if chore.get("only") and person["name"] not in chore["only"]:
        return False
    return chore["name"] not in person.get("cannot", [])


def plan_week(people, chores, last_week=None):
    """Return (assignment {chore: person}, loads {person: minutes}, unassigned [chore])."""
    last_week = last_week or {}
    loads = {p["name"]: 0.0 for p in people}
    assignment = {}
    unassigned = []
    order = sorted(chores, key=lambda c: (-weekly_minutes(c), c["name"]))
    for c in order:
        cands = [p for p in people if eligible(p, c)]
        if not cands:
            unassigned.append(c["name"])
            continue
        w = weekly_minutes(c)

        def key(p):
            share = float(p.get("share", 1.0))
            after = (loads[p["name"]] + w) / share
            repeat = 1 if last_week.get(c["name"]) == p["name"] else 0
            return (round(after, 6), repeat, p["name"])

        # prefer rotation when loads are close: compare within a 10% band of the best option
        ranked = sorted(cands, key=key)
        best = key(ranked[0])[0]
        band = [p for p in ranked if key(p)[0] <= best * 1.10 + 1e-9]
        band.sort(key=lambda p: (key(p)[1], key(p)[0], p["name"]))
        chosen = band[0]
        assignment[c["name"]] = chosen["name"]
        loads[chosen["name"]] += w
    return assignment, loads, unassigned


def fairness(people, loads):
    total = sum(loads.values())
    total_share = sum(float(p.get("share", 1.0)) for p in people)
    rows = []
    for p in people:
        target = total * float(p.get("share", 1.0)) / total_share
        got = loads[p["name"]]
        dev = (got - target) / target * 100 if target else 0.0
        rows.append({"name": p["name"], "minutes": round(got, 1), "target": round(target, 1),
                     "deviation_pct": round(dev, 1)})
    return rows


def plan(data):
    people, chores = validate(data)
    weeks = int(data.get("weeks", 4))
    result = []
    cumulative = {p["name"]: 0.0 for p in people}
    last = None
    for wk in range(1, weeks + 1):
        assignment, loads, unassigned = plan_week(people, chores, last)
        for k, v in loads.items():
            cumulative[k] += v
        result.append({"week": wk, "assignment": assignment, "fairness": fairness(people, loads),
                       "unassigned": unassigned})
        last = assignment
    return {"weeks": result, "overall": fairness(people, cumulative)}


def render(res):
    out = []
    for w in res["weeks"]:
        out.append(f"## Week {w['week']}")
        out.append("| Chore | Who |")
        out.append("|---|---|")
        for chore, who in sorted(w["assignment"].items()):
            out.append(f"| {chore} | {who} |")
        for u in w["unassigned"]:
            out.append(f"| {u} | UNASSIGNED (no eligible person) |")
        out.append("")
    out.append("## Overall fairness (minutes across all weeks)")
    out.append("| Person | Minutes | Target | Deviation |")
    out.append("|---|---|---|---|")
    for r in res["overall"]:
        out.append(f"| {r['name']} | {r['minutes']} | {r['target']} | {r['deviation_pct']:+.1f}% |")
    return "\n".join(out)


def self_test():
    base = {
        "weeks": 4,
        "people": [{"name": "Ana"}, {"name": "Ben"}, {"name": "Cem", "share": 0.5, "cannot": ["Mow lawn"]}],
        "chores": [
            {"name": "Dishes", "minutes": 20, "times_per_week": 7},
            {"name": "Laundry", "minutes": 60, "times_per_week": 2},
            {"name": "Bathroom", "minutes": 45, "times_per_week": 1},
            {"name": "Vacuum", "minutes": 30, "times_per_week": 2},
            {"name": "Trash", "minutes": 5, "times_per_week": 3},
            {"name": "Mow lawn", "minutes": 50, "times_per_week": 1},
            {"name": "Feed cat", "minutes": 5, "times_per_week": 14, "only": ["Cem", "Ana"]},
        ],
    }
    res = plan(base)
    w1 = res["weeks"][0]["assignment"]
    lawn_never_cem = all(w["assignment"]["Mow lawn"] != "Cem" for w in res["weeks"])
    cat_ok = all(w["assignment"]["Feed cat"] in ("Cem", "Ana") for w in res["weeks"])
    dishes_people = {w["assignment"]["Dishes"] for w in res["weeks"]}
    overall = {r["name"]: r for r in res["overall"]}
    max_dev = max(abs(r["deviation_pct"]) for r in res["overall"])
    two = plan({"weeks": 2, "people": [{"name": "A"}, {"name": "B"}],
                "chores": [{"name": "X", "minutes": 10}, {"name": "Y", "minutes": 10}]})
    rotated = two["weeks"][0]["assignment"]["X"] != two["weeks"][1]["assignment"]["X"]
    orphan = plan({"weeks": 1, "people": [{"name": "A", "cannot": ["Z"]}], "chores": [{"name": "Z", "minutes": 5}]})
    errors = []
    for bad in ({"people": [], "chores": [{"name": "x", "minutes": 1}]},
                {"people": [{"name": "A"}, {"name": "A"}], "chores": [{"name": "x", "minutes": 1}]},
                {"people": [{"name": "A", "share": 0}], "chores": [{"name": "x", "minutes": 1}]},
                {"people": [{"name": "A"}], "chores": [{"name": "x", "minutes": 0}]},
                {"people": [{"name": "A"}], "chores": [{"name": "x", "minutes": 1, "only": ["Q"]}]}):
        try:
            plan(bad)
            errors.append(False)
        except PlanError:
            errors.append(True)
    cases = [
        ("all_chores_assigned_w1", len(w1), 7),
        ("weekly_minutes", weekly_minutes(base["chores"][0]), 140.0),
        ("cannot_respected", lawn_never_cem, True),
        ("only_respected", cat_ok, True),
        ("dishes_rotate", len(dishes_people) >= 2, True),
        ("half_share_lower_load", overall["Cem"]["minutes"] < overall["Ana"]["minutes"], True),
        ("overall_fair_within_25pct", max_dev <= 25.0, True),
        ("targets_sum_to_total", round(sum(r["target"] for r in res["overall"]), 0) == round(sum(r["minutes"] for r in res["overall"]), 0), True),
        ("equal_tie_rotates", rotated, True),
        ("orphan_reported", orphan["weeks"][0]["unassigned"], ["Z"]),
        ("bad_inputs_rejected", errors, [True] * 5),
        ("render_has_header", render(res).startswith("## Week 1"), True),
    ]
    failed = 0
    for name, got, expected in cases:
        ok = got == expected
        failed += not ok
        print(f"{'PASS' if ok else 'FAIL'}  {name}: got={got!r} expected={expected!r}")
    print(f"\n{len(cases) - failed}/{len(cases)} passed")
    return 1 if failed else 0


def main(argv=None):
    p = argparse.ArgumentParser(description="Plan a fair, rotating household chore schedule.")
    p.add_argument("input", nargs="?", help="JSON file with weeks, people, chores")
    p.add_argument("--weeks", type=int, help="override number of weeks")
    p.add_argument("--json", action="store_true")
    p.add_argument("--self-test", action="store_true")
    a = p.parse_args(argv)
    if a.self_test:
        return self_test()
    if not a.input:
        p.error("give an input JSON file, or --self-test")
    try:
        with open(a.input, encoding="utf-8") as fh:
            data = json.load(fh)
        if a.weeks:
            data["weeks"] = a.weeks
        res = plan(data)
    except (OSError, json.JSONDecodeError, PlanError, KeyError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(res, indent=2) if a.json else render(res))
    return 1 if any(w["unassigned"] for w in res["weeks"]) else 0


if __name__ == "__main__":
sys.exit(main())Scans a codebase for TODO, FIXME, HACK, and XXX comments, extracts owner, ticket, and due date, and flags unowned, untracked, overdue, or vague items with a priority score. Use when cleaning up tech debt, before a release, or asking "which TODOs actually matter?". Includes a stdlib Python scanner with --self-test and a CI-friendly exit code.
---
name: todo-comment-debt-tracker
description: Scans a codebase for TODO, FIXME, HACK, and XXX comments, extracts owner, ticket, and due date, and flags unowned, untracked, overdue, or vague items with a priority score. Use when cleaning up tech debt, before a release, or asking "which TODOs actually matter?". Includes a stdlib Python scanner with --self-test and a CI-friendly exit code.
---

# TODO Comment Debt Tracker

You help teams turn scattered TODO, FIXME, HACK, and XXX comments into a short, owned, prioritized debt list. You scan the code, parse who owns each item, which ticket tracks it, and when it is due, then highlight the ones that are risky or forgotten. You never delete or rewrite comments on your own; you propose changes and let the team decide.

## Files in this skill

- `scripts/todo_debt.py` - scans files or directories, parses owner/ticket/due date, scores each item, and prints a markdown table or JSON (Python 3 standard library only)
- `references/comment-conventions.md` - a recommended TODO format and how to adopt it without churn
- `references/triage-rules.md` - how to decide fix now, ticket, or delete
- `templates/debt-report.md` - report for a sprint review, release checklist, or PR comment
- `examples/sample_service.py` - a small file with typical good and bad TODOs for demos

## Workflow

### 1. Scope the scan
Ask which directories matter and what to skip (generated code, vendored libraries, fixtures). The script already skips `.git`, `node_modules`, `vendor`, `dist`, `build`, virtualenvs, and `target`.

### 2. Run the scanner
```
python3 scripts/todo_debt.py src/ --today 2026-10-18
python3 scripts/todo_debt.py src/ tests/ --ext .py,.ts --json > todo-debt.json
python3 scripts/todo_debt.py examples/sample_service.py --strict
python3 scripts/todo_debt.py --self-test
```
Exit code 1 when an item is overdue or a FIXME/HACK/XXX has no ticket (`--strict`: any problem). Use it as a soft CI gate or a weekly report job.

### 3. Read the problems
- **overdue**: due date passed. Highest priority.
- **no_ticket**: nothing tracks the work; it will be forgotten.
- **stale_hack**: a HACK or XXX with no ticket, often a workaround that outlived its reason.
- **no_owner**: nobody is responsible.
- **vague**: fewer than three words, such as "TODO: fix".

Scores: FIXME/HACK/XXX start at 3, TODO at 1; +2 if overdue, +1 if no ticket.

### 4. Triage with the team
Apply `references/triage-rules.md`: fix now if it is under 30 minutes, create a ticket and add its id if it is real work, delete it if it is obsolete. Use `git blame` on the line to find a likely owner when none is written.

### 5. Report
Fill `templates/debt-report.md` with the top items, totals by marker and owner, and agreed actions. Suggest the convention in `references/comment-conventions.md` for new comments.

## Rules

- Do not count markers inside string literals or plain prose; only comments.
- Never invent ticket numbers or owners; mark them unknown and suggest how to find them.
- Do not remove comments in bulk without review; propose a patch instead.
- Respect generated and vendored code: report it separately or skip it.
FILE:references/comment-conventions.md
# Recommended TODO convention

```
# TODO(owner, TICKET-123, 2026-12-01): what needs to happen and why
```

- **owner**: a username or team handle (`alice`, `@payments-team`). One name, the person who will make the call.
- **ticket**: `#123`, `PROJ-123`, or a full issue URL. Required for FIXME, HACK, and XXX.
- **due date**: ISO `YYYY-MM-DD`, optional for TODO, recommended for HACK workarounds.
- **text**: an action plus the reason, at least a short sentence. "TODO: fix" is not useful.

## Which marker to use
| Marker | Meaning | Ticket required? |
|---|---|---|
| TODO | Planned improvement, not wrong today | Recommended |
| FIXME | Known bug or incorrect behavior | Yes |
| HACK | Deliberate workaround that should be removed | Yes, plus a due date |
| XXX | Danger, surprising code, review needed | Yes |

## Adopting without churn
1. Run the scanner and publish the report; do not mass-edit.
2. Apply the convention to new comments via code review or a lint rule.
3. Fix old comments when you touch that code anyway.
4. Revisit the totals monthly; aim for "no overdue, no untracked FIXME".
FILE:references/triage-rules.md
# Triage rules

For each item, ask in order:

1. **Is it still true?** Read the surrounding code and `git log -L` for the lines. If the issue is gone, delete the comment.
2. **Is it under 30 minutes?** Fix it now in a small PR that removes the comment.
3. **Is it a bug or a risk?** (FIXME/XXX, security, data loss, money) Create a ticket with priority, add the ticket id to the comment, and assign an owner.
4. **Is it a workaround?** (HACK) Write down the condition that allows removal ("remove after vendor SDK 5.x") and a due date.
5. **Is it a wish?** If nobody would schedule it in the next two quarters, delete it or move it to a backlog ticket.

## Priority hints
- Overdue items first, then FIXME/HACK/XXX without tickets, then unowned items in hot files (high churn).
- Items in auth, payments, data migrations, or concurrency code deserve a closer look regardless of score.

## Finding an owner
- `git blame -L <line>,<line> <file>` shows who added it; that person or their team is the default owner.
- CODEOWNERS files map paths to teams.
- If the author has left, assign to the current maintainer of the module.
FILE:templates/debt-report.md
# TODO Debt Report

**Repository:** <name>  **Scanned:** <paths>  **Date:** <YYYY-MM-DD>

## Totals
| Marker | Count | Overdue | No ticket | No owner |
|---|---|---|---|---|
| TODO | | | | |
| FIXME | | | | |
| HACK | | | | |
| XXX | | | | |

## Top 10 by score
| Score | Location | Marker | Owner | Ticket | Due | Problems | Proposed action |
|---|---|---|---|---|---|---|---|
| | | | | | | | |

## By owner
| Owner | Items | Overdue |
|---|---|---|

## Agreed actions
- [ ] Fix now:
- [ ] Ticket created:
- [ ] Delete (obsolete):

## Convention reminder
`# TODO(owner, TICKET-123, YYYY-MM-DD): action and reason`
FILE:examples/sample_service.py
"""Sample order service with typical TODO comments for demos of todo_debt.py."""
import json

TAX_RATE = 0.2  # XXX(PAY-311): confirm tax rate per region with finance


def load_orders(path):
    # TODO(maria, 2026-03-01): switch to streaming parser once files exceed 50 MB (#88)
    with open(path, encoding="utf-8") as fh:
        return json.load(fh)


def total(order):
    # FIXME: returns wrong total when a discount exceeds the subtotal
    subtotal = sum(item["price"] * item["qty"] for item in order["items"])
    discount = order.get("discount", 0)
    return round((subtotal - discount) * (1 + TAX_RATE), 2)


def notify(order):
    # HACK [2026-11-30] skip emails for test accounts until the staging mail stub is fixed
    if order.get("email", "").endswith("@test.local"):
        return False
    # TODO: retry
    return True


def label(order):
    note = "TODO: this string is not a comment and should be ignored"
    # TODO(@ken, OPS-19): move label printing to the warehouse service
    return f"{order['id']} {note[:0]}"
FILE:scripts/todo_debt.py
#!/usr/bin/env python3
"""Scan source files for TODO/FIXME/HACK/XXX comments and grade them (Python 3 standard library only).

Recognized forms (marker must follow a comment token: #  //  /*  *  --  ;  <!--):
  # TODO: plain note
  // TODO(alice): owner
  # FIXME(#123): issue number      # TODO(PROJ-42) ticket key      # TODO(https://...) link
  # TODO(bob, 2026-12-01): owner + due date   # HACK [2026-11-15] due date in brackets
Problems flagged per item:
  no_owner, no_ticket, overdue (due date before --today), stale_hack (HACK/XXX without ticket),
  vague (fewer than 3 words of text)
Exit code: 1 if any item is overdue or a FIXME/HACK/XXX has no ticket (with --strict: any problem).
"""
import argparse
import datetime as dt
import json
import os
import re
import sys

MARKERS = ("TODO", "FIXME", "HACK", "XXX")
SEVERITY = {"FIXME": 3, "HACK": 3, "XXX": 3, "TODO": 1}
COMMENT_RE = re.compile(
    r"(?:#|//|/\*|(?:^|\s)\*|--|;|<!--)\s*(?P<marker>TODO|FIXME|HACK|XXX)\b"
    r"(?:\s*\((?P<paren>[^)]*)\))?(?:\s*\[(?P<bracket>[^\]]*)\])?\s*:?\s*(?P<text>.*)$")
DATE_RE = re.compile(r"\b(\d{4}-\d{2}-\d{2})\b")
TICKET_RE = re.compile(r"(#\d+\b|\b[A-Z][A-Z0-9]+-\d+\b|https?://\S+)")
OWNER_RE = re.compile(r"^@?([A-Za-z][\w.-]*)$")
DEFAULT_EXT = {".py", ".js", ".ts", ".tsx", ".jsx", ".go", ".rs", ".java", ".kt", ".c", ".h", ".cpp",
               ".cs", ".rb", ".php", ".swift", ".sh", ".sql", ".yaml", ".yml", ".toml", ".css", ".scss",
               ".html", ".vue", ".lua"}
SKIP_DIRS = {".git", "node_modules", "vendor", "dist", "build", ".venv", "venv", "__pycache__", "target"}


def parse_line(line, path="<text>", lineno=0, today=None):
    m = COMMENT_RE.search(line)
    if not m:
        return None
    marker = m.group("marker")
    meta = ",".join(x for x in (m.group("paren"), m.group("bracket")) if x)
    text = (m.group("text") or "").strip().rstrip("*/").rstrip("-->").strip()
    owner = None
    ticket = None
    due = None
    for part in [p.strip() for p in meta.split(",") if p.strip()]:
        if DATE_RE.fullmatch(part.replace("by ", "").replace("until ", "").strip()):
            due = DATE_RE.search(part).group(1)
        elif TICKET_RE.fullmatch(part):
            ticket = part
        elif OWNER_RE.fullmatch(part) and owner is None:
            owner = OWNER_RE.fullmatch(part).group(1)
    if ticket is None:
        t = TICKET_RE.search(text)
        if t:
            ticket = t.group(1)
    if due is None:
        d = re.search(r"\b(?:by|until|before|due)\s+(\d{4}-\d{2}-\d{2})\b", text)
        if d:
            due = d.group(1)
    problems = []
    if not owner:
        problems.append("no_owner")
    if not ticket:
        problems.append("no_ticket")
        if marker in ("HACK", "XXX"):
            problems.append("stale_hack")
    if due and today:
        try:
            if dt.date.fromisoformat(due) < today:
                problems.append("overdue")
        except ValueError:
            problems.append("bad_date")
    if len(re.findall(r"[A-Za-z]{2,}", text)) < 3:
        problems.append("vague")
    return {"file": path, "line": lineno, "marker": marker, "owner": owner, "ticket": ticket,
            "due": due, "text": text, "problems": problems,
            "score": SEVERITY[marker] + 2 * ("overdue" in problems) + ("no_ticket" in problems)}


def scan_text(text, path="<text>", today=None):
    items = []
    for i, line in enumerate(text.splitlines(), 1):
        it = parse_line(line, path, i, today)
        if it:
            items.append(it)
    return items


def iter_files(root, exts):
    if os.path.isfile(root):
        yield root
        return
    for dirpath, dirnames, filenames in os.walk(root):
        dirnames[:] = sorted(d for d in dirnames if d not in SKIP_DIRS)
        for fn in sorted(filenames):
            if os.path.splitext(fn)[1].lower() in exts:
                yield os.path.join(dirpath, fn)


def is_blocking(item, strict=False):
    if strict:
        return bool(item["problems"])
    return "overdue" in item["problems"] or (item["marker"] != "TODO" and "no_ticket" in item["problems"])


def summarize(items):
    s = {"total": len(items), "by_marker": {}, "by_owner": {}, "problems": {}}
    for it in items:
        s["by_marker"][it["marker"]] = s["by_marker"].get(it["marker"], 0) + 1
        o = it["owner"] or "(unowned)"
        s["by_owner"][o] = s["by_owner"].get(o, 0) + 1
        for p in it["problems"]:
            s["problems"][p] = s["problems"].get(p, 0) + 1
    return s


def render(items):
    out = ["| Score | Marker | Location | Owner | Ticket | Due | Problems | Text |", "|---|---|---|---|---|---|---|---|"]
    for it in sorted(items, key=lambda x: (-x["score"], x["file"], x["line"])):
        out.append(f"| {it['score']} | {it['marker']} | {it['file']}:{it['line']} | {it['owner'] or '-'} | "
                   f"{it['ticket'] or '-'} | {it['due'] or '-'} | {', '.join(it['problems']) or 'ok'} | {it['text'][:60]} |")
    return "\n".join(out)


SAMPLE = '''import os
# TODO(alice, 2026-01-15): remove legacy CSV export after #412 ships
def f():
    pass  # FIXME: crashes when list is empty
// HACK [2026-12-31] skip auth in local dev
/* XXX(PROJ-77): double-check rounding with finance */
-- TODO(@bob): add index
x = "TODO: this is a string, not a comment"
<!-- TODO(carol): https://example.com/issues/9 replace hero image -->
 * TODO update docs by 2025-05-01
# todo lowercase is ignored
'''


def self_test():
    today = dt.date(2026, 10, 18)
    items = scan_text(SAMPLE, "sample", today)
    by_line = {it["line"]: it for it in items}
    cases = [
        ("count", len(items), 7),
        ("owner_parsed", by_line[2]["owner"], "alice"),
        ("due_parsed", by_line[2]["due"], "2026-01-15"),
        ("overdue_flag", "overdue" in by_line[2]["problems"], True),
        ("ticket_from_text", by_line[2]["ticket"], "#412"),
        ("fixme_no_ticket", by_line[4]["problems"][:2], ["no_owner", "no_ticket"]),
        ("fixme_blocking", is_blocking(by_line[4]), True),
        ("hack_bracket_due_future", "overdue" in by_line[5]["problems"], False),
        ("hack_stale", "stale_hack" in by_line[5]["problems"], True),
        ("xxx_ticket_key", by_line[6]["ticket"], "PROJ-77"),
        ("at_owner", by_line[7]["owner"], "bob"),
        ("vague_short", "vague" in by_line[7]["problems"], True),
        ("string_not_comment", 8 in by_line, False),
        ("html_comment_link", by_line[9]["ticket"], "https://example.com/issues/9"),
        ("star_comment_due_text", by_line[10]["due"], "2025-05-01"),
        ("lowercase_ignored", 11 in by_line, False),
        ("todo_not_blocking_default", is_blocking(by_line[7]), False),
        ("todo_blocking_strict", is_blocking(by_line[7], strict=True), True),
        ("summary_markers", summarize(items)["by_marker"], {"TODO": 4, "FIXME": 1, "HACK": 1, "XXX": 1}),
        ("score_overdue_todo", by_line[2]["score"], 3),
    ]
    failed = 0
    for name, got, expected in cases:
        ok = got == expected
        failed += not ok
        print(f"{'PASS' if ok else 'FAIL'}  {name}: got={got!r} expected={expected!r}")
    print(f"\n{len(cases) - failed}/{len(cases)} passed")
    return 1 if failed else 0


def main(argv=None):
    p = argparse.ArgumentParser(description="Find and grade TODO/FIXME/HACK/XXX comments.")
    p.add_argument("paths", nargs="*", default=[], help="files or directories to scan")
    p.add_argument("--today", help="YYYY-MM-DD for overdue checks (default: today)")
    p.add_argument("--ext", help="comma-separated extensions to include, e.g. .py,.ts")
    p.add_argument("--json", action="store_true")
    p.add_argument("--strict", action="store_true", help="exit 1 on any problem")
    p.add_argument("--self-test", action="store_true")
    a = p.parse_args(argv)
    if a.self_test:
        return self_test()
    if not a.paths:
        p.error("give files/directories to scan, or --self-test")
    today = dt.date.fromisoformat(a.today) if a.today else dt.date.today()
    exts = {e if e.startswith(".") else "." + e for e in a.ext.split(",")} if a.ext else DEFAULT_EXT
    items = []
    for root in a.paths:
        for path in iter_files(root, exts):
            try:
                with open(path, encoding="utf-8", errors="replace") as fh:
                    items += scan_text(fh.read(), path, today)
            except OSError as e:
                print(f"warn: {path}: {e}", file=sys.stderr)
    if a.json:
        print(json.dumps({"summary": summarize(items), "items": items}, indent=2))
    else:
        print(render(items))
        s = summarize(items)
        print(f"\nTotal {s['total']}; markers {s['by_marker']}; problems {s['problems']}")
    return 1 if any(is_blocking(it, a.strict) for it in items) else 0


if __name__ == "__main__":
sys.exit(main())Guide a student aged 9-15 from curiosity to a fair-test science fair project: question picker, variables table, hypothesis coach, repeatable procedure, data sheet and chart choice, backward timeline, conclusion prompts, display board layout, and judge practice, with safety flags.
Act as a Kids' Science Fair Project Mentor. You help a student (ages 9 to 15) and their parent or teacher turn a curious question into a real, testable science fair project that the student can run and explain on their own. You are encouraging, patient, and honest about what makes a fair test. You never do the project for the student: you ask guiding questions, offer choices, and let the student decide. You always flag safety concerns and steer away from anything involving open flames, strong chemicals, mains electricity, live animal experiments, or human taste tests without adult supervision and school approval.

Start by asking, in one short friendly message, for:
- The student's age or grade and how much time is left before the fair
- Two or three things the student is curious about (sports, cooking, plants, music, phones, weather, anything)
- Materials and space available at home or school, and a rough budget
- Fair rules: required sections, board size, whether an engineering design project is allowed, and any judging rubric

Then guide the project through these stages:

1. **Question Picker**: turn each curiosity into one measurable question ("Does the water temperature change how fast sugar dissolves?"). Rate each for doability, safety, and time, and help the student pick one.

2. **Variables and Fair Test**: name the independent variable, the dependent variable, and at least three controlled variables in a small table. Explain in kid-friendly words why changing only one thing at a time matters.

3. **Hypothesis Coach**: help the student write an "If ... then ... because ..." hypothesis in their own words.

4. **Materials and Procedure**: a numbered procedure a classmate could repeat, with at least three trials per condition and a materials checklist with cheap substitutes.

5. **Data Sheet**: a blank results table with units, plus a suggestion for the best chart type (bar, line, or scatter) and why.

6. **Timeline**: a backward plan from fair day with checkpoints for trials, analysis, board building, and practice, sized to the time left.

7. **Results and Conclusion Prompts**: questions that help the student explain what happened, whether the hypothesis was supported, sources of error, and what they would test next.

8. **Display Board Layout**: a simple board plan (title, question, hypothesis, procedure, data, chart, conclusion, photos) and tips for readable fonts and spacing.

9. **Judge Practice**: eight likely judge questions and a 60-second talk outline the student can rehearse.

Keep every explanation short and age-appropriate. Use checklists and tables. If the timeline is too tight, say so and suggest a smaller version of the same question. Celebrate surprising or "failed" results as real science.Opinionated preferences for building fast, friendly command-line tools in Rust.
# Rust CLI taste
- Parse arguments with clap using the derive API and doc comments as help text. Confidence: 0.95
- Return anyhow::Result from main and add context to every fallible step with .context(). Confidence: 0.90
- Define library error types with thiserror and keep anyhow in the binary only. Confidence: 0.85
- Split the crate into a thin main.rs and a lib.rs that holds the real logic for testing. Confidence: 0.85
- Write normal output to stdout and logs, progress and errors to stderr. Confidence: 0.95
- Offer a --json flag for machine-readable output and serialize it with serde. Confidence: 0.85
- Use tracing with an env filter controlled by -v flags and a RUST_LOG override. Confidence: 0.80
- Respect NO_COLOR and disable colors automatically when stdout is not a terminal. Confidence: 0.90
- Show progress bars with indicatif only for operations longer than about a second. Confidence: 0.75
- Exit with distinct, documented exit codes instead of always returning 1. Confidence: 0.80
- Read configuration in the order flags, then environment variables, then a TOML config file. Confidence: 0.80
- Find config and cache paths with the directories crate rather than hardcoding home paths. Confidence: 0.80
- Test the binary end to end with assert_cmd and snapshot output with insta. Confidence: 0.85
- Avoid async and tokio unless the tool really does concurrent network work. Confidence: 0.75
- Generate shell completions and a man page with clap_complete and clap_mangen at build time. Confidence: 0.75
- Ship prebuilt binaries for Linux, macOS and Windows with cargo-dist from GitHub Actions. Confidence: 0.80
- Run cargo clippy with warnings denied and cargo fmt --check in CI. Confidence: 0.90
- Set opt-level, lto and strip in the release profile to keep binaries small. Confidence: 0.70
- Handle Ctrl+C cleanly with the ctrlc crate and leave no half-written files behind. Confidence: 0.80
Audits foreground/background color pairs for WCAG 2.x contrast (AA and AAA for normal and large text), reports ratios and pass/fail, and notes color-blindness risks. Use when checking UI palettes, design tokens, or asking "is this gray-on-white readable?". Includes a stdlib Python contrast checker with --self-test.
---
name: accessibility-color-contrast-auditor
description: Audits foreground/background color pairs for WCAG 2.x contrast (AA and AAA for normal and large text), reports ratios and pass/fail, and notes color-blindness risks. Use when checking UI palettes, design tokens, or asking "is this gray-on-white readable?". Includes a stdlib Python contrast checker with --self-test.
---

# Accessibility Color Contrast Auditor

You help designers and frontend engineers check whether text and UI colors meet WCAG 2.x contrast ratios. You compute relative luminance contrast for foreground/background pairs, map results to AA/AAA for normal and large text, and flag pairs that rely on hue alone for meaning.

## Files in this skill

- `scripts/contrast_check.py` - computes contrast ratios for hex pairs and prints a pass table (Python 3 standard library only)
- `references/wcag-contrast.md` - thresholds and what counts as large text
- `references/color-blindness-notes.md` - why hue-only status colors fail real users
- `templates/audit-table.md` - markdown table for design reviews
- `examples/palette.json` - sample token pairs

## Workflow

### 1. Collect pairs
Ask for hex colors (`#RGB`, `#RRGGBB`, or `#RRGGBBAA` with alpha ignored against an opaque background). Note which is text/icon (fg) and which is surface (bg).

### 2. Run the checker
```
python3 scripts/contrast_check.py --fg '#1a1a1a' --bg '#ffffff'
python3 scripts/contrast_check.py --palette examples/palette.json
python3 scripts/contrast_check.py --self-test
```

### 3. Interpret
- Normal text AA needs **4.5:1**; AAA needs **7:1**.
- Large text (18pt+ or 14pt+ bold) AA needs **3:1**; AAA needs **4.5:1**.
- Non-text UI components / graphical objects that convey meaning need **3:1** against adjacent colors (WCAG 2.1 SC 1.4.11).

### 4. Answer
For each pair: ratio (one decimal), AA/AAA normal, AA/AAA large, and a short fix suggestion (darken fg, lighten bg, or add weight/size). Mention color-blindness if status depends on red vs green alone.

## Rules

- Use the WCAG relative luminance formula; do not approximate with "eyeballing".
- Ignore marketing claims about "accessible mode" unless ratios are shown.
- If alpha blending is involved, ask for the effective flattened hex on the real background.
FILE:references/wcag-contrast.md
# WCAG contrast thresholds (WCAG 2.1 / 2.2)

| Content | AA | AAA |
| --- | --- | --- |
| Normal text | 4.5:1 | 7:1 |
| Large text | 3:1 | 4.5:1 |
| UI components & graphical objects (1.4.11) | 3:1 | — |

## Large text

Large text is at least **18 CSS pt** (typically 24px) regular, or **14 CSS pt** (typically 18.66px) bold.

## Relative luminance

For sRGB channel C_srgb in 0..1:

- if C_srgb <= 0.04045: C = C_srgb / 12.92
- else: C = ((C_srgb + 0.055) / 1.055) ^ 2.4

L = 0.2126 R + 0.7152 G + 0.0722 B

Contrast ratio = (L_lighter + 0.05) / (L_darker + 0.05)

## Notes

- Placeholder / disabled text is exempt from text contrast SCs but still benefits from clarity.
- Focus indicators need 3:1 against adjacent colors (2.4.11 / 2.4.13 depending on level).
FILE:references/color-blindness-notes.md
# Color blindness notes for palettes

Contrast ratio alone is not enough when meaning is carried only by hue.

## Common pitfalls

- **Red vs green status** without icon or label: deuteranomaly/protanomaly users may not tell them apart.
- **Chart series** distinguished only by color: add patterns, shapes, or direct labels.
- **Link color** same lightness as body text: underline or weight must remain when color is removed.
- **Error borders** that are only a pale red tint: ensure 3:1 against the background and include text/icon.

## Safer patterns

1. Pair color with text ("Error", "Success") or icon.
2. Use lightness differences, not only hue shifts.
3. Test a grayscale screenshot of the UI.
4. Avoid conveying required-field state with red alone.

## Deuteranopia-friendly tip

Prefer blue/orange or blue/brown pairs over red/green for categorical data when you must use two hues.
FILE:templates/audit-table.md
# Contrast audit

- **Product / screen**:
- **Date**:
- **Standard**: WCAG 2.2 AA (default) / AAA where noted

| Token / use | FG | BG | Ratio | AA normal | AAA normal | AA large | Notes / fix |
| --- | --- | --- | --- | --- | --- | --- | --- |
| body text | `#1a1a1a` | `#ffffff` | 16.1 | pass | pass | pass | |
| muted caption | `#9ca3af` | `#ffffff` | 2.5 | fail | fail | fail | Darken to ~`#6b7280` |

## Decisions

- [ ] Update tokens
- [ ] Accept large-text-only usage
- [ ] Add non-color cue
FILE:examples/palette.json
{
  "pairs": [
    {"name": "body_on_white", "fg": "#1a1a1a", "bg": "#ffffff"},
    {"name": "muted_on_white", "fg": "#9ca3af", "bg": "#ffffff"},
    {"name": "link_on_white", "fg": "#2563eb", "bg": "#ffffff"},
    {"name": "button_label", "fg": "#ffffff", "bg": "#2563eb"},
    {"name": "error_on_white", "fg": "#dc2626", "bg": "#ffffff"},
    {"name": "white_on_light_gray", "fg": "#ffffff", "bg": "#e5e7eb"}
  ]
}
FILE:scripts/contrast_check.py
#!/usr/bin/env python3
"""WCAG contrast ratio checker for hex fg/bg pairs.

Usage:
    python3 contrast_check.py --fg '#1a1a1a' --bg '#ffffff'
    python3 contrast_check.py --palette palette.json
    python3 contrast_check.py --self-test

Python 3 standard library only.
"""
from __future__ import annotations

import argparse
import json
import math
import sys
from typing import Dict, List, Tuple


def parse_hex(color: str) -> Tuple[float, float, float]:
    c = color.strip().lstrip("#")
    if len(c) == 3:
        c = "".join(ch * 2 for ch in c)
    if len(c) == 8:
        c = c[:6]  # ignore alpha
    if len(c) != 6:
        raise ValueError(f"Bad hex color: {color!r}")
    r = int(c[0:2], 16) / 255.0
    g = int(c[2:4], 16) / 255.0
    b = int(c[4:6], 16) / 255.0
    return r, g, b


def channel(c: float) -> float:
    if c <= 0.04045:
        return c / 12.92
    return ((c + 0.055) / 1.055) ** 2.4


def relative_luminance(rgb: Tuple[float, float, float]) -> float:
    r, g, b = rgb
    return 0.2126 * channel(r) + 0.7152 * channel(g) + 0.0722 * channel(b)


def contrast_ratio(fg: str, bg: str) -> float:
    l1 = relative_luminance(parse_hex(fg))
    l2 = relative_luminance(parse_hex(bg))
    lighter, darker = max(l1, l2), min(l1, l2)
    return (lighter + 0.05) / (darker + 0.05)


def evaluate(ratio: float) -> Dict[str, bool]:
    return {
        "aa_normal": ratio >= 4.5,
        "aaa_normal": ratio >= 7.0,
        "aa_large": ratio >= 3.0,
        "aaa_large": ratio >= 4.5,
        "ui_3_1": ratio >= 3.0,
    }


def format_row(name: str, fg: str, bg: str) -> str:
    ratio = contrast_ratio(fg, bg)
    ev = evaluate(ratio)
    flags = " ".join(
        f"{k}={'PASS' if v else 'FAIL'}"
        for k, v in ev.items()
        if k in ("aa_normal", "aaa_normal", "aa_large")
    )
    return f"{name}: {fg} on {bg} -> {ratio:.2f}:1  {flags}"


def self_test() -> int:
    cases = [
        ("black_white", contrast_ratio("#000000", "#ffffff"), 21.0),
        ("white_black", contrast_ratio("#ffffff", "#000000"), 21.0),
        ("body", contrast_ratio("#1a1a1a", "#ffffff") > 12.0, True),
        ("muted_fail_aa", evaluate(contrast_ratio("#9ca3af", "#ffffff"))["aa_normal"], False),
        ("link_aa", evaluate(contrast_ratio("#2563eb", "#ffffff"))["aa_normal"], True),
        ("same_color", abs(contrast_ratio("#ffffff", "#ffffff") - 1.0) < 1e-9, True),
        ("short_hex", abs(contrast_ratio("#000", "#fff") - 21.0) < 1e-9, True),
        ("parse3", parse_hex("#abc") == parse_hex("#aabbcc"), True),
        ("ui_pass", evaluate(3.0)["ui_3_1"], True),
        ("aaa_border", evaluate(7.0)["aaa_normal"], True),
        ("just_under_aa", evaluate(4.49)["aa_normal"], False),
    ]
    failed = 0
    for name, got, expected in cases:
        if isinstance(expected, float):
            ok = abs(float(got) - expected) < 0.05
        else:
            ok = got == expected
        failed += not ok
        print(f"{'PASS' if ok else 'FAIL'}  {name}: got={got!r} expected={expected!r}")
    print(f"\n{len(cases) - failed}/{len(cases)} passed")
    return 1 if failed else 0


def main(argv=None) -> int:
    p = argparse.ArgumentParser(description="Check WCAG contrast for fg/bg hex pairs.")
    p.add_argument("--fg")
    p.add_argument("--bg")
    p.add_argument("--palette", help="JSON file with {pairs:[{name,fg,bg}]}")
    p.add_argument("--json", action="store_true")
    p.add_argument("--self-test", action="store_true")
    a = p.parse_args(argv)
    if a.self_test:
        return self_test()
    rows = []
    if a.palette:
        data = json.load(open(a.palette, encoding="utf-8"))
        for pair in data.get("pairs", []):
            rows.append(pair)
    elif a.fg and a.bg:
        rows.append({"name": "pair", "fg": a.fg, "bg": a.bg})
    else:
        p.error("provide --fg and --bg, or --palette, or --self-test")
    out = []
    any_fail = False
    for row in rows:
        ratio = contrast_ratio(row["fg"], row["bg"])
        ev = evaluate(ratio)
        if not ev["aa_normal"]:
            any_fail = True
        item = {"name": row.get("name", "pair"), "fg": row["fg"], "bg": row["bg"], "ratio": round(ratio, 2), **ev}
        out.append(item)
        if not a.json:
            print(format_row(item["name"], item["fg"], item["bg"]))
    if a.json:
        print(json.dumps(out, indent=2))
    return 1 if any_fail else 0


if __name__ == "__main__":
    sys.exit(main())
